Consider the original two-dimensional exampleThe Hessian matrix is , a symmetric matrix and positive-definite matrix. Its eigenvectors are the coordinate directions, its eigenvalues are and , and its Euclidean norm condition number is . The unique global minimum is , so the error equals . The linear map , with the identity matrix, givesFor , the two coordinate error multipliers are and . Consequently , , and the second coordinate changes sign at every step while both shrink. The Euclidean norm of the error contracts by each step. The objective gap, which we call the quadratic energy, contracts by its square:The level sets of are ellipses. Oscillation across their narrow direction is compatible with strictly decreasing energy.
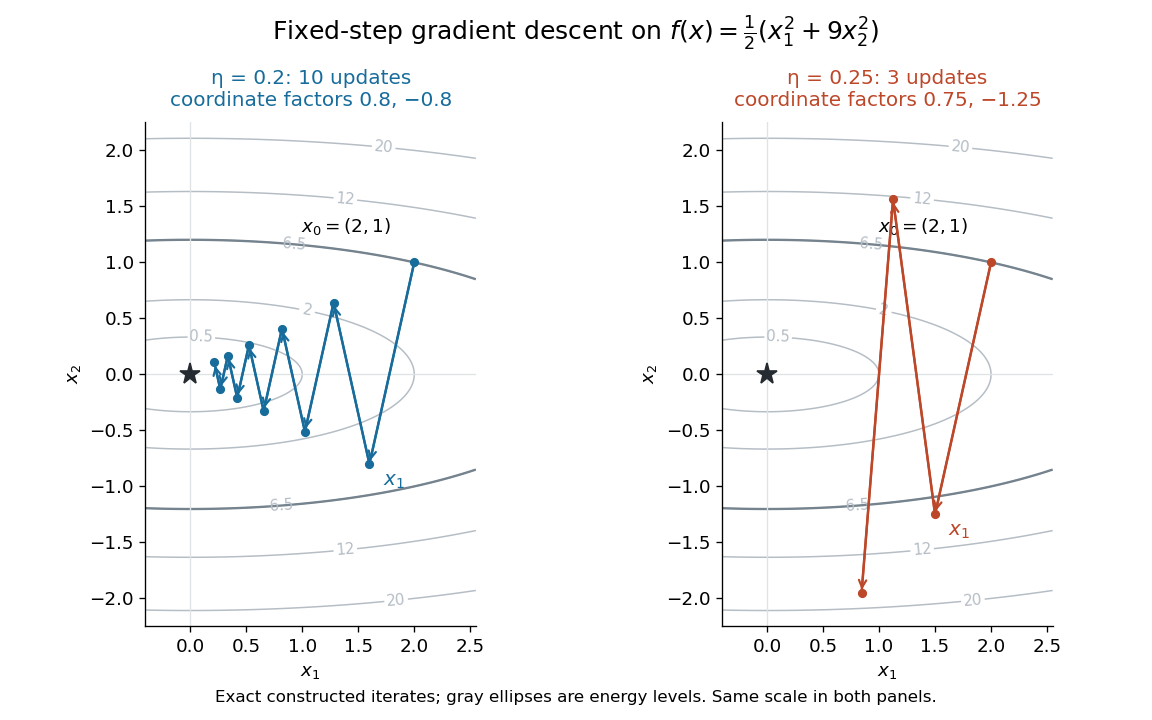
Original gradient descent iterates on : step size contracts both directions, whereas expands the second
. Details. For , the coordinate error multipliers become and , giving . The first coordinate still tends to zero, but the second alternates and grows. Direct substitution givesThus a larger positive step size can turn a strictly convex function into a divergent iteration. Energy and error are different quantities: coordinate errors carry signed multipliers, while each coordinate's contribution to energy carries the squared multiplier.


For the general quadratic form with linear termthe error obeys the same linear map . The spectral theorem for real symmetric matrices supplies an orthonormal basis of eigenvectors with positive eigenvalues . Writing gives the exact solution and energy identityTherefore convergence from every initial vector is equivalent toAt , a nonzero error component along a largest-eigenvalue eigenvector flips sign without shrinking. Above that threshold it grows. A particular start can still converge if it has zero components in every unstable direction; the interval is the condition for all starts. If , then and . These bounds follow by summing the squared components in the orthonormal basis.
For a fixed symmetric matrix and positive-definite matrix , what positive step size minimizes the largest coordinate error multiplier over all eigenvector directions? Let and . Since is a convex function of , its maximum over the eigenvalues occurs at an endpoint:Balance the two extremes by solving :Here is the Euclidean norm condition number of . This balance is optimal: for the endpoint exceeds , and for the endpoint exceeds . The optimal worst-case energy factor is , rather than . This optimizes a uniform one-step bound; a particular initial error supported on fewer eigenvectors can have a different best step size.
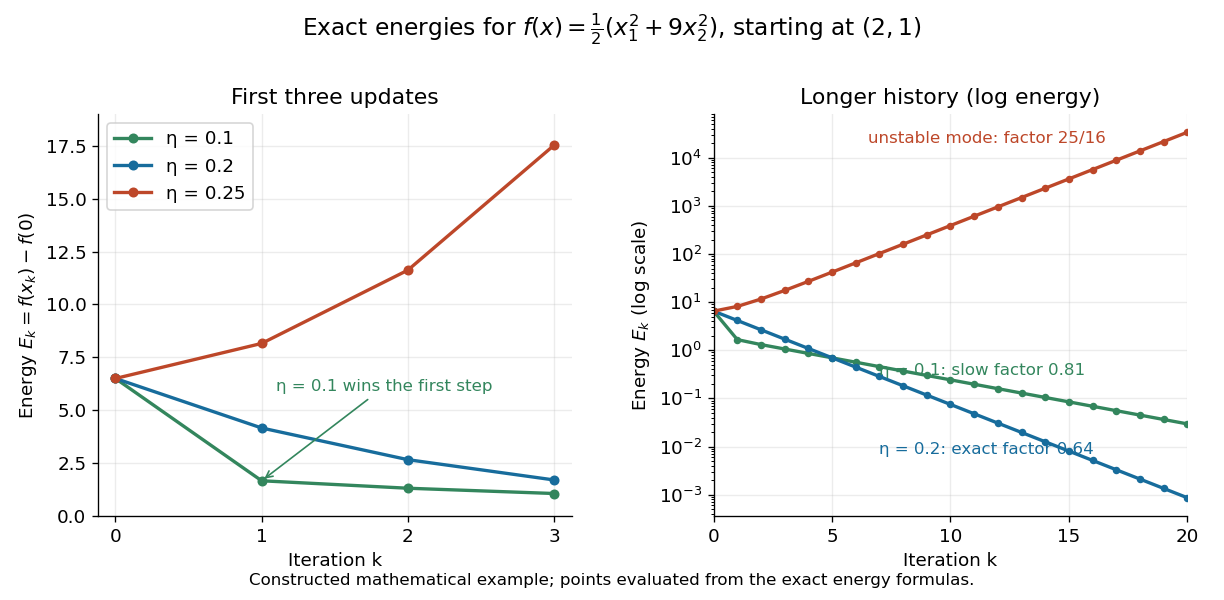
In the example , , so and . Both eigenvalue directions attain that energy factor, making the displayed history exact. The smaller step size instead givesIts first step reaches , below for , but subsequent progress is limited by the first direction's energy factor . By , the energies are approximately and , respectively; by , the iteration is ahead. A better first step need not yield a faster long-run history.
As the condition number grows, approaches one: stability in the direction of the largest eigenvalue forces small movement along the smallest-eigenvalue direction. This is a precise reason to improve scaling or use a method such as the Conjugate gradient method, rather than merely increasing the step size. When , choosing eliminates every error component in one step.
Articles by others on the same topic
There are currently no matching articles.