A symmetric function is a positive-semidefinite kernel when every finite Gram matrix is positive semidefinite.
In the compact-domain spectral setting, a Mercer kernel is a continuous symmetric positive-semidefinite kernel on a compact space equipped with a finite full-support measure. Mercer's theorem yields nonnegative eigenvalues and an expansion , giving features in . The finite-Gram positivity condition on arbitrary domains is more general than these spectral hypotheses; all such kernels still have a Reproducing kernel Hilbert space realization.
A real positive-semidefinite kernel satisfies . This follows from positivity of its two-point kernel matrix. If a diagonal value is zero, the corresponding off-diagonal values must also vanish.
On the finite formal span of symbols , define and extend bilinearly. For a positive-semidefinite kernel, the null vectors of this positive semidefinite bilinear form form its radical of a bilinear form. Quotienting by that linear subspace gives an inner product space and feature map with . This construction works for degenerate and zero kernels.
Random Fourier features represent a translation-invariant positive-semidefinite kernel by sampling frequencies from its spectral distribution and using sine and cosine features. They replace an implicit infinite-dimensional feature map by a finite random approximation.
The Gaussian kernel is a translation-invariant positive-semidefinite kernel whose canonical feature map takes values in an infinite-dimensional vector space.
For , a polynomial kernel is the positive-semidefinite kernel , where is a positive integer and . The case uses monomials of total degree ; also includes lower degrees. The feature map weights matter: listing each distinct monomial once with coefficient one generally gives a different inner product.[ref]
Gaussian Processes for Machine Learning by Carl Edward Rasmussen and Christopher K. I. Williams. Section 4.2.2, pp. 89–90, equations (4.23)–(4.24): polynomial kernels and weighted monomial features
For the homogeneous quadratic case in two dimensions, take the scaled quadratic feature mapThe inner product identity is explicit:The factor accounts for the two equal cross terms in the square. Thus an inner product of three derived coordinates can be obtained from an inner product of the two input coordinates followed by squaring. The kernel trick uses this equality inside an algorithm; the feature map explains which nonlinear functions the algorithm can represent.
Nonnegative scalar multiples, sums, pointwise products, pointwise limits, and pullbacks of positive-semidefinite kernels are positive semidefinite whenever the displayed expressions are defined.
Suppose is a positive-semidefinite kernel for every and its diagonal entries are integrable. Positivity of each kernel matrix givesThe Cauchy-Schwarz inequality makes every entry integrable, and integrating each nonnegative finite quadratic form shows that is again a positive-semidefinite kernel.
The pointwise product of two positive-semidefinite kernels is positive semidefinite because its finite kernel matrix is the entrywise product of two positive-semidefinite matrices, to which the Schur product theorem applies.
The Laplace kernel on is a translation-invariant positive-semidefinite kernel. Independent standard Cauchy random variables give its Random Fourier feature representation through their characteristic function .
A reproducing-kernel Hilbert space is a Hilbert space of functions in which point evaluation is continuous and satisfies .
For positive-semidefinite kernels with Reproducing kernel Hilbert spaces , the Reproducing kernel Hilbert space of consists of sums , withThe minimum is attained uniquely. Indeed, in the Hilbert space direct sum , the tuples summing to zero form a closed subspace : they are the intersection, over inputs , of the kernels of the continuous maps . Every affine fibre has a unique representative in by orthogonal decomposition by a closed subspace. The vector lies in and represents evaluation in the quotient; its evaluation at is , identifying the positive-semidefinite kernel with .
For a real-valued loss function depending only on evaluations at , and a positive squared-norm penalty, any minimizing tuple in a sum of reproducing-kernel Hilbert spaces has the formwith the same coefficient vector for every component. The tuple must be the unique minimum-norm decomposition of its sum. Apply the representer theorem to that sum and note that the displayed tuple has total squared norm , exactly the norm of the sum. This argument is conditional on existence of a minimizer; arbitrary loss functions need not attain their infimum.
The reproducing property is ; it turns point evaluation into an inner product with a kernel section.
The representer theorem reduces regularized optimization over a reproducing-kernel Hilbert space to the span of kernel sections at the observed points.
A kernel method represents data through a positive-semidefinite kernel, allowing algorithms to use inner products in an implicit feature map.
Kernel ridge regression minimizes empirical squared error plus the squared norm in a Reproducing kernel Hilbert space. The representer theorem reduces it to ridge regression with the kernel matrix as its feature Gram matrix.
For the unscaled objective , the kernel-ridge hat matrix is . Its prediction variance is . For eigenvalues , use and to bound the variance and the squared bias. The latter also uses the reproducing property and Bessel inequality, and does not require invertibility of .
EXISTING BODY EXPANSION, not a new concept: replace the present one-direction definition of Faithfulness of a directed acyclic graph in probability-and-statistics.bigb, under Causal directed acyclic graph, with the following body. Retain its existing header and parent.
Every positive-semidefinite kernel has a Hilbert-space feature map satisfying , and determines a unique reproducing-kernel Hilbert space.
The kernel trick evaluates inner products of feature map outputs through without explicitly constructing those vectors. An algorithm expressed entirely through these inner products can therefore operate on nonlinear derived coordinates using only evaluations of a positive-semidefinite kernel on the original inputs. A classifier linear in the derived coordinates can have a nonlinear boundary in the original coordinates.
The polynomial kernel gives a finite, fully visible example: corresponds to . The XOR separation by a product feature below makes the interaction coordinate useful, while dual prediction with a kernel shows how to predict without calculating it explicitly.
An arbitrary score called a similarity need not be a positive-semidefinite kernel. Symmetry alone, even with nonnegative entries, is insufficient: the symmetric matrixhas for , so it cannot be a Gram matrix of real inner products. A positive-semidefinite kernel requires a positive semidefinite matrix for every finite choice of inputs, not just the observed training data.[ref]
Gaussian Processes for Machine Learning by Carl Edward Rasmussen and Christopher K. I. Williams. Section 4.1, p. 80: Gram matrices, quadratic-form definition of positive semidefiniteness, and nonnegative eigenvalues
The existing Moore-Aronszajn theorem connects this requirement to a Reproducing kernel Hilbert space; this example needs only finite linear algebra.Give the four corners of the square the exclusive or labels: when the input signs differ and when they agree. In the following order,No affine function has the required strictly positive scores at and strictly negative scores at : both pairs have midpoint zero, so would have to be both positive and negative. This also rules out perfect classification by a single threshold with a consistent tie rule.
Under the polynomial kernel's quadratic feature map, the two classes become two distinct vectors:The hyperplane separates them. With and , the score and classifier areAll four signed scores equal one. In the input plane the boundary is , the union of the coordinate axes; in the derived coordinates it is a single hyperplane. The feature map identifies opposite corners, which is harmless for these labels because opposite corners belong to the same class. A fixed feature map would not separate labels that disagree at identical mapped vectors.

XOR labels in the input square and the quadratic feature slice
. The dashed diagonals join equal-label input pairs and share their midpoint, obstructing affine separation. In the feature panel all mapped points have third coordinate one; the two coincident pairs are separated by the horizontal hyperplane at second coordinate zero. Details.
If the weight vector lies in the linear span of the training feature map outputs, write . ThenThis is a dual representation: coefficients weight training examples rather than feature coordinates. They need not be positive, and need not be unique when the kernel matrix is singular. Some kernel methods instead write with under their own optimization constraints.[ref]
The kernel trick by Ryan Giordano. Kernelizing classification with support vector machines: displayed prediction as a sum of label-weighted kernel evaluations
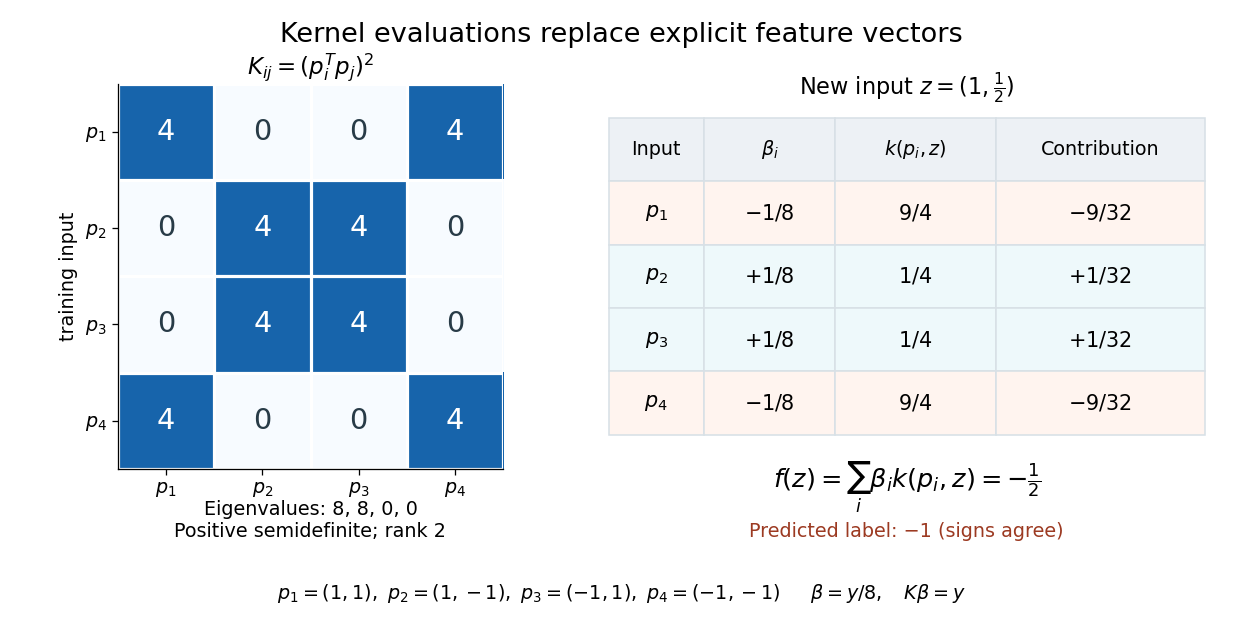
The formula is an algebraic conversion for a weight vector in this linear span, not a claim about every possible weight vector. The representer theorem gives a broader reason this form appears in regularized kernel methods.For the XOR separation by a product feature, let have rows . The Gram matrix of those rows, equivalently the kernel matrix, isIts eigenvalues are , so it is a positive semidefinite matrix of rank two, not an invertible matrix. More generally, for any real coefficient vector and any finite set of inputs,This proves the positive-semidefinite kernel condition for the displayed polynomial kernel on all of , rather than checking only this square.
Here , so the explicit choice gives and . ConsequentlyFor the new input , the four polynomial kernel evaluations are . Their weighted sum is , and the sign function predicts . No explicit feature map is needed for this calculation. These coefficients were constructed to reproduce the chosen separator; no fitting algorithm or generalization guarantee is being asserted.

For input coordinates, the homogeneous quadratic polynomial kernel has a weighted quadratic feature map with distinct monomials. Computing an inner product of already stored mapped vectors costs arithmetic operations, whereas costs using the input vectors. Here denotes big O notation. Higher fixed degrees can make the dimension gap much larger.
Sample count still matters. With training examples, materializing a dense kernel matrix stores numbers and requires distinct evaluations using symmetry. A dense direct solve for kernel ridge regression typically takes operations after constructing the kernel matrix, while a dual prediction with nonzero coefficients uses kernel evaluations. Explicit finite feature maps can be preferable when is small relative to , and a stored primal weight vector can make prediction depend on rather than on . The kernel trick by Ryan Giordano (sections Ridge regression and The polynomial kernel) explains the change from feature-coordinate equations to training-example equations; neither representation is universally faster.
The kernel trick saves explicit feature construction when the positive-semidefinite kernel is economical to evaluate; it does not remove the cost of optimization, choose a useful positive-semidefinite kernel, or establish generalization. Random Fourier features illustrate a different tradeoff: replacing the exact Gaussian kernel with a finite approximate feature map can reduce dependence on the sample count while introducing approximation error.
Kernel principal component analysis diagonalizes a centered kernel matrix to perform principal component analysis in an implicit feature space.
If a stationary Gaussian process has covariance spectral density , its reproducing-kernel Hilbert space has normon the functions for which this integral is finite.
Articles by others on the same topic
There are currently no matching articles.