An inner product assigns a scalar to two vectors and supplies their lengths and orthogonality. Using the convention linear in the first argument, it satisfiesThe resulting norm is . Over the real numbers, conjugation has no effect and the form is symmetric and bilinear. Over the complex numbers, it is sesquilinear; the convention linear in the second argument is also common, so formulas for coefficients must match the stated convention.
The Euclidean example is . For real and this gives , while and . If , then : perpendicularity becomes an algebraic equation. The Cauchy-Schwarz inequality gives , and in a real inner product space it makes the angle formula meaningful for nonzero vectors.
Different inner products express different measurements. The weighted example on gives , so its unit-length vectors lie on an ellipse. For functions, an integral such as supplies the geometry of the L2 space. This lets orthogonal projection and least-squares solutions apply to curves as well as coordinate lists.
At distinct real nodes with positive weights , the displayed expression is an inner product on the real vector space of polynomials of degree at most . Symmetry and bilinearity follow from finite sums. If its squared norm vanishes, positivity of every weight forces at every node. The root bound for a nonzero polynomial then forces , proving positive definiteness.
More generally, on any vector subspace of real functions, the evaluation form is an inner product exactly when the evaluation map is injective. On polynomials of degree at most it fails: the nonzero node polynomial vanishes at all nodes. This gives a positive semidefinite form with a nontrivial kernel. On the smaller polynomial space, the Lagrange interpolation polynomial identifies evaluation coordinates with , and Cauchy-Schwarz inequality follows either from the Euclidean inequality in those coordinates or from minimizing over real .
On real symmetric matrices of size , the displayed pairing is symmetric because . It is not bilinear: , whereas linearity would require . Its self-pairing is always nonnegative, but a nonzero singular matrix has , so positive definiteness fails as well. For it reduces to the ordinary real inner product. The Frobenius inner product supplies the appropriate bilinear, positive-definite geometry in every size.
Let be the vector space of real polynomials of degree of a polynomial at most . Choose distinct real sample points and positive real weights . Thenis an inner product. Symmetry and bilinearity follow from linearity of polynomial evaluation. Its value at is nonnegative, and equality forces all . By the root bound for a polynomial, a nonzero polynomial of degree of a polynomial at most cannot vanish at distinct points. Thus the form has positive definiteness.
Equivalently, the polynomial evaluation map on a finite point set identifies with , equipped with a weighted Euclidean inner product. Too few sample points destroy positive definiteness: if the distinct points number at most , the nonzero polynomial lies in and has zero sampled squared norm.
For three equally weighted samples at , an orthonormal basis isThis construction gives a finite sampling version of orthogonal polynomials and permits exact Gram-Schmidt orthogonalization using only finitely many evaluations.
An inner product space is a real or complex vector space equipped with a positive-definite inner product. Over the real numbers the form is symmetric and bilinear; over the complex numbers it is conjugate symmetric and sesquilinear. It defines the norm . The Cauchy-Schwarz inequality proves the triangle inequality for this norm. A complete inner product space is a Hilbert space; every finite-dimensional inner product space is complete.
Averaging squared norms of all signed sums of finitely many vectors in an inner-product space cancels every mixed term. This equates the average to the sum of the individual squared norms, distinguishing Hilbert-space geometry from other sequence-space norms.
The Fischer inner product on polynomials is . Multiplication by is adjoint to differentiation by . Therefore multiplication by is adjoint to the ordinary Laplacian, yielding the harmonic decomposition of homogeneous polynomials by finite-dimensional orthogonality.
For complex matrices, the inner product is conjugate-linear in its first argument. On real symmetric matrices it becomes . In particular , identifying quadratic forms with linear tests on matrices.
For the real two-by-two matrix space, the Frobenius inner product is . The displayed four matrices form an orthonormal basis. The first spans the identity direction, the next two span the traceless symmetric matrices, and the last spans the antisymmetric matrices. Symmetric and antisymmetric matrices are orthogonal because transposition changes the sign of their trace pairing; pairing with the identity gives the trace. This basis therefore displays the orthogonal direct sum into these three natural pieces.
Let be a real symmetric matrix and a real antisymmetric matrix of the same size. Invariance of the trace under transpose and the cyclic trace identity giveHence . Equivalently these two matrices are orthogonal for the Frobenius inner product, since . Together with the unique symmetric and antisymmetric parts of a matrix, this is an orthogonal decomposition of the real square matrices.
The discrete L2 inner product is the cell-volume-weighted Hermitian inner product on a uniform grid. Its associated norm is the discrete L2 norm. It provides the finite-dimensional analogue of spatial integration by parts and continuous energy method identities.
For a positive weight , the weighted inner product of functions is . It is the usual inner product in the L2 space for the measure . A Sturm-Liouville eigenfunction expansion uses this weight to make its eigenfunctions orthogonal.
The weight specifies how different locations contribute to a squared error: . More weight makes an error in that region more costly. The weighted Euclidean inner product makes the same choice for a finite list of coordinates.
For an explicit real-function example on , let and approximate by a constant function. The orthogonal projection onto a finite-dimensional subspace spanned by the function givesThe best unweighted constant is . Giving greater weight to larger moves the best constant upward, so a weighting choice changes the approximation even though the allowed family of functions is unchanged.
A positive measurable weight defines the displayed norm on the L2 space for the measure , with functions identified when equal almost everywhere. This is the norm induced by the weighted inner product. Changing changes the contribution of each region to approximation error. If are nonzero mutually orthogonal real functions, completing squares shows that the unique best approximation to real in their linear span has coefficients .
A symmetric positive-definite matrix defines an inner product on real coordinate vectors byFor diagonal , positive diagonal entries weight the squared coordinate errors. This is the finite-coordinate version of a weighted inner product; the positive-definite matrix example appears in Francis Narcowich, Inner Products and Norms, standard inner products, example 8.
For , the squared norm of is . A first-coordinate error of one costs as much as a second-coordinate error of two. The unit sphere is the ellipse , and orthogonality means . Thus “closest” and “perpendicular” depend on the chosen inner product. The orthogonal projection residual example shows how this changes a best approximation.
A dot product measures how much two Euclidean vectors point along each other. This article uses real Euclidean vectors in , with the usual Cartesian basis: multiply matching coordinates and add,The result is a scalar, while is the Euclidean norm. This real convention has no complex conjugation; for vectors over the complex numbers, use the convention specified in inner product.
For two nonzero Euclidean vectors, the same dot product records their angle through the cosine:Here is an inverse trigonometric function. The Cauchy-Schwarz inequality guarantees that the normalized ratio lies in . The zero vector has dot product zero with every vector, but its angle is undefined: the ratio would divide by zero. To outline the geometric identity, expand and compare with the law of cosines.[ref]
Take and . Their Euclidean norms are and , andThe unit vector selects the horizontal direction. The scalar projection says how far reaches along that direction; its vector projection is . Thus splits into an aligned part and an orthogonal projection residual.
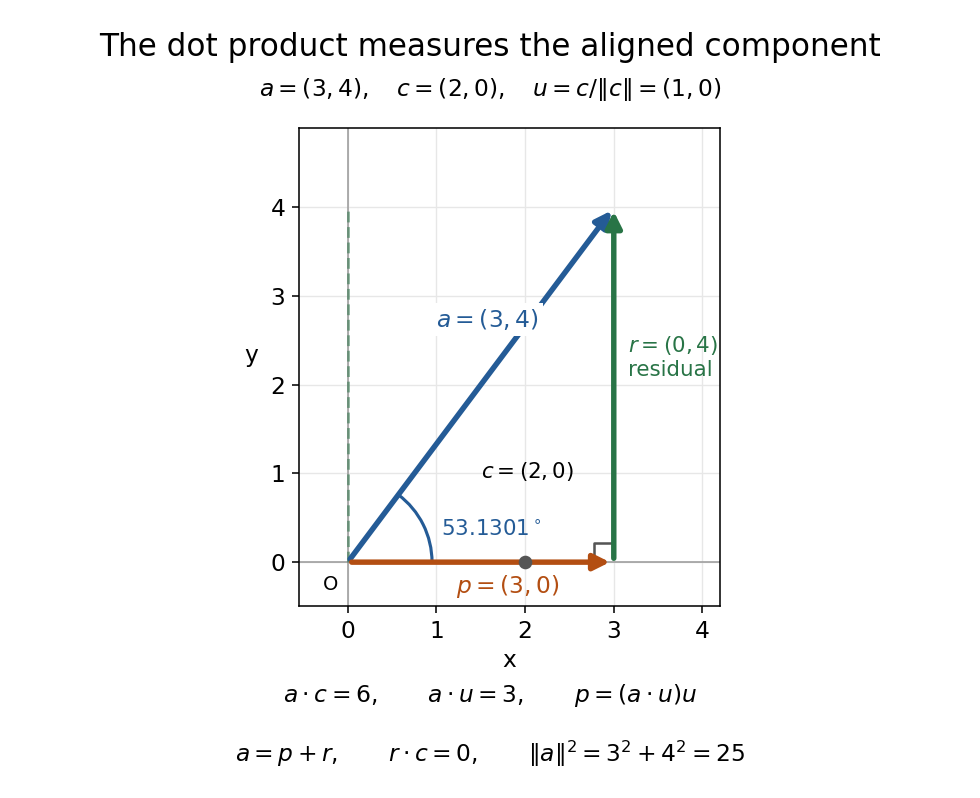
The vector projection of onto the horizontal line is ; the orthogonal projection residual is and the angle is
. Details. For , the dot product proves orthogonality; both Euclidean norms are . For , : the scalar projection onto is , because reaches against that chosen direction. Its angle with is .
Keeping fixed and choosing of Euclidean norm gives . At angles , the dot products are . Positive values mean partial alignment, zero means orthogonality, and negative values mean a component against the other direction.
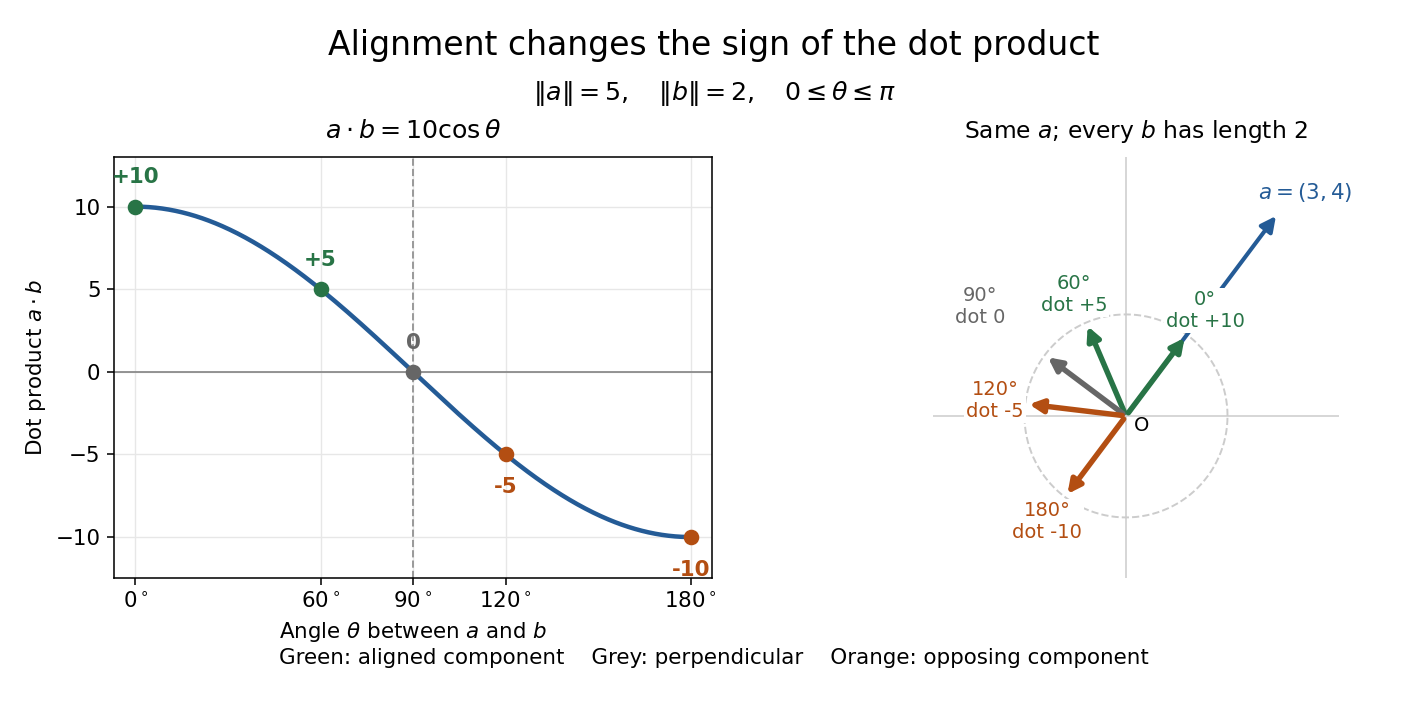
With Euclidean norms and , the dot product follows ; equal-length arrows show positive, zero, and negative alignment with
. Details. This interpretation explains work: for a constant force and a straight displacement , counts the force component along the motion. A sideways force contributes zero work, and an opposing force contributes negative work.[ref]
For two sparse vectors stored as increasing nonzero-coordinate streams, advance whichever current index is smaller; that coordinate has no possible partner in the other remaining stream. At equal indices, accumulate the product and advance both. The loop invariant accounts for all matched coordinates already passed and excludes any future match for skipped smaller coordinates. Termination occurs when either stream ends. The method uses time and constant auxiliary space, with floating-point results subject to the chosen evaluation order.
For nonzero real vectors in a Euclidean space, their angle is determined by the displayed dot product formula. The Cauchy-Schwarz inequality puts the quotient in , so the inverse cosine is defined. Perpendicular vectors have angle , parallel vectors pointing the same way have angle zero, and those pointing in opposite directions have angle . A zero vector has no uniquely defined direction and hence no angle by this definition.
For nonzero vectors in a complex inner product space, the displayed quotient defines the ordinary real angle in the underlying real inner product space, whose inner product is . The complex Cauchy-Schwarz inequality bounds it between and . This convention depends on the vectors' phase factors. The different phase-invariant convention measures an angle between complex one-dimensional subspaces; the two conventions should not be interchanged.
The scalar projection of a real Euclidean vector onto a nonzero Euclidean vector is its signed component along the unit vector :For , the scalar projection onto is , while that onto is . Reversing the measuring direction reverses the sign; the scalar projection is not necessarily a nonnegative length. For nonzero , it also equals , using the angle with and its cosine. For the zero vector it is zero, even though that angle is undefined.
The vector projection multiplies the scalar projection by the chosen unit vector, giving the orthogonal projection onto the linear span of a nonzero real Euclidean vector :For and , this gives and ; the dot product checks the orthogonal projection residual. Replacing by gives the same : reversing direction changes the scalar projection, but preserves the vector projection onto the line.
For a short proof of the nearest-point property, any vector on this line satisfies by the Pythagorean identity. The second term is uniquely minimized at . This connects a directional measurement to the orthogonal projection used in approximation.[ref]
https://ocw.mit.edu/courses/18-06-linear-algebra-spring-2010/resources/lecture-15-projections-onto-subspaces/. Strang, MIT 18.06, Lecture 15: projections onto subspaces
For , the binary inner product is in . Its value is the parity of the coordinates at which both vectors are one.
An orthonormal set consists of vectors that have norm one and are pairwise orthogonal. Its Gram matrix is the identity matrix.
A real matrix whose columns are an orthonormal set, equivalently . In the complex case use the conjugate transpose instead. This requires ; only in the square case does the transpose also provide a two-sided inverse, making an orthogonal matrix.
An orthonormal basis of a Hilbert space is an orthonormal set whose linear span has the whole space as its closure. This completeness of an orthonormal system allows every vector to be expanded in the basis vectors, with convergence in norm. In finite dimension it is also a basis in the finite-linear-combination sense.
An orthonormal set is complete in a Hilbert space when the closure of its linear span is the whole space. Equivalently, the only vector orthogonal to every member is zero: project any vector onto the closed span, and its remaining orthogonal component must vanish. This is completeness of an expansion system, distinct from completeness of the ambient metric space.
Coordinates relative to an origin and an orthonormal basis preserve Euclidean distances: if , then . This matters when finding the eccentricity of a conic section in an oblique plane: arbitrary projected coordinates need not preserve the ratio of its semi-major axis to its semi-minor axis.
A complete orthonormal basis in a Hilbert space resolves the identity as . In infinite dimension the partial sums converge strongly: their action on each fixed vector converges in norm. Generalized position and momentum eigenstates instead give distributional integral resolutions, such as , with their normalization interpreted through the Dirac delta function.
For a real orthonormal basis , each vector has expansion . Since this holds for every , the sum of the rank-one orthogonal projection matrices is the identity matrix. Their pairwise products vanish for distinct basis vectors. For a complex inner product space, replace the transpose by the conjugate transpose.
For vectors , the Gram matrix isTwo finite vector families with the same Gram matrix are related by an isometry between their spans; in finite dimensions that isometry can be extended to a unitary map after completing orthonormal bases.
A real matrix product giving pairwise dot products of columns, for , or rows, for . It is a positive semidefinite matrix. The kernel of a Gram product is determined by the corresponding factor, which makes these products useful for converting a zero quadratic form into an exact null space condition.
For real vectors in a Euclidean inner product space, their Gram matrix satisfies the displayed identity by expanding the squared norm. Thus every Gram matrix is a positive semidefinite matrix, and it is a positive-definite matrix exactly when the vector family is linearly independent. The complex version replaces transposes by conjugate transposes and uses .
For , the Gram matrix of unit vectors with common distinct-pair inner product is . Its eigenvalues are on the all-ones direction and on its orthogonal complement. It is a positive-definite symmetric matrix exactly when , permitting a linearly independent realization in . An explicit construction takes the columns ofThe two orthogonal projections have product zero, so ; positive eigenvalues also make invertible. At either endpoint the corresponding eigenspace becomes a linear dependence.
The determinant of a Gram matrix is nonnegative and vanishes precisely when its vectors are linearly dependent. In Euclidean three-dimensional space, three column vectors form a square matrix , whose Gram matrix is . Its determinant is , the square of the scalar triple product and of the parallelepiped volume.
For a basis of a finite-dimensional inner product space with conjugate-linear first argument, define and . Then and . This is the inner-product representation of the dual basis; requiring the dual vectors to lie in the given span is essential.
For a matrix with independent standard normal entries, is a Gaussian empirical Gram matrix and has expectation equal to the identity. With mean known to be zero it is the raw empirical second moment. Subtracting a sample mean would give a different estimator. On any fixed unit vector its quadratic form is a chi-squared variable divided by .
For with independent standard Gaussian rows in dimension , combine a constant-radius sphere metric net, the quadratic form net bound, the chi-squared concentration inequality, and a union bound. This gives for a numerical . Taking larger than a constant times gives exponential decay in . The subspace is fixed, so no union over supports is needed.
If has entrywise maximum norm at most , every vector supported on at most coordinates satisfies . Thus the squared norm distortion is at most on all such sparse vectors. Use the quadratic inequality at , where a ratio would be undefined.
A finite-dimensional linear subspace of an inner product space has a unique closest vector to any given vector . This is its orthogonal projection . If is an orthogonal basis of , compute it one direction at a time:The inner product convention here is linear in its first argument, including over the complex numbers. For an orthonormal basis, each denominator is one. When consists only of the zero vector, the empty sum gives . The finite-dimensional formula is described in Francis Narcowich, Inner Products and Norms: minimization problems.
Take and , using the dot product. With ,The orthogonal projection residual has . To verify the best approximation directly, every candidate in the line is , andThe smallest squared Euclidean norm error is therefore , attained only at . The diagram connects the perpendicular residual to this one-variable quadratic polynomial.
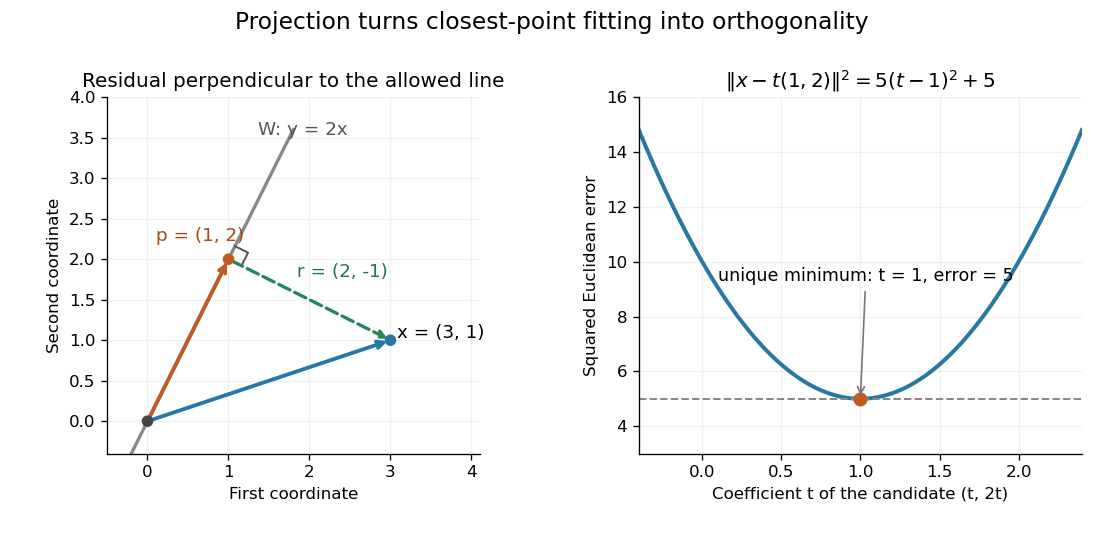
The perpendicular residual identifies the closest point on a line and the unique minimum of the squared error
. Details. The general mechanism is the Pythagorean theorem in an inner-product space. For any , the vectors and are orthogonal, soMoving away from inside adds a nonnegative squared norm, which is zero only when . This proves both optimality and uniqueness.
The useful feature is separation of preparation from evaluation. Construct an orthonormal basis once with the Gram-Schmidt process, then obtain each new best approximation using inner products instead of a fresh optimization problem. When is the column space of a matrix, this gives linear least squares; when is spanned by orthogonal polynomials, it gives a least-squares polynomial in an orthogonal-polynomial basis. The ambient inner product space need not be a Hilbert space for this finite-dimensional construction. In an infinite-dimensional target linear subspace, existence requires additional hypotheses, supplied by orthogonal decomposition by a closed subspace.
In the weighted inner product , the best approximation to in the span of is the displayed polynomial. The normal equations are and . Their solution gives , . The residual is orthogonal to that span, so the Pythagorean theorem proves minimality and uniqueness. Its squared norm is . A weight vanishing at a single endpoint still gives a positive-definite inner product on continuous functions: a nonzero continuous function remains nonzero on an interval where the weight is positive.
An orthogonal projection residual is the difference between a vector and its orthogonal projection onto a linear subspace . It is orthogonal to every vector in , so for all . The Gram-Schmidt process uses such residuals to remove directions already represented by earlier basis vectors.
This is an optimality condition as well as a geometric description. No permitted change within can remove a further orthogonal component of . In the preceding dot product example, is perpendicular to the line spanned by .
The selected inner product matters. Keep and the same line, but use the weighted Euclidean inner product with . The projection coefficient and residual becomeNow , although . The orthogonality is with respect to , so it need not look perpendicular in the ordinary drawing. The squared weighted error isThe weighted optimum reduces the first-coordinate error from to , at the cost of increasing the magnitude of the second-coordinate error from to . The weights express which errors are more costly.
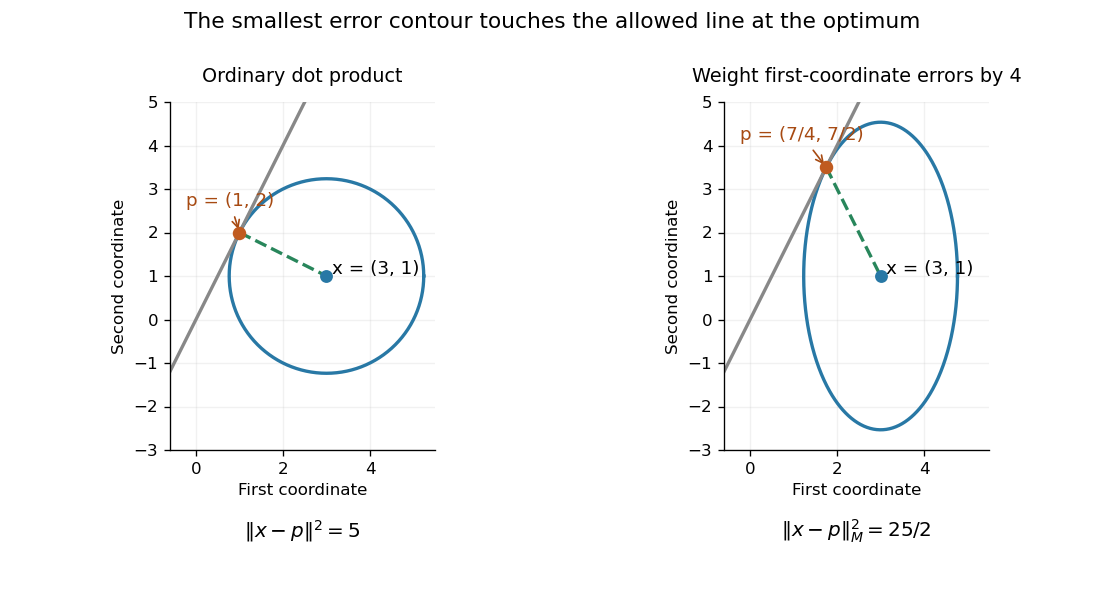
Changing the inner product changes the closest point: a circle and a weighted error ellipse touch the same permitted line at different points
. Details. In linear least squares, residual orthogonality to the column space is expressed by the normal equations for linear least squares. With a weighted Euclidean inner product, the corresponding real-matrix equation is . This makes the choice of error measurement part of the mathematical model, rather than merely a plotting convention.
A matrix represents a linear projection when applying it twice has the same effect as applying it once. For an orthogonal projection with the standard Hermitian inner product on , the additional condition is that the conjugate transpose equals the original matrix:Thus is both idempotent and a Hermitian matrix. Over the real numbers this says . Its image of a linear map is the retained linear subspace, while its kernel of a linear map is the orthogonal complement: vectors in the image are unchanged, and vectors in the kernel become zero.
For a matrix with full column rank, projecting onto its column space givesThe invertibility of follows from linear independence of the columns. If those columns are an orthonormal set, and . These formulas and the conditions in the real case are developed in MIT 18.06SC, Projections onto Subspaces, pp. 1–3.
For the line spanned by ,In particular, and . The eigenvalues are on the retained direction and on the removed direction. This exposes the meaning of an orthogonal projection as retaining selected components, rather than stretching them.
Symmetry refers to the specified inner product. In the real weighted setting, the formula becomes and satisfies and . For the preceding weighted line example,It is not symmetric under the ordinary transpose, but it is an orthogonal projection for the weighted Euclidean inner product. The matrix criterion should therefore be used with the standard Hermitian inner product, not silently transferred to a different geometry.
Under orthogonal projection from one plane onto another, a circle of radius becomes an ellipse with semiaxes and , where is the angle between the planes' unit normal vectors. To prove this, choose one in-plane unit vector parallel to the planes' intersection and the other perpendicular to it. The first vector is unchanged by the projection; the second has projected length and remains perpendicular to the first. Parametrizing the circle in that orthonormal basis therefore gives projected coordinates . Parallel planes have a circular image, and perpendicular planes give the degenerate case of a line segment. An arbitrary center simply projects to the center of the image.
For a nonnull vector in a space with a nondegenerate bilinear form, projects onto the subspace transverse to . It obeys and .
For orthogonal polynomials under a positive weighted integral inner product, the least-squares approximation to of degree at most isIts residual is orthogonal to every polynomial of degree at most .
Two vectors are orthogonal when their inner product is zero.
For real Euclidean vectors, the inner product is the dot product, so and are orthogonal: . For nonzero Euclidean vectors, this means their angle is . The zero vector is orthogonal to every vector, although it has no direction or defined angle.[ref]
https://ocw.mit.edu/courses/18-06-linear-algebra-spring-2010/resources/lecture-14-orthogonal-vectors-and-subspaces/. Strang, MIT 18.06, Lecture 14: orthogonal vectors and subspaces
In an abstract inner product space, orthogonality always refers to its chosen inner product. For example, the weighted inner product makes and orthogonal, since . Their ordinary dot product is , so their arrows are not perpendicular in the usual Cartesian coordinate system. The algebraic definition also applies to functions, where arrows need not be available.
A finite collection of nonzero pairwise orthogonal vectors is linearly independent. Given , take the inner product with to obtain . Positive definiteness and force for every index. The nonzero condition matters: adjoining a zero vector preserves pairwise orthogonality but destroys linear independence.
In the Hilbert space , choose orthonormal functions and . Their inner product is zero, but for the real potential energy ,Thus ordinary orthogonality alone does not remove an off-diagonal matrix element of a spatially varying potential energy. A constant scalar potential does give zero between distinct orthonormal states. The example separates these two claims; it is not a model of localized atomic orbitals in a particular crystal.
An orthogonal basis of an inner-product vector space consists of nonzero mutually orthogonal vectors that span the space. The orthogonal projection of onto a finite-dimensional span is . Dividing each vector by its norm produces an orthonormal basis. For centered random variables, the inner product is covariance; an orthogonal basis therefore consists of uncorrelated variables, without requiring unit variance.
Two vectors are nonorthogonal when their inner product is nonzero. In the power method, the starting vector must be nonorthogonal to a dominant eigenvector.
The Gram-Schmidt process turns a finite ordered family of linearly independent vectors in an inner product space over the real numbers into an orthonormal basis of their linear span. It keeps every successive linear span, so the first new vectors describe exactly the same directions as the first inputs. Its idea is geometric: remove the orthogonal projection onto directions already found, then divide the remaining vector by its norm. This makes a complicated basis easier to use without changing the vector subspace it describes.[ref]
Start with and . At step , use the previously obtained orthonormal set to defineThe sum is the orthogonal projection onto a finite-dimensional subspace , and is the orthogonal projection residual. Linear independence ensures : otherwise would already be a linear combination of earlier inputs. If the input family is linearly dependent, use only the retained orthonormal vectors in the sum and omit an input whenever its remainder is the zero vector; do not divide by zero. The retained outputs still form an orthonormal basis of the original linear span, but their number can be smaller than .
For a short verification, orthonormality makes every earlier inner product vanish:Also is minus a linear combination of earlier vectors, while is plus that same linear combination. These two inclusions, followed by division by a nonzero norm, giveThe argument also works in an inner product space over the complex numbers with the existing inner product convention, linear in the first argument: the coefficients remain . With the convention linear in the second argument, write instead.
For a first picture, take and in with the ordinary dot product. ThenSubtracting the diagonal component leaves an orthogonal direction; dividing by its norm makes its length one. If the second input were instead, its orthogonal projection would be the entire input and , revealing linear dependence.
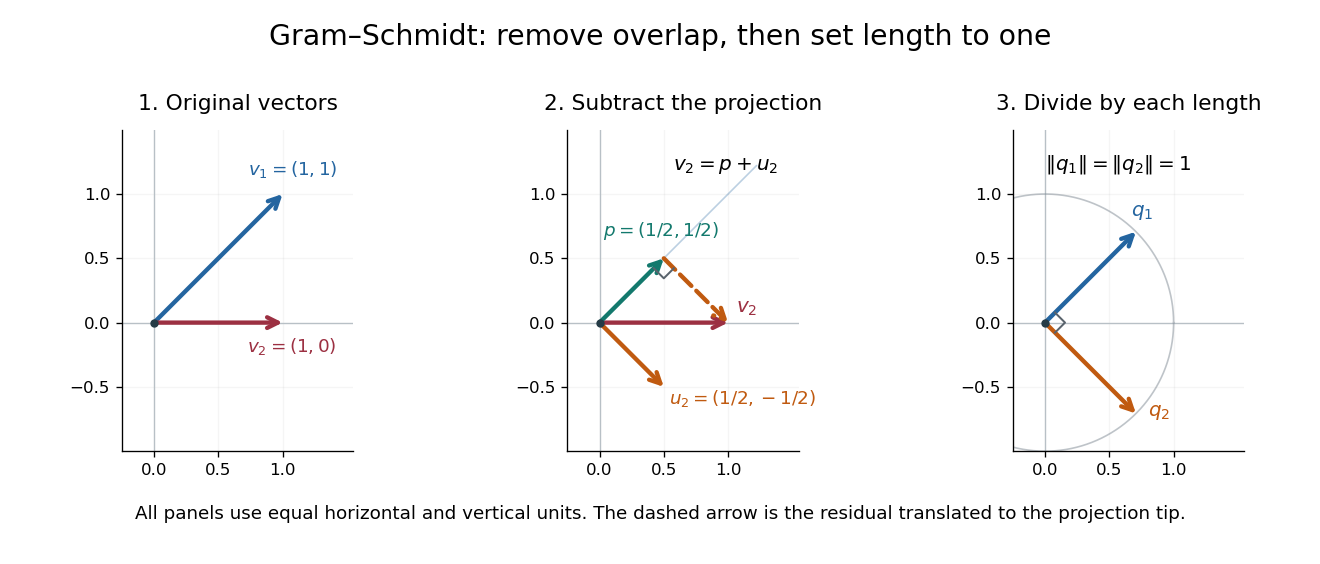
Gram-Schmidt orthogonalization in : input vectors, subtraction of an orthogonal projection, and an orthonormal basis
. Details. For a full three-dimensional calculation, use the ordinary dot product and the input vectorsThe first two steps giveAt the third step, the inner products are and . ConsequentlyThe three numerator vectors have pairwise dot products and squared Euclidean norms . Thus the displayed outputs are indeed an orthonormal basis, and the three nonzero remainders also confirm linear independence of the inputs. Keeping the removed coefficients produces the QR decomposition below.
An immediate reward is a reusable orthogonal projection: once an orthonormal basis of a vector subspace is known, any vector hasFor the linear span of just the first two inputs in the three-dimensional example, gives . Its orthogonal projection residual is , visibly in the missing orthogonal direction. This is the geometry behind the linear least-squares problem.
The formulas above describe exact arithmetic. With floating-point arithmetic, subtracting an orthogonal projection nearly equal to the input can leave a small remainder; dividing by its small norm can magnify existing roundoff error. The Classical Gram-Schmidt and Modified Gram-Schmidt arrangements agree in exact arithmetic but can give different rounded results. Exact linear dependence and a small computed remainder therefore require different judgments in a numerical implementation.[ref]
https://nhigham.com/wp-content/uploads/2023/10/high95m.pdf. Higham, The Test Matrix Toolbox for Matlab, §8, p. 22
For a linearly independent ordered family in a real inner product space, require each unit vector to lie in the span of the first inputs and be orthogonal to all earlier inputs. That orthogonal part of the successive span is one-dimensional. Subtracting the earlier orthonormal components gives its nonzero generator . Every possible unit choice is therefore . Since , the positive normalization fixes the sign uniquely. This distinguishes uniqueness of the normalized ordered construction from the many possible orthonormal bases of the whole space.
Classical Gram-Schmidt computes all orthogonal projection coefficients from the original input , then subtracts their sum as in the displayed Gram-Schmidt process formula.
Modified Gram-Schmidt starts with and, for each retained orthonormal vector in order, replaces by . Each orthogonal projection coefficient uses the current remainder. In exact arithmetic, subtracting earlier orthogonal directions does not change the inner product with , so the final equals the Classical Gram-Schmidt remainder ; then divide by if it is nonzero.
A reduced QR decomposition of an matrix over the real numbers with full column rank, , writes , where is with orthonormal columns and is a upper triangular matrix with positive diagonal. Applying the Gram-Schmidt process to the columns of constructs and records the coefficientsThis last column identity is exactly the matrix multiplication . The upper triangular matrix records that the th input uses only the first new directions, while its positive diagonal records the norms of the nonzero orthogonal projection residuals. Since , one also has ; denotes the transpose and the identity matrix. Over the complex numbers, use the conjugate transpose in these identities.
For the three-dimensional Gram-Schmidt process example, the exact matrices areFor example, the last column reconstructs asThe diagonal entries are approximately . Each is a norm of the new direction before it was scaled to length one.
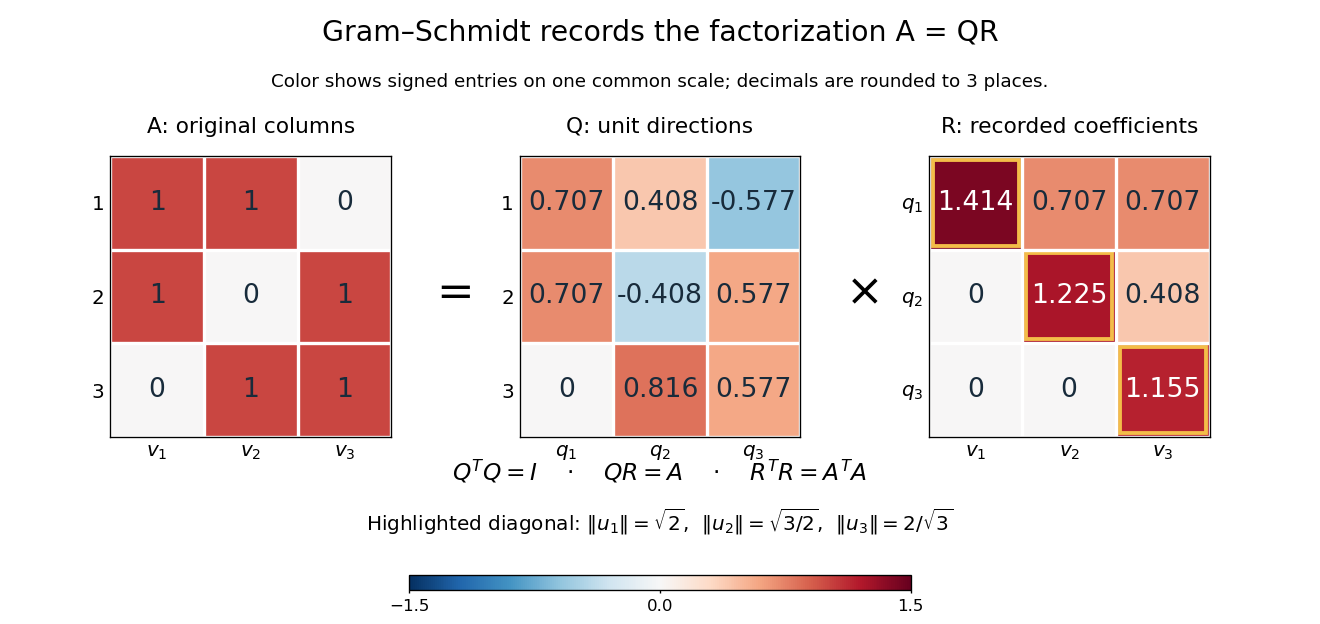
The computed QR factorization: input matrix , orthonormal columns of , and the upper triangular matrix of orthogonal projection coefficients
. Details. For a linear least-squares problem, the orthogonal projection of onto the column space of is . Hence the minimizing coefficients solve the linear system by back substitution. Let consist of the first two columns of the example; its reduced factors are and the leading block of . For , the linear system isThus , agreeing with the orthogonal projection computed above, and the minimum Euclidean norm of is . The QR decomposition separates building an orthonormal basis from recovering coefficients in the original basis.[ref]
https://ocw.mit.edu/courses/18-065-matrix-methods-in-data-analysis-signal-processing-and-machine-learning-spring-2018/resources/lecture-9-four-ways-to-solve-least-squares-problems/. Strang, MIT 18.065, Lecture 9: Four Ways to Solve Least Squares Problems
Let with and square invertible upper triangular . The normal equations for linear least squares reduce from to the system in the title. It is solved by back substitution. The geometric identity proves existence and uniqueness of the minimizer. For tall , is an orthogonal projection, not the identity on the entire observation space.
Let be block diagonal with blocks . If a real invertible matrix commutes with , its QR decomposition , with orthogonal and upper triangular with positive diagonal, has both and . Indeed , so is orthogonal and upper triangular in blocks. Orthogonality forces its off-diagonal blocks to vanish. Its diagonal blocks are . For with , this block is . Orthogonality of its columns forces , and hence each block is the identity. Thus , proving the claim.
If a real -by- matrix has full column rank, with , then is positive-definite. Its upper-triangular Cholesky decomposition , with positive diagonal, is unique. Defining gives and . Any other such factorization yields another Cholesky factor of , so its and then its must agree. This proves existence and uniqueness; it does not assert that forming is the most numerically stable algorithm.
For a full-column-rank matrix , extend the thin QR decomposition to an orthogonal matrix . Thenso maps the column space of onto the first coordinate directions. Successive Householder transformations construct the same reduction without first forming a full orthogonal basis.
A linear least-squares problem minimizes over . If has full column rank, orthogonality reduces it to the upper-triangular system formed from the leading block of and the leading entries of .
For a symmetric bilinear form , the same projection formulaproduces a -orthogonal basis whenever the chosen pivots are nonzero. Reordering the input vectors can avoid a zero pivot when a suitable anisotropic vector remains.
Articles by others on the same topic



Appears to be analogous to the dot product, but also defined for infinite dimensions.