A Gaussian process is a stochastic process whose every finite vector of values has a multivariate normal distribution. Its law is determined by its mean and covariance functions.
Gaussian process regression estimates an unknown function by assigning its values a Gaussian process law, then conditioning on observed values, often with independent Gaussian noise. The covariance function expresses the proposed relation between nearby inputs; the conditional multivariate normal distribution gives the resulting Gaussian process regression posterior. Its conditional mean provides a prediction and its conditional variance quantifies uncertainty under the chosen model. The index set can represent spatial locations or other inputs as well as time.
Let and let be a centered Gaussian process whose increments are independent of the past filtration, with deterministic variance . Its displayed exponential is a positive martingale. Indeed, is a centered Gaussian random variable with variance , so the Gaussian moment-generating function givesThe sign-reversed process has the same variance and the same conclusion. Continuity of paths is unnecessary for this conditional-expectation argument.
A centered continuous stationary scalar Gaussian process of positive variance can be Markov only if its covariance satisfies the displayed equation for . Gaussian conditioning makes the future conditional mean ; the Markov property then forces the equation by conditioning a future observation on the present and past. Conversely this equation makes the Gaussian residual future independent of the past, proving the Markov property. In the nondegenerate decaying case the covariance is a single exponential. A sum with positive coefficients and distinct positive decay rates fails the equation and hence is not scalar Markov.
For independent standard normal variables and at each fixed time, the series defines in . Every finite linear combination is an limit of Gaussian variables and is Gaussian. Thus this constructs a Gaussian process with the Gram covariance kernel . It supplies no sample-path continuity without additional assumptions.
The canonical distance is the L2 norm of an increment of a Gaussian process. It is a pseudometric, since distinct parameters may represent equal random variables almost surely. Its metric covering number appears in the Dudley entropy integral. For standard fractional Brownian motion, ; a normalization with twice the covariance function multiplies this distance by .
A fractional Brownian motion with Hurst exponent is a centered Gaussian process with the displayed standard covariance function and a continuous modification. Its increment variance is . Some sources omit the factor , multiplying the process by ; the corresponding increment variance is then . Its canonical pseudometric of a Gaussian process is proportional to , which gives finite expected value of its absolute supremum on compact intervals through the Dudley entropy integral.
For fractional Brownian motion, controls the variance of increments and the scaling of its finite-dimensional distributions. Larger means smaller increment variance on intervals shorter than one and greater sample-path Hölder continuity.
For centered multivariate normal distributions, if for every pair, then the displayed comparison holds. For a quick proof, make independent and set . Apply Gaussian integration by parts to . With softmax function weights and , the derivative of is . Since , let . Singular covariance matrices follow by adding identical small independent normal noise to both vectors and taking a limit.
For centered multivariate normal distributions represented by vectors with equal corresponding variances and for all distinct indices, for every threshold vector. In particular the supremum of is stochastically smaller than the supremum of . Equal corresponding variances are essential to this formulation. The related Sudakov-Fernique inequality compares expected values of maxima using variances of increments and does not require equal pointwise variances.
A Gaussian process has a mean-square derivative at when its difference quotients converge in L2 space. The mean-square convergence need not give differentiable sample paths. For a centered stationary process with twice continuously differentiable covariance function , the difference quotients are Cauchy in L2 space, since their covariance is a rectangular average of . Their limits form a Gaussian process with covariance function .
For a centered Gaussian process with covariance function , twice continuous differentiability of and differentiability of at zero imply a differentiable modification of a stochastic process on compact intervals. The even function satisfies , so the mean-square derivative has variance of increments . A normal distribution has fourth absolute moment three times the square of its variance, so Kolmogorov continuity theorem gives a continuous modification of . The mean-square fundamental theorem of calculus identifies its path integral with a modification of a stochastic process of . This argument does not require integrability of or continuity of .
If an L2 space-valued map has a continuous mean-square derivative , then its increments equal the Bochner integral of . To see this, for each partition interval , continuous linear observations and the scalar mean-value bound give . Sum these errors. Uniform continuity of makes the total error tend to zero as the mesh tends to zero, while the Riemann sums converge to the Bochner integral. This proves the fundamental theorem of calculus in L2 space. If a Gaussian process derivative also has a continuous modification, its anchored path integral therefore produces a differentiable modification of a stochastic process of the original Gaussian process.
Gaussian process classification links latent variables from a Gaussian process to class probabilities. A binary probit regression likelihood is under conditional independence. The posterior distribution of the latent values is not a normal distribution.
This covariance function is periodic with period . Map time to the circle and pull back a Gaussian kernel; since , this proves positive semidefiniteness. A Gaussian process with this kernel has and therefore repeats at every fixed phase. Replacing the inner by changes the actual period to .
A zero-mean Gaussian process need not have zero average in each realization. For the periodic covariance function, the constant Fourier component iswhere is a modified Bessel function. Replacing by gives a Gaussian process with kernel . This is a positive-semidefinite kernel because it is a covariance after a linear transformation, and each sample has zero period average. The real integral representation of the modified Bessel function I0 yields the displayed constant.
Let latent values have a multivariate normal distribution , and observe with independent Gaussian noise . Integrating over gives , where . If is positive-definite, its log-marginal likelihood isThe first term measures the residual under the proposed covariance matrix; the determinant term accounts for the volume of the proposed observation law. Both matter when comparing covariance function parameters. With a single observation, and , this reduces to .[ref]
Gaussian Processes for Machine Learning by Carl Edward Rasmussen and Christopher K. I. Williams. Chapter 2, equation (2.30); nonzero-mean extension by centering
A positive-definite observation-noise covariance matrix makes positive-definite even when is singular; mutually independent errors with strictly positive variances are one sufficient case. If is singular, a Gaussian observation law still exists but has no ordinary density on the full observation space; the inverse-and-determinant formula above is then not valid. This is a likelihood for kernel and mean parameters after latent-value integration, rather than an assertion that estimated parameters have no further uncertainty.
For a Gaussian random vector and an -Lipschitz function in the Euclidean norm, put . If , the Gaussian concentration inequality givesand thereforeWrite with a standard Gaussian random vector . The composed function has Lipschitz constant at most . The Gaussian logarithmic Sobolev inequality and Herbst argument give the exponential bound, and the Chernoff bound supplies the tails.[ref]
Probability in High Dimension by Ramon van Handel. Theorems 3.24–3.25 and their exponential-moment proof
For example, has , so its deviations depend on the largest covariance eigenvalue rather than directly on the number of coordinates. The center can still grow with dimension. If , is constant almost surely and every positive deviation has probability zero.
For a standard Gaussian vector and a smooth Lipschitz function with , represent its centered value as the terminal martingale . The Itô formula gives gradient integrand , whose norm is at most . Its terminal quadratic variation is therefore at most . The Dambis-Dubins-Schwarz theorem bounds the terminal deviation by a maximum of Brownian motion over . Symmetry, the Brownian reflection principle, and the Gaussian tail bound give the displayed inequality. The square on the Lipschitz constant is essential by scaling.
For independent and identically distributed random variables with a centered multivariate normal distribution, a continuously differentiable function with bounded gradient, and a convex function for which the expressions are integrable, the displayed inequality holds. First apply Jensen inequality conditionally to . For the Gaussian rotation of independent copies, the chain rule gives . A second application of Jensen inequality to the uniform measure on , followed by the Gaussian rotation of independent copies, proves the inequality. The useful choice yields a Gaussian concentration inequality through an exponential moment of an absolute standard normal variable.
Let be a centered Gaussian process with a separable version: its relevant suprema are captured by a countable dense index subset. Give the canonical pseudometric of a Gaussian process , and assume it is totally bounded. With metric covering number and diameter , the Dudley entropy integral boundsfor a universal constant . Finiteness of the integral gives a finite expected supremum. For an absolute supremum, include an anchor: . The anchor term cannot generally be omitted.
The proof builds successively finer nets. Write each increment as a telescoping sum between neighboring net scales, bound each finite Gaussian maximum by its scale times the square root of the logarithmic net size, and sum over scales. This becomes the displayed entropy integral.[ref]
The version assumption is substantive. If is uniform on and , every finite vector is zero almost surely and is therefore a degenerate Gaussian vector; the canonical pseudometric is identically zero. Yet for every outcome. Its all-zero separable modification has supremum zero. Finite-dimensional laws alone do not control the supremum of an arbitrary uncountable version.
An isonormal Gaussian process over a real Hilbert space is a centered Gaussian process satisfyingIt turns the geometry of into the covariance structure of a Gaussian family.
For any real separable Hilbert space , any orthonormal basis and independent standard normal random variables , the displayed series converges almost surely for each fixed and in L2 space. Indeed, the Parseval identity for a Hilbertian basis gives , so the partial sums form an L2 space-bounded martingale. The martingale convergence theorem supplies both limits. Every finite linear combination has the normal distribution with variance . Thus its finite-dimensional characteristic function is , independent of the chosen orthonormal basis. This proves equality of the finite-dimensional distributions of the resulting isonormal Gaussian processes; pathwise equality needs a coupling.
For an isonormal Gaussian process on a real Hilbert space and , the positive density has expectation one and defines an equivalent probability measure. Under this measure, has mean and the same covariance as before. The shifted family is again an isonormal Gaussian process. This follows by evaluating the joint Gaussian exponential formula for any finite collection of arguments. It is the Hilbert-space version of exponential tilting.
Gaussian white noise is a generalized Gaussian process with zero mean and covariance proportional to a Dirac delta function in time, and possibly in space. It is the formal time derivative of Brownian motion and has independent fluctuations on disjoint time intervals.
Observe on , where is an unknown deterministic drift and is standard Brownian motion. The observation against a deterministic test function is , with covariance . Gaussian white noise is represented by an isonormal Gaussian process on test functions rather than a pointwise noise function. Taking is the usual statistical scaling.
Generalized Gaussian white noise over a real Hilbert space is an isonormal Gaussian process with covariance . Its law is carried on a larger observation space; the identity is not the covariance of an infinite-dimensional -valued Gaussian measure because it is not a trace-class operator. A deterministic signal defines a translated observation law with Radon-Nikodym derivativeIn an orthonormal basis, is a stochastic series with total variance , not an inner product of two -valued observations. The formula follows from the Cameron-Martin theorem for a Gaussian measure in its generalized white-noise version, or from finite-dimensional Gaussian likelihood ratios. On , generalized noise can be realized on tempered distributions; an unweighted global negative Sobolev space is not automatically a suitable almost-sure support on an unbounded domain. The stochastic series avoids imposing that unsupported regularity.
The Gaussian sequence model observeswhere the are independent standard normal variables and the unknown signal commonly lies in . It is the coordinate representation of a Gaussian white-noise experiment.
A Bernstein-von Mises theorem identifies a centered, scaled posterior distribution with the Gaussian law suggested by an efficient likelihood approximation. In an infinite-dimensional model, this conclusion requires control of prior-induced bias; a positive marginal prior density alone does not state enough assumptions.
A concrete calculation shows the issue. In the Gaussian sequence model, let , with , and assign independent priors with every and . Put . For a nonzero coefficient vector , the linear functional has the exact posterior lawThe efficient observation statistic exists as a Gaussian noise pairing even though itself is not in . dominated convergence gives . To center at , however, one also needsThe remaining noise part of the scaled centering error has variance . Under this displayed bias condition, the conditional law of converges in total variation distance, in sampling probability, to . Without bias control, convergence of posterior variances is insufficient. The calculation is specific to conjugate product Gaussian priors; general nonparametric results impose their own prior, truth and functional regularity hypotheses.[ref]
Nonparametric Bernstein-von Mises theorems in Gaussian white noise by Ismaël Castillo and Richard Nickl. 2013, Section 2.3.1, linear-function inference; the conjugate-coordinate calculation is derived here
A Gaussian net test turns a finite covering of an alternative into a test with an explicit covering-number cost. In the Gaussian sequence model , compare a null with centers in L2 space satisfying . Put and reject if anyEach pairing is well-defined as an isonormal Gaussian process pairing even though the noise sequence itself is not in L2 space. Under the null, it is centered normal with variance before subtracting the threshold. The Gaussian tail bound and union bound giveIf for some center, the mean of that center's displayed statistic is at least , by the Cauchy-Schwarz inequality. ThusA radius- net with centers in the separated alternative supplies such a test for its entire covered set. To make the first error small, the squared separation must dominate . This is why metric complexity, rather than just individual Gaussian tails, enters composite testing.
Because Gaussian white noise is not an vector, least squares over is defined by maximizingover , with the noise pairing interpreted through an isonormal Gaussian process. Differences of this contrast equal the formal differences of squared residual norms.
A centered continuous Gaussian process that is also a martingale has independent increments. Every future increment has zero covariance with every finite vector of past values by the martingale property; uncorrelated jointly normal variables are independent.
Every centered continuous Gaussian martingale starting at zero is a deterministic time change of Brownian motion. Its clock is the continuous increasing function , and .
If a continuous local martingale starts at zero and has deterministic continuous quadratic variation , the Dambis-Dubins-Schwarz theorem gives . It is therefore a centered Gaussian process. The converse follows from independent increments of a Gaussian martingale.
The exponential covariance function on the real line isHere is the marginal variance and the correlation time. For , the centered stationary Gaussian process with this covariance function is the Ornstein-Uhlenbeck process solvingwith the initial value independent of future Brownian motion increments. The explicit stochastic-integral solution gives . Its conditional future equals the exponentially decayed present plus independent Gaussian noise, giving the Markov property.
The cusp at zero determines its roughness. For ,which diverges. Thus a continuous version exists, but it has no mean-square derivative of a Gaussian process. A smooth-looking covariance away from the diagonal does not imply differentiable paths.[ref]
A Gaussian random field is a spatially indexed Gaussian process; its law is determined by its mean and covariance kernel.
A centered Gaussian random field with the displayed covariance. It has independent increments over disjoint rectangles. At fixed positive , is standard Brownian motion in . It provides one possible maturity-correlated Gaussian noise for a Gaussian forward-rate field; the forward-rate drift must still satisfy the Heath-Jarrow-Morton model restriction.
Let be a standard Gaussian random variable and independent symmetric signs, independent of . The stationary sequence has standard Gaussian marginals and identity covariance, but is not jointly Gaussian. For two coordinates its moment-generating function is , rather than . Consequently a field's Gaussian one-point densities and two-point covariance alone do not justify an exponential moment of a Gaussian linear functional.
If is a centered Gaussian random field, the transformation retains zero mean and introduces a three-point connected correlation function at first order in . Wick contractions give times the sum of products of two covariances. The corresponding local cosmological model uses .
If a linear functional of a real Gaussian random field exists in mean square, it is a Gaussian random variable. Completing the square in its density givesFor a complex linear functional , apply this to ; then .
For a real standard Gaussian random vector , a real symmetric matrix , and strictly positive,Diagonalize and complete the square in each coordinate. Failure of strict positivity makes the positive exponential integral divergent. The same formula extends to a self-adjoint trace-class quadratic form of an isonormal Gaussian process, with square-summable linear coefficients and a Fredholm determinant. A linear-plus-quadratic Gaussian random field functional is reduced to this form by its covariance square root.
A stationary Gaussian random field has Gaussian finite-dimensional distributions invariant under common spatial translations. Its mean is constant and its two-point covariance depends only on the separation of the points.
For a zero-mean stationary Gaussian random field , the unnormalized autocorrelation function of a random field isIt depends only on the separation , and is the pointwise variance. If , the normalized correlation is ; the two conventions have different units.
For a mean-square continuous field, its spectral measure of a stationary random field obeys . If is integrable, an ordinary power spectral density exists and, in the angular-wavevector convention,Thus has density . A spectral measure need not have a density: a spatially constant centered Gaussian field of variance has and spectral measure , concentrated at zero wavevector. Calling every spectrum an ordinary function would miss this case.[ref]
Gaussian Processes for Machine Learning by Carl Edward Rasmussen and Christopher K. I. Williams. Chapter 4, Section 4.1, Bochner representation and spectral-density distinction; Fourier factors explicitly chosen here
For , the covariance function is . It involves fourth moments and is not determined by the two-point correlation of in general. For a centered Gaussian pair the fourth-moment identity reduces it to . This extra Gaussian hypothesis must be stated before using that reduction.
For a centered Gaussian random field with covariance and a sufficiently regular functional , the Furutsu--Novikov formula is the functional integration by parts identityIt closes moment equations for systems driven multiplicatively by Gaussian fluctuations.
When a random medium's longitudinal correlation length is much shorter than the scale on which a propagating envelope changes, the Markov approximation replaces the longitudinal covariance by white noise with the same integrated covariance. Field-moment equations then become local in propagation distance.
The Gaussian free field is a centered Gaussian random field whose covariance is the Green kernel of a Laplace operator. It has discrete versions on graphs and continuum versions as a random generalized function on a domain.
The discrete Gaussian free field on a transient weighted graph is the centered Gaussian random field whose covariance kernel is the random-walk Green function of a transient weighted graph.
A Gaussian free field with Dirichlet boundary condition is fixed to zero on a boundary set and has density proportional to the exponential of minus one half of its discrete Dirichlet energy on the remaining vertices.
Conditionally on all other values, a discrete Gaussian free field value is Gaussian with mean equal to the weighted average of its neighbors and variance equal to the reciprocal local precision.
Conditioning a Gaussian free field on its values along a boundary leaves an independent zero-boundary Gaussian free field plus the harmonic extension of those boundary values in each remaining component.
The Continuum Gaussian free field on a planar domain is a centered Gaussian process indexed by finite-energy measures or test functions, with covariance given by the Green function of the Laplacian on .
If is a conformal map, pulling back a zero-boundary Gaussian free field on gives a zero-boundary Gaussian free field on . This follows from the conformal invariance of the planar Dirichlet Green function.
For finite Borel measures of finite Green energy, the zero-boundary Gaussian free field on is characterized bywhere is the zero-Dirichlet Green function of the Laplacian.
For a Gaussian free field with boundary heights and on the two sides of the starting point, its distinguished zero-height interface has chordal law. Conditional on an initial curve segment, the field is a zero-boundary field in the slit domain plus . Its mean bracket equals minus the variation of its conditional Green covariance. Subtracting the initial harmonic function gives the corresponding coupling to a zero-boundary field.
Let be a continuous local martingale on , with deterministic , and let be a continuous nonnegative adapted finite-variation process with deterministic . Suppose and almost surely. For each real , the Itô formula showsis a complex local martingale: its two finite-variation terms cancel. Its absolute value is at most one, so it is a true bounded martingale. Consequentlywhich identifies the entire normal distribution by its characteristic function.
For example, and give . The residual-variance condition is essential for this conclusion. With and throughout, the displayed exponential is still a bounded martingale, but its terminal mean variable is the constant zero, not . In a field-revelation construction, represents a conditional mean and the remaining conditional variance; only after the latter has vanished does the martingale expectation identify the terminal sample law.
A continuum field level line is specified by the harmonic boundary heights it creates and the conditional zero-boundary field remaining on each side. Since a Continuum Gaussian free field is a random distribution, this is not the pointwise set of its zeros. For the height jump appropriate to the Green-function normalization, the zero-height line between opposite Dirichlet heights is chordal .
Fix a bounded planar domain and explicitly choose the Dirichlet form normalizationIts Dirichlet Green function of the Laplacian satisfies . Let be an orthonormal basis of the corresponding Sobolev space . The formal expansionis interpreted as a weak kernel identity. Concretely, for smooth compactly supported test functions ,The identity follows by applying Parseval's identity to the two Riesz representatives for the integration functionals. It is not a claim that arbitrary Sobolev space basis functions have pointwise values everywhere or that the series converges on the singular diagonal.
For a finite measure with finite Green energy, the same Hilbert-space identity gives . This is the square-summability condition for a Finite-Green-energy measure pairing with a Gaussian free field. An alternative energy normalization rescales both the basis and the Green kernel; specifying the factor prevents an unnoticed mismatch.[ref]
Gaussian free fields for mathematicians by Scott Sheffield. Section 2, Hilbert-space basis construction; the energy has been explicitly rescaled here
Let be a finite measure on with finite Green energy, in the normalization of the Green-kernel expansion in the Dirichlet space. For an orthonormal basis and independent standard Gaussian random variables , defineThe sum converges in L2 space, since the sum of the coefficient squares equals the Green energy. It is centered Gaussian withFor several measures, the same coefficients give their cross-covariances by the corresponding mixed Green integrals.
The joint law is independent of the chosen basis. A stronger pathwise statement needs consistent coefficients: realize the field through one isonormal Gaussian process on the Dirichlet Hilbert space and take for each basis. Then Parseval's identity makes both expansions equal to the same -pairing in L2 space. Drawing a fresh independent coefficient family for a different basis produces another field with the same law, not the same outcome-by-outcome field. This distinguishes basis invariance of a construction from an unspecified coupling of two constructions.[ref]
Gaussian free fields for mathematicians by Scott Sheffield. Sections 2.1–2.3: Gaussian Hilbert spaces and series construction
For an open , the field decomposes as , where is an independent zero-boundary Gaussian free field on and is harmonic on and agrees with the outside field in the distributional sense.
A random set is local for a Gaussian free field if, conditionally on the set and its associated harmonic function, the remaining field is an independent zero-boundary field in its complement. This extends the deterministic Domain Markov property of the Gaussian free field to appropriate random revealed domains. Arbitrary field-dependent random sets need not have this property.
For the zero-boundary Gaussian free field in the unit disc, choose the logarithmic Green normalizationFor , let be the uniform probability measure on the circle of radius about zero. The Circle-average process of the Gaussian free field is the measure pairing . This is meaningful even though the continuum field has no ordinary pointwise values: the circular measure has finite Green energy, because its diagonal logarithmic singularity is integrable.
Decreasing radius means increasing logarithmic time. Angular averaging of the Green kernel gives . Thus in L2 space as , and define by this limit; it is not a pointwise field restriction to the unit-disc boundary. The Circle-average process of the Gaussian free field is Brownian motion article verifies the covariance and continuity. For another positive Green normalization the same process is rescaled by its square root.[ref]
Gaussian free fields for mathematicians by Scott Sheffield. Section 2.8, Circle averages and thick points; logarithmic normalization specified here
In the logarithmic normalization of the Circle-average process of the Gaussian free field, the circular averages form standard Brownian motion in logarithmic radius. Let and . Averaging over the two circles gives zero by the mean value property for harmonic functions. The average of is , including equal radii by integrability of the logarithmic singularity. HenceThe pairings are jointly Gaussian and centered. Their increments on disjoint logarithmic-time intervals have zero covariance, hence are independent. Also , so the Kolmogorov continuity theorem supplies a continuous modification. Together with the limiting value , this proves the Brownian motion law.
The result describes one nested family of circle averages about a fixed center, not the field on every spatial curve as a single Brownian path. If the Green kernel is multiplied by , the covariance becomes and is standard Brownian motion.
For a measure and Green kernel , its Green energy isFinite Green energy is the variance condition needed to pair a Gaussian free field with .
Pinning a Gaussian free field at a vertex gives the field with value zero at and covarianceIt is independent of the removed scalar Gaussian mode at .
Every linear subspace that is measurable for the cylinder sigma-algebra has probability zero or one under a centered Gaussian process.
A Gaussian measure on a real topological vector space is a Borel probability measure whose image under every continuous linear functional is a one-dimensional normal distribution.
A Gaussian random variable in a Banach space taking values in a separable Banach space satisfies the displayed exponential-integrability bound for some positive . In particular every finite power of its norm has a finite expected value. The value of depends on the Gaussian measure; the theorem does not assert this for every positive .
For a centered Gaussian random variable in a Banach space, its first Gaussian chaos is the closed linear subspace of L2 space generated by its continuous linear observations. Every element is a centered Gaussian random variable, and every finite collection has a multivariate normal distribution: approximate in L2 space and pass to the characteristic function. The first Gaussian chaos supplies the scalar coordinates of its Cameron-Martin space of a Gaussian random variable in a Banach space.
A random variable in a real separable Banach space is Gaussian when has a normal distribution for every continuous linear functional . It is centered when all these expected values vanish. Its probability law is a Gaussian measure. Degenerate normal distributions are allowed.
Suppose is a nonzero separable Banach space, the Cameron-Martin space of a Gaussian random variable in a Banach space is a dense subset of , and every centered ball of positive radius has positive probability. Then is strictly increasing on . For , choose in that Cameron-Martin space of a Gaussian random variable in a Banach space with and . The closed ball of radius centered at lies in the annulus and has positive probability by the symmetric Gaussian translation lower bound. The nonzero assumption is necessary: on the distribution function equals one everywhere.
For with injective covariance operator of a Gaussian measure, its translated law is an equivalent probability measure to if and only if , the Cameron-Martin space of a Gaussian measure. For such ,The series has mean-square convergence and converges almost surely under , with normal distribution . Its exponential density has expected value one by the moment-generating function of a normal distribution. Finite-dimensional projections give the formula by ratios of multivariate normal densities; convergence of these likelihood ratios gives the infinite-dimensional result. The expression is only formal when the sample is outside . For , translation gives mutually singular measures.
For a centered Gaussian random variable in a Banach space, a Borel set , and in its Cameron-Martin space of a Gaussian random variable in a Banach space, the Cameron-Martin theorem for a Gaussian measure gives the translated density . The joint law of is invariant under simultaneous negation. Averaging the two density formulas therefore replaces by , proving the lower bound. No convexity of is required.
For a centered Gaussian measure on a real Hilbert space with injective covariance operator of a Gaussian measure , its Cameron-Martin space is , with inner product . In an orthonormal basis satisfying , it consists of exactly the vectors for which . It is complete in this stronger norm even if its range is not closed in the ambient norm. Its importance is that it describes precisely the translations that preserve the null sets of the Gaussian measure, as in the Cameron-Martin theorem for a Gaussian measure. For generalized Gaussian white noise over , the corresponding Cameron-Martin space is L2 space itself.
Let be the first Gaussian chaos of a centered Gaussian random variable in a Banach space. By Fernique's theorem, is a Bochner integral in . The map is injective, because implies for every continuous linear functional , hence . Its range becomes a Hilbert space under . The embedding in is continuous by Cauchy-Schwarz inequality. Its reproducing property is . Thus this is the Reproducing kernel Hilbert space of the random variable, including degenerate laws. For , the scalar coordinate has variance ; it is generally a measurable linear coordinate rather than a continuous functional on .
The covariance operator of a Gaussian measure on a real Hilbert space satisfies . A positive self-adjoint operator is the covariance of a Hilbert-space-valued Gaussian random variable exactly when it is trace-class.
If with and , thenconverges in mean square and almost surely in the Hilbert space, and has Gaussian law .
A Bayesian inverse problem combines a prior measure on an unknown with a likelihood for observed data . When the likelihood is proportional to , Bayes' formula gives
Suppose an unknown has prior distribution and its conditional observation law has jointly measurable Radon-Nikodym derivative relative to a fixed observation law . If for -almost every pair, thendefines the posterior distribution for almost every observation. Indeed, for almost every , so Tonelli theorem gives . Hence is finite almost everywhere, and positivity of and Fubini's theorem give almost everywhere. The data law is , and integration of the proposed posterior against this data law recovers the joint law. This proves the conditional distribution property and also shows that the data law is an equivalent probability measure to .
A Bayesian inverse problem is well posed in total variation when a unique posterior exists for every datum and the map from data to posterior is continuous in total variation distance.
A Bayesian inverse problem is well posed in Hellinger distance when every datum determines a unique posterior and the posterior depends continuously on the data in Hellinger distance. Since posterior measures are dominated by the prior and squared Hellinger distance is at most twice total variation distance, total-variation well-posedness implies Hellinger well-posedness.
An Ornstein-Uhlenbeck process combines mean reversion with continuing random fluctuations. In the scalar model, its stochastic differential equation iswhere is a standard Brownian motion. The drift points towards : it is negative above and positive below it. The coefficient sets the speed of mean reversion, while sets the strength of the random forcing. We consider a fixed or normal initial value independent of future Brownian increments, giving a Gaussian process and a Markov process.
For a stipulated example, use , , and the fixed initial value , in arbitrary consistent state and time units. Then the expected value relaxes as and the variance grows as . At time one they are about and ; the limiting variance is one. The sample paths keep fluctuating even after the expected value is close to two. The Ornstein-Uhlenbeck transition distribution describes this evolving uncertainty; Ornstein-Uhlenbeck stationary initialization instead starts with that limiting normal distribution already in place.
A physical motivation is the velocity of a particle undergoing Brownian motion: linear drag removes a persistent initial velocity, while random forcing continually renews it. The original calculation gives a normal distribution for the velocity after subtracting its exponentially decaying initial contribution, with decay rate equal to the friction coefficient divided by the particle's mass.[ref]
On the Theory of the Brownian Motion by G. E. Uhlenbeck and L. S. Ornstein. On the Theory of the Brownian Motion, abstract: velocity minus its decaying initial contribution; friction coefficient divided by mass
A position coordinate in an overdamped harmonic optical trap gives another interpretation of the same scalar equation, with for spring constant and drag coefficient . Its physical assumptions and connection to measurements are developed in thermal calibration of an optical trap.For overdamped Brownian motion in potential , the relaxation time is and the equilibrium covariance function is . Expanding the squared displacement between two equilibrium samples gives the title expression. Initializing the particle exactly at the centre instead gives variance . Both are valid but concern different initial ensembles; their saturation values differ by a factor of two. These formulas neglect inertia and require times long compared with momentum relaxation.
For a fixed initial value , the Ornstein-Uhlenbeck process has the normal distributionThe two parameters of are the expected value and variance, not the standard deviation. At the variance is zero and the value is fixed. More generally, its transition kernel over any interval of length has conditional expected value and conditional variance when the current value is . The coefficients depend on elapsed time; the initial probability distribution determines whether the resulting stochastic process is stationary.[ref]
In the stipulated example , , , , the expected value at time two is and the variance is . The initial distance from two has fallen by a factor , but the standard deviation has grown to about . Approaching the reference level in expected value is compatible with growing uncertainty from a perfectly known initial value.
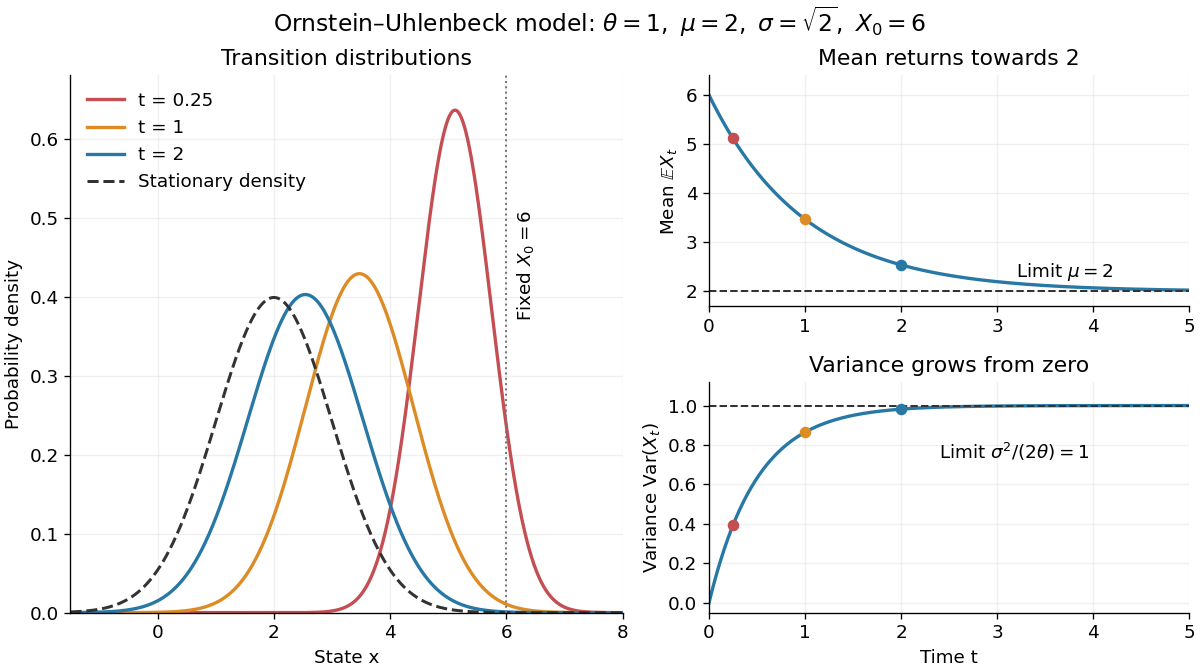
Ornstein-Uhlenbeck transition densities, mean relaxation and variance growth from a fixed initial value
. Details. 
The solid probability density functions use times , and ; the dashed curve is the limiting normal distribution with expected value two and variance one. The curves are exact model predictions. There is no ordinary density for the fixed value at time zero.
A short derivation uses the integrating factor . The Itô product rule gives , henceThe stochastic integral has zero expected value. The Itô isometry gives its variance as . Its deterministic integrand makes it a Gaussian random variable, yielding the displayed normal distribution. Shifting the integration interval gives the same transition kernel from any later time.
Set and draw independently of future Brownian increments. The Ornstein-Uhlenbeck process is then a strictly stationary process, withEvery time has the same normal distribution, and the covariance function depends only on the time lag. For a Gaussian process these properties also make all its finite-dimensional distributions invariant under a common time shift. The stationary distribution balances the continual random forcing against the contracting drift.[ref]
Applied Stochastic Differential Equations by Simo Särkkä and Arno Solin. Applied Stochastic Differential Equations, Example 6.8, printed pp. 91–92, equations (6.73)–(6.76): steady-state variance and covariance
With a fixed , the covariance function instead isIn particular, it is zero when , since the initial value has no uncertainty. The second term records the fixed start; it is the general scaling of the zero-start Ornstein-Uhlenbeck covariance. The pure exponential covariance function displayed above assumes stationary initialization. For a fixed start, that function emerges as the late-time limit at fixed lag, while the one-time probability distributions approach by convergence in distribution.
For the stipulated , , , stationary initialization has variance one from the outset. Its autocorrelation is , so the correlation time is one: a lag of one reduces the autocorrelation to . Its raw second moment includes the squared expected value; it must not be confused with the covariance.
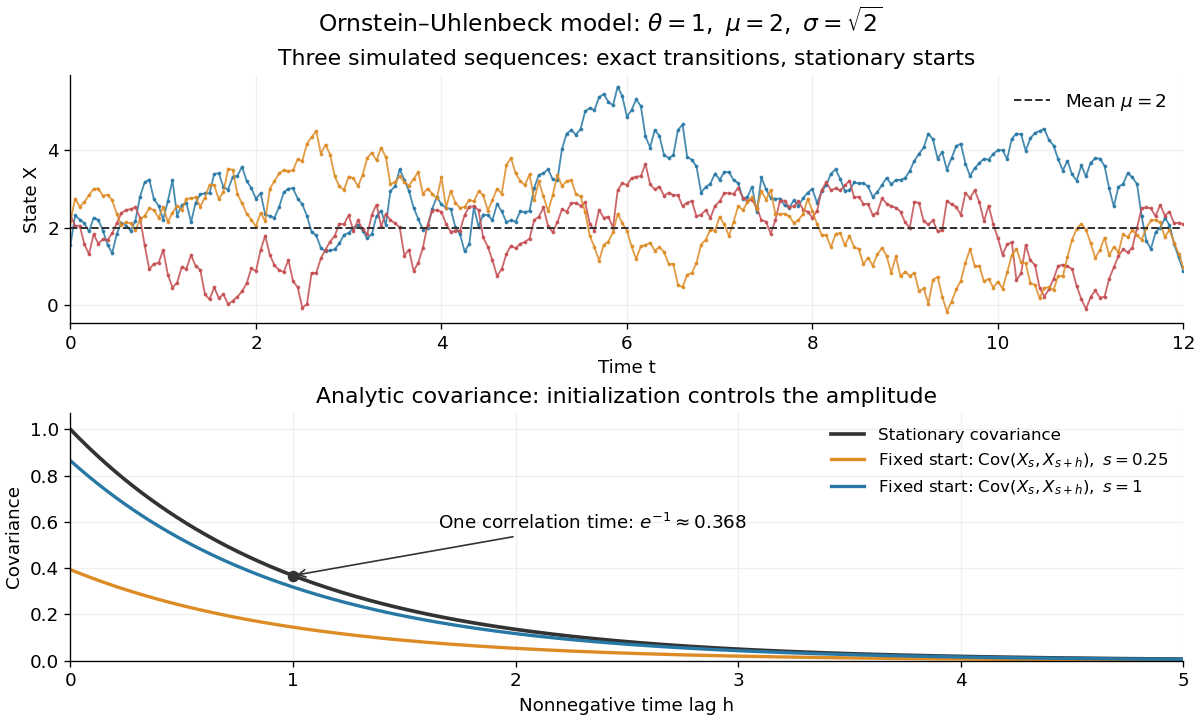
Simulated stationary Ornstein-Uhlenbeck samples and analytic covariance compared with a fixed start
. Details. 
The upper panel shows three simulated sequences with independent stationary initial values and exact transitions at spacing . Joining their points only guides the eye; it does not simulate a continuous sample path between those points. The lower panel shows analytic covariance functions: the stationary curve and, for comparison, for fixed initialization at two different ages . These are simulated samples and model curves, not measured trajectories or empirical covariance estimates.
For any step , set . The Ornstein-Uhlenbeck transition distribution gives the exact updateusing a fresh independent standard normal random variable for each interval. The update reproduces the joint probability distribution on the selected time grid. It can start from a fixed value or use Ornstein-Uhlenbeck stationary initialization. On an equally spaced grid it is an autoregressive process of order one after subtracting . Its stationary variance follows directly from .
For the stipulated example with , and the innovation variance is . Given , the next conditional expected value is about and the conditional standard deviation is about .
The Euler-Maruyama method instead approximates the same stochastic differential equation byFor its stationary variance solves , givingAt in the example, this is , about above the continuous model's stationary variance. If , this Euler recurrence has no finite stationary variance despite the stable continuous model. Exact transitions avoid this discretization error at sampled times; neither update alone determines the unresolved motion between samples.
For an adapted stationary process with the displayed bounds, the Itô formula and stationarity give . The Cauchy-Schwarz inequality makes each integrand nonnegative, so equality holds almost everywhere. Then , proving for almost every time and outcome. Thus the process solves the Ornstein-Uhlenbeck stochastic differential equation and its initial value, rather than stationarity alone, determines its coupling with W.
Two Ornstein-Uhlenbeck processes with the same driving Brownian motion have the displayed difference. If is standard normal and independent of future Brownian increments, replacing it by produces another stationary process with the same covariance and second moment, but a different pathwise coupling. Equal initial values are necessary for indistinguishability of stochastic processes.
For , set and . This is a Brownian motion in the new filtration; its independent Gaussian increments have variance equal to elapsed time. The Itô product rule gives . Its initial value is , independent of future W increments, and its covariance function is . Consequently it is a stationary Ornstein-Uhlenbeck process. The quadratic variation of the unscaled time change is , not .
The linear stochastic differential equation has the explicit solution . Its integrating factor is . For , an independent initial normal variable of variance makes its zero-mean Gaussian process stationary.
Let , , and , . The logarithm is a centered Gaussian random variable of variance . Squaring the stochastic kernel and integrating proves this formula. The exponential moment of a Gaussian linear functional gives and the displayed long-time growth exponent. Positive moment growth with zero mean strain reflects the breadth of the log-normal distribution; it does not imply positive growth of the mean logarithm.
The weighted strain density in Ornstein-Uhlenbeck multiplicative amplification evolves under . Setting eliminates its first derivative. Shifting and scaling to gives . The quantum harmonic oscillator levels yield the displayed eigenvalues. Its ground state is the dominant positive mode; higher sign-changing modes may occur in a transient expansion.
For a thermal inertial Langevin equation conditioned on fixed initial position and velocity, the centered displacement is . With the fluctuation-dissipation relation for a Langevin particle, and integrating the squared kernel gives the displayed variance. At short times it is per component; at long times it is . Averaging initial velocity over thermal equilibrium adds a ballistic contribution and gives per component.
For deterministic and real , the Ornstein-Uhlenbeck stochastic differential equation has solutionMultiply by the integrating factor and apply the Itô product rule to obtain it. The stochastic integral is centered Gaussian and its variance, by the Itô isometry, isThus the apparent zero-denominator case is ordinary Brownian motion, and negative gives growing rather than mean-reverting fluctuations.
For , take an independent initial value . Adding its variance contribution gives the time-independent variance and covariance function , making the process stationary. A deterministic zero start instead has the transient variance in the display. These are different initial ensembles, so their variances should not be interchanged.
For with , the explicit stochastic integral is . The Itô isometry on the overlap of the two integration intervals gives the displayed covariance. The second exponential records the zero initial condition; removing it gives the stationary Ornstein-Uhlenbeck process covariance.
A multivariate Ornstein-Uhlenbeck process obeys . If every eigenvalue of has positive real part, its stationary covariance is the unique solution of .
Let be the centered stationary solution of , where is a real matrix with eigenvalues of positive real part and is an -dimensional Brownian motion. Use the two-sided angular-frequency conventionThe Ornstein-Uhlenbeck power spectrum isThe stationary linear filter has transfer matrix , so the output spectral matrix is , explaining the adjoint and sign of the second factor. This matrix is Hermitian positive semidefinite for every frequency.
For scalar with , the spectrum is , proportional to a Cauchy distribution probability density function. Its inverse-frequency integral gives variance , checking the normalization. With ordinary frequency and inverse transform , use . A one-sided positive-frequency spectrum doubles this density away from zero. These conventions must be matched when comparing a theoretical spectrum with measured spectral power.
In the classical thermal model, a coordinate in a harmonic potential obeys , where is the drag coefficient and . Its stationary one-sided spectral density per hertz is the displayed Lorentzian line shape. The integral over positive frequencies equals , consistent with the equipartition theorem. On a log-log plot the spectrum is flat for and has slope for . The crossover is determined by the restoring stiffness and drag; an added detector response multiplies the mechanical spectrum by the squared magnitude of its transfer function.
For stationary covariance , the mean over duration has variance . At this becomes . Closely sampled positions remain correlated and cannot be counted as independent.
Articles were limited to the first 100 out of 102 total.
Articles by others on the same topic
There are currently no matching articles.