Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article

The void fraction is the fraction of a mixture's local volume occupied by gas. For a horizontally uniform bubbly liquid it is the transported concentration in a one-dimensional gas-volume continuity equation. It is distinct from gas mass fraction because gas and liquid have different mass densities.
Laminar flow is a regime of fluid flow in which the motion remains organized, with neighboring fluid parcels following smooth, coherent paths rather than the irregular interacting fluctuations characteristic of turbulence. In a straight pipe, the simplest example consists of coaxial layers sliding past one another. This describes the character of the motion, not a requirement that every parcel have the same velocity. Nor does it require steady flow: a smooth profile can evolve in time as viscosity transmits motion from a newly moving wall into a resting fluid. The unsteady wall-driven solution provides an explicit example. [ref]
https://notes.shreyasmandre.com/fluid-dynamics-notes/Ch3.html. Shreyas Mandre, Fluid Dynamics Lecture Notes, section 3.3
The Reynolds pipe-and-dye experiment makes this distinction visible. A thin injected dye band can remain coherent in laminar flow, whereas irregular motion can fold it and carry dye across the pipe. However, molecular diffusion can spread dye even in laminar flow, and an inlet disturbance can move a coherent band without producing turbulence. A dye band is a streakline, not a measurement of the entire velocity field; in steady flow an ideal passive tracer's streakline coincides with a streamline. Reynolds explicitly distinguished a wandering band from one broken into eddies. [ref]
https://archive.org/stream/philtrans06508925/06508925_djvu.txt. Osborne Reynolds, An Experimental Investigation (1883), section 11, pp. 941–943
For a circular pipe of internal diameter , define the mean axial velocity using the volumetric flow rate and cross-sectional area :Here is mass density, is dynamic viscosity and is kinematic viscosity. This particular Reynolds number uses the diameter and mean velocity, not the radius or centreline velocity. Small Reynolds number generally favors laminar flow, but a single universal critical Reynolds number does not distinguish it from turbulence in all geometries and experiments. Even in a given pipe, inlet conditions and the magnitude of disturbances affect the observed onset. Reynolds demonstrated this dependence by deliberately inserting a wire coil. [ref]
https://archive.org/stream/philtrans06508925/06508925_djvu.txt. Osborne Reynolds (1883), section 23, pp. 955–956
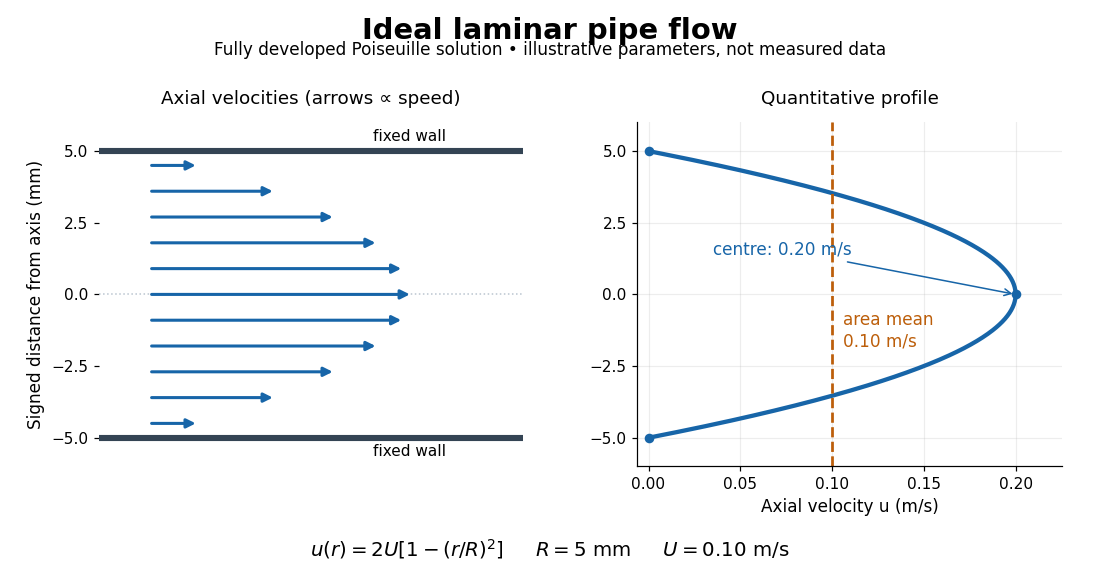
The quantitative example above assumes steady flow, incompressible flow, a Newtonian fluid with constant dynamic viscosity, a straight horizontal circular pipe of radius , stationary walls satisfying the no-slip boundary condition, and fully developed flow. The last assumption means that the axial velocity profile no longer changes downstream. A positive pressure drop over a developed length gives the Hagen-Poiseuille equation:The velocity is zero at the wall and maximal at the centre. Averaging over the circular area, whose annuli have area , gives ; averaging along one diameter would give a different answer. These assumptions produce a parabola, rather than every laminar flow having a parabolic profile. [ref]
https://notes.shreyasmandre.com/fluid-dynamics-notes/Ch3.html. Shreyas Mandre, Fluid Dynamics Lecture Notes, section 3.2.2, equations (3.9)–(3.11)
As a stipulated calculation, take , , , and , and assume the developed laminar flow above. Then , , , (about ), and . These are predictions from chosen parameters, not measurements or a claim that guarantees laminar flow in every apparatus.
The beauty of this example is that a spatially varying velocity field still gives an exact relation between two accessible measurements, pressure drop and volumetric flow rate. It predicts the hydraulic resistance . Doubling the radius therefore multiplies by sixteen at fixed pressure drop, length and dynamic viscosity, provided the model remains applicable. This makes the laminar flow model useful for sizing narrow tubes or determining dynamic viscosity. It also explains why a persistent narrow dye band can be informative without implying that the fluid is moving as a uniform plug.
An inode is a data structure describing an object in an inode-based file system. For an ordinary file, it records file metadata such as type, owner, access permissions, size and hard link count, together with information locating the contents. In the direct-reference toy layout, inode 42 points to file data blocks 7 and 9; its two names
a and b live in directory entries. Other file systems can locate contents differently, so the diagram is a model of the separation rather than a universal storage layout. [ref]https://pages.cs.wisc.edu/~remzi/OSTEP/file-implementation.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 40, sections 40.3–40.4: inodes and directory organization
An inode number is unique only within its file system among allocated objects. Two different file systems can each have inode 42, referring to unrelated files. POSIX exposes the file system's device identity as
st_dev and the file's serial number as st_ino; the pair identifies a file within a running system. Neither the bare inode number nor that pair is a permanent historical identifier: after reclamation, a later file can reuse the number. In particular, comparing an old saved number with a new one does not establish continuity of the file. [ref]https://pubs.opengroup.org/onlinepubs/9699919799/basedefs/sys_stat.h.html. The Open Group, POSIX.1-2017, sys/stat.h: joint identity from st_dev and st_ino
The design's appeal is that one inode unifies the file metadata and contents reached through several directory entries. Ritchie and Thompson's original 1974 account explicitly describes a directory entry as a name and an i-number, with the corresponding inode holding ownership, protection, size, content addresses and the hard link count. It gives a concrete early explanation of how names and file identity can evolve separately. [ref]
https://www.cs.cmu.edu/~15712/papers/ritchie74.pdf. Ritchie and Thompson, The UNIX Time-Sharing System, 1974, section 4: implementation of the file system
// Target: computer-science.bigb
NTFS is a filesystem used by Windows, organizing file metadata through a master file table and supporting features including access control lists, sparse files, named streams and metadata journaling. The metadata journal helps recover filesystem structural consistency after an interrupted operation; it does not make every application's recent data automatically durable. Files can use multiple allocation extents, and the logical byte sequence is separate from its physical placement. Exact limits and feature availability depend on the system version and configuration.[ref]
https://learn.microsoft.com/en-us/windows/win32/fileio/filesystem-functionality-comparison. Microsoft, functionality, journaling and security tables
// Target: computer-science.bigb
The File Allocation Table filesystem family tracks file storage through a table indexed by allocation cluster. A file's directory entry points to its first cluster; table entries link later clusters or mark the end of its chain. Following that chain reconstructs a fragmented file. This simple organization differs from an extent tree that describes long contiguous runs at once. FAT variants differ in entry widths and other layout rules. File length and cluster-chain traversal must agree with the on-disk metadata; the file's bytes do not necessarily occupy one contiguous interval.
// Target: computer-science.bigb
An access control list associates an object with entries describing permissions for specified users, access-control groups or principals. A file ACL might grant one access-control group read access and one user write access while denying others. The effect of multiple entries, inherited entries and defaults depends on the system's evaluation rules; treating every ACL as a simple unordered union of grants can be wrong. An ACL describes policy associated with an object, while an access check evaluates that policy for a particular operation and security context.
// Target: computer-science.bigb
A separately retained copy intended to recover files after loss or unwanted changes. A journal can be overwritten after a journal checkpoint and can faithfully commit an unwanted deletion; it does not supply that historical copy or protect against loss of the device holding the only copy.
// Target: computer-science.bigb
A Linux kernel file system whose documented file-system journaling modes provide the implementation examples here. The diagrams specify a simpler abstract protocol, not its full on-storage format.
A write whose durable result after a crash is either the complete old record or the complete new record. Its unit and failure conditions must be stated. The diagrams assume this property for each payload record, final-location record, commit marker and retirement marker; they do not derive it from the size of a file data block.
A request whose successful completion, under the device's stated contract, makes preceding covered writes survive loss of volatile memory cache contents. The diagrams wait for completion at each persistence boundary. Storage flush and atomic storage write are different properties: persistence of completed writes does not make a multi-record update indivisible.
A data structure using a bit per allocation unit to mark whether it is available. Its agreement with ownership references is a file-system crash consistency requirement; changing just this structure does not install the owner's update.
File-system journaling makes a group of related file system updates recoverable after a crash by recording them in a journal before changing their final storage locations. The useful promise is file-system crash consistency: after journal replay, a protected file-system transaction has taken effect completely or has not taken effect. File-system transaction durability adds a different promise: an acknowledged update survives the crash. The protected group can contain only file metadata, or both file metadata and file data blocks, depending on the file-system journaling mode.
Consider a tiny file containing
ABCD in four-byte file data block 7. Its inode records size 4 and a reference to block 7. Appending EFGH in previously free block 9 requires three new stored records: , the inode with size 8 and references to blocks 7 and 9; , the block allocation bitmap marking block 9 allocated; and , file data block 9 containing EFGH. An inode reference to a block still marked free lets a later allocation overwrite live contents; allocating a block without recording its owner can leak space. Even mutually consistent file metadata can expose stale contents if has not reached storage. Chapter 42 of Crash Consistency: FSCK and Journaling (section 42.1, pp. 2–4) develops this three-record append problem; the names, block numbers and tiny contents here are original teaching choices.The first diagram protects all three records with write-ahead logging. Each journal payload record identifies a final destination and its complete new contents. A storage flush makes the complete journal payload durable before a separate journal commit record is written and made durable. Only then may a journal checkpoint copy the records to their final locations. The journal remains available until those copies have themselves passed a storage flush; it can then be retired and its space reused. Journal replay repairs an interrupted journal checkpoint using the retained new contents.[ref]
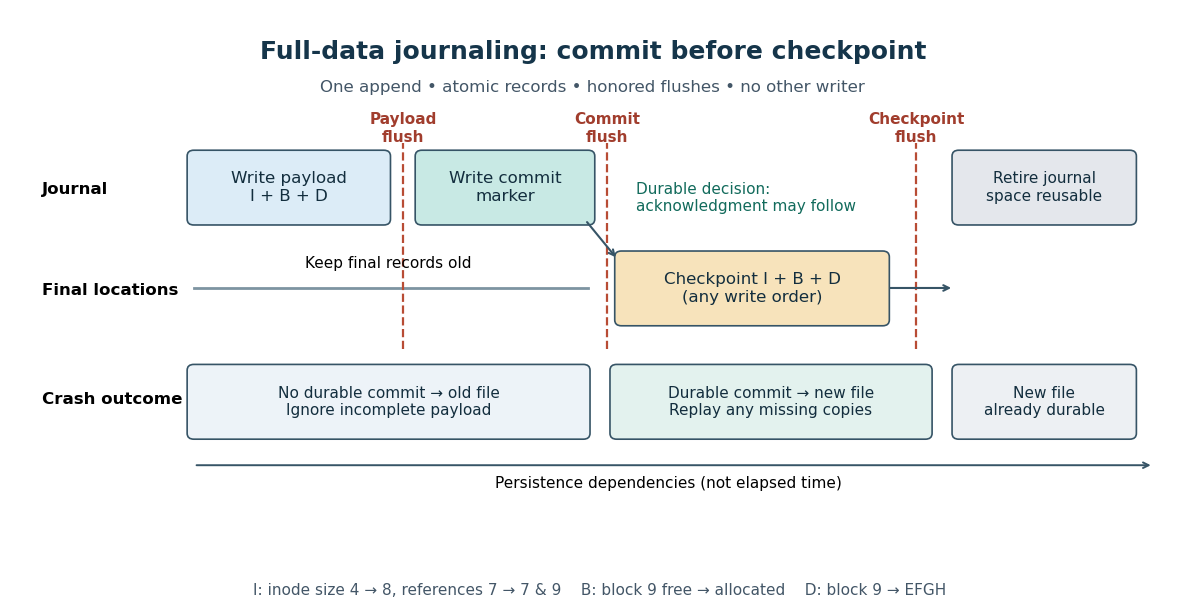
Write-ahead logging separates durable journal commit records from journal checkpoints and safe journal reuse
. Details. These are persistence dependencies, not a claim that issuing writes in this order is sufficient. A device can report completion while its volatile memory cache still holds the only copy. The Linux kernel documents both flushing earlier completed requests and making completion of a particular request depend on persistence. The timeline uses separate storage flushes to make the dependencies explicit; an implementation can use equivalent device-supported operations. A commit write can persist before its storage flush returns: recovery uses the actual durable marker, while acknowledgment waits for successful completion.[ref]
The appeal is that recovery knows exactly which updates to finish. It does not have to infer a user's intended contents from contradictory inodes and block allocation bitmaps. The cost includes writing the journal payload as well as its final copies and waiting for persistence boundaries. The journal records a recent transition, not a historical collection of recoverable files; file-system journaling is not a file-system backup.
A memory cache of device blocks indexed by device identity and block number. A hit avoids slow device access; a miss obtains a buffer and reads the block. Dirty buffers carry modified data that must be written before reuse, and pinned buffers cannot be evicted while an operation uses them. Deferred writes improve throughput but need explicit durability handling.
A buffer cache can hold both file data blocks and storage containing file metadata, such as inodes and block allocation bitmaps. Reusing a buffered device block saves repeated input-output; retaining several modifications before buffer cache writeback can combine them into one transfer. Section 40.7 of Operating Systems: Three Easy Pieces by Remzi H. Arpaci-Dusseau and others explains these benefits for file systems.[ref]
File System Implementation. pp. 14–16: caching and buffering
The central distinction is that a dirty buffer needs a write, whereas a pinned buffer must retain its identity. A clean buffer can still be pinned, and a dirty buffer can have no client references. Neither releasing a reference nor obtaining a cache hit establishes file-system transaction durability.
The organization of names and the rules for resolving them to files. A path such as
/notes/a selects successive directory entries starting from the root file-system directory. Its spelling describes a route, not an immutable identity: replacing the final directory entry can make the same path reach a different inode.A file containing directory entries. Each entry supplies a name in that file-system directory; two entries in the same file-system directory cannot have the same name. In an inode-based file system, a file-system directory has its own inode, and its contents describe names of other objects. [ref]
https://pubs.opengroup.org/onlinepubs/9799919799/basedefs/V1_chap03.html#tag_03_103. The Open Group, POSIX.1-2024, sections 3.103–3.104: directory and directory entry
An object whose contents and attributes can be accessed through operating system interfaces. Here an ordinary file means a byte sequence with file metadata, distinct from a file-system directory or a symbolic link. Its contents need not disappear when the creating operating-system process ends.
Represent the abstract sequence by
front @ rev rear. Keep the front nonempty unless both lists are empty. Prepending to the rear enqueues; when the front is exhausted, reverse the rear once. Along a single sequence of uses, each element crosses between lists at most once, giving constant amortized analysis cost per operation. Reusing an old persistent version can repeat a reversal and needs a separate analysis.// Destination: computer-science.bigb
Alcoholic fermentation produces ethanol and carbon dioxide from sugars through an enzyme-catalyzed pathway. See Saccharomyces cerevisiae for its ideal glucose balance and yeast for the distinction between living cells and active extracts.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact