Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 66 4 b Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-06
Set and . Since , . Differentiate the ordered exponential products, using that each matrix commutes with its own exponential:Here the commutator convention is ; this fixes both signs. The error satisfies , so the variation-of-constants formula givesThis is the symmetrized exponential-splitting defect identity. Symmetry of was not needed for the identity itself; it will be used to bound their exponentials in part (c).
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 66 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06By orthogonal diagonalization of a real symmetric matrix, write , with orthogonal . Its matrix exponential has the same eigenvectors and positive eigenvalues . Orthogonal invariance of the induced Euclidean norm gives the exact identityThis proves the requested inequality with equality. If a real number gave the bound for every , evaluating on a unit eigenvector for at any would give , so . Thus the stated exponent is the smallest possible. For a symmetric matrix the spectral abscissa and Euclidean logarithmic norm coincide, unlike the general nonsymmetric case in Question 1.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 66 3 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Write and . The zeros of are , so the stability function has no pole in the closed left half-plane. A direct modulus calculation givesFor this is nonnegative, and hence . Therefore the Lobatto IIIA method is A-stable. It is not L-stable, because for large negative real ; unconditional scalar stability need not strongly damp the stiffest modes.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 66 3 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06The Lagrange interpolation polynomials for these nodes areTheir integrals give the Lobatto IIIA method tableauTo verify its nonlinear order, not just its scalar linear order, set , and . Direct multiplication verifies the fourth-order conditions for a Runge-Kutta method:Powers of are componentwise. These eight Butcher order conditions establish order at least four for general smooth ODEs. On the Dahlquist test equation, elimination of the stages givesA nonzero fifth-order step defect rules out order five. Thus the method has exactly order four.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 66 3 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Let be the collocation polynomial of degree at most over one step, with , and let . Its derivative, of degree at most , is fixed by its values at the distinct nodes. Lagrange interpolation therefore givesIntegrating from zero to yieldsAt this gives the stage equations of an implicit Runge-Kutta method; at it gives the update. ConsequentlyConversely, stages satisfying these equations define the integrated polynomial displayed above. It takes the stage values at the nodes and has the required derivative there, so it solves the collocation equations. This proves equivalence for every common solution branch, not merely equality on the scalar test equation. Also , since the Lagrange polynomials sum to one. Stage existence or uniqueness requires the usual implicit-solvability assumptions; for a Lipschitz vector field a sufficiently small step gives a contraction. This is the collocation Runge-Kutta method construction.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 66 2 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Use the standard A-stability convention including the root condition at . The amplification polynomial of a multistep method isZero-stability first restricts the possible parameters to . For , as tends to negative infinity, one amplification root tends to , whose modulus exceeds one. For , the characteristic equation is ; large negative real likewise gives an exterior root. Thus is necessary.
For sufficiency take . The leading coefficient cannot vanish in the closed left half-plane. On the unit circle the boundary-locus test for multistep A-stability uses and giveswhere the denominator is nonzero. When , the exceptional zero of at is not a zero of and therefore cannot be an amplification root for a finite . Near on the negative real axis, the root issuing from one is and is strictly inside the disk; the other root is close to and is also inside. Roots vary continuously, cannot escape through infinity because the leading coefficient is nonzero, and cannot cross the unit circle anywhere in the open left half-plane by the displayed boundary formula. Thus every root remains inside there. Continuity gives the boundary case; for a unit root on the imaginary axis can occur only at , where it is simple. For , cancellation of the harmless zero root leaves the trapezoidal rule, whose amplification factor has modulus at most one.
ThereforeThe third-order member is convergent but not A-stable, consistent with the Second Dahlquist barrier. At , has a permanent unit root and a double root at : the unreduced method is not zero-stable and is not A-stable under the stated convention. Testing only the open half-plane while overlooking its zero-step behavior would give a weaker conclusion.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 66 2 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06The Dahlquist equivalence theorem states that a consistent linear multistep method is convergent for suitably consistent starting values exactly when it is zero-stable. The root condition for a multistep method requires every root of to lie in the closed unit disk, with every unit-modulus root simple.
The roots are and . Thus is necessary; is excluded because it gives a double root at one. At , the two unit roots are distinct, so the endpoint is allowed. Combined with part (a), this provesAssume a locally Lipschitz vector field, a smooth solution on the fixed time interval, a nearby solvable implicit branch and starting errors of the required order. The global order is three at and two at the other convergent parameter values. Outside this interval, zero-step perturbations already grow through either an exterior root or a unit-root polynomial factor.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 66 2 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06The characteristic polynomials of a linear multistep method areTo determine formal order, substitute a smooth exact solution and expand about the first time level. The exponential-symbol order criterion for a multistep method collects precisely the same coefficients:The constant, linear and quadratic coefficients vanish for every . The cubic coefficient vanishes only at , where the quartic coefficient is . HenceHere order means the exact-solution step residual is . It is a formal consistency result, not a convergence assertion. In particular at both and vanish, and the double root at one destroys zero-stability; cancelling its common factor gives a different, first-order recurrence with an additional integration constant left unspecified by the original formula.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 66 1 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Put and retain the same matrix . The Crank-Nicolson method isTake the real mesh-weighted inner product with . The cross terms cancel, and the identity from part (b) givesThe implicit system is uniquely solvable: if , thenso . Therefore its dissipative Cayley-transform contraction satisfiesIterating proves unconditional stability for every ; the perturbation bound is one and does not depend on the mesh or time-step ratio.
The printed hint's exponential estimate is valid with the logarithmic norm, but its proposed bound by is not a general inheritance principle. For the trapezoidal stability function , that real number can even be negative when , whereas a norm is nonnegative. The direct energy proof above establishes the required result without that assertion.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 66 1 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Let , impose , and write the method of lines system as , whereThus is a negative definite symmetric matrix and is a skew-symmetric matrix. Use the mesh-weighted Euclidean norm . Discrete summation by parts yields the centered Dirichlet drift-diffusion energy identityConsequentlyThe same estimate controls perturbations and is uniform in the number of grid points and in the fixed drift coefficient. Finite-dimensional linear ODE theory guarantees existence, so this proves stability of a numerical method for the semidiscretization.
The factor simply rescales the vector norm and does not change the induced matrix norm. Equivalently the symmetric part is , whose largest eigenvalue is . This is the Euclidean logarithmic norm, rather than generally the spectral abscissa of a nonnormal matrix. No periodic Fourier mode assumption has been made: the zero endpoint terms are part of the proof. In particular positivity of both off-diagonal coefficients is not needed for this stability result.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 66 1 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Take real and use the L2 norm on the spatial interval. Existence, uniqueness and continuous dependence are the three requirements of Hadamard well-posedness. An energy method supplies the decisive estimate. For a smooth solution with homogeneous Dirichlet boundary conditions, integration by parts givesThe drift contributes only a boundary term, which vanishes. The Poincaré inequality further givesApply the same argument to the difference of two solutions to obtain uniqueness and continuous dependence on the initial data.
For existence, use the Dirichlet gauge transform for constant drift: satisfies with zero boundary values. Expanding in its Fourier sine series givesFor the series defines a solution continuous in down to and smooth for positive time; multiplication by the fixed bounded exponentials preserves this interpretation. Its energy estimate follows by approximation with smooth initial data. For a classical solution at the initial corners, require the usual smoothness and boundary compatibility instead. The problem is well posed in , with a contraction estimate independent of the initial data.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 65 4 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06The fidelity norm here is unsquared, as in the original PDF. Write , so . Introduce and . The second-order cone reformulation of one-sided quadratic denoising issubject to the affine cone constraintswhere is the second-order cone. All coordinates displayed inside the cone memberships are affine in the optimization variables, so stacking them has precisely the form . The first cone enforces , and each three-dimensional cone enforces . The two scalar inequalities give .
Every feasible lift therefore has objective at least the original objective. Conversely, for any , choose , and to attain equality. Thus the reformulation is exact. It is a second-order cone program over the product , a proper closed self-dual cone. It preserves the asymmetric derivative penalty; replacing it by would change the problem.
The canonical Lorentz-cone barrier is on , and each orthant coordinate contributes . Their sum, composed with the affine slack map, isIts domain explicitly requires , , and ; the positive Lorentz branch must not be inferred merely from positivity of a squared expression. The barrier parameter of the product-cone barrier is , with two per Lorentz block and one per scalar orthant slack. A strict feasible lift can always be obtained by choosing above both bounds, above , and above the fidelity norm.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 65 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Introduce the primal slack . The Lagrangian is , with . Minimizing over is finite only when . Thus the conic dual problem isThe primal-dual gap at feasible points is . Self-duality specifies the multiplier cone; it does not alone guarantee feasible or bounded problems. The central-path discussion assumes primal and dual strict feasibility and a finite optimum. These additional existence conditions are not implied by the given full column rank of .
Let be the canonical logarithmically homogeneous self-concordant barrier, with parameter and . For each , minimizing defines the primal central path. Its stationarity defines the dual path through . The joint characterization isEuler's identity for logarithmic homogeneity gives , so . The gap tends to zero as . If is the dual barrier, the equivalent dual relation is . A self-dual cone does not justify identifying two arbitrary primal and dual barrier functions without this relation.
For a target parameter , form residuals , and . Linearization gives the central-path Newton systemFor a strictly feasible primal-dual iterate with , elimination reduces it toThe barrier Hessian is positive definite and has full column rank, so the reduced matrix is positive definite. Alternatively a changing path parameter can be included as an additional linear term ; the displayed system instead fixes the new target parameter before solving.
This is an interior-point method because iterates stay in the cone interiors where the barrier and its gradient/Hessian are defined. A full Newton step need not do so. Use a fraction-to-boundary or backtracking step: decrease until and lie in , then enforce an appropriate barrier or residual decrease. Such a positive step exists because the current points are interior. Local barrier norms can also certify an interior step via the Dikin ellipsoid.
For a practical starting point, choose and solve a conic phase-I problem, for example minimizing subject to and . A large positive with an arbitrary gives a strictly feasible start for this auxiliary problem. A feasible point with certifies . If the original problem is strictly feasible, a small negative is feasible, so phase I can find such a certificate. A similar feasibility procedure handles the dual equality and interior. Alternatively an infeasible-start primal-dual method or homogeneous self-dual embedding starts with interior cone variables while allowing nonzero linear residuals, and can report infeasibility rather than presume an interior solution exists.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 65 3 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Write and , with Euclidean adjoints determined by the chosen discretization and boundary conditions. Take the usual positive total generalized variation weights . Introduce a primal variable throughThe support function of the row-ball product is a sum of row norms. Convex duality gives the equivalent augmented saddle problemThe equality follows by dualizing the row-ball constraint. With positive radii, strictly satisfies both row constraints, supplying the finite-dimensional qualification for this splitting. The original feasible dual set is compact and nonempty, and the quadratic primal term is coercive; saddle points exist. The TGV divergence splitting avoids the difficult projection onto .
Use the Chambolle–Pock algorithm. Choose with ; the sufficient bound is convenient. Initialize and , . For , computeThe dual update is a Euclidean projection onto a convex set onto ; the two primal updates are the quadratic proximal operator and radial soft thresholding. Their signs follow from . All substeps are closed form, and the standard finite-dimensional primal-dual convergence result applies to this saddle problem with the stated step-size condition. The iterates satisfy ; the additional constraint is enforced through the splitting at convergence, not claimed for every intermediate iterate. If a weight is zero, the corresponding row projection or support-function proximal step is interpreted directly rather than by division by zero.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 65 3 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Fix and minimize . A proper lower semicontinuous convex function has an affine minorant , as follows by separating a point below its closed epigraph. HenceThe quadratic dominates the linear term, proving coercivity. Properness supplies at least one finite trial value, lower semicontinuity passes to limits, and finite-dimensional compactness makes a bounded minimizing sequence converge along a subsequence to a minimizer. Thus the proximal operator exists at every .
The subdifferential sum rule applies because the quadratic is finite and continuous everywhere. The Fermat rule for convex minimization givesThus the minimizer lies in . The uniqueness proved in part (a), or strict convexity of the quadratic sum, now yieldsThis proof displays the separate roles of properness, lower semicontinuity, convexity and finite dimension. In particular, compactness here is not inferred merely from strict convexity.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 65 3 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06For a step size , define the set-valued mapsThe forward subgradient step maps to the set . If is differentiable this is the explicit gradient step . The backward subgradient step consists of the satisfying , an implicit step for the subgradient flow. It is the resolvent of a monotone operator associated with .
Suppose . Then . The two defining subgradient inequalities areTheir sum proves monotonicity of a convex subdifferential, . But , soConvexity supplies the subgradient inequalities and monotonicity; membership in the subdifferential ensures the two function values are finite, so subtraction is legitimate. Positivity of supplies the decisive sign. Properness rules out the identically infinite and negative-infinity pathologies in the overall setting, but lower semicontinuity is not needed for this at-most-one argument. Its role is in existence, proved next. The backward step cannot have two values, though uniqueness alone has not yet shown its domain is all of .
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 65 2 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Let be any constrained minimizer for and let be a dual optimum. Set the common optimal value to . Weak duality and feasibility implyAll inequalities are therefore equalities. In particular, minimizes , whose term is constant. HenceThis proves the claim for every constrained minimizer, rather than just for the particular one used to establish a saddle point. The multiplier may be zero, and the penalized minimizer then need not be unique.
Conversely, for the quadratic makes the penalized objective coercive and strictly convex, so it has a unique minimizer . Choose . If a feasible had , thencontradicting penalized optimality. Thus solves the constrained problem at that budget. This is constrained-penalized equivalence for total variation denoising. It is a correspondence of minimizers and suitable parameters, not a claim that every budget has a unique multiplier or a unique constrained minimizer.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 65 2 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Let and fix the reference noise budget . Define the convex perturbation functionPositive increases the allowed squared noise level. The feasible epigraph set is convex and closed, so this is a proper lower semicontinuous jointly convex perturbation. Writing the inequality indicator as a supremum over its multiplier givesThe Lagrange dual function is for . In the signed convex conjugate convention of part (a), ; positive gives dual objective because the perturbation can be made arbitrarily large.
The feasible ball is nonempty and compact, so lower semicontinuity of total variation gives a primal minimizer. For , satisfies , providing the Slater condition. Total variation is finite everywhere in the given discretization and hence continuous. Strong duality and dual attainment give a finite optimal . The pair satisfies the Karush-Kuhn-Tucker conditionsEquivalently,Thus the set of saddle points is nonempty. Compactness handles primal attainment, while strict feasibility supplies a finite multiplier; these are distinct steps. An inactive constraint can yield . At , feasibility still forces , but this strict-feasibility argument does not apply.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 65 2 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Use for the perturbation variable and for its dual variable. The full Fenchel conjugate is . One signed-marginal convention isThe primal problem of convex perturbation duality is and its dual problem of convex perturbation duality is . The signed dual marginal is concave; some conventions instead use as a convex marginal. The definitions above fix all signs. Weak duality follows from . Also , so .
For a sufficient strong duality condition, assume is jointly proper convex, is proper with finite, and is finite and continuous in a neighborhood of . More generally suffices in finite dimensions. A supporting subgradient then exists, andThus the dual is attained with no gap. This condition does not by itself assert attainment of the primal infimum; that needs an additional compactness or coercivity argument.
The same subgradient describes sensitivity analysis in convex perturbation duality: bounds the optimum's change under perturbation. When is finite convex near zero, its one-sided directional derivative is . If , then is differentiable there andThese conditions allow first-order sensitivity predictions; without differentiability the subgradient set gives directional bounds. Multipliers can measure the value of relaxing constraints, quantify changes in noise tolerance, and guide parameter choice without resolving every perturbed problem. For the constraint convention in part (b), the noise-budget sensitivity is negative the nonnegative constraint multiplier.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 65 1 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The conjugate of an infimal convolution is the sum of the conjugates:Here , and , the indicator functional of the unit infinity-norm ball. ThusThe infimal convolution is finite convex and continuous, so the Fenchel-Moreau theorem applies without a closure defect. By equality in the Fenchel–Young inequality and the subdifferential sum rule,This is precisely the variational characterization of projecting onto the cube. ConsequentlyFor the primal split, and . These directly minimize the two scalar terms. The Huber loss is continuously differentiable, including at , but its second derivative changes there. The one-dimensional sketch shows a quadratic center joined tangentially to linear tails:
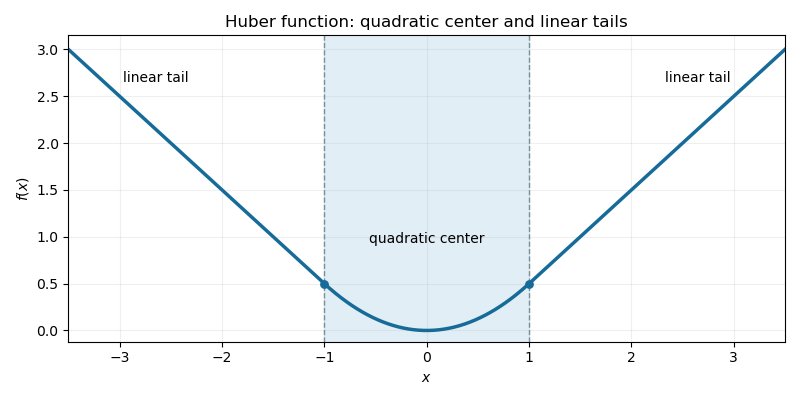
Applied to a discrete gradient, the Huber gradient regularizer penalizes small slopes quadratically and large slopes linearly. Compared with pure squared-gradient smoothing it preserves large edges better; compared with pure total variation denoising it encourages small smooth variations and reduces the strong preference for piecewise-constant plateaus. It can therefore be useful for denoising signals or images containing both smooth regions and sharp transitions. It still penalizes edges and can bias their amplitude, and it does not guarantee complete elimination of staircasing in total variation denoising. The unit threshold must be scaled appropriately for data units and grid spacing.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact