
Stellar homology Created 2026-09-24 Updated 2026-10-03
Stellar polytrope Created 2026-09-24 Updated 2026-10-03
A stellar polytrope obeys for constant and polytropic index . Its dimensionless density profile satisfies the Lane-Emden equation.
CNO cycle Created 2026-09-24 Updated 2026-09-24
Proton–proton chain Created 2026-09-24 Updated 2026-10-06
The proton–proton chain converts hydrogen to helium and dominates hydrogen burning in stars near and below the Sun's mass. Near , its specific energy generation is roughly proportional to .
Symmetrization rigidity for a perimeter minimizer Created 2026-09-24 Updated 2026-09-24
Perimeter decrease under Steiner symmetrization Created 2026-09-24 Updated 2026-09-24
For a convex planar domain between graphs and , the Euclidean triangle inequality giveswhich is the pointwise perimeter comparison with its symmetrization.
Area preservation under Steiner symmetrization Created 2026-09-24 Updated 2026-10-14
Every perpendicular chord keeps its length under Steiner symmetrization, so Fubini's theorem preserves the total area.
Constitutional supercooling Created 2026-09-24 Updated 2026-10-06
Constitutional supercooling occurs when liquid ahead of a solidification phase boundary lies below its local liquidus. In a saline liquid with and , salt rejection enriches the interface liquid and depresses its liquidus; as the concentration decreases away from the interface, the liquidus rises. If it rises faster than the actual temperature, a supercooled interval appears. This can make a planar solidification phase boundary unstable.
Neumann solution of the Stefan problem Created 2026-09-24 Updated 2026-09-24
The Neumann solution places a planar phase boundary at . Similarity reduction of the heat equation gives temperature profiles in terms of the error function, while the Stefan condition determines implicitly.
Phase boundary Created 2026-09-24 Updated 2026-09-28
A phase boundary is an interface separating distinct phases of matter. Its temperature, velocity, and flux jumps are constrained by phase equilibrium and conservation laws.
Stefan condition Created 2026-09-24 Updated 2026-10-06
The Stefan condition equates latent heat generated by motion of a phase boundary to the jump in conductive heat flux across it. With interface speed and normal directed from solid to liquid, one common sign convention is
Regularization Created 2026-09-24 Updated 2026-11-05
Regularization constrains or penalizes fitting to control the complexity or instability of a learned rule. A penalty formulation iswhere is empirical loss function and measures a chosen notion of complexity. Ridge regression penalizes squared coefficient size, the Lasso penalizes the L1 norm, and a roughness penalty penalizes derivatives of a fitted function. Early stopping can regularize an iterative fitting procedure without an explicit added penalty.
For a scalar observation with centered noise of variance , minimizing gives . Its mean squared error is : shrinkage reduces variance while introducing bias. This illustrates why regularization can improve prediction, but does not improve risk at every parameter value for every tuning choice. Cross-validation or a validation set can choose strength while a reserved test set assesses the fitted procedure.
Overfitting Created 2026-09-24 Updated 2026-10-14
Overfitting occurs when further adaptation improves training error while degrading performance on new data, for example by fitting incidental disturbances instead of a stable regression function. A gap between training error and test error alone does not prove that a simpler rule would generalize better. Compare candidates using cross-validation or a validation set; reserve the test set for assessment. Regularization and early stopping can limit adaptation. [ref]
https://web.stanford.edu/~hastie/ISLR2/Slides/Ch2_Statistical_Learning.pdf. ISLR chapter 2 slides, assessing model accuracy
Evaluate the training error example at , , none coinciding with a training input. The mean squared discrepancy is , , and for degrees 1, 2, and 7. Thus degree 7 improves training error but worsens recovery of the target relative to degree 2. Degree 1 misses the target's curvature, illustrating underfitting.
These are errors against a known noiseless target, not test errors against fresh noisy responses. In a separate noiseless control, degrees 2 and 7 both recover this target exactly; their numerical held-out errors are approximately and . The fixed-disturbance simulation illustrates a mechanism, not a universal numerical benchmark or a claim that higher polynomial degree always harms generalization.
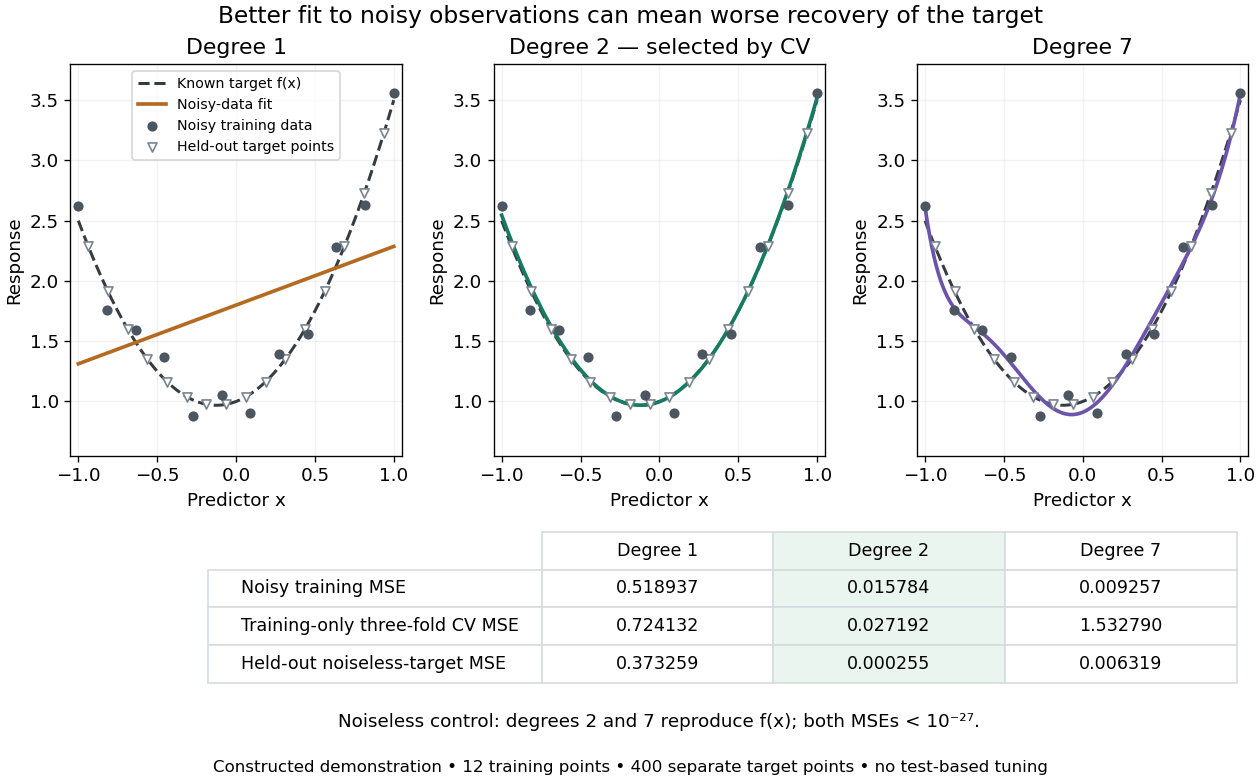
Noisy polynomial fitting, training-only degree selection, and separate noiseless-target evaluation
. Details. 
Neural network Created 2026-09-24 Updated 2026-11-05
An artificial neural network is a parameterized system of interconnected computational units whose outputs depend on weighted inputs. A feedforward neural network commonly composes layerswhere are weight matrices, are biases and are activation functions. Recurrent neural networks instead reuse a state through time; weight sharing also imposes structure in a convolutional neural network.
A loss function measures how well outputs serve the task. Backpropagation applies the chain rule to compute parameter gradients, which an optimization algorithm can use for learning. For example, a hidden rectified unit followed by a weighted output represents a piecewise affine function. With identity activations in every hidden layer, successive affine maps collapse to one affine map, so depth alone adds no nonlinear expressiveness.
The useful representation depends on architecture, data and training. Fitting many parameters does not establish generalization; regularization, independent evaluation and the target data distribution remain relevant.
Cross-validation Created 2026-09-24 Updated 2026-10-14
Cross-validation estimates predictive performance by repeatedly fitting on one part of the data and evaluating on held-out observations. In K-fold cross-validation, divide training data into disjoint folds ; identifies observation 's fold, and is fitted without fold . The displayed average scores each observation using a rule that did not train on it. Weight by observation count when fold sizes differ. Leave-one-out cross-validation uses one observation per fold. [ref]
https://web.stanford.edu/~hastie/ISLR2/Slides/Ch5_Resampling_Methods.pdf. ISLR chapter 5 slides, resampling methods
For the training error example, three folds contain indices with equal remainder modulo 3. Each fit uses eight observations. The squared-error loss averages for degrees 1, 2, and 7 are , , and respectively. Select degree 2 and refit on all twelve training data observations. The folds reuse scarce data while challenging each candidate to predict unseen responses; they do not touch the final test set.
Any learned preprocessing, including variable selection, must also be fitted within each training fold to avoid data leakage. [ref]
https://web.stanford.edu/~hastie/ISLR2/Slides/Ch5_Resampling_Methods.pdf. ISLR chapter 5 slides, the wrong and right way
Repeated tuning can itself overfit the cross-validation score; nested cross-validation uses inner folds for model selection and outer folds for assessment of that entire procedure. [ref]Folds use fewer training observations than the final refit, and their scores are dependent because training observations overlap. [ref]
https://web.stanford.edu/~hastie/ISLR2/Slides/Ch5_Resampling_Methods.pdf. ISLR chapter 5 slides, correlated fold estimates
Splitting must match deployment: for time series forecasting, rolling-origin cross-validation trains on the past and evaluates later observations, preventing future information from entering a forecast. Ordinary random folds need not answer that forecasting question. [ref] Classification in statistical learning Created 2026-09-24 Updated 2026-09-28
Neyman-Pearson lemma Created 2026-09-24 Updated 2026-11-05
For testing one simple hypothesis against another, a test that rejects for sufficiently large likelihood ratio has greatest power among all tests of no greater size.
Score test Created 2026-09-24 Updated 2026-11-05
The score test evaluates the score function at the parameter estimate constrained by the null hypothesis. The likelihood gradient records which local parameter directions would improve the fit; the Fisher information supplies its sampling scale. For a fully specified regular null , with total-sample score and total-sample information ,has an asymptotic chi-squared distribution with degrees of freedom equal to the dimension of the tested parameter. The same sample-size convention must be used in both and .
For independent Bernoulli trials, let be the number of successes among trials. Testing with givesThe signed square root is the familiar null-standardized success-count statistic. Its two-sided large-sample calibration uses ; a small sample can instead use the exact binomial distribution.
With nuisance parameters, estimate them under the null and use the corresponding efficient score and efficient information for the tested restrictions. An unadjusted information block can give the wrong scale. Unlike the Wald test, the score test does not require an unrestricted estimate under the alternative.
Likelihood-ratio test Created 2026-09-24 Updated 2026-11-05
A likelihood-ratio test rejects where the alternative likelihood is sufficiently large relative to the null likelihood.
Wald test Created 2026-09-24 Updated 2026-11-05
For an approximately normal estimator, the one-parameter Wald statisticis approximately standard normal under . A two-sided test reports .
There are unlisted articles, also show them or only show them.