A neural network composes affine maps with nonlinear activation functions and learns their weights from data.
A network in which competition allows the strongest responding unit to dominate while suppressing alternatives. A sparse winning population is a softer variant; inhibition and normalization specify the mechanism rather than following automatically from a diagram.
Repeated differentiation through a deep or recurrent neural network can make some gradient components extremely large. In the scalar recurrence , the derivative with respect to is , which grows exponentially if . Large individual matrix norms alone do not imply such growth, because directions can change or cancel; the full product of step Jacobian matrices determines the effect.
Repeated differentiation through a deep or recurrent neural network can make gradients associated with distant layers or earlier sequence positions extremely small. A simple mechanism is a product of step Jacobian matrices whose operator norms are all bounded above by some : the product operator norm is then at most over steps by submultiplicativity. This can impede learning long-range dependencies in a recurrent neural network.
A neural network whose hidden state follows a recurrence with shared parameters. It represents dependence across sequence positions through its hidden state. The standard recurrence is sequential across positions, and differentiation through many steps multiplies step Jacobian matrices, potentially causing a vanishing gradient or an exploding gradient.
A recurrent architecture that uses learned gates to regulate state preservation, replacement or readout. Gating can improve useful memory and learning over long intervals, but does not by itself establish biological implementation or solve arbitrary temporal credit assignment.
A recurrent network with a continuous family of stable or approximately stable activity patterns, such as a localized bump at any angle on a ring. Recurrent dynamics maintain the represented variable while motion-related input updates it and sensory input anchors it. Postulating the attractor family does not by itself explain its developmental origin.
A training regularization method that randomly removes selected activations or connections. In inverted dropout with keep probability , multiply each retained activation by , so its conditional expectation equals the original activation; inference then uses the unmasked activations. The random masks discourage dependence on a particular small collection of activations.
A connection that adds a sublayer's input to its output, using a projection when dimensions require it. Its derivative is , so the derivative has a direct identity contribution in addition to the sublayer's contribution. This supports propagation through a deep network but does not itself guarantee bounded gradients.
For , define and . Layer normalization returns , with learned coordinatewise scale , shift , and fixed . In a transformer block, this normalization is applied across feature coordinates separately within each example and sequence position; it does not average over a batch.
A sequence model built from stacked transformer blocks, using self-attention to mix information between positions and positionwise feedforward neural networks to transform their representations. Positional encoding supplies sequence-order information. An autoregressive decoder uses causal self-attention; generation remains sequential even when training computations over known sequence positions are parallel.
Information representing sequence position or relative position, supplied to input representations or to attention scores. It can be fixed or learned. Without order information or a position-dependent mask, a self-attention layer using shared projections treats a simultaneous permutation of sequence positions equivariantly.
An attention operation in which queries, keys, and values are projections of one sequence's representations. At each position, learned similarities between its query and permitted keys determine a weighted sum of the corresponding values. Scaled dot-product attention and multi-head attention are standard implementations; causal self-attention restricts which positions can be accessed.
Self-attention whose output at sequence position may depend only on positions at or before . In a score matrix, set forbidden future-position scores to negative infinity before applying the softmax function; the corresponding weights become zero. This permits parallel computation over a known training sequence without allowing future tokens to influence earlier predictions.
Several independently learned query, key, and value projections apply scaled dot-product attention in parallel. Concatenating their outputs and applying a learned output projection allows different heads to mix sequence information using different learned representations.
With query and key dimension , form the score matrix , apply the softmax function row by row, and multiply by the values . If query and key coordinates have independent unit variance, their dot product has variance ; division by keeps that score scale of order one. Optional additive masks exclude forbidden keys before the softmax function.
A standard transformer block combines multi-head attention with a positionwise feedforward neural network, wrapping each sublayer in a residual connection and layer normalization. An encoder-decoder transformer's decoder also has a cross-attention sublayer. Pre-normalization and post-normalization variants differ in where layer normalization occurs relative to the sublayer and residual connection.
The learned additive constant in a unit preactivation, . It can be represented by weight on a constant input .
Reuse of one learnable parameter in multiple computational positions. In a convolution this reduces parameter count and imposes translation equivariance away from boundary effects.
A network using local connections and shared filter weights across input positions. For a two-dimensional convolution the parameter count is , independently of spatial image dimensions.
A network layer aggregating nearby activations, for example by a maximum or mean. Pooling can reduce spatial size but does not by itself guarantee arbitrary translation invariance.
A binary threshold unit outputs one when its weighted input reaches its threshold and zero otherwise. Its hard threshold is not differentiable, so ordinary backpropagation cannot directly train the exact threshold model. Smooth activation functions can approximate its computation.
An activation function converts a unit's weighted input to its output. A sigmoid function, hyperbolic tangent or rectifier can give nonlinear features. Replacing all hidden activation functions by the identity collapses consecutive affine layers into a single affine map, removing the representational benefit of those hidden layers.
An associative memory retrieves a stored pattern from a related cue. An incomplete cue supplies only some coordinates; a corrupted cue supplies some wrong coordinates. A Hopfield network implements retrieval by making intended patterns stable states with surrounding basins of attraction. This turns correction into a collective computation: no unit needs to know the entire desired answer. A cue outside the appropriate basin of attraction can retrieve another pattern or an unintended stable state.
Reinstatement of a stored representation from an incomplete or degraded cue. Recurrent autoassociative memory provides one mechanism; its success depends on the cue entering the correct basin of attraction. Partial-cue deficits after CA3-targeted NMDA receptor deletion support a hippocampal role without identifying a unique weight-update rule.[ref]
Requirement for hippocampal CA3 NMDA receptors in associative memory recall by Kazu Nakazawa and others. Abstract; pp. 211–218, adult CA3-restricted deletion and full-cue versus partial-cue recall
A transformation that makes representations of similar inputs less overlapping, helping reduce interference between stored events. It must retain enough information for useful downstream learning and retrieval. The dentate gyrus is a proposed substrate, with quantitative input–output evidence from spatial cue-conflict experiments.[ref]
CA3 retrieves coherent representations from degraded input: direct evidence for CA3 pattern completion and dentate gyrus pattern separation by Joshua P. Neunuebel and others. Abstract; simultaneous DG/CA3 recordings during local/global cue conflict
A memory retrieves a stored pattern from a partial or corrupted version of that pattern. A recurrent Hopfield network supplies a precise idealization through stored attractors and their basins of attraction. Retrieval can fail through interference, ambiguous cues or spurious stable states.
A learned map retrieves an associated output pattern that need not equal its input cue. With normalized cue vectors and targets , Hebbian learning gives . For orthonormal cues, ; taking the matrix product proves exact retrieval. Nonorthogonal cues add interference . Additional context is required if one identical cue should select different outputs on different occasions.
A recurrent network with symmetric interactions and an energy function. In the binary version, units take values , self-couplings are zero, and asynchronous threshold updates can retrieve stored patterns from incomplete or corrupted cues. Fixed points are local energy minima, which need not be the intended memories or global minima.
For a symmetric matrix of couplings with , define the energy landscapeThe factor removes double counting. The local input is . Choosing to agree with lowers this energy; this mathematical energy need not be a conserved physical quantity. Its pairwise form connects the model to the Ising model; competing couplings also motivate the comparison with a spin glass. Here retrieval seeks a useful nearby local minimum, so reaching the global minimum is not the goal.
John Hopfield's 1982 computer study stored random binary strings in neural networks of 30 and 100 units. Couplings were prepared from the stored patterns; asynchronous updates supplied the computational apparatus. Starting at each nominal memory, the readout counted Hamming distances after settling as storage load varied. Corrupted starting patterns separately tested recovery. Varying the load and cue damage exposed interference between memories. These simulations supported collective retrieval, not a measurement of biological memory capacity.[ref]
Neural networks and physical systems with emergent collective computational abilities by John Joseph Hopfield. 1982, pp. 2555–2557, storage Eq. 2, Fig. 2 and corrupted-start tests
For symmetric zero-diagonal weights and zero thresholds, update one binary unit to the sign of its current field, retaining it at a zero field. The displayed energy change is negative on every actual flip. There are finitely many states, so a fair asynchronous update schedule eventually reaches a fixed point that is a minimum against single-unit flips. Synchronous updates can instead cycle, and local minima need not be global minima.
To obtain the displayed identity, subtract the two energies. Terms not involving cancel, and symmetry combines the two copies of each pair. With thresholds included the result is . The zero-threshold expression above is its specialization. At , keeping the old state rules out motion along equal-energy states. Finiteness then excludes infinitely many strict decreases, while fairness ensures that an unstable unit cannot be ignored forever. A local minimum here means no single flip lowers energy; equality directions can remain.
The asynchronous condition matters even for two units: with and zero thresholds, simultaneous updates alternate and forever. Either single-unit update instead reaches an aligned stable state.
For binary units and desired patterns , use these symmetric weights and set . For one pattern, the field at that pattern is , so it is stable. Several patterns add cross-talk terms; storage by this rule alone does not guarantee stability of every arbitrary collection of patterns.
Writing givesfor stored patterns. The subtraction removes the forbidden self-couplings. It makes explicit how the desired association competes with all other stored patterns. An unintended stable state can therefore arise even though every update obeys asynchronous Hopfield energy descent.
Store only with , zero thresholds, and Hebbian memory weights for a Hopfield network. If bits differ from , their Hamming distance is and . Squaring this sum and subtracting the diagonal terms yields the displayed energy. Thus gives .
For the cue , the first unit has input and flips to . The second then has and flips to , completing recall. The energy drops . Every cue with at most two wrong bits is corrected under a fair asynchronous schedule: a wrong bit sees the correct majority among the other four, while a correct bit either sees agreement or retains its value at a tie. The opposite pattern is also stored implicitly, so cues with at least three errors retrieve it. This is a limitation of this symmetric one-pattern construction.
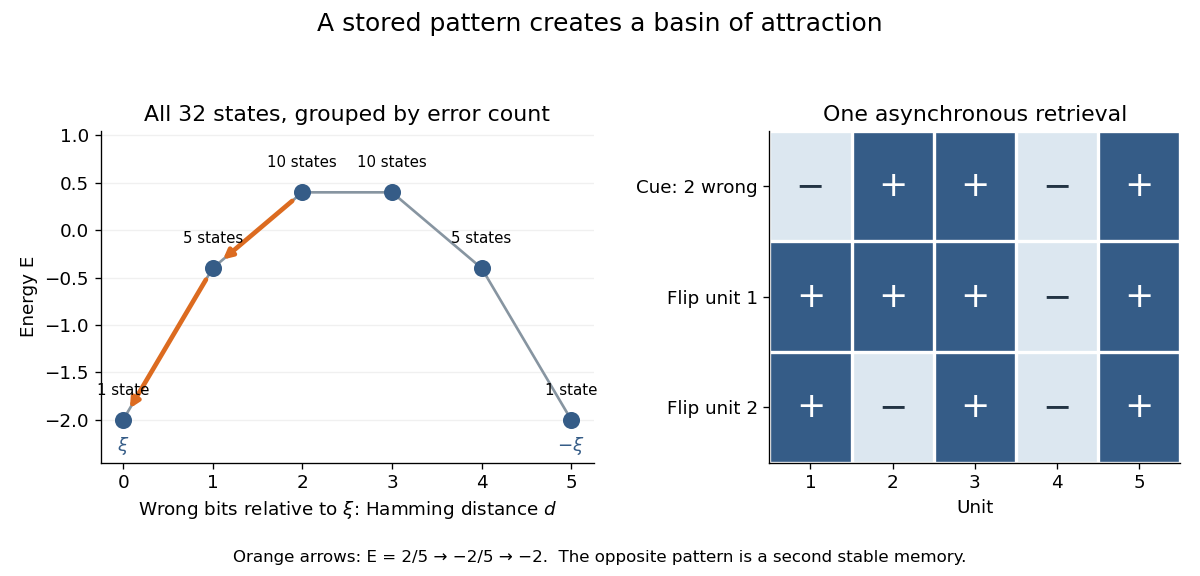
An exact five-unit memory landscape and correction of two wrong bits
. Each point represents every state at the indicated Hamming distance; multiplicities count the states. Arrows follow two actual updates of the illustrated cue under asynchronous Hopfield energy descent. This is an original finite calculation. Details.A Boltzmann machine is a stochastic neural network that learns a probability distribution specified by pairwise energies. To compare it directly with a Hopfield network, use the bipolar energy . Here controls the preference for low energy, and the partition function normalizes all states. In a computational model, is an algorithmic inverse temperature; interpreting it as additionally requires physical energy units.
A random single-unit Gibbs sampling update has conditional probabilityIndeed, the two possible energies differ by ; their normalized Boltzmann weights give this logistic function. Random selection of one unit at a time satisfies detailed balance. For finite weights and finite positive , all conditional probabilities lie strictly between zero and one, so the finite Markov chain can reach every state and can remain in place. Its unique stationary distribution is . A short run need not yet sample that distribution accurately.
As , a nonzero field selects its sign, approaching asynchronous Hopfield energy descent. At zero field the stochastic rule remains a fair coin, whereas the deterministic convention above retains the old value. At finite inverse temperature, uphill moves permit exploration beyond one local minimum. Recall and learning are different operations: sampling changes the units at fixed weights; learning changes the weights to fit the training data.
Split the units into visible units , whose patterns occur in the training data, and hidden units . Let be the empirical probability distribution and maximize the average log-likelihood , where . The positive phase clamps to data and averages over ; the negative phase releases all units and averages over . The displayed difference uses these two expectations. When both units are visible, the positive pair product is supplied directly by the data.
For a proof, write . Differentiating each finite sum gives, respectively, and . Since , subtraction proves the rule. Similarly . A small positive step along these gradients increases log-likelihood. The negative term suppresses associations overproduced by the model; strengthening observed pairs alone misses this correction. The identity requires equilibrium expectations; estimates from insufficiently mixed sampling can give a biased update.
A visible unit represents an observed coordinate of the data. Clamping it means holding that coordinate fixed while other units update. In a Boltzmann machine, hidden units are unobserved coordinates summed out to obtain the visible marginal distribution.
Take two visible bipolar units, no hidden units, zero thresholds, , and . As original training data, assign probabilities each to and and each to and . The data pair product averages to . Enumeration of all four states gives two weights and two , hence the partition function andStarting at , the positive-minus-negative difference is . A gradient ascent step of size gives . Each aligned state now has probability and each opposed state , bringing the model toward the data. The log-likelihood increases from to . Solving gives , which reproduces the data exactly. Since , this is the unique maximum. These are exact enumerations and their decimal evaluations, with no sampling or laboratory measurements.
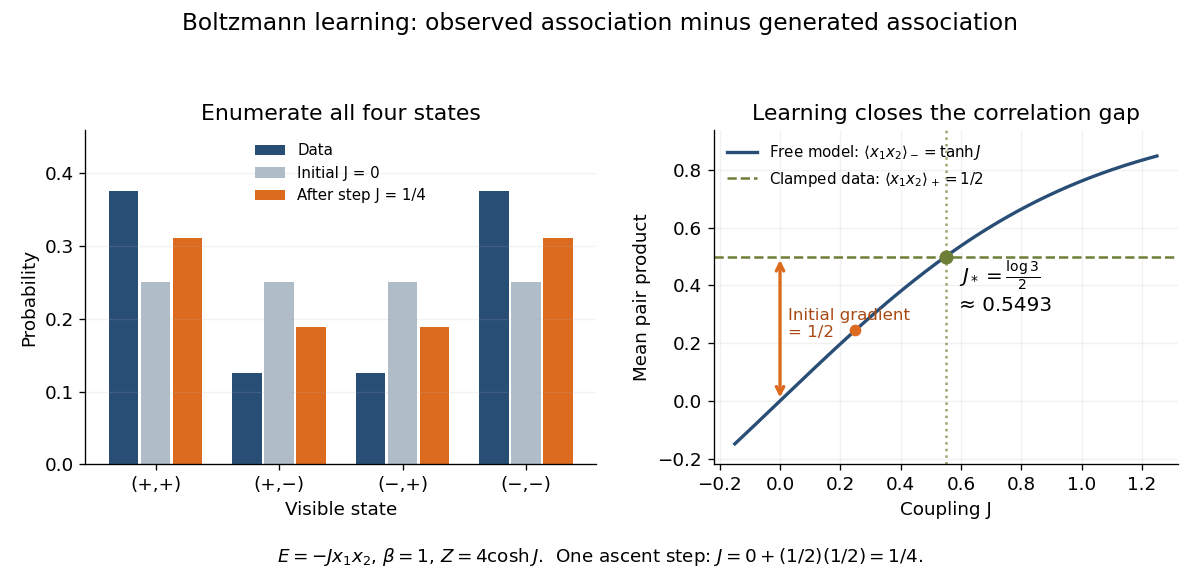
Exact probabilities and positive-minus-negative learning for two visible units
. Left: data and model probabilities before and after one gradient ascent step. Right: the data pair-product average and the model average determine the log-likelihood derivative; their intersection gives the optimal coupling. Details.David H. Ackley, Geoffrey Hinton and Terrence J. Sejnowski tested their 1985 algorithm on a simulated 4–2–4 encoder. Two four-unit visible groups communicated through two hidden units, with no direct connections between the groups. Preparation set weights to zero and supplied corresponding one-active-unit patterns. Noisy clamping and annealed settling generated pair-coactivation readouts, compared with freely running readouts to choose weight changes. Learned hidden codes were the outcome. Equal sampling effort in clamped and free conditions supplied the comparison; noise limited weight growth. Finite settling was assumed to reach equilibrium, limiting the evidence for exact likelihood learning.[ref]
A feedforward neural network composes layers without directed cycles, passing each layer's activations only to later layers.
A layered neural network with affine maps and activation functions, usually with dense connections between successive layers. A dense layer with inputs and outputs has parameters including biases.
Let be the number of active inputs. Four hidden units , , detect successively larger counts. A binary threshold unit with weights on these features and threshold returns one precisely for . Each hidden input weight is one. This computes parity with a single hidden layer, but representability does not guarantee easy learning by backpropagation.
Backpropagation applies the chain rule from a neural network's output toward its input to compute the gradient of a loss with respect to every parameter.
Apply the chain rule to a recurrent network unrolled over its input sequence, adding contributions to parameters reused at multiple time steps. Products of state Jacobians convey effects from earlier states to later losses. This can compute exact gradients for the chosen finite unrolling, while physiological availability of the same history and error signals is a separate question.
A learning scheme replacing a transposed forward-weight matrix in the teaching signal with a separate fixed random matrix. Simulations show that adaptation of the forward weights can make this feedback useful on tested tasks. It need not equal the exact loss gradient, and successful simulations alone do not establish the mechanism in the brain.[ref]
Random synaptic feedback weights support error backpropagation for deep learning by Timothy P. Lillicrap and others. Results, Figure 1 and Figure 2; Discussion: random feedback, learning performance and biological limitations
Exact backpropagation computes hidden teaching signals using the transpose of the current forward weight matrix. Explaining how a biological feedback pathway could know or maintain those weights is the weight transport problem. Useful approximate error correction need not satisfy exact reciprocal weight equality.[ref]
Random synaptic feedback weights support error backpropagation for deep learning by Timothy P. Lillicrap and others. Results, Figure 1 and Figure 2; Discussion: random feedback, learning performance and biological limitations
For squared loss , let and . The chain rule gives and . A gradient descent step of size uses and , with every derivative evaluated at the same pre-update weights.
For hidden activations and class probabilities , a one-hot label has log-likelihood . Put and . ThenThese follow from the chain rule and give single-observation stochastic gradient descent updates for the negative log-likelihood.
The standard logistic function maps a log odds to probability . More generally, its translated and scaled form is .
If , then for every , replacing by and by leaves each exponent unchanged. The same choices therefore cannot identify both an unrestricted value scale and inverse temperature. Fixing a value scale or adding independent measurements is needed to break this equivalence.
Adding the same scalar-valued function of the input to every class logit leaves all softmax probabilities unchanged. A reference-class constraint removes this common-shift non-identifiability.
For one-hot label and predicted class probabilities , categorical cross-entropy is , the negative categorical log-likelihood.
Articles by others on the same topic

A neural network is a computational model inspired by the way biological neural networks in the human brain process information. It consists of interconnected groups of artificial neurons (also called nodes) that work together to process data and recognize patterns. Neural networks are a key component of machine learning and deep learning technologies.


