local polynomial regression fits a low-degree polynomial by weighted least squares near each target point.
For equally spaced fixed-design nonparametric regression, independent mean-zero uniformly finite-variance errors, a bounded compactly supported kernel, and a uniformly invertible local Gram matrix, Degree gives the displayed bound for bounded derivatives. Kernel weights have absolute sum and squared sum . Polynomial reproduction removes a degree- Taylor polynomial. Without the Degree requirement the general bias of an estimator is only .
local linear regression fits to responses near each target by weighted least squares, then returns the fitted intercept. With weights , put and . If , then . Its polynomial reproduction property of local polynomial regression reproduces affine functions, reducing boundary bias relative to a local constant fit.
A nonnegative regression kernel supplies weights in a local weighted least squares fit. Unlike a probability density function, its integral need not equal one, because rescaling every weight does not change the fitted coefficients.
A smoothing bandwidth determines the scale over which a regression kernel averages data, or a kernel for density estimation spreads each observation. It has the same units as the observations. In kernel density estimation, changing changes the visible detail while preserving the total integral one. For a Gaussian density kernel, each bump has standard deviation and its individual contribution has peak height .
If the smoothing bandwidth is too small relative to the spacings in a statistical sample, the kernel density estimator shows narrow spikes tied to individual observations: apparent peaks may be sampling accidents. If it is too large relative to features of the unknown probability density function, it blurs distinct groups together and spreads fitted probability far from the observations. An intermediate smoothing bandwidth can reveal broad structure, but visual smoothness alone cannot establish accuracy.
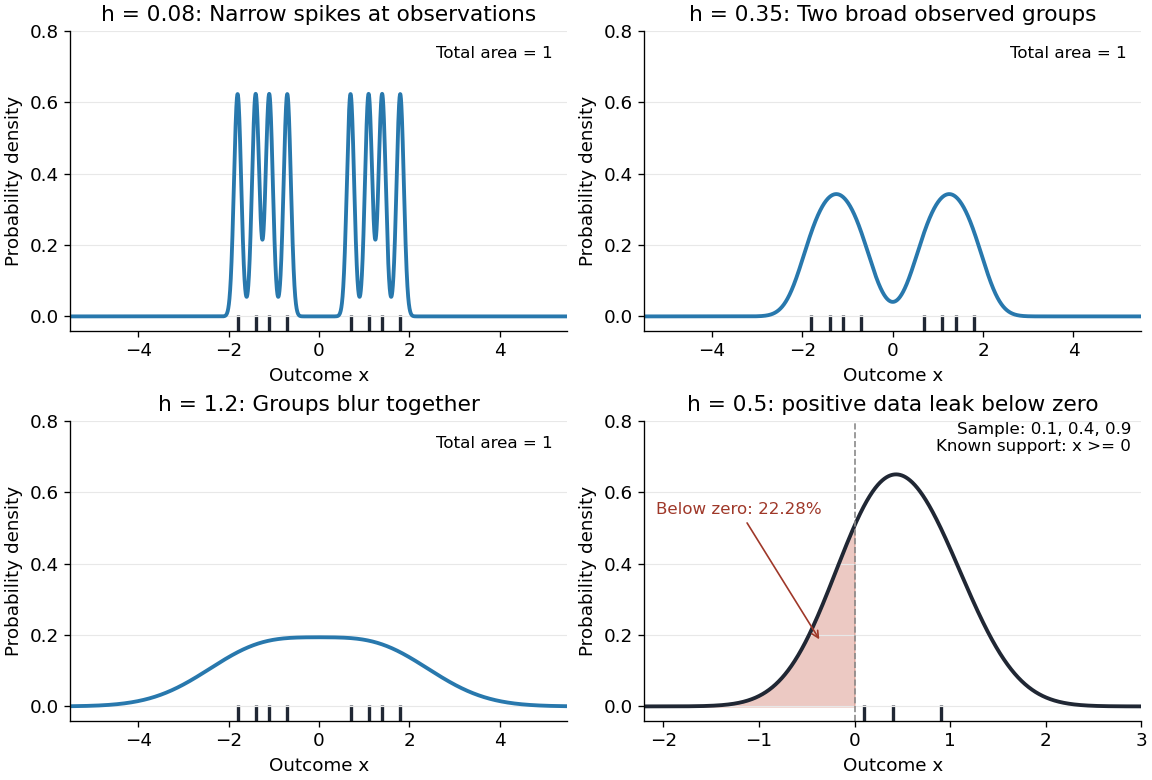
The same sample at three Gaussian bandwidths, and leakage below zero for a separate positive sample
. Details. 
The first three panels use exactly with smoothing bandwidths , and , respectively. Every curve has area one; the two groups in the observed statistical sample become less distinct as increases. No true probability density function is specified in this illustration, so the middle panel is illustrative, not a certified optimal fit. The fourth panel uses and to illustrate boundary bias of a kernel density estimator.
For a fixed nonnegative kernel for density estimation with finite squared integral, a probability density function that is bounded and continuous at an interior point with , and a deterministic sequence , the pointwise sampling variance obeysThus decreasing the smoothing bandwidth increases the leading sampling variance while reducing interior smoothing bias of an estimator: this is a bias-variance tradeoff. The conditions and express two goals, increasingly fine resolution and enough observations contributing locally. Practical methods such as plug-in bandwidth selection use the data to choose ; pointwise optimal kernel bandwidth depends on local features of the unknown probability density function. The smoothing bandwidth remains a tuning choice in nonparametric statistics, and knowing the support of a probability distribution can require more than a width adjustment near a boundary.
Estimate the unknown curvature in the AMISE minimizer and substitute it into that formula. A consistent positive curvature estimate makes the selected bandwidth ratio-consistent. Pilot smoothing is needed because differentiating an undersmoothed density estimator magnifies variance. A normal-reference pilot can initialize an estimate of a higher derivative functional; the final density-curvature estimate is computed from the data rather than assuming the density is normal.
Twice integrating by parts gives . Estimate this by averaging a fourth-derivative kernel density estimator at the observations. Its expectation contains diagonal term and leading smoothing bias . Balancing them yields pilot scale . With suitable derivatives and tails, the estimation error is bounded by , giving an relative-bandwidth bound after substitution. More carefully calibrated bias cancellation can improve that bound.
// Target: statistical-inference.bigb
The uniform smoothing kernel assigns equal weight inside the window and zero weight outside. Its Nadaraya–Watson estimator is the average of observations in that window.
The unit-width centred box kernel is . It has integral one and squared norm one. Its rescaling averages a function on intervals of length . It is obtained from the uniform smoothing kernel with support by rescaling, and is useful in both kernel density estimation and local polynomial regression.
The local polynomial Gram matrix is the weighted matrix of inner products of the local monomial basis. Its invertibility makes the local fit unique.
The effective kernel weights express a local polynomial regression fit as a linear combination of the responses. At target , set , , and . If the local polynomial Gram matrix is invertible, thenwhere . This follows by solving the weighted least squares normal equations and taking the fitted intercept.
The effective kernel weights are not the raw weights . They depend on the whole local design and satisfy the polynomial reproduction identities and for . Even when , individual can be negative. For a local linear regression at through observations at , the weights are , giving intercept . The negative weight is what permits exact extrapolation of a straight line; forcing all weights positive would lose that property at this target.
Local polynomial weights of Degree reproduce every multivariate polynomial of total degree at most : applying the estimator to its design values returns its value at the target point.
If a degree- local polynomial is fitted in the scaled coordinate , its coefficient of that coordinate divided by estimates the first derivative. Its effective weights differentiate every polynomial of Degree at most exactly at the target.
This local-constant estimator is one particular kernel regression method.
The Nadaraya–Watson estimator is the degree-zero local polynomial estimateAt a support boundary it generally has first-order bias because it reproduces constants but not linear functions.
For the unit-width symmetric box kernel for density estimation, suppose the design density is positive and differentiable at , the regression function is twice differentiable there, and the conditional variance and design density are bounded near . Write . Symmetry cancels its linear Taylor term, giving ; independence gives . The absolute error bound for a ratio estimator with a controlled denominator gives the displayed rate if the small-denominator contribution is negligible. The balance gives . Interior design positivity matters: support boundaries can prevent the linear cancellation.
A local constant estimator reproduces constants but need not reproduce an affine regression function near a support boundary. Let , take and the regression kernel , and suppose . At target zero, the noiseless Nadaraya–Watson estimator averages for . Whenever , its exact fitted value isSince , this is the bias of an estimator when observation errors have zero expected value. Under and , it is asymptotic to . The one-sided boundary window has a nonzero first coordinate moment, explaining the first-order bias. An invertible local linear regression fit reproduces exactly at the target and removes this term. If , the local constant average is undefined rather than zero, so a nonempty window is a necessary condition.
For fixed , design , , a nonzero nonnegative symmetric piecewise regression kernel supported on , and , , write and . On the rescaled grid of spacing , the Riemann sum error for is , by bounded variation. The normalized first and second local moments are therefore and . A uniform second-order Taylor expansion gives the displayed bias of an estimator, since . Equivalently it is . The first-order term explains the generic boundary bias of a local constant estimator.
For an equally spaced design with independent errors of variance at most and a regression function with Lipschitz constant , the unit-width box kernel estimator averages the observations in the window. Its bias is at most , and its variance is at most . The window occupancy for an equally spaced regression design gives, whenever ,In the usual range , this is uniformly up to the boundary. For arbitrarily large bandwidth, the stochastic error cannot continue to decrease as : once all observations are included the estimator is simply their mean.
Let be an interior target for fixed-design nonparametric regression with equally spaced sites, regression function differentiable at , and independent mean-zero errors of common variance . Use a nonnegative symmetric unit-integral compactly supported piecewise smooth regression kernel , with and . For the Nadaraya–Watson estimator,The noise variance factor is essential; alone assumes unit variance.
For the bias, expand uniformly in the shrinking window. Symmetry cancels the limiting first moment and the grid error is . For the variance, independent errors give ; the two kernel Riemann sums yield . Hence the squared bias of an estimator is . This is a pointwise differentiability argument; it does not supply a uniform remainder over an arbitrary class of functions.
Articles by others on the same topic
There are currently no matching articles.