Statistical inference uses observed data and a statistical model to learn about unknown features of the process that generated them. In a parametric statistical model, write : the probability distribution depends on an unknown statistical parameter . An estimand specifies the target, such as a mean or a difference of means. A statistic is a function of the observations; an estimator is a statistic used to estimate the target. Uppercase denotes the random data before observation, while lowercase denotes their realized values.
Three questions lead to different outputs. Statistical estimation asks which target value the observations suggest. A confidence interval asks for a range produced by a procedure with calibrated coverage probability. A hypothesis test asks whether the observations depart sufficiently from a specified null hypothesis to enter its rejection region. These outputs complement one another: an estimated effect size describes magnitude, while a standard error describes the sampling distribution of an estimator. A p-value describes a tail probability under the null hypothesis.
The appeal of statistical inference is that it turns variable observations into reproducible uncertainty statements. In the normal mean confidence interval with known variance below, a sample mean of has standard error : both the estimated shift and its precision matter. The calibration depends on the statistical model, including independence and the specified probability distribution. Increasing sample size improves precision under those assumptions; it does not repair a systematically misleading sampling procedure. Bayesian inference provides another framework, using a prior distribution and a likelihood function to obtain a posterior distribution.
Sampling bias is a systematic distortion arising when the sampling mechanism makes the observed sample unrepresentative of the target statistical population for the estimand of interest. It is distinct from random sampling variability and from other causes of the bias of an estimator.
Suppose a population has equal-sized groups with values zero and ten, so its mean is five. If independent sampling with replacement chooses the first group with probability , the sample mean has expectation one and converges to one as the sample grows. More data reduce its random variation without removing the selection bias. Known selection probabilities can support a design-based correction, but a group never sampled cannot be recovered merely by assigning larger weights to observed units.
Statistical sampling selects observations from a target statistical population through an explicit selection procedure or statistical model. It links observed values to the larger collection about which conclusions are sought. The accessible sampling frame and the statistical population need not coincide, which can cause sampling bias even in a large statistical sample.
For a finite statistical population with values , suppose every unit has known positive inclusion probability . If is the selected statistical sample, thenis an unbiased estimator of the total . Indeed, writing the sum with inclusion indicator functions gives . Under simple random sampling without replacement of size , , so is the sample mean. The selection procedure also determines dependence between selected units and the resulting sampling variability; unbiasedness alone does not specify its size.
A sampling frame is the operational list or other device identifying the units from which a statistical sample can be selected. The intended statistical population, the sampling frame and the responding units can differ. A register of residential addresses, for example, can serve as a sampling frame for a household survey, but may miss newly built homes and include demolished buildings.
If 100 of 1000 target households are absent from the sampling frame, randomly selecting 90 of the 900 listed households gives each listed household inclusion probability and each omitted household inclusion probability zero. Increasing the sample among listed households cannot by itself correct that lack of coverage. Duplicate entries create a different problem: units with more entries can be more likely to be selected. A sound design therefore documents how frame units map to population units and distinguishes coverage errors from sampling variability.
Randomized response masks which of two complementary binary questions a person answered. Suppose the sensitive property has probability , and independently the direct question is selected with known probability , while the complementary question is selected otherwise. Truthful answers then have yes probability . The investigator observes only the answer, preserving uncertainty about an individual's status while permitting population statistical estimation when .
For independent responses, , and the affine estimator is an unbiased estimator. Its variance is , by the mean and variance of a binomial distribution. Equivalently the variance is , exposing the extra sampling uncertainty caused by the masking. At , all produce and identifiability fails. At or , there is no masking and the extra variance vanishes.
Because , maximum likelihood estimation gives . This follows by maximizing the binomial likelihood over the interval and then inverting its monotone affine parametrization. Clipping can introduce bias: for , and , the clipped estimate has mean .
Analysis investigating patterns and generating or refining hypotheses through the data. It is scientifically useful when its data-dependent role is reported honestly. Findings developed through exploration need further independent evaluation before being presented as confirmed predictions.
Analysis evaluating a hypothesis or model whose relevant specification was fixed independently of the data used for its evaluation. The evidential interpretation depends on the complete analysis procedure, including selection and stopping rules.
Recruitment based mainly on accessibility rather than known probability selection from a defined target population. A larger convenience sample can reduce some sampling variability without eliminating selection bias or making respondents relevant to the intended construct.
The observations or participants obtained through convenience sampling.
The set of units or situations to which a study intends its claims to apply. A recruitment pool, the observed sample and the target population can differ. External validity concerns whether the evidence transports to the intended target.
An analysis in which data capable of revealing the sought result are hidden while selection and inference procedures are chosen. It reduces result-dependent tuning. calibration samples and predefined validation samples remain necessary; blinding does not itself correct a defective background model.
A pseudolikelihood multiplies conditional probabilities rather than the full joint likelihood function. It can be useful for fitting a Markov random field, but using the product itself as a probability density defines a different model unless an additional equivalence is established.
Overestimation of effect magnitude when noisy discoveries are selected for unusually strong apparent effects. Independent replication and explicit modeling of the selection process help correct the bias.
Frequency estimation infers a periodic signal's frequency from observed samples. It may use a peak of the discrete Fourier transform, or fit a sinusoidal model with amplitude, phase, and frequency as unknown parameters. Its attainable precision depends on noise, observation duration, sampling rate, and the estimator. Fourier frequency resolution alone does not specify that precision.
An effect size measures the magnitude of an observed or modeled relationship. A standardized mean difference expresses a mean contrast in standard-deviation units; other effect sizes include a correlation coefficient or odds ratio. Magnitude is distinct from the evidence against a null hypothesis supplied by a p-value: a small effect size can have a small p-value in a sufficiently large sample.
The fraction of total observed sum of squares attributed to a model effect under a specified analysis of variance decomposition. Its interpretation depends on the design and sum-of-squares convention.
An effect size comparing an effect sum of squares with that effect's own error sum of squares. It need not be the fraction of total observed variation, and partial values for several effects need not sum to one. The relevant error term must be identified, especially in repeated-measures designs.
Statistical process control compares observed process outcomes with a stable reference model and control limits reflecting expected sampling variation. An observation outside those limits is a signal to investigate, not proof of a specific cause. Varying sample volumes require varying limits, and multiple testing changes the chance of a chance signal somewhere in the display.
A CUSUM accumulates evidence for a change in a monitored probability distribution. With a log-likelihood ratio increment favoring a specified changed distribution, reset the accumulated score at zero and signal when it exceeds a chosen boundary . For , is the largest nonnegative sum of successive increments ending at . This permits repeated detection of a change with an unknown onset, rather than a single fixed-start test.
For independent Poisson observations, comparing mean with gives the displayed log-likelihood ratio. Updating a CUSUM with these scores targets the specified multiplicative increase. Its expected score is negative under the null and positive under the alternative when , so resetting at zero discards earlier evidence against an increase.
The average run length of a CUSUM is the expectation of its first signalling time under a specified data model and initial chart state. A large in-control average run length discourages false alarms; a small out-of-control value indicates rapid detection. The mean alone does not give a finite-horizon Type I error probability or the complete detection-delay distribution.
A fast initial response CUSUM starts a CUSUM with a positive head start below its signalling boundary. Before its first reset, it accumulates a fixed-start log-likelihood ratio like a sequential probability ratio test; after resetting to zero it behaves as an ordinary CUSUM. It gives faster initial detection when the process may already be out of control, at the cost of changed initial false-alarm behavior.
A hospital mortality funnel plot places each hospital's observed mortality proportion against its case volume. Under an independent binomial distribution model with common target p, the standard error is , so uncertainty bands contract as volume grows. This is a provider-performance plot, distinct in purpose and axes from a meta-analysis funnel plot. A signal requires investigation of data quality and patient case mix before drawing a causal conclusion.
The displayed pointwise control limits follow from the normal approximation to an observed binomial proportion. Clip plotted limits to the probability range. Their nominal coverage is approximate and can be poor for small expected counts; exact binomial tails give a discrete alternative. Pointwise coverage does not provide simultaneous coverage of all hospitals; use Bonferroni correction or another familywise error rate procedure when that is the required guarantee.
Control limits bound the sampling outcomes expected under a specified reference process. An observation outside a limit is a statistical hypothesis testing signal to investigate the reference model. These are limits for observations under that model, rather than a confidence interval constructed around each observed estimate. Their calibration may be pointwise, simultaneous or sequential.
The delete-one form of jackknife resampling recalculates a statistic after deleting each observation in turn. It uses one observed statistical sample to investigate how sensitive an estimator is to its individual observations, and supplies both a jackknife variance estimator and jackknife bias correction. The calculations are deterministic once the data are fixed: no random draws are needed.
In the basic setting, are independent and identically distributed random variables, with sample size . Let be the observed values and a scalar estimator of an estimand . Apply the same estimation rule to each reduced statistical sample, using its new sample size wherever the rule requires it:Every index is deleted exactly once; an unusual value is treated by the same rule as every other value. The mean summarizes the deletion estimates. They overlap in observations, so they are generally not independent random variables representing fresh repetitions of the original experiment. Cosma Shalizi's [ref]
https://stat.cmu.edu/~cshalizi/490/23/2023-11-29-jackknife.pdf. Carnegie Mellon jackknife notes, Sections 1–3 and 5
explain this construction and its scaling.For a concrete sample mean, use the data , whose full sample mean is . The five deletion sample means, in observation order, areDeleting raises the sample mean by , while deleting lowers the sample mean by . Thus has the largest deletion effect in this statistical sample. This is a descriptive sensitivity calculation, not a rule for removing that observation: the full sample mean remains .
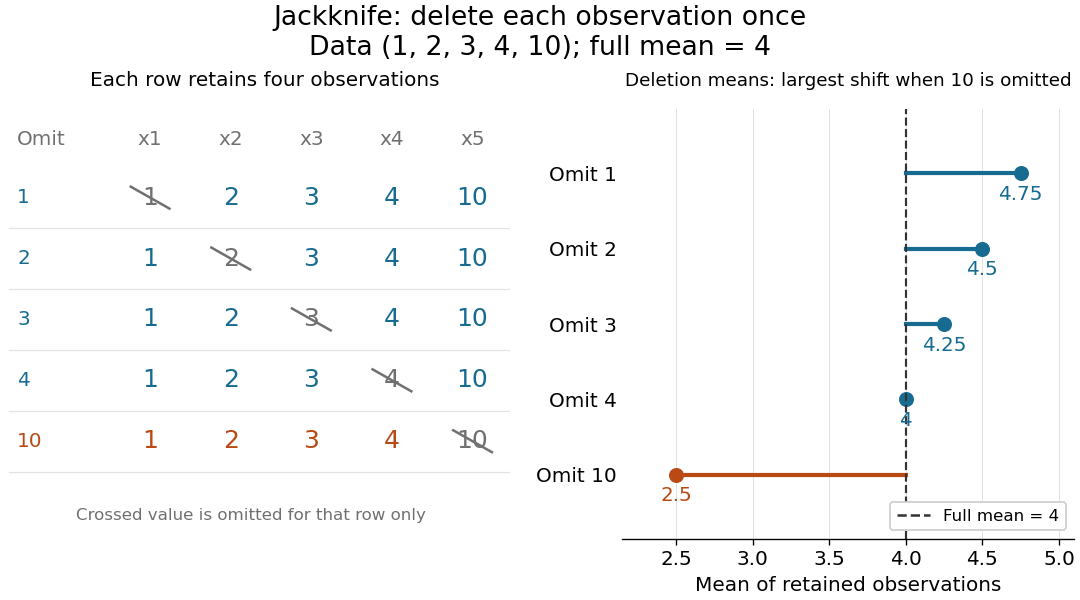
Delete each observation once and recompute the sample mean
. The left panel shows all five reduced statistical samples from ; each crossed entry is omitted only for that row. The right panel shows their sample means against the full sample mean . The orange row makes the deletion effect of visible. Details.Early literature includes M. H. Quenouille's [ref]
https://academic.oup.com/jrsssb/article/11/1/68/7026551. Approximate Tests of Correlation in Time-Series, JRSS B 11(1), 68–84 (1949)
and John W. Tukey's one-paragraph abstract [ref]https://www.jstor.org/stable/2237363. Bias and Confidence in Not-Quite Large Samples, Annals of Mathematical Statistics 29(2), 614 (1958)
, within the issue's collected abstracts. Shalizi's [ref]https://stat.cmu.edu/~cshalizi/490/23/2023-11-29-jackknife.pdf. historical notes and bibliography
discuss the later development of jackknife bias correction and the jackknife variance estimator.The jackknife variance estimator estimates the sampling variance of the full-data estimator, using the deletion estimates and their mean from jackknife resampling:The square root is the estimated standard error. The factor multiplies the divisor- variance of the deletion estimates: those estimates vary less than estimates from new independent experiments because almost all their observations are shared. Ryan Tibshirani's [ref]
https://www.stat.cmu.edu/~ryantibs/statcomp-F15/lectures/design.html. Carnegie Mellon notes on computing jackknife standard errors
give the same scaling in terms of the divisor- sample variance of the deletion estimates.For the sample mean, this formula has an exact algebraic simplification. With denoting the usual sample variance,and thereforeUnder the independent and identically distributed assumption and a finite second moment, is an unbiased estimator of the population variance . Consequently is an unbiased estimator of the sample mean's sampling variance . The equality itself holds for any observed data with ; its sampling interpretation uses the stated assumptions.
For , the sum of squared deviations from the sample mean is , giving sample variance . The deletion sample means have squared deviations totaling , soHere estimates the variance of individual observations, while estimates the sampling variance of their sample mean. These answer different questions.
For more general statistics, validity requires regularity beyond the deletion formula, such as a sufficiently smooth function of sample means with suitable moments. Ordinary delete-one jackknife resampling can fail for nonsmooth quantiles, including the median; see Larry Wasserman's [ref]
https://www.stat.cmu.edu/~brian/valerie/617-2022/0%20-%20books/2006%20-%20Wasserman%20All%20Of%20Nonparametric%20Statistics.pdf. All of Nonparametric Statistics, Section 3.1
. With statistical dependence, deleting individual observations need not reproduce the relevant sampling variance; the deletion scheme must reflect that statistical dependence. Shalizi's [ref] distinguish the basic independent and identically distributed case from extensions.For independent identically distributed observations with finite fourth moment, the sample mean of their squares has sampling variance . Its jackknife variance estimator is exactly the displayed unbiased estimator, since its leave-one-out values differ from their average by . The conditional bootstrap variance of a sample mean is . Thus the two methods have a known finite-sample scaling difference, despite sharing the same large-sample target.
In a parametric statistical model, the likelihood function compares parameter values, while sampling distributions calibrate tests and confidence intervals. A sufficient statistic retains the parameter information. Conditioning on an observed ancillary statistic restricts that calibration to experiments with the same ancillary configuration, instead of averaging over configurations whose distribution is unrelated to the parameter. Since the ancillary's marginal law is parameter-free, conditional and unconditional likelihoods have the same parameter-dependent factor. With a nuisance parameter, a conditional law or pivotal quantity must remove it before inference for the parameter of interest can use a nuisance-free reference law.
When an experiment's configuration is observed, inference conditions on the experiment actually performed rather than averaging over its possible configurations. Conditioning on an ancillary statistic is a central application; freedom from a nuisance parameter must still be checked in the resulting conditional distribution.
The one-sample Kolmogorov-Smirnov test checks goodness of fit by comparing an empirical distribution function with a specified cumulative distribution function . Its Kolmogorov-Smirnov statistic is the largest vertical gap anywhere between the two curves. Every threshold asks the same concrete question: what proportion of the observations are at or below it, and what probability does the proposed probability distribution assign there? A large discrepancy supplies evidence against the null hypothesis.
For example, four stipulated observations compared with the uniform distribution on give . Just before , only two observations have been counted, so the empirical distribution function approaches , while approaches . The Kolmogorov-Smirnov statistic section calculates every jump-side gap. These are exact illustrative numbers, not experimental measurements or a claim of statistical significance.
The ordinary one-sample calibration assumes independent and identically distributed real observations and a simple hypothesis , with a continuous function fixed before inspecting these observations. All statistical parameters of must be specified.[ref] Under that null hypothesis, the probability integral transform gives with the uniform distribution on , retaining independence. Consequently the sampling distribution of depends on the sample size , but not on the particular continuous . This is the useful sense in which the calibration is distribution-free.
For the exponential distribution of rate one, for . Take for the four stipulated above. The probability integral transform changes the horizontal coordinates but preserves both the order statistics and their cumulative heights, so the same Kolmogorov-Smirnov statistic appears on both scales. More generally, for continuous , the jump-side formulas depend only on . Strict increase everywhere is unnecessary: intervals on which is constant have probability zero under the null hypothesis. This explains the invariance without assuming a strictly positive probability density function.
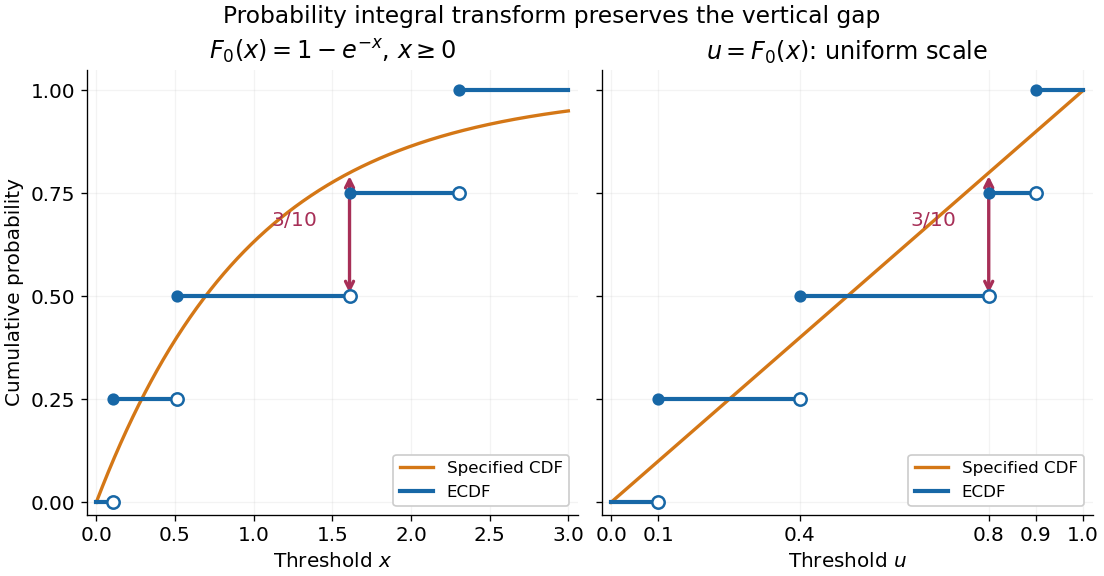
The probability integral transform preserves the Kolmogorov-Smirnov gap on exponential and uniform scales
. The same four stipulated points are shown as on the left and on the right. Open circles indicate left limits of the empirical distribution function, filled circles its values. The gap is approached from below the third observation on both scales. Details.The observed Kolmogorov-Smirnov statistic is a discrepancy, whereas its p-value is a tail probability under the null hypothesis:Here is computed from a fresh sample of the same sample size. Choose a significance level before the test and reject when the calibrated p-value is at most . The value alone supplies neither a p-value nor a rejection decision. Failure to reject does not establish that the null hypothesis is true. A finite-sample calibration and the asymptotic Kolmogorov-Smirnov theorem are distinct; a cutoff for must be rescaled before use with .[ref]
Fitting statistical parameters on the tested observations replaces by the random . The resulting transformed observations need not be independent and identically distributed uniforms, so the ordinary reference law fails. The Lilliefors test addresses a particular fitted normal distribution. More general parametric bootstrap calibration must simulate from the fitted statistical model and repeat the fitting in every replicate; holding the fitted statistical parameters fixed during those comparisons calibrates a different procedure. Such a parametric bootstrap requires its own validity justification rather than inheriting exactness from the simple-null test.
For a discrete probability distribution, is generally not uniform. Equal observations also arise from rounding, so tied data require a calibration that accounts for the discrete probability distribution or the rounding rule. The discrepancy remains meaningful, but continuous-null p-values are not automatically valid. Statistical dependence likewise changes the reference law. The two-sample Kolmogorov-Smirnov test compares two empirical distribution functions and has a different calibration.[ref]
For an empirical distribution function and a specified cumulative distribution function , the one-sample Kolmogorov-Smirnov statistic is their Kolmogorov distance:The displayed sum uses an indicator function. With this convention, is right-continuous. For distinct observations, its value and its left one-sided limit at the th order statistic are and .
For continuous , both jump sides matter. Define the two directional discrepancies byThus uses the empirical distribution function immediately after a jump, and uses its left one-sided limit.[ref] A supremum need not be attained.
For , on , and the stipulated order statistics , the complete calculation isThe last two columns give the signed directional gaps: , , and . In contrast, checking only gives and misses the largest gap approached as . At itself, the gap has already fallen to .
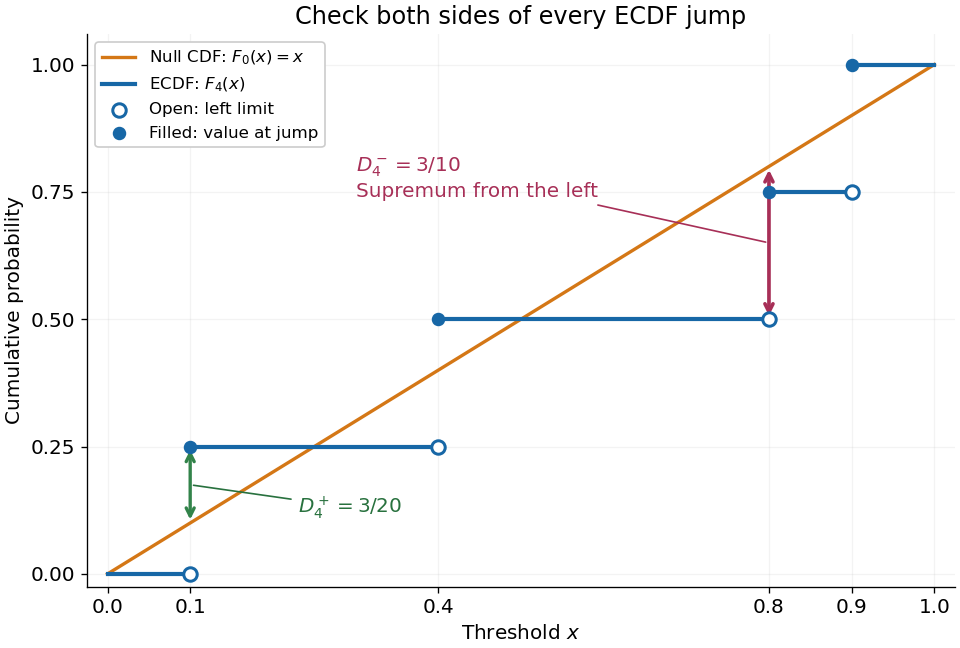
The finite formula follows from the behavior between jumps: the empirical distribution function is constant and the cumulative distribution function is monotone, so the largest directional gaps occur at the two interval ends, possibly as one-sided limits. The two tails introduce no larger gap. Checking every jump side therefore gives the exact supremum.
A common normalized Kolmogorov-Smirnov statistic is , which equals in this example. Its large-sample reference law comes from the Kolmogorov-Smirnov theorem. The unscaled remains the largest difference of cumulative probabilities, not a p-value.
There is a useful exact exception to the usual warning about fitting statistical parameters. Suppose independent and identically distributed observations have the uniform distribution on with unknown . Let and let be the label of its almost surely unique maximizing observation. Conditional on and , the surviving labelled observations are independent with the uniform distribution on ; after division by they are independent and identically distributed uniforms on . These are conditional distributions defined by probability density functions, since the event has probability zero.
To check this, the joint probability density function of and is for . Dividing the original joint probability density function by this factor gives the conditional survivor probability density functionThis factorization proves the claimed conditional independence; scaling removes . Keep the surviving labels in a fixed order, or apply an independent random permutation. The sorted survivors instead have the joint law of uniform order statistics and exhibit statistical dependence; sorting does not affect their empirical distribution function. Delete the maximum itself, which would otherwise become a forced value , and compute the Kolmogorov-Smirnov statistic using sample size and jump heights . This gives an exact conditional Kolmogorov-Smirnov test under the uniform-endpoint statistical model. It does not justify fitting an arbitrary endpoint or other statistical parameters and using the ordinary -sample calibration.
The Lilliefors test calibrates the Kolmogorov-Smirnov statistic against a normal distribution whose mean and variance are estimated from the tested observations. In the original procedure, is the sample variance with denominator , and is the standard normal distribution function. Its reference law includes this fitting step. The original paper's opening procedure and Table 1 explain the changed calibration.[ref]
On the Kolmogorov-Smirnov Test for Normality with Mean and Variance Unknown by Hubert W. Lilliefors. pp. 399-400: opening procedure and Table 1 of the original article; inspected mirrored text
The two-sample Kolmogorov-Smirnov test compares two empirical distribution functions from independent samples, each internally independent and identically distributed, under the null hypothesis that their underlying probability distributions coincide. Both curves are estimated from data, so calibration depends on both sample sizes; the usual asymptotic scaling is . Tied data can be handled by an appropriate permutation test under the required exchangeability, rather than by assuming the untied continuous-null law.[ref]
All evidence in observed data about a parameter is contained in its likelihood function; proportional likelihoods carry the same evidence. If a stopping rule contributes only a positive factor independent of the parameter to the complete observed-sample likelihood, that factor does not change likelihood-based inference. Recording only a coarsened part of the sample produces a different likelihood and is not covered by the same invariance claim.
For independent exponential observations of rate , stopping after observation with known probability gives a complete-data likelihood proportional to . Its minimal sufficient statistic is by the parameter-free likelihood-ratio criterion. If only the last value is recorded, its density instead is . The stopping rule therefore changes the coarsened-data inference even though it adds no complete-data likelihood factor involving .
An estimand is the population quantity an analysis seeks to learn, as distinct from an estimator calculated from a sample. In a randomized controlled trial, the causal effect of treatment assignment and the effect of actual treatment receipt are different estimands when adherence is imperfect.
Statistical efficiency compares the precision of procedures estimating the same estimand. For unbiased estimators, relative efficiency is commonly a ratio of their variances; lower variance means more information from the same sample size. An efficient estimator attains a relevant information lower bound. A baseline-adjusted linear regression can improve precision in a randomized controlled trial by removing prognostic variation.
A statistical functional assigns a target value to each probability measure in a statistical model. Examples include an expected value, a quantile, and an integral of a power of a probability density function. Its behavior along statistical paths determines whether first-order influence-function representers are available.
A functional statistic evaluates a statistical functional at the empirical distribution . The map acts on distributions, whereas is a statistic. If has an asymptotic linear representation, thenA square-integrable influence function with mean zero consequently gives asymptotic variance by the central limit theorem.
Along bounded density tilts, this functional has derivative . At a bounded baseline density its canonical gradient, relative to these regular paths, is . A common local bound on nearby densities suffices to obtain the same derivative along arbitrary differentiable-in-quadratic-mean paths in that bounded neighborhood. A bounded baseline alone is insufficient, because of the spike obstruction to density-power differentiability.
A perturbation can have negligible Hellinger distance but a large integral of its density's fourth power. At the uniform density on , let on and zero elsewhere, and let . Then and , so the score function is zero. However . Thus the density fourth-power functional is not continuous along this differentiable-in-quadratic-mean path, despite a bounded baseline and individually bounded nearby densities.
A statistical functional is pathwise differentiable relative to chosen statistical paths if its derivative along every path depends only on that path's score function and defines a bounded linear functional on their statistical tangent space. The Riesz representation theorem expresses this derivative as an L2 inner product with a unique element of the statistical tangent space, the canonical gradient. A path family and the associated derivative remainder conditions must both be specified; a formal derivative along one convenient family does not establish differentiability along all paths.
An influence-function representer is a centered square-integrable function representing derivatives of a statistical functional along all admissible score functions. Representers may differ by a function orthogonal to the statistical tangent space. This pathwise definition is distinct from defining an influence function solely by point-mass contamination paths.
The canonical gradient is the influence-function representer in the statistical tangent space . It equals the orthogonal projection onto of any representer. Every other representer differs from it by an element of , so the Pythagorean theorem in an inner-product space gives it minimum variance. For in an unrestricted density model with bounded , it is .
Statistical estimation uses observed data to infer numerical properties of a population or model. A point estimator gives a value, while a confidence interval describes uncertainty with a specified coverage property. Maximum likelihood estimation is one approach; bias, variance, identifiability and the sampling or selection mechanism all affect an estimate's interpretation.
An estimation error is the difference between an estimator and the statistical parameter it estimates. It is a random variable before observing the sample. Its mean is the bias of the estimator, and its mean square is the sum of the variance and squared bias. Standardizing an estimation error by its standard error often yields an approximate standard normal distribution, allowing construction of a Wald confidence interval.
A statistical estimate is the realized numerical value of an estimator after observing a statistical sample. Before observation, the estimator is a random variable or random vector; its realized value is the estimate. Both are commonly written , so context distinguishes them.
A ratio estimator divides one statistic by another, for example an estimated joint moment by an estimated marginal probability. Its definition must specify what happens when the denominator is zero. A denominator bounded away from zero permits direct error bounds through .
Set , and define the estimator on zero-denominator events as part of the model. On , its error is at most . Centering and applying the Cauchy-Schwarz inequality gives the displayed bound, where is the expected error on . This controls a ratio estimator without falsely assuming that its numerator and denominator are independent.
Probability sampling chooses observational units by a specified random mechanism with known inclusion probabilities. This separates design-based representativeness from the convenience of obtaining particular observations. Simple random sampling, stratified sampling and cluster sampling are different designs with different precision and cost properties.
A finite population total adds a specified numerical value over every labelled unit in a fixed, finite population :The target must specify both the population and the measured variable. It may be a total inventory mass, the total number of employees across establishments, or the sum of a binary property. If , the total counts units having the property; it is not automatically the population size . A finite population mean is , when is known and positive.
An original inventory has four containers holding of a material. The total is and the finite population mean is per container. Giving every container the same mass fraction of an analyte is a separate assumption: the total analyte mass instead requires summing each container's mass multiplied by its own mass fraction. The target follows the physical quantity being added.
When only a sample is observed, the unweighted sample sum is generally not an unbiased estimator of . Using inclusion indicators and inclusion probabilities givesIf every , the Horvitz-Thompson estimator instead satisfiesThis is a consequence of the sampling design, without requiring the fixed population values to follow a statistical distribution.[ref]
A Generalization of Sampling Without Replacement From a Finite Universe by D. G. Horvitz and D. J. Thompson. 1952, finite-universe estimation framework, pp.663–685
A full census removes sample-selection variation, but imperfect measurement can still make the recorded sum differ from the intended physical total.Design-based inference evaluates an estimator by the random mechanism selecting a sample from a fixed finite population. Population values are held fixed; the selected subset is random under a known sampling design . ThusThe subscript identifies the source of randomness. An unbiased estimator of a finite population total has for each eligible fixed population. The unequal-probability total developed by D. G. Horvitz and D. J. Thompson is a central example.[ref]
A Generalization of Sampling Without Replacement From a Finite Universe by D. G. Horvitz and D. J. Thompson. 1952, unequal-probability sampling and unbiased finite-universe estimation
For an original example, let the fixed population values be and sample one label uniformly. Every inclusion probability is , so the Horvitz-Thompson estimator is . Its three equally probable values are , while the actual total is . Consequently,The estimator is unbiased even though none of its possible estimates equals the target. Unbiasedness describes averaging across the sampling design, rather than guaranteed accuracy in an individual sample.
A confidence interval with design-based coverage must likewise succeed at its stated rate across repeated selections under the specified design. That property requires a justified construction; unbiasedness of a point estimate alone supplies no coverage guarantee. Repeating a convenient calculation on the same selected units does not reproduce the selection process. Assumptions about measurement error or missing responses must also be stated separately, since knowledge of the original selection probabilities alone does not repair those later stages.
A sampling design specifies a probability distribution over the possible samples from a defined population:For sampling distinct labelled units, is a subset of the population. The design includes the selection mechanism, not merely the final sample size. A procedure with repeated draws can instead require a distribution over ordered sequences; the resulting inclusion probabilities concern whether a label appears at least once.
The design determines inclusion probabilities and joint inclusion probabilities throughThese connect the physical sampling procedure to the Horvitz-Thompson estimator and its sampling variance.[ref]
A Generalization of Sampling Without Replacement From a Finite Universe by D. G. Horvitz and D. J. Thompson. 1952, general unequal-probability sampling without replacement
An original comparison uses four fixed values and selects two units. Under simple random sampling, every one of the six pairs has probability . Each , so the Horvitz-Thompson estimator is twice the selected sum. It takes values with probabilities . Its expected value is the true finite population total , and its variance isA second design chooses only or , each with probability . It has the same sample size and the same individual inclusion probabilities, but the estimator is now or , giving variance . Pair selection matters even when individual representation agrees.
A third design chooses uniformly among the four pairs containing one label from each of those two groups. Its total estimate is always for this particular population. This illustrates the potential gain from stratified sampling when groups correspond to relevant variation, not a claim that the third design dominates for every possible population. A reproducible design records the eligible labels and actual random selection rule before interpreting the observed sample.
The Horvitz-Thompson estimator estimates a finite population total by expanding each observed unit's contribution by the reciprocal of its inclusion probability. D. G. Horvitz and D. J. Thompson introduced the general unequal-probability construction in 1952.[ref]
A Generalization of Sampling Without Replacement From a Finite Universe by D. G. Horvitz and D. J. Thompson. Original publication, Journal of the American Statistical Association 47(260), pp. 663–685, December 1952
Let be fixed values attached to labelled population units. A sampling design selects a random subset , with known inclusion probabilities . Thenwhere is the inclusion indicator. This is inverse probability weighting for a finite population.[ref]
Unequal Probability Sampling in Penn State STAT 506. Lesson 3, Definition 3.2, Horvitz–Thompson estimator
Its expected value is immediatelyThe subscript emphasizes design-based inference: the fixed values are not assumed to follow a probability model; the sample-selection mechanism supplies the randomness. The inclusion indicators need not be independent. Dividing by known gives an unbiased estimator of the finite population mean.For an original exact example, use values and choose samples , , with probabilities , respectively. The inclusion probabilities are . The corresponding estimates of the total are , andSimply multiplying each sample mean by three instead gives totals , with expected value . Equal treatment of the observed values ignores the unequal chances of observing them.
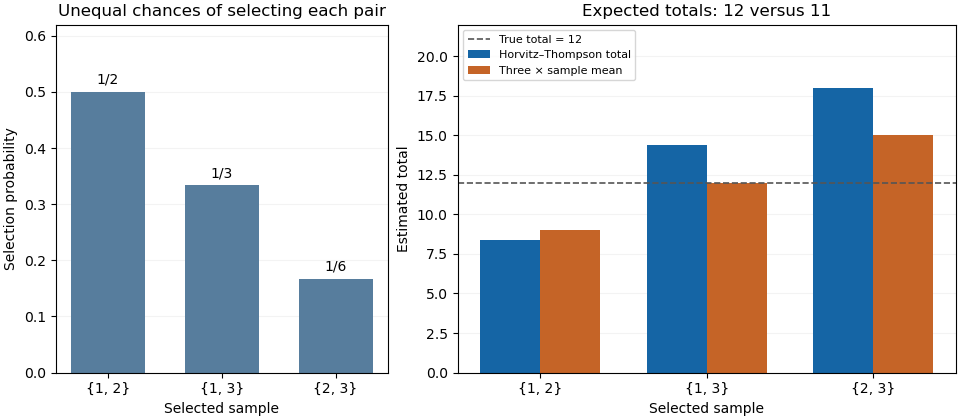
Inverse-inclusion weighting corrects the expected total in an unequal-probability sample
. Original exact enumeration of three possible two-unit samples from values 2, 4 and 6. The left panel shows their selection probabilities; the right compares the Horvitz-Thompson total with three times the sample mean. The population total is 12. Details.The sampling variance depends on pair information. Put , including . Bilinearity of covariance givesFor the three-unit design it is , found directly from . Thus an unbiased estimator need not give a nearly correct total in each sample.
With pairwise inclusion positivity, the same expansion device applied to pairs constructs the Horvitz-Thompson variance estimator:Its expected value equals the preceding population sum because . In the worked design its three possible values are , whose probability-weighted average is . This particular unbiased estimator of variance can therefore be negative for an individual sample. Its expected value identity is a statement about repeated selection.
If , an arbitrary unobserved cannot contribute to an unbiased total estimate. If a distinct pair has , its product cannot be recovered by the pair-expansion argument. Finally, dividing the weighted sum by the random sum of its inverse-probability weights changes the estimator into a ratio; the indicator proof above no longer establishes that this ratio is an unbiased estimator. The known population size and the actual sampling design are part of the result.
The Horvitz-Thompson variance estimator estimates the sampling variance of a Horvitz-Thompson estimator using observed values and known individual and joint inclusion probabilities. It is a random estimate of a fixed design-dependent variance, rather than the variance itself.
Let be an inclusion indicator, , and , with . For fixed population values , write . Bilinearity of covariance givesUnder pairwise inclusion positivity, a sample provides the estimatorThe diagonal terms are included. Taking expected values replaces by 1, proving . This is the pairwise counterpart of inverse-probability expansion for the finite population total.[ref]
An original exact example uses fixed values . Select with probabilities , respectively. Then , and the possible total estimates are . Their expected value is the true total 4, with varianceFor those same samples, the variance estimates are . Their expected value is also 2. In particular, for , the two diagonal contributions are 4 and 2, while the combined off-diagonal contribution is , giving .
Thus this unbiased estimator of variance can be negative in a realized sample. Replacing a negative result by zero changes its expected value; in this example that modification raises the mean estimate to . A positive square root is therefore not always available as a sample standard error from this particular formula. If some , dropping an unobservable cross-product does not preserve the proof; the missing term needs separate analysis.
The single-draw variance identifiability obstruction is the inability, for an unrestricted finite population, to construct a universally design-unbiased estimate of a total estimator's variance from just one observed unit. The estimator can estimate the total unbiasedly while the required cross-products for estimating its sampling variance are never jointly observed. This is an obstruction to the stated one-draw estimation problem, not a claim that a parameter can never be identified from repeated independent samples.
An original two-unit proof makes the distinction exact. Sample label or2 with equal probability and observe only . The Horvitz-Thompson estimator of the finite population total is . Its expectation is , and its design variance isSuppose a proposed variance estimate returns after observing unit1 and after observing unit2. Unbiasedness for every pair would requireThe left side is additive in the two unknown values, while the right side contains an unobserved product.
To prove impossibility without smoothness assumptions, evaluate both sides at . Every additive function has rectangular contrast . The required variance has contrast . The contradiction rules out such an unbiased estimator. Independent auxiliary randomization does not help: averaging it out merely replaces each by another function of the same single observed value.
Here the individual inclusion probabilities are positive, but the joint inclusion probability for distinct units is zero. The usual Horvitz-Thompson variance estimator needs pairwise inclusion positivity to turn sample cross-products into unbiased population cross-product estimates. The primary analysis of zero pairwise probabilities identifies precisely these missing terms.[ref]
Conservative variance estimation for sampling designs with zero pairwise inclusion probabilities by Peter M. Aronow and Cyrus Samii. §2.1, pair-expansion variance estimator; §2.2 and Proposition1, missing products under zero pairwise probabilities
Extra information can change the problem: observing suitable pairs, imposing a justified population relation, or accepting a model-based or conservative estimate uses assumptions absent from the proof. Observing one value also does not prevent writing a biased variance estimate. What fails is a single-draw unbiased estimator valid for every unrestricted population, even though the total estimator itself remains unbiased.
Sampling with replacement returns each selected label to the available population before the next draw. Independent uniform draws from a fixed population are independent and identically distributed; a label can recur. Replacement by itself does not imply uniformity or independence.
An inclusion probability is the probability that a particular unit belongs to the selected sample. For sample size in simple random sampling from labels it is . It differs from the selection probability at a particular draw position.
A joint inclusion probability is the probability that two specified population units both belong to a random sample :For the same unit twice, , where is its inclusion probability. For distinct units, is generally not : selection can make their inclusion indicators dependent. These probabilities describe the sampling procedure, rather than a relationship between the measured values of the two units.[ref]
Unequal Probability Sampling in Penn State STAT 506. Lesson 3, inclusion probabilities and finite-population estimation
For simple random sampling of distinct labels from labels, counting subsets containing both and giveswith value zero if . Since ,For , each unit has inclusion probability , but a particular pair has joint inclusion probability . Conditional on including one member, the other is included with probability , not .
Equal individual inclusion probabilities do not determine these pair probabilities. A different procedure that chooses only or , each with probability , still includes each unit with probability . Yet and . Thus two procedures can agree on individual representation while producing different dependence and different precision for a population summary. The distinction motivates keeping pair information when calculating the variance of weighted survey estimators; the classical general treatment is due to D. G. Horvitz and D. J. Thompson.[ref]
A Generalization of Sampling Without Replacement From a Finite Universe by D. G. Horvitz and D. J. Thompson. Publisher abstract and original publication, pp. 663–685
Pairwise inclusion positivity requires every distinct pair of population units to have positive joint inclusion probability under the sampling design:For Horvitz-Thompson variance estimator, the probabilities must also be known, and individual inclusion probabilities must be positive. Each pair can then, at least in principle, contribute an observed product to a pair-expansion estimate. Positivity is not independence: need not equal .[ref]
Conservative variance estimation for sampling designs with zero pairwise inclusion probabilities by Peter M. Aronow and Cyrus Samii. Section 2, conditions for measurability; section 2.1, pair expansion
For simple random sampling of distinct labels from , . Consequently, gives pairwise positivity, whereas selecting exactly one label gives positive individual inclusion probabilities but zero probability of ever observing two distinct values together. This distinction separates unbiased total estimation from unbiased estimation of its sampling variance.
An original two-unit proof shows what information is missing. Sample one of two fixed values uniformly. The Horvitz-Thompson estimator is or , and its variance isAny estimator based only on the observed label and value has expected value of the form . Its mixed difference over is zero. The target's mixed difference is insteadNo such estimator can therefore be unbiased for this variance for every possible pair of values. Additional randomization internal to the estimator does not help: conditioning on the observed data still produces functions of this same separated form. This is an information limitation, not division by zero that can be repaired by assigning a convenient numerical convention.[ref]
Conservative variance estimation for sampling designs with zero pairwise inclusion probabilities by Peter M. Aronow and Cyrus Samii. Sections 1 and 2.2, impossible unbiased recovery of jointly unobservable cross-products
Strict positivity alone also does not guarantee useful precision. A very small produces a large inverse-probability multiplier on a rare observed pair. Designing a usable survey therefore requires attention to both observability and the resulting sampling variance.
An inclusion indicator records whether a specified population unit appears in a sample :It is an indicator random variable, with expected value and variance . Its randomness comes from sample selection; the population value attached to unit may be treated as fixed in a sampling calculation.[ref]
Unequal Probability Sampling in Penn State STAT 506. Lesson 3, inclusion probabilities and inverse-probability total estimation
Inclusion indicators turn a sum over a changing sample into a sum over fixed population labels:If every , the same identity immediately provesThe inverse-inclusion-probability total is unbiased because , not because the selected units must look typical in every realization.
Pair products connect the notation to joint inclusion probabilities: , so . For a fixed sample size , in every realization. Consequently,In simple random sampling with , the four individual variances sum to , while the six distinct pair covariances are each . Their doubled sum is , giving total variance zero. Treating the inclusion indicators as independent would incorrectly predict a random sample size. The notation makes that error easy to detect.
Unequal probability sampling assigns different inclusion probabilities to different population units. Estimating an unweighted population summary generally requires accounting for these differences in the estimator.
The finite population mean for is the arithmetic mean of all fixed values in the target population. Under simple random sampling, the sample mean is an unbiased estimator of it.
For , the finite population variance measures spread about the finite population mean. Survey-sampling formulas commonly use denominator ; the denominator- version is . The normalization must be specified when using a finite population correction.
Sampling without replacement selects distinct labelled units: after a unit is selected it is unavailable for the remaining draws. Distinct labels can carry equal numerical values, so repeated values do not necessarily imply a repeated unit. The rule alone does not specify selection probabilities; a procedure favoring particular units is still sampling without replacement but need not be simple random sampling.
In uniform sequential sampling without replacement, the next label is chosen uniformly among those remaining. For a population of labels, any ordered sequence of distinct labels has probability . Each size- subset has possible orders, so its probability is . This gives the fixed-size simple random sampling design. Equivalently, take the first labels of a uniformly random permutation. Restricting a uniformly random permutation to a specified label set preserves uniformity; biased modulo mappings should not replace uniform selection.
The draw positions have identical marginal probability distributions, but exhibit statistical dependence. If the first label is , the conditional probability that the second label is is zero, whereas its marginal probability is . Thus these draws are not independent and identically distributed when and . For a marked subset of labels, counting size- subsets with binomial coefficients gives the hypergeometric distribution. The resulting negative covariance explains the finite population correction for both counts and sample means.
Draw two distinct positions uniformly from a fixed population with . Let and . Each draw has expected value , whileSubtracting the product of the expected values proves the covariance formula and explains the finite population correction. If the sampled values are coin biases and the actual tosses are conditionally independent given those biases, the law of total covariance gives the same covariance for their head indicator random variables.
Take a uniformly random permutation of distinguishable objects, of which are marked. Let mean that position is marked. Every object is equally likely at a specified position, so . For distinct positions , their ordered pair is uniform among distinct-object pairs, of which are marked pairs. This proves the second formula. For , the conditional probability is .
For the count of marked objects among the first positions, indicator random variables and linearity of expectation give . These draws are exchangeable but generally dependent; equal marginal probabilities do not imply independence.
Draw balls sequentially without replacement from green and red balls. Let be the first positive draw count at which the numbers of drawn green and red balls agree. For ,where denotes the falling factorial and is a Catalan number. Odd first return times are impossible because equality requires an even total number of draws.
To count the successful colour orders, encode green by a step and red by a step . If the first step is positive, a first return time means that the partial sums remain strictly positive until the last step. Delete the first positive step and the last negative step, and shift the remaining heights down by one. The result is a Dyck path of length , of which there are . Interchanging the colours doubles this count. Every such colour order has the same probability under sampling without replacement, namely , proving the formula. In particular, the numbers of successful colour orders at lengths two, four and six are two, two and four; balanced orders with an earlier return must not be counted.
When items among are marked, inspect a uniformly random permutation until the first marked item. For its first position to be , the other marked positions must lie among the last slots. This yields the displayed law with support . It is the first-success form of sampling without replacement. For one marked item the position is uniform, while its conditional success chance after failures increases to .
Cluster sampling chooses groups of observational units, such as production days, rather than dispersed individual units. Testing every unit in a selected group is a one-stage cluster sample. Positive within-cluster intraclass correlation reduces the information supplied by a fixed number of sampled units, although collecting clustered observations can be cheaper.
The design effect is a sampling variance under a complex design divided by the corresponding simple-random-sampling variance. For independent equal-size clusters of size with exchangeable intraclass correlation , a common mean-estimation approximation is . It expresses the loss of effective sample size from positive correlation; finite-population and unequal-cluster-size designs require their own calculation.
Stratified sampling partitions a population into strata and samples separately within each. It guarantees specified representation and can improve precision when the strata describe population variation. Equal sampling fractions give equal unit inclusion probabilities; unequal fractions require appropriate weighting for population summaries.
Suppose the variance is and the sampling cost is , with positive costs, variance coefficients and budget. The Cauchy-Schwarz inequality gives . Equality forces proportional to and a tight budget, proving the displayed unique optimum. The minimal variance is . For the optimization Lagrangian , the multiplier and budget derivative both equal . Therefore a small resource change changes the optimum by . This is a continuous allocation; integer sample-size restrictions define a separate optimization problem.
Here simple random sampling means a random unordered subset of exactly distinct labels from , with every size- subset equally likely. The sample size is fixed in advance, , and sampling without replacement prevents duplicate units. This is SRSWOR; some texts also use "simple random sampling" for independent uniform draws with replacement, which is a different design.[ref]
Chapter 2: Simple Random Sampling. Sampling Theory, Chapter 2, Simple Random Sampling, PDF pp. 1–4: replacement conventions and ordered versus unordered sample probabilities
Every label has inclusion probability , but equal inclusion probabilities alone are insufficient. For example, from six labels choose either or with probability . Each label is included with probability , yet eighteen of the twenty size-three subsets are impossible: this is a two-group cluster sampling design. Unequal probability sampling deliberately changes inclusion probabilities, often to improve precision for a particular estimand, and generally requires an appropriately weighted estimator rather than the plain sample mean.
Consider the original mathematical population with labelled values , and let . The fifteen equiprobable subsets, followed by their sample means, areTheir sample means sum to , giving expected value . Their squared deviations from sum to , giving variance . This is an enumeration over hypothetical selections from six stipulated numbers, not measured survey data.
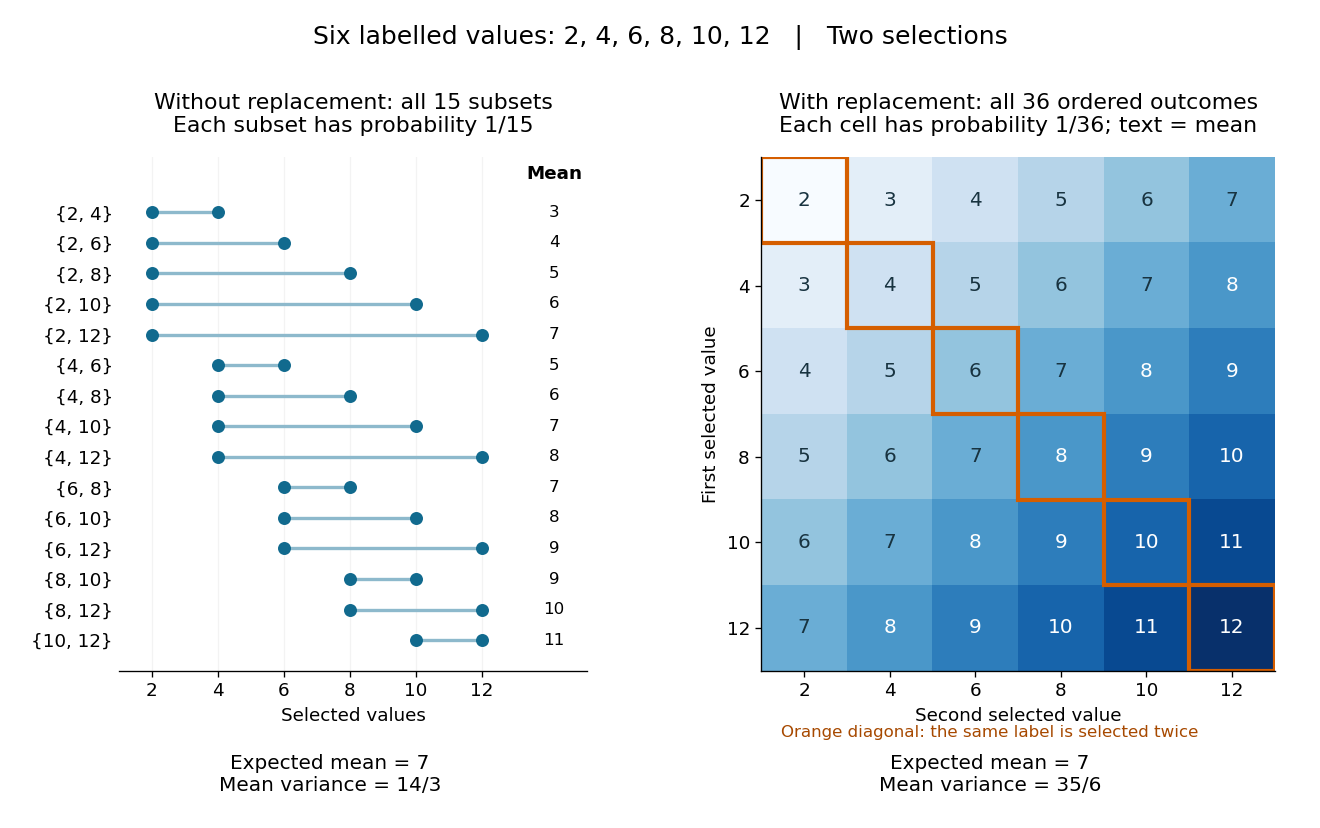
All fifteen size-two subsets and all thirty-six ordered replacement outcomes from six labelled values
. Details. With independent uniform sampling with replacement, the ordered outcomes each have probability . The two orders and are distinct outcomes, and is now possible. Forgetting order does not make the resulting unordered multisets equiprobable: has probability but has probability . The thirty-six sample means still have expected value , but their squared deviations sum to , giving variance . Avoiding duplicate labels improves precision for this fixed population.
In finite-population sampling, a simple random sample of fixed size without replacement is a subset of labelled units drawn so that every size- subset has probabilityThe sample is the selected subset; simple random sampling is the procedure that generates it. This definition does not require the observed values to be distinct, only the selected population labels. The without-replacement convention is important because an independent repeated draw from a population is a different design.[ref]
Unequal Probability Sampling in Penn State STAT 506. Lesson 3, simple-random-sampling specialization
One construction randomly orders all labels and takes the first . Each particular subset can occupy those positions in permutations, out of , proving the probability above. Equivalently, draw successively and uniformly from the remaining labels, then discard their order.
For , there are possible samples. A particular unit belongs to four of them, so its inclusion probability is ; a particular pair is one complete sample, so its joint inclusion probability is . These are properties of the procedure before observing which subset was obtained.
A simple random sample need not resemble the whole population in every realization. For fixed values , six of the ten size-two samples contain only zeros. Thus the sample mean is zero with probability , although its expected value is the finite population mean . The remaining four samples each have mean , giving . Unbiasedness concerns repeated selection, rather than a guarantee about any one sample. Coverage of the population labels and faithful implementation of the selection rule remain essential.
Fix real population values . Define the finite population mean and two normalizations of the finite population variance byThe values are fixed; only the selected subset is random. For its sample mean , the exact design expectation and variance areThe sample mean is an unbiased estimator of the finite population mean. At , every unit is observed and exactly, so the variance is zero. The case is deterministic and is handled directly, since is undefined then.[ref]
Chapter 2: Simple Random Sampling. Sampling Theory, Chapter 2, PDF pp. 2, 6–9: variance normalizations, unbiasedness, covariance derivation and finite population correction
The finite population correction depends on the baseline. With the normalization it is multiplying . With the normalization it is multiplying , the exact variance for independent uniform sampling with replacement. The standard error uses the square root of the relevant variance factor. Mixing the two normalizations gives a wrong answer even at , when replacement cannot matter. For the six-value example, , , and , reproducing without replacement and with replacement.
A short proof exposes the statistical dependence. Let be the value at position in uniform sequential sampling without replacement, so each has expected value and variance . Write . Every ordered pair of distinct labels is equally likely, and , hence for ,Linearity of expectation proves unbiasedness without requiring independence. The variance of a sum includes all ordered covariance terms, givingFor the original population, each pair of distinct draw positions has covariance . Drawing a high value leaves a lower mean among the remaining values, balancing subsequent draws. Equal marginal probability distributions therefore coexist with negative covariance.
When , the sample variance is an unbiased estimator of . To check this independently, use : its expected value is . Thus unbiasedly estimates the variance of the sample mean; its square root estimates the standard error, but need not be unbiased.[ref]
Chapter 2: Simple Random Sampling. Sampling Theory, Chapter 2, PDF pp. 10–12: sample-variance and standard-error estimation
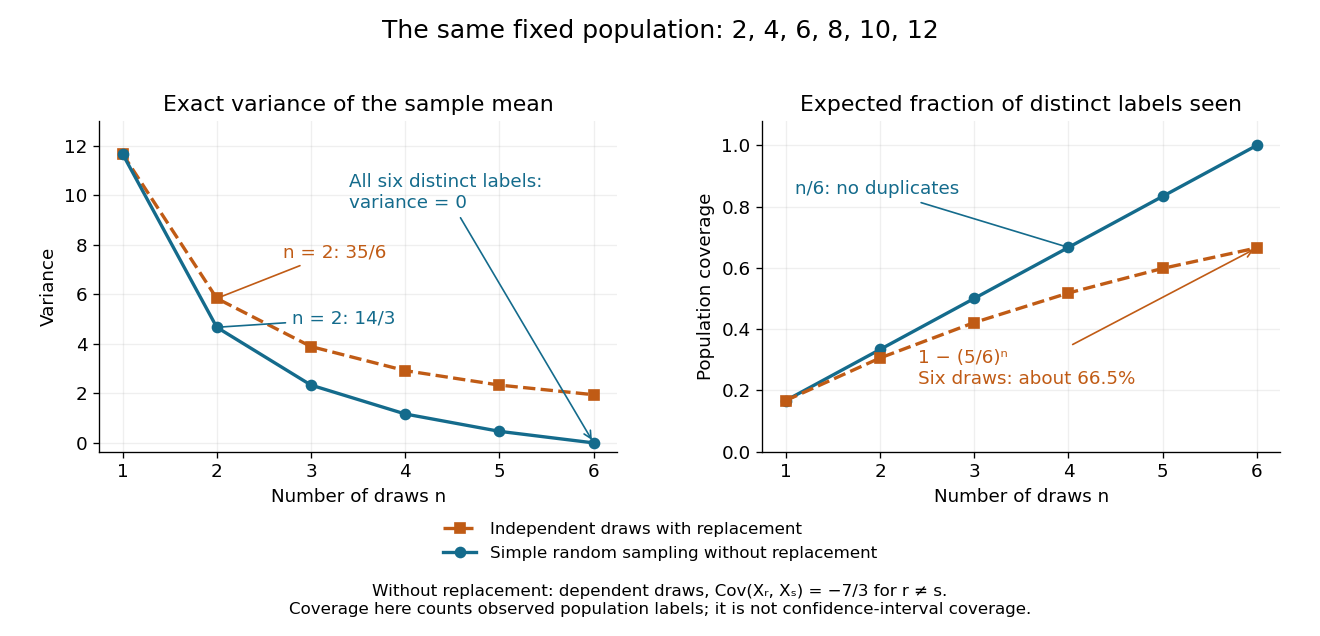
Exact mean variance and expected distinct-unit coverage as sample size grows in the six-value population
. Details. The diagram compares variance with the expected fraction of distinct population labels observed. Without replacement this fraction is exactly ; with independent uniform sampling with replacement, a label is missed with probability , so linearity of expectation gives expected fraction . At six draws, replacement covers only about of labels on average and retains sample mean variance ; sampling all six distinct labels covers the population completely and removes selection uncertainty. This population coverage is distinct from confidence interval coverage probability.
The correction matters when the sampling fraction is appreciable. It calibrates uncertainty about this fixed population under the specified selection mechanism. It does not correct unequal selection weights, missing observations or measurement errors; observing every label also does not eliminate uncertainty about a larger unobserved population. Moreover, an exact variance alone does not guarantee the coverage probability of a proposed confidence interval: a small discrete sampling distribution can make a normal approximation inaccurate.
The sampling fraction is the sample size divided by the finite population size. In simple random sampling, it determines how much the finite population correction reduces the variance relative to .
A scoring rule turns a probability distribution forecast and an observed outcome into a number. For example, a forecast of rain with probability should express uncertainty more usefully than a bare prediction of rain. A scoring rule lets us compare such forecasts after observations arrive, and its choice determines whether exaggerating confidence pays. A proper scoring rule rewards an honest account of uncertainty in expected value.
There are two sign conventions. A reward is maximized; a loss function is minimized. The conversion reverses every comparison. Here the linear probability score is a reward, while the binary Brier score and the negative logarithmic scoring rule are losses. Calling all three a "score" without specifying the direction would hide the central difference.
Throughout the binary examples, the random variable has a Bernoulli distribution with actual success probability , and the report assigns probability to and to . The value is stipulated by this statistical model; it is not inferred from data or a claim that a forecasting system is calibrated. In practice the true predictive distribution is unknown, and the relevant is the conditional probability of success given the information available when the forecast is issued. Propriety evaluates incentives for reporting that predictive distribution; it does not supply the unknown probabilities.
The linear probability score pays the reported probability of whichever binary outcome occurs. With report and observed , its reward isIt looks sensible: assign more probability to what happens and receive more reward. But the expected value under a Bernoulli distribution with true success probability isThis is an affine function of the report. When , the maximum over is at ; when , it is at . At , every report ties. Thus the linear probability score encourages reporting certainty about the more likely outcome and is not a proper scoring rule.
For the stipulated , the expected value of the reward is . Honest reporting earns in expectation, whereas earns . The forecaster improves expected reward by replacing a 70% forecast with a 100% forecast. The Brier score and logarithmic scoring rule avoid this incentive, as the expected-score diagram under proper scoring rule shows.
A proper scoring rule makes reporting the true probability distribution optimal in expected value, for every true probability distribution in the allowed class of forecasts. In the reward convention, the inequality in the title holds for every report and true law . The expected value is always taken under , because the report does not change how the outcome is generated. In the loss convention the same definition readsThis requirement makes a proper scoring rule useful for eliciting probabilities and comparing predictive distributions: deliberately distorting a known forecast cannot improve its expected reward or expected loss. The reward convention and its strict version are set out in Strictly Proper Scoring Rules, Prediction, and Estimation by Tilmann Gneiting and others (Section 1).
For the Bernoulli distribution with , the Brier score has expected loss , and the negative logarithmic scoring rule has expected loss . Both are minimized at the honest report . The linear probability score, by contrast, maximizes its expected reward at . These are statements about averaging over both possible outcomes with their actual probabilities.
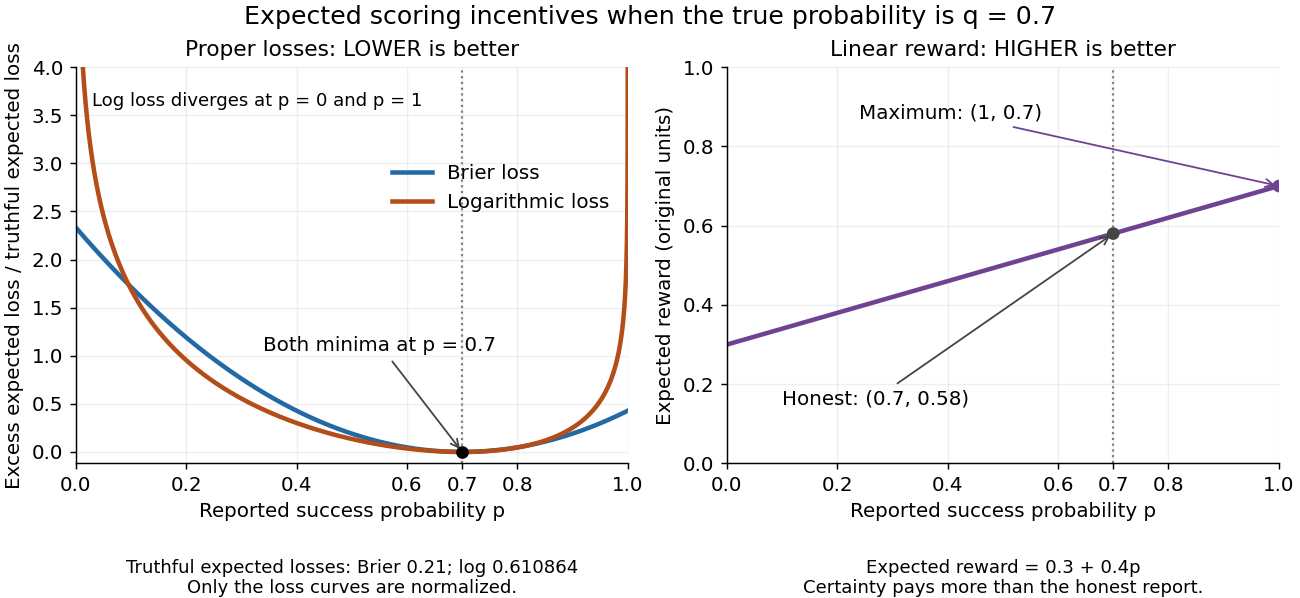
Expected losses of the Brier score and logarithmic scoring rule favor ; the linear probability score rewards
. Details. The left panel displays each excess expected loss divided by that rule's expected loss at : for the Brier score and approximately for the logarithmic scoring rule. This normalization permits comparison of curve shapes and preserves the minimizing report, since it subtracts a constant and divides by a positive constant independent of . Zero means no excess expected loss. The right panel shows the unmodified linear probability score reward, with its maximizing direction labeled explicitly.
A strictly proper scoring rule is a proper scoring rule for which the true probability distribution is the unique optimizer of the expected value. Equivalently, any different admissible probability distribution gives strictly larger expected loss. For probability density functions, two densities that agree almost everywhere represent the same probability distribution. Ordinary propriety permits ties: the constant reward is a proper scoring rule, because every report ties, but it is not a strictly proper scoring rule and elicits no information.
Strict propriety concerns expectation, not guaranteed success on each observation or each realized dataset. With the stipulated Bernoulli distribution , suppose the outcome is . The honest report then has Brier score loss , while has loss . The logarithmic loss similarly gives losses and . The honest forecast loses this comparison on that draw, which occurs with probability in the stipulated statistical model.
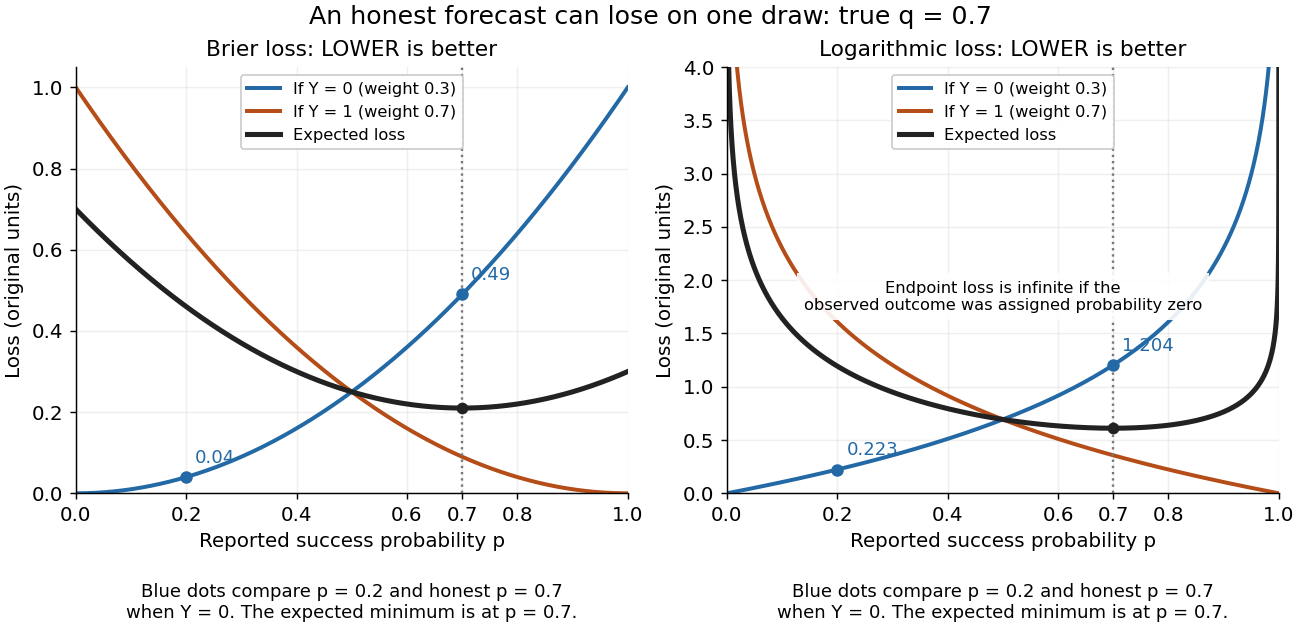
Individual outcomes can favor a different report even though the expected Brier score and logarithmic loss are uniquely minimized at
. Details. The loss curves favor , and the loss curves favor . Their weighted average, with weights and , favors . Choosing a report after observing would use information unavailable at forecast time. Even an average loss on a finite dataset can rank an honest forecast below a competing forecast through outcome variation; strict propriety guarantees the ranking in expected value under the specified information and true predictive distribution.
The binary Brier score applies squared-error loss to a reported success probability and the observed indicator . It is a loss, so smaller is better. Its values lie in : predicting the outcome with certainty gives zero, while assigning it zero probability gives one. Unlike the logarithmic scoring rule loss, the binary Brier score remains bounded even for a confidently wrong forecast.
For a Bernoulli distribution with true success probability , averaging the two squared losses givesThe report controls only ; the remaining term is the variance of the Bernoulli random variable. Consequently the Brier score is a strictly proper scoring rule. At , the expected loss is , with unique minimum at . Reporting instead gives expected loss , despite its better loss on the particular outcome above.
For several possible categories, the Brier score sums the squared differences between reported probabilities and observed category indicators. With two categories that sum is , so its numerical values are twice the binary convention used here, with the same optimizing report. Brier's original [ref]
https://www.u-cursos.cl/ingenieria/2025/1/CI71C/1/material_docente/bajar?bajar=1&id=8745481. Verification of Forecasts Expressed in Terms of Probability (1950), equation (2)
averages these category-sum losses over forecasts. Strictly Proper Scoring Rules, Prediction, and Estimation by Tilmann Gneiting and others (Section 3.1, Example 1, and Table 1) gives the category-sum and binary forms as negative rewards; negating them gives the losses described here.The logarithmic scoring rule rewards the natural logarithm of the reported probability mass or probability density at the observed outcome. The title uses the reward convention. For a binary report , its negative is the logarithmic loss:For this is ; for it is . At an endpoint, use these outcome-specific forms: assigning zero probability to the outcome incurs infinite loss, while assigning it probability one gives zero. The natural logarithm therefore makes a confidently wrong binary forecast far more costly than the bounded Brier score does.
Under the stipulated Bernoulli distribution with , the expected logarithmic loss isIts unique minimum is at , where the expected loss is approximately . At it is approximately . More generally, the excess expected logarithmic loss over truthful reporting is the Kullback-Leibler divergence in the order true law first, reported law second:For , this Kullback-Leibler divergence is nonnegative and vanishes only at , explaining why the logarithmic scoring rule is a strictly proper scoring rule. The same Kullback-Leibler divergence identity applies to probability density functions relative to a common measure when the truthful expected logarithmic loss is finite and the comparison expected value is well defined.[ref]
Strictly Proper Scoring Rules, Prediction, and Estimation by Tilmann Gneiting and others. Section 3.1, Example 3, and Section 4.1
For sequential forecasts, the existing prequential log score identity explains how logarithmic rewards add over observations.The probability chain rule makes a sum of sequential predictive log scores equal the log Bayesian model evidence when the forecasts are coherent Bayesian one-step predictions under proper priors. Differences of total scores are therefore log Bayes factors.
The number of free dimensions remaining after specified constraints often determines a reference sampling distribution. In a full-rank normal linear model with observations and mean coefficients, the residual space has dimension . A regular nested likelihood-ratio test instead uses the difference in free statistical parameter dimensions. Boundary constraints may invalidate this regular calibration.
A statistic is a measurable function of observed data whose definition does not involve an unknown parameter. It may be scalar or vector valued. Sufficient statistics summarize all information about a parameter in the conditional-distribution sense.
A statistic is complete for a parameter family if the displayed implication holds for every measurable integrable under all parameter values. This property does not itself assert sufficiency; a complete sufficient statistic has both properties. A nonconstant unbiased estimator of a known constant provides a direct obstruction to completeness.
Bounded completeness requires the defining implication for a complete statistic only for bounded measurable functions. Completeness implies it, but the converse need not hold. If a sufficient statistic gives a parameter-independent event probability and the conditional probability of that event is nonconstant, then is a bounded zero-mean obstruction to bounded completeness.
A meta-analysis combines statistical evidence from several studies addressing a common estimand. It may assume a shared effect or use a random-effects meta-analysis to represent between-study variation. Inverse-variance weighted means combine independent effect estimates when their variances are known or estimated; differences in study validity and effect modifiers require substantive assessment, not just weighting.
Divide studies by a specified characteristic and estimate an effect in each subgroup, then test the difference using an independent subgroup contrast in meta-analysis or an appropriate interaction model. The test of a between-group difference is distinct from separate tests against no effect within each group. Exploratory splits can be affected by multiple testing and by confounding between study characteristics.
A forest plot shows each study's effect estimate and confidence interval, together with a pooled estimate when appropriate. A vertical null-effect line allows comparison on a common scale. For an odds ratio the null is one and a logarithmic axis treats reciprocal ratios symmetrically; marker areas commonly encode study weights.
A funnel plot displays study effect estimates against a measure of their precision, often standard error increasing down the vertical axis. Under a common-effect model, imprecise estimates spread more widely around the effect. Asymmetry is evidence of a small-study effect and can be consistent with publication bias, but it has other possible explanations.
A small-study effect is a systematic relationship between study precision or size and estimated effect. It may result from selective publication, design differences, effect modification or other heterogeneity. A regression of effect on its standard error tests one such relationship; it does not by itself determine which mechanism generated it.
Publication bias arises when the availability of studies depends on the results, such as their significance, magnitude or direction. A meta-analysis of the available studies can then differ systematically from one including all eligible evidence. Funnel plot asymmetry can motivate investigation but does not establish this mechanism; heterogeneity and other small-study effects can also cause asymmetry.
A selection model combines a distribution for all study results with a probability that a result becomes available. The observed distribution is reweighted by this probability and renormalized. Assumed or estimated selection mechanisms permit sensitivity analysis of a meta-analysis, but unavailable results generally prevent a fully assumption-free correction.
For studies conditionally independent given the truth of one relationship, the event that at least one is positive has probability under the alternative and under the null. Its Bayes factor therefore gives the displayed posterior odds. For interior error probabilities these tend back to the prior odds . If power exceeds size, the Bayes factor decreases to one: the quotient of geometric sums is a weighted average of decreasing powers .
This result concerns the coarsened selection event. Full observed results instead multiply their individual Bayes factors, and concordant evidence can accumulate without this bound. It is a useful example of information discarded by publication bias.
Trim and fill estimates missing studies from funnel plot asymmetry by trimming extreme studies to locate a centre and filling in counterparts on the less represented side. The adjusted meta-analysis includes these imputed estimates. Its interpretation depends on a symmetry model for missing evidence; it is not a guarantee that genuine publication bias has been removed.
For independent subgroup estimates with variances , the null contrast has Wald statistic . If evidence overlaps, include minus twice the covariance in the contrast variance. A nonsignificant comparison is not proof of equivalence.
Systematic displacement of an individual study estimate caused by design, conduct, analysis or selective reporting. Combining estimates can reduce random error without reducing this bias. Bias-adjusted meta-analysis and analyses restricted or stratified by relevant bias domains can assess its impact.
Model study estimates as noisy versions of the target effects plus study-specific biases. External information or sensitivity parameters describe those biases and their uncertainty. Removing an assumed bias without propagating its uncertainty overstates precision; observed study data alone generally do not identify the adjustment.
Articles were limited to the first 100 out of 573 total.
Articles by others on the same topic



Statistical inference is a branch of statistics that involves drawing conclusions about a population based on a sample of data taken from that population. It provides the framework for estimating population parameters, testing hypotheses, and making predictions based on sample data. The primary goal of statistical inference is to infer properties about a population when it is impractical or impossible to collect data from every member of that population.