The surviving four-page PDF does not include the separate S-Plus output sheets. Consequently it does not identify several fitted formulas, coefficients, test results or survival-table crossing times. The solutions below derive the identifiable results and explain the output interpretation; numerical conclusions requiring those absent sheets are distinguished explicitly from what the printed information establishes.
The official PostScript edition has also been rendered and checked: it has the same four pages and contains no separate output sheets.
For a group with sample size , let be its overweight count. The natural sampling model is a binomial distribution, , with observed proportion . A grouped-binomial logistic regression specifiesFitting event/nonevent counts, or fitting the proportions with weights , gives the same binomial likelihood. The weights represent trial counts; unweighted regression of the proportions would give small and large groups the same influence. If printed percentages are rounded, exact original event counts are preferable to manufacturing fractional counts from .
Year should ordinarily be a factor with three levels unless a linear trend over time is specifically intended. Country, sex and age group are also possible factors. The actual subset, reference levels and formula are absent from this PDF. For a year-by-age interaction term, writeWith treatment contrasts, is the baseline logit, and are effects at the reference level of the interacting factor, and is an additional difference of log-odds differences. Exponentiating a main-effect contrast gives an odds ratio; exponentiating an interaction contrast gives a ratio of odds ratios. It is incorrect to interpret a main effect as a constant effect across the other factor when the interaction term is present.
A coefficient table should be read as estimate, standard error, a Wald estimate/error ratio and its reference-distribution probability. A whole multi-level interaction term is better tested by a nested likelihood-ratio test, using the decrease in deviance and the number of added independent coefficients. Null and residual deviances, residual degrees of freedom, convergence and fitted probabilities should all be checked. Large residual dispersion suggests lack of fit or dependence within sampled schools; a quasibinomial regression or an appropriate clustered analysis may then be preferable. Residual deviance is not automatically a valid chi-squared goodness-of-fit statistic for sparse groups or after estimating a free dispersion.
An interaction plot should display the group means or fitted probabilities against year, with separate lines for the interacting factor, and should also inspect the link scale. Nonparallel probability curves alone do not establish a logit interaction: even an additive logit model transforms nonlinearly to probabilities. As an independent descriptive illustration, the original study's Table 2 reports English boys' age-specific percentages. The following original plot shows their widening age differences after 1984 on both scales. It uses published descriptive values, not a reconstruction of the absent examination fit. The data are from pmc.ncbi.nlm.nih.gov/articles/PMC26603/ .
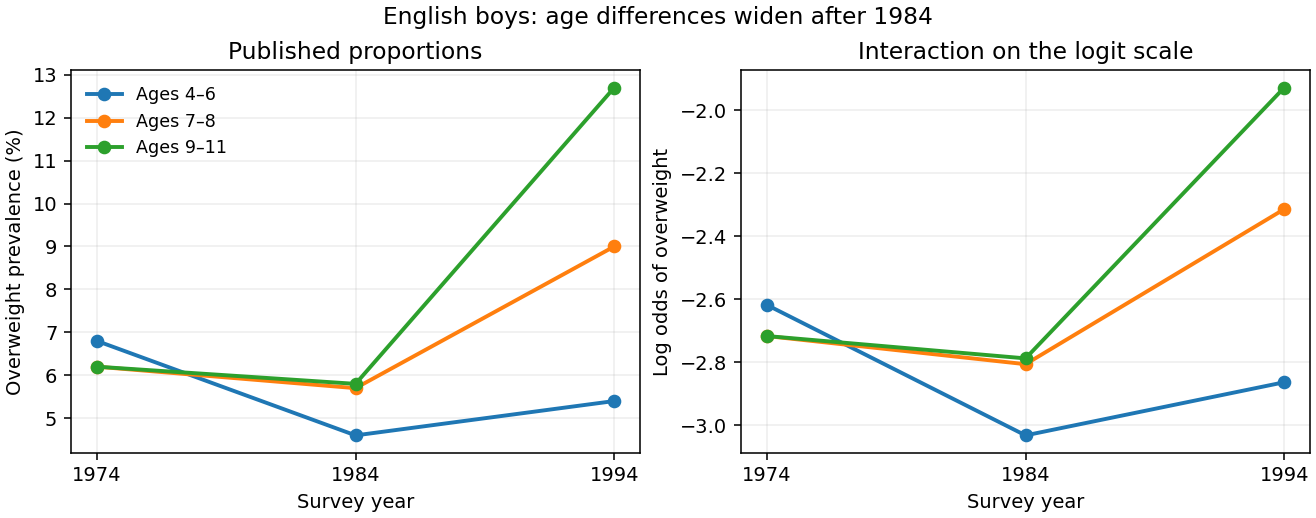
Published English boys' overweight prevalence by age and year, shown on probability and logit scales
. Details. 
For example, on the probability scale the 1984–1994 increase for the oldest group exceeds that for the youngest by percentage points using the rounded table values. On the logit scale the corresponding difference of differences isThis describes the interaction pattern, but its sampling uncertainty requires the group counts. The absent output prevents identifying the exam fit's coefficient estimates and significance tests.
There are two different uses of Poisson regression. A rare-event approximation models withThe fixed offset accounts for exposure, and exponentiated slopes are risk ratios, not odds ratios. The approximation is most appropriate when probabilities are small; it is not exact for appreciable prevalence because binomial variance is rather than .
An exact alternative stacks event and nonevent counts in each group and fits a log-linear model with a separate group intercept and event-by-predictor effects:Conditioning on their total gives the binomial event probability , whose logit is exactly . Profiling the group intercepts enforces the observed totals and reproduces the grouped-binomial logistic regression. This Poisson surrogate for a conditional multinomial model is exact and should not be confused with the rare-event approximation.
The missing output is needed to identify the actual regression formula, response column, transformations and coefficient estimates. A useful possible analysis regresses the maintained-school percentage among acceptances on the corresponding percentage among applications, allowing for year; it must be described as a model of college-level composition, not a direct estimate of individual acceptance probabilities.
For instance, if and are these two percentages, a normal linear model might specify , with a slope-by-year interaction term if needed. The intercept is the expected response at zero predictor, often an extrapolation; the slope is a percentage-point change in acceptance composition per percentage-point change in application composition. A slope of one is not by itself evidence of equal acceptance chances: equal chances within every college would give the entire relation , including zero intercept and no year shift. A fit with positive slope mainly confirms that applicant composition helps predict acceptance composition.
Regression diagnostics should include residuals versus fitted values and predictors, a residual normal Q-Q plot, checks of heteroscedasticity, regression leverage, studentized residuals and Cook's distance. The aggregate mature-college category merits an influence check and a sensitivity analysis: combining several colleges can conceal different within-college patterns. Repeated observations from the same college across years may have correlated errors, so treating them as independent needs justification. Check nonlinearity, the year interaction and the effects of excluding no observation except with a substantive reason.
Percentages are bounded, and their precision depends on their denominators. A simple weighted least squares or binomial analysis requires the underlying numbers accepted, not merely percentages. For a proportion based on people, the working variance is under independent sampling, rather than constant across colleges. If the predictor percentage is itself estimated, an ordinary regression also ignores its uncertainty. The supplied summaries cannot recover all four cells of each college contingency table or the actual fitted numerical output.
The published Cambridge percentage table nevertheless allows a descriptive comparison of acceptance rates. Write for the maintained-school proportion among applicants and for its proportion among acceptances. The relative risk from group compositions givesThe overall acceptance probability cancels by Bayes' theorem. This risk ratio compares acceptance probabilities; it is not the acceptance odds ratio, which also needs the overall acceptance probability.
For Christ's, the two published application/acceptance pairs give risk ratios and . If the displayed percentages were rounded to the nearest whole percentage point, the relative risk bounds from rounded group compositions give ranges approximately and . Thus both comparisons remain below one under that rounding assumption. These are descriptive comparisons of observed groups, without adjustment for applicant qualifications or a causal effect interpretation. The published compositions determine approximate relative acceptance rates, but not their standard errors or the original regression results.
The printed formula expands to the main effects of school type, acceptance and college, together with school-type-by-college and acceptance-by-college interactions. It contains neither a school-type-by-acceptance interaction nor the corresponding three-way interaction. Its Poisson regression model is thereforeFor every college the mean table has odds ratioThus it tests conditional independence of school type and acceptance given college, while permitting both margins to vary freely across colleges. It does not merely assert a common, possibly nonzero association.
The maximum likelihood estimation score equations match every school-type-by-college and acceptance-by-college margin. Solving them gives the stratified two-by-two conditional independence model's fitted countsIndeed these counts factor by row and column and have exactly the observed margins. For nondegenerate tables there are three free mean parameters per college: one total and two independent margin proportions. There are cells and parameters, hence 25 residual degrees of freedom. The residual deviance iswith zero-count contributions interpreted as zero. The Poisson linear terms cancel because the fitted totals equal the observed totals. Under the null and suitable large-count regularity, compare with . Sparse cells, structural zeros or degenerate margins require a different calibration, such as an appropriate conditional test or simulated reference distribution.
A large residual deviance is evidence of school-type/acceptance association in at least some colleges. A small one indicates compatibility with conditional independence, not proof of identical admission processes or absence of selection on qualifications. Residuals and individual college contrasts locate departures. Adding the school-type-by-acceptance term gives a common odds ratio, one extra parameter and 24 residual degrees of freedom. Adding the full three-way term permits each college's association and saturates the tables. The first comparison tests a common association; the second checks whether a common association is adequate. No frequencies are supplied here to evaluate these tests numerically.
The output must first identify the response scale and the formula. If the initial fit is ordinary least squares to the untransformed response with all fifteen predictors and an intercept, its normal linear model isFor full rank , the residual degrees of freedom are . The residual standard error is and estimated coefficient covariance is . A coefficient test divides the estimate by its standard error and compares with a reference distribution; the overall test of all fifteen slopes compareswith . The intercept-only residual sum is . Adjusted R-squared penalizes the loss of residual degrees of freedom, unlike ordinary .
Each regression coefficient measures a conditional association holding the other columns fixed. The southern-state indicator compares two state categories at equal values of all other predictors. Rescaling changes the units of a coefficient, so one cannot infer effects per original currency unit or per original percentage unit without the scaling information. If the actual formula uses , exponentiating a coefficient gives a multiplicative response change rather than an additive change; if both response and a predictor are logged, the slope is an elasticity. These interpretations cannot be interchanged.
The two police-expenditure variables are likely strongly associated and need a multicollinearity check: individual coefficients can be unstable even when their joint contribution predicts well. Their actual correlation should be calculated, not presumed numerically. Similar considerations apply to age-specific unemployment. With only 47 observations and up to 16 mean parameters, examine regression leverage, Cook's distance, residual distribution, variance versus fitted values, nonlinear effects and predictive cross-validation. State-level geographical dependence may also violate the independent-error model.
The observations are aggregate states. An association between a state covariate and crime rate is not an individual causal effect: ecological fallacy, confounding and reverse causation are relevant. For example, greater recorded crime can induce greater police expenditure. The absent coefficient table and model call prevent deciding which predictors were significant or even whether the fitted response was transformed. The preceding degrees of freedom and formula interpretations are conditional on the explicitly stated full linear-model specification.
For a normal linear model with fixed observations and mean coefficients, maximizing over the error variance gives . The maximized negative twice log-likelihood is plus a constant common to the candidate models. Counting the variance as another parameter adds the same penalty two to every model, so the stated criterion is equivalent for comparing them:The Akaike information criterion balances fit against parameter count; smaller values are preferred. It does not compare models using different response scales or different sets of observations without further adjustment.
Stepwise selection by the Akaike information criterion compares allowed one-term additions and deletions, takes a change lowering the criterion, and repeats until no allowed change improves it. The search direction, initial fit and lower/upper scopes matter. A displayed no-change row represents the current model. The term degrees of freedom show how many coefficients a change removes, the residual sum reflects its fit, and the AIC column determines the selected move. The search is greedy, not a guarantee of the best subset over the entire model space. The software's scope and direction conventions are documented in stat.ethz.ch/R-manual/R-devel/library/MASS/html/stepAIC.html .
Deleting coefficients changes the criterion byThus the AIC deletion threshold in a normal linear model isFor a single coefficient, its partial F-test statistic must be below for AIC to favor deletion. At the full 47-observation, 16-coefficient fit this is approximately , corresponding to . Therefore AIC selection is not equivalent to retaining only coefficients with a conventional five-percent p-value.
The final model should be described by its retained terms, signs, conditional effect sizes, uncertainty, residual diagnostics and prediction behavior. A coefficient that survives selection need not identify a causal mechanism, and its ordinary final-model p-value ignores the preceding search. Stability under bootstrap resampling and predictive cross-validation are useful. The absent search trace and final model prevent identifying the actual deletion sequence, final predictors, coefficients, RSS or AIC. The given starting name does not specify any of those facts.
The survival estimates favor the new treatment at the two reported times, with absolute survival differences at two years and at five years. These point differences alone do not establish efficacy. Randomization supports a causal comparison of the treatment assignments, but sampling variance, censoring, follow-up, protocol adherence and the prespecified endpoint still matter. One should not infer a statistically established benefit merely from two larger estimates.
A Kaplan–Meier estimator iswhere is the risk set and the event count. Its uncertainty depends on the actual risk sets, not just the initial group size. The Greenwood formula estimatesWithout the missing survival tables one cannot calculate these standard errors or the uncertainty of the group difference. In particular, replacing the estimator variance by the variance of an uncensored binomial proportion would generally be wrong.
I would advise presenting both curves with numbers at risk and confidence intervals, checking independent censoring, and reporting a prespecified overall comparison plus an effect estimate and interval. For an unadjusted log-rank test, write and . Its hypergeometric null variance isTerms with no possible variation contribute zero. This compares the entire event history rather than selecting two arbitrary times, uses the available risk sets, and avoids choosing favorable time points after examining the curves. It is especially effective under proportional hazards. Crossing curves can make a log-rank comparison insensitive; a prespecified restricted mean survival time difference or another suitable time-varying analysis may then be more informative. An overall comparison does not make a clinically important prespecified time-point contrast invalid.
The Kaplan–Meier median survival time is the first event time at which . Monotonicity of the reported estimates impliesIf the new-treatment curve never reaches one half during observed follow-up, its median is not estimable from that curve. The exact crossing times cannot be reconstructed from two survival probabilities: the standard curve could first cross at three or at four years and still have the same values at two and five years. The point estimates suggest benefit, but the evidence and exact medians require the missing event/censoring tables. Neither a conclusive agreement nor a conclusive rejection of benefit is justified from these numbers alone.
These are separate data, so results from the randomized trial must not be carried over. First inspect the construction of the survival response: a command creating a survival time object must pair follow-up in months with an event indicator, whose death/censoring coding should be checked explicitly. A censoring time is not an observed death time. Stratified product-limit fits would then summarize Kaplan–Meier estimators for the dose groups before adjusted regression.
If the fitted command is a Cox proportional-hazards model with dose, sex and age, its specification isThere is no separate intercept estimate because an intercept is absorbed into the unspecified baseline hazard . With the stated coding, compares high-dose with low-dose death hazards at equal sex and age; compares female with male hazards at equal dose and age; is the hazard multiplier for a one-year age increase. A negative treatment coefficient would correspond to a lower fitted hazard under high dose. A hazard ratio is not a ratio of survival probabilities, nor directly a ratio of survival times. Under this model the survivor function is .
The coefficient standard errors, Wald ratios and exponentiated confidence intervals should be read together. The common large-sample interval for a coefficient's hazard ratio isGlobal likelihood-ratio, score and Wald tests assess the included slopes jointly; for exactly these three one-coefficient terms their reference degrees of freedom are three. They need not coincide in a small sample. The Cox partial likelihood uses the event risk sets; the fitted log-likelihood is not a full likelihood for an estimated baseline survival curve. The method for tied event times should be recorded.
Check the proportional hazards assumption using scaled Schoenfeld residuals and time trends; check the functional form of age, influential subjects and independent censoring. Dose-by-age or dose-by-sex interaction terms are scientifically possible but require enough information and a stated model comparison. Adjustment can alter a crude dose association, and the allocation mechanism here is not specified as randomized. No coefficients, confidence limits, significance results, exact fitted calls or diagnostics for this dataset are recoverable without the output sheet. The displayed model is an interpretation template, not a claim that it was the exact missing command.
Use the index order in the probability specification: influence , accommodation type , contact and satisfaction . Put , which is conditioned on. The independent multinomial likelihood isThus the relevant sample is a collection of conditional satisfaction distributions for fixed covariate strata; it is not a model for the marginal distribution of the three covariates. In the published dataset there are three influence, four accommodation, two contact and three satisfaction levels, giving 24 strata and 72 cells; these dimensions are documented in stat.ethz.ch/R-manual/R-devel/library/MASS/html/housing.html .
The missing output does not identify its two actual formulas. Two standard canonical models can nevertheless be derived explicitly, and the following general result identifies the sufficient statistics for any specified baseline-logit model. The first standard model has no response/covariate association: for every stratum. Its likelihood factors asTherefore the pooled satisfaction totals are sufficient, with only two independent totals because the grand total is fixed. The maximum-likelihood estimator is , and fitted counts are . A Poisson surrogate formula with all covariate-stratum interactions and only a satisfaction main effect produces this same conditional model. It has two conditional parameters and 46 residual degrees of freedom when all 24 strata are present.
For the standard additive multinomial logistic regression, use the final satisfaction category as baseline and writeSet a reference effect to zero for each covariate factor. Define for , and . The probabilities areSubstitution into the conditional log-likelihood givesThe second term depends on the parameters and the fixed stratum totals, not on any additional within-stratum cell allocation. The Fisher-Neyman factorization theorem therefore proves thatThese margins contain linear redundancies; after reference constraints an equivalent independent statistic has dimensionHence its residual degrees of freedom are . In the equivalent Poisson surrogate for a conditional multinomial model, include a separate stratum intercept and response interactions with each individual covariate. The 24 nuisance intercepts plus 14 response parameters give 38 parameters in 72 Poisson cells, again 34 residual degrees of freedom. Since the stratum totals are fixed in the conditional experiment, they need not be included as random sufficient statistics there; they do belong to the unconditional Poisson model's sufficient margins.
The derivation extends to either actual model once its formula is known. If is its covariate design vector and the baseline logits are , thenThus the conditional multinomial sufficient statistics are , for . For an identifiable unrestricted canonical parameter space they are also minimal up to linear equivalence: the ratio of two data likelihoods is parameter-independent exactly when the differences of all these design-weighted sums vanish. This follows because that ratio contains .
Consequently an influence-by-type response interaction adds the margins ; influence-by-contact adds ; type-by-contact adds . A saturated model requires the individual cells, subject to the fixed stratum totals. A hierarchical log-linear model leads to the same response/covariate margins and the fixed covariate margin. There is no need to guess sufficient statistics from the number of displayed coefficients: they follow from the actual design columns and the likelihood.
To read a printed fit, check whether it is a Poisson surrogate, a baseline-category multinomial model or an ordinal cumulative model, then inspect its reference levels, signs of response contrasts, standard errors, residual deviance, degrees of freedom, nested comparisons and predicted probabilities. A baseline-logit coefficient changes odds of one satisfaction level against the baseline, not necessarily cumulative odds of high satisfaction. Normalize Poisson fitted counts within each covariate stratum to get fitted response probabilities. Empty or sparse cells can cause boundary fits or invalidate a naive deviance reference distribution.
A proportional-odds model instead specifies . It uses the response ordering, with shared slopes across cutpoints. Its category probabilities are differences of cumulative logistic probabilities, so its log-likelihood is not the canonical linear expression above. The baseline-category margins just derived are not generally sufficient for that model; the full conditional cell table is always sufficient. Without the missing formulas it is not possible to certify which two specific models were fitted or their actual sufficient-margin lists and test results. The null, additive and general-design derivations above state precisely which model each answer belongs to.
A direct grouped-binomial logistic regression can dichotomize satisfaction, for example high versus low-or-medium. In each covariate stratum use the high count as successes and the sum of the other counts as failures, with total . This models and is appropriate if that binary contrast is substantively intended, but discards distinctions among the merged categories. Another cutpoint gives a different binary question.
There is also an exact sequential binomial factorization preserving all three categories. With their probabilities in one stratum,Multiplying these two conditional binomial likelihoods gives the multinomial likelihood: the combinatorial coefficients multiply to , and the probability factors reduce to . Continuation-ratio logits can therefore fit two logistic regressions, using the remaining stratum total as the second denominator. These are conditional stage models, not two independent counts with the same fixed denominator. Their regression restrictions need not equal those of the additive baseline-category model.
Finally, an ordinal analysis may fit cumulative binary contrasts and examine whether their slopes can be shared in a proportional-odds model. The binary indicators at different cutpoints from the same person are dependent. Do not stack them as independent binomial observations and multiply their marginal likelihoods; fit the joint ordinal likelihood or use a method with the appropriate dependence correction. This distinction separates a convenient descriptive collection of binary fits from a coherent multinomial or ordinal model.
Articles by others on the same topic
There are currently no matching articles.