These solutions follow the original examination of 11 June 2013, code
4208.[ref]Functional programming, design and analysis of algorithms examination paper by the University of Oxford (2013). pp. 2–7, Questions 1–8
Each question's Haskell definitions form a separate namespace; hide redefined Standard Prelude names when compiling them. Unless stated otherwise, arguments are finite and total. Time complexity counts primitive operations; the cost of comparing variable-length words and the growing bit cost of exact integer arithmetic are stated separately where relevant.[ref]The map function changes each element of a list while preserving its order and length. List concatenation removes one level of nesting. Currying changes a function on a pair into a function taking its two arguments separately; uncurrying reverses this conversion:
map :: (a -> b) -> [a] -> [b]
map f []     = []
map f (x:xs) = f x : map f xs

concat :: [[a]] -> [a]
concat []       = []
concat (xs:xss) = xs ++ concat xss

curry :: ((a, b) -> c) -> a -> b -> c
curry f x y = f (x, y)

uncurry :: (a -> b -> c) -> (a, b) -> c
uncurry f (x, y) = f x y
These polymorphic type signatures impose no numerical, equality or ordering constraints: the definitions only inspect list or pair structure and apply a supplied function. In particular,The recursive equations describe the two possible list constructors, so they also explain how the empty case terminates each finite computation.
In the type signature
map :: (u -> v) -> [u] -> [v], the supplied function is concat :: [[a]] -> [a]. Type inference therefore identifies u with [[a]] and v with [a]. Consequently,map concat :: [[[a]]] -> [[a]]Thus is the principal type. For example,
map concat [[[1],[2,3]],[[4],[]]] gives [[1,2,3],[4]]: it concatenates each inner group, preserving the outermost grouping.Both uses of
x in this definition have the same monomorphic type within the body. Write x :: u -> v. The inner application x z forces z :: u and has type v; the outer application x (x z) forces v = u. Thus x :: u -> u. Finally, x (x z) is applied to y, so u must itself be a function type, say a -> b. This givesf :: ((a -> b) -> a -> b) -> a -> (a -> b) -> b
f x y z = x (x z) yThe principal type is thereforeThe argument
x transforms a function into another function of the same type. The body transforms z twice, then applies the resulting function to y; no recursive type equation is required.Represent Pascal's triangle by an infinite outer lazy list, each of whose elements is one finite row. Pad the preceding row with zero on its left and on its right, then add corresponding entries:
pascal :: [[Integer]]
pascal = iterate next [1]
  where
    -- Padding supplies the two boundary entries as well as the interior sums.
    next :: [Integer] -> [Integer]
    next row = zipWith (+) (0 : row) (row ++ [0])
Here
iterate next [1] begins [[1],[1,1],[1,2,1],[1,3,3,1],...]. Every call to next receives a finite row, so its final zero is reachable. Lazy evaluation produces any requested finite prefix without trying to finish the infinite outer list.Indexing rows and columns from zero, Pascal's rule saysTake out-of-range binomial coefficients to be zero. The seed is the zeroth row, and the padded addition implements this identity at every position, including the two boundaries. Mathematical induction therefore proves every generated row correct. Using unbounded integers prevents overflow. Generating rows zero through takes arithmetic operations, with additional bit costs as the binomial coefficients grow.
Use structural induction on the finite list
xs, strengthening the induction hypothesis to hold for every accumulator value . For the empty list, the defining equation of the left fold givesFor the inductive step, suppose the identity holds for the tail zs and every accumulator. Expand the first left fold, apply the induction hypothesis at accumulator , and then use the supplied compatibility law:HenceOnly equation (1) is needed for this part; the seed condition in equation (2) enters the next proof. Quantifying over the accumulator is essential because the recursive call changes it.Again use structural induction on the finite list. At
[], both the right fold and the left fold return the seed . If they agree on zs, thenThe third line uses part (a); the fourth uses equation (2). Thus the left-right fold equivalence isThis is a statement about values on finite, total inputs. It does not assert equal evaluation costs or equal behaviour on infinite lists.concat :: [[a]] -> [a]
concat = foldr (++) []For three inner lists, this constructs
xs ++ (ys ++ (zs ++ [])), preserving the elements' original order. The concise answer is .Set both and equal to list concatenation, with . Associativity gives
xs ++ (ys ++ zs) = (xs ++ ys) ++ zs, which is equation (1). The two identity laws give xs ++ [] = [] ++ xs, which is equation (2). Part (b) therefore yieldsconcat :: [[a]] -> [a]
concat = foldl (++) []Thus on finite lists. The argument order is unchanged: the accumulator is the already concatenated prefix, and the next inner list is appended to its right. This preserves the order but repeatedly copies that prefix.
Let there be inner lists, of lengths , and let . Evaluate the whole output list spine, taking each input element as an already available value. The defining equation
(x:xs) ++ ys = x : (xs ++ ys) shows that list concatenation traverses its left operand, sharing its right operand.The right fold puts each original inner list on the left of exactly one concatenation. Thus its total element traversal is proportional to , and visiting the outer list costs :The term matters when many inner lists are empty. With rows each of length , the bound is . In particular, with uniformly bounded positive row length it is linear in .
Write , with . At the th step of the left fold, the left operand of list concatenation is the accumulated prefix of length . Fully forcing these concatenations repeatedly copies earlier elements. Including the traversal of the outer list and the whole output spine givesFor singleton inner lists, this becomes , whereas the right fold takes . More generally, for equal positive length , the left fold takes .
An bound is tight in the worst case over length distributions, but is not a tight formula for every distribution: if all elements occur only in the final inner list, all earlier accumulators are empty and the cost is . Lazy evaluation changes when the work happens; it does not remove repeated prefix traversal when the whole result is demanded.
A word can be a string, and the input text a list of those strings. Use names that avoid clashing with the Standard Prelude machine-word type
Word:type TextWord = String
type Text = [TextWord]Thus . These are type synonyms, so ordinary string and list operations remain available without wrapping or unwrapping constructors. They describe input that has already been tokenized; punctuation and word boundaries do not need a separate treatment here.
Normalize each word once by applying
toLower to its characters. Maintain an association list whose keys are distinct normalized words and whose values are their frequencies:import Data.Char (toLower)
type TextWord = String
type Text = [TextWord]
type Frequency = Integer
type Entry = (TextWord, Frequency)
count :: Text -> [Entry]
count = foldl addWord [] . map (map toLower)
where
-- Increment the unique matching key, or append a new key with count one.
addWord :: [Entry] -> TextWord -> [Entry]
addWord [] w = [(w, 1)]
addWord ((v, n):rest) w
| w == v = (v, n + 1) : rest
| otherwise = (v, n) : addWord rest wAfter any input prefix, each normalized word seen so far occurs exactly once as a key, with its number of occurrences as value. This loop invariant holds initially for the empty association list. A step either increments the unique existing entry or introduces exactly one new entry, so mathematical induction provesfor every word that occurs. In particular,
Baa and baa contribute to the same key baa; the three frequency-two keys in the source example are baa, yes and sir.The association list preserves first-occurrence order, although the specification allows any order here. For input words and distinct normalized words, it performs key comparisons in the worst case. Character normalization costs the total input character count, and a string comparison can inspect multiple characters. Characterwise
toLower supplies the intended case-insensitive comparison convention for the example; full Unicode case folding can require a different normalization policy.Compare frequencies in decreasing order and use lexicographic order on words to break ties. Implement merge sort explicitly, so no imported sorting routine is needed:
-- Entry, TextWord and Frequency are as in part (b).
before :: Entry -> Entry -> Bool
before (w, p) (v, q) = p > q || (p == q && w <= v)

sort :: [Entry] -> [Entry]
sort []  = []
sort [x] = [x]
sort xs  = merge (sort left) (sort right)
  where
    (left, right) = splitAt (length xs `div` 2) xs

merge :: [Entry] -> [Entry] -> [Entry]
merge [] ys = ys
merge xs [] = xs
merge xa@(x:xs) ya@(y:ys)
  | before x y = x : merge xs ya
  | otherwise  = y : merge xa ys
The merge algorithm step always emits the smaller key under the ordering . The unchosen heads cannot precede that emitted entry because each input is already sorted. It preserves all entries, and each call removes one head, so it terminates with exactly the sorted union of the inputs. Mathematical induction over the recursive splits establishes correctness of merge sort.
For entries, splitting and merging cost per level, and there are levels:The base cases take constant time. This counts word comparisons as primitive operations, as in the question. If the maximum compared word length is , the character-operation bound becomes , in addition to frequency comparison costs.
For the supplied input,
sort . count yields[("baa",2),("sir",2),("yes",2),("any",1),("bags",1),("black",1),
("full",1),("have",1),("sheep",1),("three",1),("wool",1),("you",1)]In particular, the secondary ordering places
sir before yes, even though yes appears earlier in the original text. The requirement concerns sort; the simpler association list implementation of count has its own cost.An empty constructor and a constructor containing a label and two subtrees give a polymorphic algebraic data type:
data STree a = Empty | Node (STree a) a (STree a)
  deriving (Eq, Show)
The binary search tree invariant is at each
Node left x right, together with the same invariant recursively in both subtrees. Labels are distinct because the representation is of a set. The declaration itself needs no ordering constraint; operations that compare labels require Ord a in their type signatures.Follow the unique branch in which the new key could belong. At an equal key, keep the existing node so that duplicate insertion does not change the represented set:
insert :: Ord a => a -> STree a -> STree a
insert y Empty = Node Empty y Empty
insert y (Node left x right) =
  case compare y x of
    LT -> Node (insert y left) x right
    EQ -> Node left x right
    GT -> Node left x (insert y right)
The Haskell Ord class supplies the three-way comparison. Each visited nonempty node costs one such comparison; rebuilding a node preserves all untouched subtrees. The inserted key satisfies every comparison along its search path, so it obeys both the local and ancestor binary search tree inequalities.
For height of a binary tree , the worst search costs when it reaches the bottom. With existing nodes, a chain can require comparisons, giving a worst case of . Under the standard random-insertion model, distinct keys arrive in a uniformly random order and the expected path length is . Thus the usual average-case answer is for growing , but this expectation needs the stated distribution: an arbitrary unbalanced binary search tree has no logarithmic guarantee.
A tree fold replaces
Empty by a seed and Node by a combining function. The combining function receives the already folded left subtree, the node's label and the already folded right subtree:foldSTree :: (b -> a -> b -> b) -> b -> STree a -> b
foldSTree combine empty Empty = empty
foldSTree combine empty (Node left x right) =
combine (foldSTree combine empty left)
x
(foldSTree combine empty right)Its polymorphic type signature isThe result type need not be the label type: it may be a list, a number or another structure. No ordering constraint is needed because this tree fold follows constructors without comparing labels.
Use the empty list for an empty subtree, and join the left result, the current label and the right result:
flatten :: STree a -> [a]
flatten = foldSTree (\left x right -> left ++ (x : right)) []
Thus . This is an inorder traversal. By structural induction, each subtree produces its labels in order; the binary search tree invariant places every left label below and every right label above , proving that the whole result is increasing. The definition works for any binary-tree shape, although its result is sorted only when the ordering invariant holds. Repeated list concatenation can give quadratic cost on a left chain; the question asks for a tree fold definition, rather than an optimal traversal implementation.
An empty binary search tree has zero nodes; a nonempty node contributes one in addition to the sizes of its two subtrees:
size :: STree a -> Integer
size = foldSTree (\left _ right -> 1 + left + right) 0
The answer is . The tree fold visits every node once, so this takes arithmetic operations for nodes.
Count the number of nonempty levels on the longest root-to-leaf branch, taking the empty binary search tree to have depth zero:
depth :: STree a -> Integer
depth = foldSTree (\left _ right -> 1 + max left right) 0
Thus . A singleton has depth one under this convention. If height of a binary tree is instead counted in edges, subtract one for a nonempty tree. The complete tree fold takes operations.
Search as for insertion. Removing a node with at most one nonempty child leaves that child in its place. With two children, use the smallest key in the right subtree as the replacement and remove that occurrence from the right subtree:
delete :: Ord a => a -> STree a -> STree a
delete _ Empty = Empty
delete y (Node left x right) =
  case compare y x of
    LT -> Node (delete y left) x right
    GT -> Node left x (delete y right)
    EQ -> join left right
  where
    -- Join two search trees with every left key below every right key.
    join :: STree a -> STree a -> STree a
    join Empty r = r
    join l Empty = l
    join l r = let (smallest, rest) = takeMin r
               in Node l smallest rest

-- Precondition: the input tree is nonempty.
takeMin :: STree a -> (a, STree a)
takeMin Empty = error "takeMin: empty tree"
takeMin (Node Empty x right) = (x, right)
takeMin (Node left x right) =
  let (smallest, rest) = takeMin left
  in (smallest, Node rest x right)
The call to
takeMin occurs only after both empty cases have been excluded. Its structural recursion follows left children until it reaches the minimum label and rebuilds the path with that occurrence removed.For a matching label and successor , all left labels are below , while every label remaining on the right is strictly above . Thus replacing by preserves the binary search tree invariant. Every other branch preserves the invariant by structural induction. The resulting set is exactlyWhether the key is absent or present, untouched subtrees can be shared. The search path followed by the successor path uses time and fresh nodes for original height of a binary tree , so the worst case is without balancing. This is persistent binary search tree deletion: the original value remains available.
A length-zero graph path starts and ends at the same vertex. Therefore is the Boolean identity matrix. A graph path of length at most one is either such a stationary graph path or one original directed edge:The logical disjunction is entrywise. Diagonal entries of may be false if there are no self-loops, but every diagonal entry of is true because the zero-length graph path is allowed.
A graph path of length at most either already has length at most , or consists of a prefix of length at most followed by one edge. ThereforeThe forward implication follows by removing the final edge of a nonempty graph path. Conversely, concatenating the indicated prefix and edge gives a walk of length at most , and removing repetitions if necessary gives a graph path no longer than that walk.
Writing for Boolean matrix multiplication, the formula is . Because includes the identity matrix, an equivalent formula isCompute each new matrix from an unchanged copy of the preceding matrix, so the subscript continues to specify exactly the length bound.
P := I OR E
repeat:
    Q := P OR boolean_product(P, E)
    if Q = P: return P
    P := Q
At the start of each iteration, for the current length bound . The update produces , proving the loop invariant by mathematical induction. If , every edge extension of a known graph path is already known. Repeating the same update then makes no further change, so every longer graph path is represented as well.
Every reachable pair of distinct vertices has a simple path of at most edges: a repeated vertex allows the intervening part to be deleted. Thus the process stabilizes after finitely many updates and returnsThis is the reflexive transitive closure. An alternative stopping rule is to stop once the length bound is at least , avoiding a final equality-detection iteration. For or , already suffices.
Interpret the source's as the maximum finite shortest-path distance among reachable pairs, taking when only length-zero graph paths are needed. This is the length bound required for reflexive transitive closure. A directed graph cycle permits arbitrarily long walks, so the maximum length of all possible walks would not be a finite termination parameter.[ref]
For the elementary dense implementation, each Boolean matrix multiplication evaluates all triples , with no early exit. Each equality test costs . Starting from , the algorithm reaches after updates when , then performs one further update to detect stability. Consequently, for ,For the usual nontrivial case , this is . Since , the overall worst case is . This bound is tight for this implementation: the directed chain has and gains previously unknown pairs at every length until then, while every update scans all triples. This tightness does not claim an inherent lower bound for the reflexive transitive closure problem; it concerns the specified repeated-extension algorithm.
Split a graph path of length at most into two consecutive parts of length at most , allowing a zero-length part. Conversely, concatenating two such parts gives a walk of length at most and hence the same reachability. ThereforeStart at , then square to obtain . Stop at equality of successive matrices, or after the length bound reaches . The invariant is now after squarings. Equality implies closure under composition, and the included identity matrix ensures reflexivity.
For the same elementary dense Boolean matrix multiplication and equality stopping test, the cost isThe additive constant covers the final stability check and the cases . Thus, with , the number of cubic passes falls from to . In terms of alone the worst-case bound improves from to for these implementations. A directed chain also requires logarithmically many squarings. This comparison uses ordinary triple-loop multiplication, rather than a faster matrix multiplication method.
Divide-and-conquer algorithms split a problem into smaller instances of the same kind, solve them recursively, and combine the solutions. A base case handles instances too small to split. For merge sort, divide the input into two halves, recursively sort both halves, and merge them by repeatedly taking the smaller current head. Empty and singleton inputs are already sorted.
The merge algorithm step preserves sortedness because its chosen head is no larger than either remaining head; it also preserves every input occurrence. These facts and mathematical induction on input length prove correctness. Splitting and merging take time, soAt each level the subproblem sizes sum to , and there are levels. Part 3(c) supplies an explicit Haskell implementation of this construction with a more specialized comparison rule. Standard array implementations use auxiliary storage.
Restrict attention to distinct keys; any comparison sort must handle these inputs. A deterministic comparison sort can be represented by a binary decision tree: an internal node records a comparison and its two possible outcomes, and a leaf records the final ordering of the input positions.
There are possible relative orders. Two different orders cannot finish at the same leaf, since the algorithm would then output the same ordering of positions for both, making at least one result incorrect. A binary decision tree of height has at most leaves. HenceUsing the given bound, or just the last factors of , givesThis is a worst-case comparison sorting lower bound, and merge sort achieves the same order. The result concerns comparison sorting; a procedure that uses numerical digits or bounded integer values has a different computational model.
Assume . Apply a worst-case comparison sort, such as merge sort or heapsort, to the whole array, then copy its first entries to the output. The copying costs , soThe comparison sorting lower bound makes the full-sort stage tight. For the sample array, the sorted order begins , which is the required prefix for . This method spends time ordering all unreported elements as well.
Store the array as a binary heap with min-heap order. Build it bottom-up by sifting down internal nodes in reverse order, rather than inserting all values one at a time. The sum of subtree heights is , so construction costs . Then perform minimum extractions: output the root, move the last remaining entry to the root, and sift it down to restore the heap order.
Each extraction returns the smallest remaining key, so the outputs are the smallest keys in increasing order. For a heap of current size , an extraction takes time. HenceThe tight worst-case bound for this ordinary binary heap implementation isWhen the extraction term is substantial, worst-case extractions follow root-to-leaf paths of logarithmic length; when is small, the linear construction already dominates. The bound stays valid at , since . Building by separate insertions would lose the linear construction bound and is unnecessary.
Use deterministic median of medians to select the element of rank in worst-case time. Partition the array about that value, retaining the smallest elements. The input is a set, so there are no equal-key ambiguities: take the smaller values and the selected value itself. Sort these elements with merge sort, then output them.
For completeness, median of medians groups values in fives, finds each small group's median, recursively selects a median of those medians as a pivot, and recurses only into the partition containing the requested rank. At least entries lie on each side of the pivot. Its worst-case recurrence isSelection and partitioning cost , and sorting the retained prefix costs for . Including output at givesScanning the input is necessary even to identify its minimum. Ordering the selected distinct values also has the comparison sorting lower bound , so this is asymptotically optimal for the task. A usual randomized Quickselect gives linear expected selection time, but its quadratic worst case would not establish the requested worst-case guarantee.
Dynamic programming specifies a collection of overlapping subproblems, expresses each answer using smaller subproblem answers, and stores answers so each subproblem is solved once. One may fill a table in dependency order or use memoization to compute only requested entries. The key design choice is a state that retains every feature needed by later decisions.
The principle of optimality says that, after a decision in an optimal solution, the remaining decisions must solve the corresponding residual subproblem optimally. Otherwise, replacing that residual solution by a better one would improve the entire solution. This replacement argument requires the state to describe the residual constraints completely. Its useful form here isThe maximization applies to these value-maximization problems; minimization uses the analogous minimum recurrence.
In the 0-1 knapsack problem, item has weight and value . Choose a subset of the items, using each at most once, whose total weight is at most and whose total value is as large as possible. For the capacity-indexed dynamic program, take and the weights to be nonnegative integers. The empty choice is allowed.
Let be the greatest value attainable using only items with capacity . The base case is . With item unavailable when it is too heavy, the recurrence isEvery feasible optimum either excludes item , giving the first candidate, or includes it exactly once, leaving capacity for earlier items. The principle of optimality proves that the remaining earlier items must attain the indicated residual optimum. Conversely, either candidate constructs a feasible solution, so taking the larger is both necessary and sufficient. Mathematical induction on proves the table's meaning and the final answer .
Store item weights and values in arrays and the values in a two-dimensional array with entries. Fill rows in increasing ; each entry uses at most two values from the previous row. There are constant-work updates, givingFor positive growing capacities this is the familiar bound. The terms also cover capacity zero and zero-weight items: one must not initialize every to zero if zero-weight, positive-value items are allowed.
To recover an actual subset, store the chosen alternative at each entry or compare the two candidates while tracing backward from . A selected item changes to ; an excluded item changes it to . This takes extra time.
If only the optimal value is needed, keep two rows, using space. With strictly positive weights, a single capacity row updated in decreasing capacity also prevents item reuse. The two-row version handles zero weights without special in-place reasoning. The running time is pseudopolynomial, since the binary input length of is only logarithmic in its numerical value.
For the two-bag 0-1 knapsack problem, let be the maximum total value using the first items, with remaining capacity limits in the first bag and in the second. Initialize . Item has exactly three possible decisions: omit it, place it in bag one if it fits, or place it in bag two if it fits. HenceA braced candidate with a false condition is omitted. All candidates refer to layer , which prevents the same item from entering both bags. Combining two independently optimized single-bag knapsacks would not enforce that restriction.
The principle of optimality proves correctness exactly as in part (b): condition on the location of the final item and replace the earlier items by the optimal feasible residual assignment. Every candidate is realizable, and every feasible assignment belongs to one of the three cases. The final answer is .
Fill the three-dimensional array in increasing item index. Each of its updates inspects at most three candidates:For positive capacities the customary expression is . Keeping only two item layers reduces space to for the optimal value. Full decision storage also permits backward reconstruction of each item's bag assignment. Nonnegative integer weights and capacities are the assumptions behind this capacity-indexed dynamic programming table.
Use Kahn's algorithm for topological sorting. With an adjacency list representation, count every vertex's indegree by scanning the edges. Put all zero-indegree vertices in a queue. Repeatedly remove one such vertex , append it to the output, and delete its outgoing edges by decrementing the stored indegree of each neighbour; enqueue a neighbour exactly when its count becomes zero.
The loop invariant is that stored counts are the indegrees in the unreported subgraph and the queue contains exactly its unreported zero-indegree vertices. A nonempty finite Directed acyclic graph always has such a vertex: otherwise following incoming edges would eventually repeat a vertex, creating a directed graph cycle. Thus the queue cannot become empty while any vertex remains.
For every original edge , cannot enter the output until that edge has been removed by outputting . ThereforeEach vertex enters and leaves the queue once, and every edge is scanned a constant number of times, giving time and auxiliary space beyond the adjacency lists. If given only an adjacency matrix, scanning neighbours instead takes time.
Allow a zero-length graph path, as in Question 5. Then every vertex reaches itself, proving reflexivity. If , its definition already includes both directions of reachability, so interchanging proves symmetry.
If and , concatenate the graph paths and to obtain reachability from to . Similarly concatenate and for the reverse direction. Repeated vertices can be removed if graph paths are required to be simple. Thus , proving transitivity. ConsequentlyThe zero-length convention matters for an isolated vertex: it is still a singleton strongly connected component.
Here the source's unrestricted “cycle” means a closed walk, permitting repeated vertices; part (d) explicitly separates this from a simple cycle.[ref]
Suppose a closed walk contains both colours. Any two vertices on it reach one another by following suitable portions of the closed walk. All its vertices, and therefore all its edges, lie inside one strongly connected component. That strongly connected component contains internal edges of both colours.
Conversely, suppose one strongly connected component contains a black edge and a white edge . Its strong connectivity supplies a graph path from to and another from to , both inside the component. ConcatenateThis is a closed walk containing both chosen edges. Either connecting graph path may have length zero. Thus the mixed-colour closed walk criterion isThe edges must be internal: differently coloured edges merely leaving a strongly connected component do not establish the claim.
Take two directed triangles meeting only at a central vertex . Make entirely black and entirely white. All five vertices lie in one strongly connected component, since every vertex can reach and can be reached from . It contains internal edges of both colours.
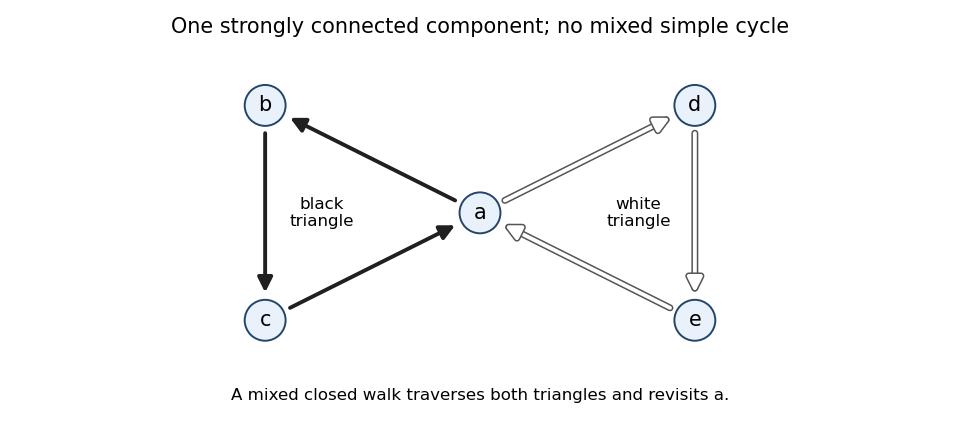
Two monochromatic directed triangles sharing one vertex give a mixed closed walk but no mixed simple cycle
. Details. 
A closed walk can traverse the black triangle and then the white triangle. But a simple cycle using edges from both triangles would have to pass through to change triangles and pass through again to return. It would repeat other than the single start/end identification, contradicting simplicity. Removing separates the two triangles, so no other transition between them is possible. ThereforeThis example avoids self-loops and works even when a directed simple cycle is required to have at least three vertices.
Use the two-pass strongly connected component algorithm. First run a complete depth-first search of , starting a new search at each unvisited vertex as necessary. Append each vertex to a list when its recursive call finishes. Next construct the graph transpose by reversing every edge. Reset all visited flags. Process the vertices in decreasing first-pass finishing order, running depth-first search in from each still-unvisited vertex. The newly reached vertices in each such search form one strongly connected component.
To prove this, contract each strongly connected component to one vertex. The resulting condensation graph is a Directed acyclic graph, because a directed graph cycle of distinct components would make them mutually reachable and hence a single component. For a component , write for its largest first-pass finishing time. If there is an edge between distinct components, then . Indeed, if the first search reaches before , it can reach , which must finish before the search in finishes. If it reaches first, cannot reach or they would be the same component, so finishes before is discovered.
Among unreported components, the one with greatest therefore has no incoming edge from another unreported component in . In the graph transpose it has no outgoing edge to any other unreported component. A second-pass search cannot escape it, while strong connectivity lets that search reach all its vertices. Earlier reported components are ignored by the visited flags. Repeating this argument provesBoth depth-first searches visit every vertex and scan every edge once, and transposition costs . Therefore the total time complexity is with adjacency lists. Storage for the transpose is , while visited flags, finishing order and the search stack use additional space. No sorting is needed: reverse the list recorded at finishing time.
Articles by others on the same topic
There are currently no matching articles.