Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Perimeter
Determinant Created 2026-09-24 Updated 2026-10-14
The determinant assigns a scalar to a square matrix. For a linear map on the real plane, it measures signed area scaling: its absolute value tells how much area grows, and its sign records whether the orientation of a vector space is preserved or reversed. In three dimensions, the same idea measures signed volume. Over a field, a square matrix is an invertible matrix exactly when its determinant is nonzero. These are two views of one phenomenon: losing an independent direction collapses full-dimensional volume and makes the original input impossible to recover uniquely.[ref]
https://www.math.ucla.edu/~rse/algebra_book.pdf#page=716. Elman, Lectures on Abstract Algebra, section 121: determinant and inverse
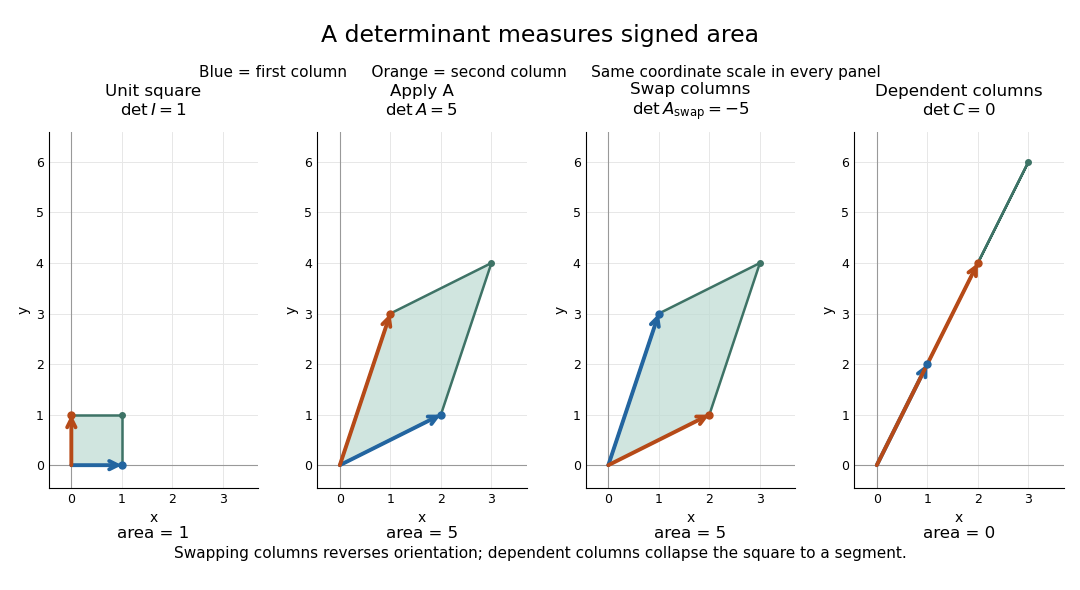
Start with an explicit matrix and its action on a vector:The columns are the images of the standard basis vectors: and . Consequently the unit square with corners becomes the parallelogram with corners . Its area is five. Every small patch of this square undergoes the same linear map, so the factor describes the whole deformation, rather than just one specially chosen boundary. The matrix mixes horizontal and vertical components, but its determinant compresses that combined effect into one area factor.[ref]
https://ocw.mit.edu/ans7870/18/18.013a/textbook/HTML/chapter04/section01.html. MIT calculus notes, section 4.1: determinants and area
Now exchange the columns:The parallelogram occupies exactly the same region, but its generating vectors arrive in the opposite order. Moving from the first column to the second now turns clockwise rather than counterclockwise. Ordinary area remains five; the oriented volume in two dimensions changes sign. A negative determinant therefore signals reversed orientation of a vector space, not a negative amount of material. Keeping the sign makes successive reversals calculable: two reversals restore the original orientation of a vector space.
Compare a singular matrix:Its columns are linearly dependent: the second is twice the first. The unit square collapses onto the segment from to , which has zero area despite nonzero length. Since , the kernel of a linear map contains a nonzero vector; inputs differing by that vector have identical outputs. The collapsed picture explains why an inverse matrix cannot exist.
For , recovery is possible, and the complete matrix multiplication check isHere is the identity matrix. The inverse matrix restores the original square, shrinking its area by . Generally, the adjugate identity gives whenever the determinant is nonzero over a field; this is why the denominator matters.[ref]
https://ocw.mit.edu/ans7870/18/18.013a/textbook/HTML/chapter04/section04.html. MIT calculus notes, section 4.4: determinant and inverse
The multiplicativity of the determinant describes two successive deformations. Matrix multiplication means that applies first, then . TakeThe first linear map doubles area; the second multiplies the resulting area by five. Thus the unit square passes through areas , with the last parallelogram bounded by . Direct calculation agrees:This explains physically why area factors multiply instead of adding. The general identity holds for square matrices of the same size, including singular matrices. If either stage loses a direction, later processing cannot recover the discarded information.[ref]
https://ocw.mit.edu/ans7870/18/18.013a/textbook/HTML/chapter32/section04.html. MIT calculus notes, section 32.4: determinant products
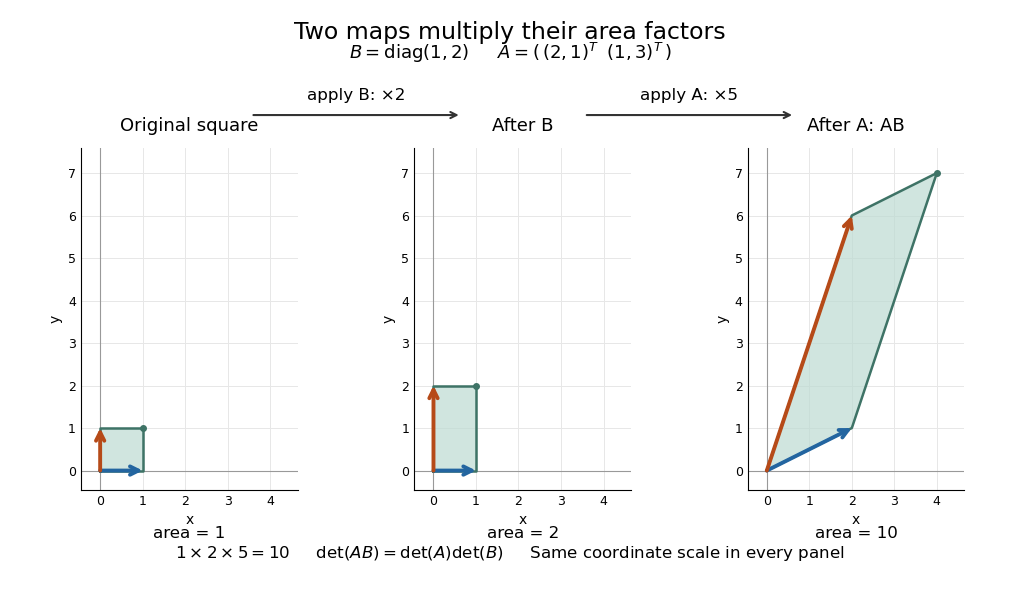
Successive linear maps multiply area factors: one becomes two, then ten
. Details. The same interpretation works in three dimensions without drawing a new picture. The diagonal matrixsends the unit cube to a rectangular box with side lengths two, three, and one. Its ordinary volume is six. The minus sign comes from reversing the third direction, so the oriented volume is minus six. Replacing the last diagonal entry by zero flattens the cube into a planar region: its area may be positive, but its three-dimensional volume is zero. This distinction matters whenever a linear map changes shape: the determinant measures size in the full input dimension, rather than the size of whichever lower-dimensional object remains.
The determinant measures neither trace nor perimeter. For , the trace happens also to be five, but the identity matrix in two dimensions has trace two and determinant one. The first parallelogram above has perimeter , compared with four for the unit square; boundary length follows a different rule. Nor does determinant one require every length to stay fixed: the diagonal matrix preserves area while stretching one direction and compressing the other.
These properties make the determinant useful when coordinates obscure what a deformation does. A nonzero determinant certifies that linearly independent input directions remain distinguishable; its magnitude counts the area or volume represented by a transformed cell. That second role reappears in the change of variables formula, where the Jacobian determinant corrects the sizes of small cells. Signed volume also separates a deformation that reverses the orientation of a vector space from one that merely stretches it, even when both give identical ordinary volume factors.[ref]
https://ocw.mit.edu/ans7870/18/18.013a/textbook/HTML/chapter24/section02.html. MIT calculus notes, section 24.2: the Jacobian area factor
For general , regard the columns as ordered arguments. The determinant is the unique alternating multilinear map to the scalar field normalized by . The multilinearity of the determinant means linearity in each column separately, with all others held fixed:Alternation means equal columns give zero; exchanging columns negates the result. Normalization sets the oriented volume of the standard basis to one. These properties also hold in rows. For real three-dimensional columns, their determinant is the scalar triple product, and its absolute value is the enclosed volume. Over other fields, the algebraic definition still works even without a geometric notion of positive volume.[ref]
https://web.mit.edu/18.06/www/Spring16/lecture22.pdf. Barwick, MIT 18.06 Lecture 22: the determinant axioms
Separate linearity does not mean the determinant is a linear map on the whole matrix. Scaling every column of an -by- matrix by gives . For our two-dimensional example, : doubling both directions quadruples area. The power records how many independent directions are being scaled together.
The properties suggest practical computations. Adding a multiple of one column to another preserves the determinant: the extra term has repeated columns and vanishes. This is the algebra behind an area-preserving shear mapping. Alternatively, expansion along a row uses cofactors, each a matrix minor multiplied by a sign:where deletes row and column . The Leibniz formula for determinants supplies the general entry formula. Both calculations encode the same geometric invariant; the defining properties explain their structure without requiring memorization of a separate recipe for every size.[ref]
https://ocw.mit.edu/ans7870/18/18.013a/textbook/HTML/chapter04/section03.html. MIT calculus notes, section 4.3: cofactor expansion
Fractional programming 2026-10-20
Optimization of an objective given as a ratio, such as area divided by perimeter. When the denominator is positive, a trial ratio can be tested by maximizing numerator minus times denominator.
Objective function 2026-10-13
An objective function is a real-valued function assigning a score to each decision under consideration. An optimization problem seeks a feasible solution maximizing or minimizing this score. The optimizing decision and its score are different objects: in the budget constraint example, the decision is and the optimal value is .
Choosing an objective function expresses what matters. With and , maximizing makes every feasible point equally good; maximizing selects ; maximizing rewards balance. If are side lengths, is a rectangle's area, and the budget constraint fixes its perimeter at . The same mathematics then says that a square encloses the largest area among these rectangles.
For the product objective function, the positive level sets are hyperbolas. Each collects decisions with identical scores. The highest attainable level set touches the feasible set at ; higher ones miss it entirely.
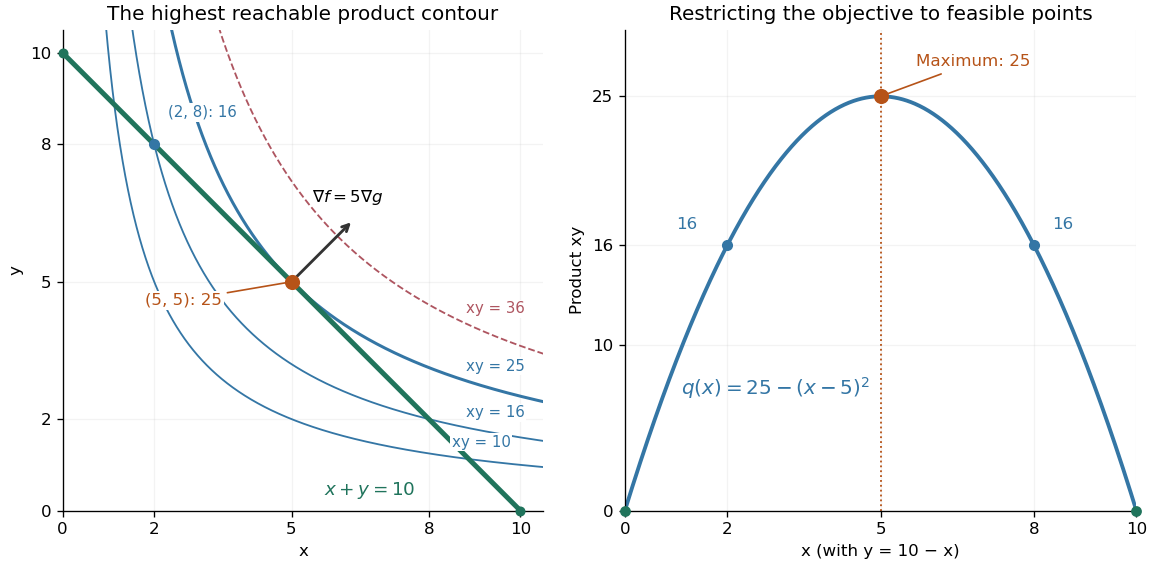


The product is neither a convex function nor a concave function on the positive quadrant: along it is , while along it is . Yet its restriction to this feasible set is a strictly concave function. Thus the geometry of the allowed decisions can make an otherwise nonconcave maximization problem tractable. Replacing by always converts a maximization problem into an equivalent minimization problem.
// Target: mathematical-optimization.bigb
Past exam of the mathematics course of the University of Cambridge 2013 iii Paper 64 1 Solution Created 2026-10-03 Updated 2026-10-07
Write for the total variation seminorm on a domain. For a locally integrable real function its dual definition isThe bounded-variation space consists of functions with finite , equipped with . In the equivalent distributional derivative description, is a finite vector-valued Radon measure and is its total variation measure.
To establish completeness of the bounded-variation space, let be Cauchy in this norm. Completeness of gives in . Given , choose so that whenever . For fixed , the given lower semicontinuity yieldsSince , we obtain . In particular has finite variation; the triangle inequality then puts in the BV space. The same bound proves convergence in the full norm, so this is a Banach space.
For the disk data, put and assume . The exact total variation denoising of a disk isHere is the positive part. A total variation calibration certifies global optimality, including competitors that are not radial or piecewise constant. Define the bounded vector fieldIt has . Its normal component is continuous across the circle, so the distributional divergence has no extra boundary measure. Direct differentiation gives . The dual definition implies : for the standard domain one can cut off at radius , with the error bounded by , and then smooth the test field. In the larger homogeneous bounded-variation space, the same error is bounded by . Thus both usual whole-plane formulations give the same certificate.
Use the perimeter identity and . If , then and . Consequently every competitor satisfiesIf , replace by . Its norm is still at most one, its divergence is , and equality in the calibration holds at . The identical comparison proves optimality and uniqueness of zero, including the threshold . The only general results used are completeness of , lower semicontinuity of variation, the indicator-perimeter identity, the distributional integration-by-parts/dual variation formula and the quadratic norm identity. For , the unique squared-error minimizer is simply .
Perimeter 2026-10-07
The perimeter of a measurable set relative to an open domain is the total variation seminorm of its indicator function there. For a smooth region it equals the Hausdorff measure of the boundary lying inside the domain. Global perimeter uses the entire space as the domain; an internal interface shared by two regions appears in both relative perimeters and must be counted only once in a segmentation energy.
Semiperimeter 2026-10-20