Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 38 5 ii Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
The command uses the model without covariates, starts in mild fatigue at time zero, and calculates expected accumulated years in each state between times and . Let be the fatigue state and its fitted generator matrix. For the occupation time of a continuous-time Markov chain,the expected finite-horizon occupation time isThe first equality follows by interchanging a bounded time integral and expected value, and the second uses the homogeneous continuous-time Markov chain transition matrix. The reported expectations are 7.014800 years mild, 1.724686 years moderate, and 1.260514 years severe. They sum to ten because the person occupies exactly one state at every time. All repeated entries are counted: these are not the lengths of single holding times, the durations until first reaching each state, or the probabilities of occupying the states at year ten. The interpretation of the time limits is also given in the package documentation.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 38 5 i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The fitted continuous-time multi-state model allows only adjacent fatigue-state jumps. Its four transition intensities, in reciprocal years, are shown here:
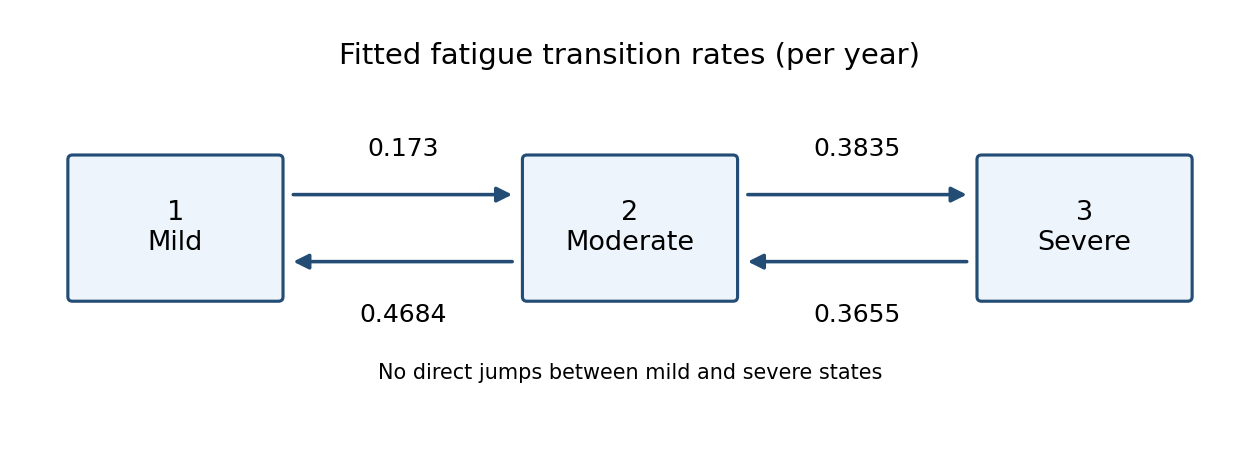
Estimated fatigue transition intensities: mild to moderate 0.173, moderate to mild 0.4684, moderate to severe 0.3835, and severe to moderate 0.3655 per year
. Details. In state , the total exit intensity is . By the holding time law for a continuous-time Markov chain, the time until the next jump has an exponential distribution with this rate. ThereforeThe printed interval for gives the interval for . Taking reciprocals reverses the endpoints, so the transformed confidence interval for the mean holding time isFor the next jump's destination, competing outgoing intensities giveIndeed the density of a first jump to at time is ; integrating gives the ratio above. This is a conditional next-jump probability, not a transition probability of being mild at a fixed later visit.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 37 1 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For the binomial distribution, . Thus the compound binomial distribution hasSet . Since and , differentiating three times givesThe first two cumulants, for comparison, are and .
Choose deterministic claim sizes . Then , so andThis is strictly negative for and . A concrete negative-skewness example is , , , for whichThere is no contradiction with positive claims: bounded Bernoulli-type totals can have more mass near their upper value and a longer left tail.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 37 1 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Put . The count has the zero-based geometric distribution, whose probability generating function is . Hence the aggregate has a compound geometric distribution, withThis transform requires ; it holds for every . To differentiate explicitly, let . ThenandAt zero, and , givingEvery term is positive for and strictly positive claim sizes. Therefore the unstandardized skewness is positive, even if the claim-size third central moment itself is negative. The zero-based convention matters: there is no factor in the numerator of this aggregate transform.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 37 1 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For the Poisson distribution, , so the aggregate has a compound Poisson distribution andThree differentiations immediately giveThe first two cumulants are and . If and claim sizes are strictly positive, , so the paper's unstandardized skewness is strictly positive. For the degenerate count , the aggregate is zero and the third central moment is zero; strict positivity presumes a positive claim intensity.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 4 g Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let and , where is the standard normal distribution upper-tail probability. The mixture model givesFor , threshold inference for a mixture proportion therefore givesThis is a method-of-moments estimate when it lies in . More formally, if of the independent genes exceed the threshold, then , and its constrained maximum-likelihood estimate clips the displayed value to . No numerical estimate is determined without the given value of .
Here . Matching exactly requires , equivalently . For smaller positive , the maximum is at , and a large-sample exceedance fraction this high suggests a mismatch with the prescribed component variances. Sampling fluctuation is still possible; an observed fraction need not equal its expectation. If , the denominator vanishes and this summary gives no information about . Because for finite , matching in expectation also forces . Thus the summary suggests tension with the earlier prior concentrated near , under this mean-zero alternative model. The event is the one-sided exceedance , not .
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 4 f Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Introduce independent component indicators , and auxiliary slab effects , independent of the indicators. Set . Then inactive genes have exactly zero effect, while active genes have the stipulated normal distribution. With supplied as known data and elicited positive beta shapes, one suitable WinBUGS model isThe normal arguments are precisions, not variances. Supply all observed
model {
q ~ dbeta(aq, bq)
for (i in 1:N) {
z[i] ~ dbern(q)
u[i] ~ dnorm(0, 1/V)
theta[i] <- z[i]*u[i]
y[i] ~ dnorm(theta[i], 1)
}
}y values, monitor q, theta and optionally z, and assess Markov chain Monte Carlo convergence diagnostics. The proper auxiliary prior remains defined for inactive genes, where is not informed by the likelihood. This represents the exact point-null mixture prior, rather than replacing its point mass by a narrow continuous spike. Conditional on the indicators, has beta distribution , providing a useful check on the update. Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 4 e Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use prior elicitation to make the qualitative judgments quantitative: ask whether represents a mean, median or mode, and what probability “unlikely above ” should mean, for example a upper-tail probability. A beta distribution on is a convenient family. If is taken as the mean, write its parameters as , , then choose so that the desired tail probability above is obtained. Check its quantiles and prior predictive distribution for plausibility, and assess sensitivity to reasonable alternative elicited values. The information suggests an informative prior near , but does not uniquely determine its parameters.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 4 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Under the independent-gene version of the model, integrating both component labels and effects givesThis product uses independence of the gene effects and observation errors conditional on the shared parameters. Maximize its logarithm over , for example with a one-dimensional bounded optimizer or a grid followed by refinement. Its derivatives areThus the log likelihood function is concave. An interior maximum-likelihood estimate solves the score equation; otherwise it is at zero or one, determined by the endpoint score signs. An alternative expectation-maximization algorithm iteratesFor , the components coincide and is not identifiable; for the full observation values carry information about the mixing fraction.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 4 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Integrating the positive component's normal distribution prior gives its prior predictive distribution:The negative component gives . Let and denote those centred normal densities. The point-null mixture prior assigns component odds , so the posterior odds of the positive component areIts posterior probability is . Evidence depends on , so large effects of either sign favour the positive component. This is the marginal distribution before observing , not the posterior predictive law for a second observation conditional on it.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 4 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Within the positive component, normal-normal conjugacy givesCompleting the square yieldsHere positive denotes membership in the variable-effect component, not the condition ; its normal prior permits effects of either sign.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Compute the Bayesian model evidence for each model by integrating its sampling density against its parameter prior:The posterior odds are the prior odds multiplied by the Bayes factor:The parameter priors used for evidence must be normalized; arbitrary normalization constants in model-specific improper priors would make this comparison undefined.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 3 h Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use conditional versus marginal posterior predictive checks to replicate new plates, rather than recycling the fitted plate effects. For each joint posterior draw of , draw fresh independent and thenUse the same doses and three-plate design, giving the posterior predictive distribution for repeated experiments. Compare observed dose means and their trend, the high-dose downturn, within-dose spreads, and outliers with the replicated curves and intervals. For example compare a discrepancywith draw by draw. The resulting posterior predictive tail fraction or graphical rank assesses whether the observed trend is unusual under this model. Fresh plate effects are needed to assess the population dose-response assumption. Reusing the fitted effects would mainly check the conditional sampling layer and could hide systematic departures from the proposed curve.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 3 g Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For each plate use its conditional fitted intensity, including the fitted random effect. At a posterior draw form the Pearson residualA simpler plot uses in this expression, but posterior draws also display uncertainty in the fitted values. Look for residuals centred around zero, unexpectedly large tails or isolated outliers, and patterns with dose, fitted intensity or plate grouping. For known conditional parameters the Poisson distribution gives mean zero and variance one for this residual; approximate normality is reasonable only at adequate count sizes. Fitting the same data and estimating latent effects changes its calibration, so compare the diagnostics with residuals from conditional posterior predictive checks, rather than treating them as independent exact standard normals.
This checks the plate-level Poisson sampling layer given the effects and can reveal remaining unmodelled variation. It does not by itself establish the population dose-response curve: fitted plate effects can absorb departures from that curve.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 3 f Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Under the common observation-level Bayesian deviance convention, DIC is , with the effective parameter count in DIC defined by . The no-random-effect model's effective count is near three, corresponding to its three fitted regression coefficients. With plate random effects, the effective count rises to : the local effects add flexibility, but their partial pooling means they do not count as eighteen fully independent unrestricted fitted parameters. The effective count need not be an integer or equal the raw parameter count; the scale parameter controls that shrinkage.
Adding the plate effects reduces the average Bayesian deviance by at an effective-complexity cost of . Therefore its DIC is lower byThe reported criterion favours the overdispersed model. This is a fit-complexity comparison, not a posterior probability or Bayes factor. In a hierarchical Bayesian model, the interpretation depends on whether deviance is conditional on local effects or has marginalized them out; these figures use the supplied observation-level convention.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 3 e Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Delete the plate random effects from the linear predictor and remove their stochastic nodes and the unused scale/precision nodes. The observation layer then remains a Poisson distribution withFor example the essential WinBUGS observation block can be written asRetain the coefficient priors. This is the sampling model implemented directly; attempting to keep
for (i in 1:doses) {
for (j in 1:plates) {
y[i,j] ~ dpois(mu[i,j])
log(mu[i,j]) <- alpha + beta*log(x[i]+10) + gamma*x[i]
}
}1/(tau*tau) while fixing tau to zero would divide by zero. Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 3 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The regression coefficients have independent proper uniform distributions on very wide finite intervals. These are flat in the coefficients, not flat in fitted rates, and can be highly informative on the rate scale. The scale is uniform on , and WinBUGS receives the corresponding precision for each normal distribution random effect. Writing , the induced prior density isIt is proper and integrable at zero.
The usual scale-invariant variance prior would instead cause an improper posterior from a log-uniform random-effect scale prior. After integrating out the plate effects, the likelihood function tends as to the ordinary positive Poisson likelihood. On any compact interior set of coefficient values this limit is positive and bounded away from zero. Hence the posterior normalizing integral contains a divergent factor . There is no posterior distribution under that prior, even if formal full conditional distributions appear usable. Thus a proper prior with integrable mass near zero is needed here. The reciprocal-scale rule is the standard pure-scale Jeffreys prior; it should not be confused with the model-specific information prior for an additive variance component.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 3 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Centre and scale both predictors, particularly the raw dose whose scale is much larger than that of . For example use , and the linear predictor . This reduces the intercept-slope correlations and numerical scale disparities; further orthogonalizing correlated columns or updating coefficients jointly can improve Markov chain Monte Carlo mixing. The exact old prior can be retained through the corresponding coefficient transformation; assigning new independent priors to transformed coefficients would instead change the prior.
For weakly informed plate effects or small , use the non-centred Gaussian random-effect parameterisation with . This often reduces dependence between the scale and local effects; it is not guaranteed to outperform the centred version when plate effects are strongly informed. Sensibly calibrated proper priors also avoid the enormous initial log intensities permitted by the stated coefficient ranges. Use dispersed chains and Markov chain Monte Carlo convergence diagnostics to assess stationarity, agreement between chains and effective sample size of a Markov chain. Reparameterization can improve mixing; simply retaining more iterations does not remove poor mixing.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 3 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let . The Poisson-lognormal random-effect model assigns each plate a random intensity . Conditional on that intensity its Poisson distribution has mean and variance both , but marginalizing over the normal distribution of the random effect givesThe law of total variance yieldsThis exceeds the mean whenever . The independent plate effects supply additional heterogeneity without inducing dependence between plates conditional on the global parameters. Also is the median random intensity, not its marginal mean; the factor matters for population predictions.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 36 3 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14At several doses the three replicate plates differ much more than the square-root-of-mean scale expected from a Poisson distribution. For example the group at dose has sample mean about and sample variance about , rather than variance near . Its counts span a range of , compared with a Poisson standard deviation about . The dose- and dose- groups likewise have variances above their means. Thus extra plate-to-plate variation is plausible. With only three replicates per dose this is evidence suggesting overdispersion, rather than a precise determination of it; not every group has excess sample variance.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact