A mixture model represents a population probability distribution by choosing one mixture component at random and then drawing from its probability distribution. For a finite mixture model whose mixture components have probability density functions , the resulting mixture distribution has probability density functionThe mixture weights ensure and . For discrete random variables the same formula uses probability mass functions; without either kind of density, write for component distributions . A zero mixture weight makes that mixture component inactive.[ref]
Finite Mixtures. Finite Mixtures, sections Latent discrete parameterization and Summing out the responsibility parameter: nonnegative normalized weights, categorical labels, and the sum of weighted normal densities
The mixture components need not occupy disjoint bins of . Two normal distributions both have positive probability density functions everywhere, so the same value can plausibly come from either mixture component. The Two-Gaussian mixture example makes this overlap visible, and its mixture responsibilities quantify the remaining uncertainty about the latent variable. This is useful when a single normal distribution cannot represent the population's shape, but a fitted mixture model alone does not establish that its mixture components are real biological or social groups.
For a two-component mixture model with known component tail probabilities above a threshold, the overall probability is . An empirical exceedance fraction gives the displayed method-of-moments estimate when . Under independent observations, the exceedance count has a binomial distribution, and its constrained maximum-likelihood estimate is the same expression clipped to . Equal component tail probabilities make this summary uninformative about .
A Gaussian scale mixture is a random variable , where has a standard normal distribution and is independent of a positive random scale . Its probability density function is the average of the conditional normal densities. Random scales can produce larger kurtosis than a single normal law.
An independent unit-scale Rayleigh distribution variable and standard normal distribution variable give with Laplace distribution of density . Indeed its characteristic function is .
A finite mixture model draws each observation from one of finitely many component distributions according to a categorical latent label.
A mixture component is the conditional distribution of given a component label . Its probability density function integrates to one; its weighted contribution to the mixture distribution integrates to the mixture weight . Thus a mixture component is a distribution, rather than a region assigned to it by a clustering rule.
Generate a finite mixture model by drawing a categorical variable with , then drawing from the mixture component . The indicator random variables satisfy : exactly one mixture component generates each draw. The joint probability distribution obeys , and the law of total probability gives the mixture distribution after summing out .[ref]
For independent draws from this statistical model, draw a fresh for each . Drawing one shared latent variable for an entire collection is a different joint probability distribution: its individual marginal distributions can match the same mixture distribution while its observations are dependent.
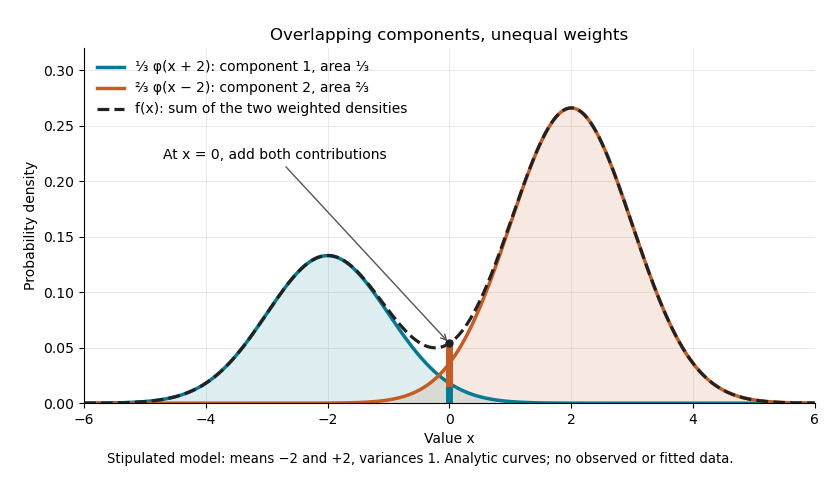
Stipulate an original Gaussian mixture distribution with mixture weights , , component means , , and component variances both equal to one. These are chosen statistical parameters, with no observed sample or fitting. If is the standard normal distribution probability density function, thenIn the figure, the two colored curves are weighted probability density functions, with areas and . Adding their heights at every gives the black curve. Neither colored curve stops at a dividing line.

The law of total expectation and law of total variance give the total mean and variance:All of the extra variance comes from variation between component means. Equivalently, the second moment is , so the variance is .
A mixture distribution is different from a deterministic linear combination of random variables. If independent and are drawn and , then has a normal distribution with the same mean but variance , rather than . Every draw of uses both random variables. A draw from the mixture distribution instead uses , where the mixture allocation indicators are independent of and select exactly one of them. The expression for adds densities, not simultaneous random outcomes.
In a finite mixture model with hidden membership, the component label is a latent variable and is observed. If an actual recorded label specifies which mixture component generated , then is observed and its likelihood contribution is . With the label hidden, the observed likelihood contribution is the sum . A hard assignment chosen from mixture responsibilities is an inference under the statistical model, not an additional recorded label.
Simultaneously applying a permutation to the mixture weights and mixture components leaves unchanged. Thus identifiability of named components requires a convention, such as ordering distinct component means; label switching describes the associated inferential issue.[ref]
Even after choosing label names, identical mixture components reveal only their combined mixture weight, and an inactive mixture component has undetermined statistical parameters. Adding mixture components increases flexibility but can cause overfitting; judge predictions using cross-validation, rather than interpreting every fitted component as a discovered population.[ref]
Mixture Models. §21.1.6, printed pp. 445-446: probabilistic clustering and evaluation on future data
If component priors are exchangeable, permuting component labels leaves the mixture likelihood and posterior distribution unchanged. A sampling chain can visit these equivalent modes, making naive component-by-component averages misleading. Predictive densities and other permutation-invariant summaries avoid the issue; component-specific interpretation requires an explicit identification or relabelling rule. Nonexchangeable weight priors can break exact symmetry but do not remove every multimodality problem.
In a finite normal distribution mixture with allocation labels , independently assign , and weights a Dirichlet distribution. Let count allocations to component and sum their observations. The conditional mean precision is , giving . The conditional variance is the displayed inverse-gamma distribution; weights have Dirichlet parameters increased by allocation counts. Allocation probabilities are proportional to . Independence of the mean prior from is important: its density does not add an extra inverse-gamma shape term.
A mixture responsibility is the posterior probability of a component label given an observation and current parameters: . Each observation's responsibilities sum to one. The expectation-maximization algorithm uses these soft assignments rather than fixed hard cluster labels.
For fixed statistical parameters and , Bayes' theorem gives the mixture responsibilityIt is the conditional expectation of the mixture allocation indicator. This posterior probability concerns the hidden label, with held fixed; it does not require a prior distribution over . For a continuous , use the density ratio to define this conditional distribution, rather than dividing probabilities of the zero-probability event .[ref]
Finite Mixtures. Finite Mixtures, section Recovering posterior mixture proportions: Bayes formula for label probabilities conditional on the observation, component parameters, and mixing weights
For the Two-Gaussian mixture example, the component density ratio is , so the posterior probability ratio and the mixture responsibilities areAt the two unweighted component densities are equal, so the mixture responsibilities equal the mixture weights: , . At , the second component density is twice the first and its mixture responsibility is . Equal mixture responsibilities instead occur at : the more frequent second mixture component is favored even slightly to the left of the midpoint.
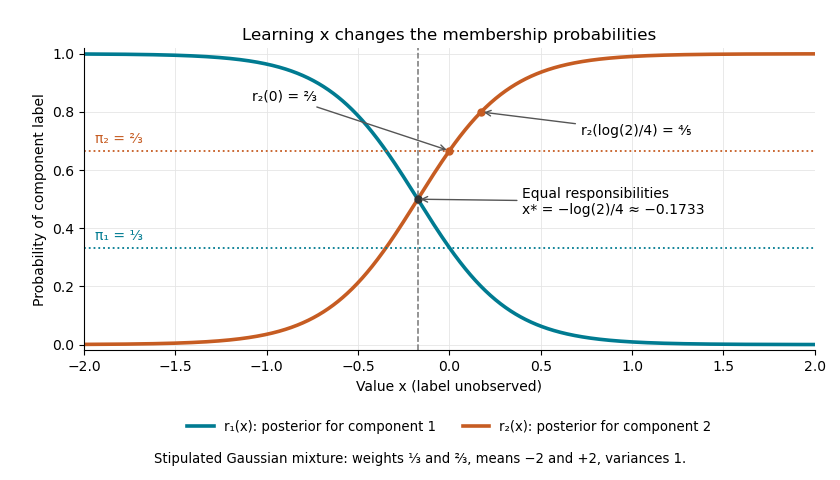

The mixture weights describe membership before learning ; mixture responsibilities describe membership after learning . The law of total expectation gives under this statistical model, although varies across individual values. In fitting by the expectation-maximization algorithm, evaluate mixture responsibilities at the current statistical parameters and recompute them after an update.
A finite Gaussian mixture with a common variance has density , with positive common variance and weights summing to one. The means locate its latent components, which need not correspond to distinct modes. It has free parameters: weights, means and one variance. EM for Gaussian mixtures with a common variance supplies iterative likelihood updates.
Residual mixture clustering first removes a fitted covariate-dependent mean and then explores latent groups in the regression residuals. It seeks differences relative to the adjustment rather than raw-response differences. Mixture responsibilities express uncertain membership. The fitted mixture alone does not establish distinct real-world populations, and two-stage residual mixture fitting ignores some adjustment uncertainty.
Fitting a mixture model to regression residuals treats the fitted mean adjustment as fixed. Even with independent homoscedastic errors, ordinary least-squares residuals have covariance matrix and satisfy fitted linear constraints, so they are not exactly independent observations. A joint mixture regression with shared slopes or a bootstrap of the whole fitting process better accounts for the first-stage estimation uncertainty.
The E-step computes mixture responsibilities from the old parameters. Put . The M-step updates , and . The variance uses new means and old responsibilities. EM likelihood monotonicity guarantees nondecrease of the observed likelihood, not a global optimum.
A mixture weight is the probability assigned to one component of a mixture model; all mixture weights are nonnegative and sum to one.
A Dirichlet process mixture model uses a Dirichlet process as a random mixing distribution, allowing the number of occupied mixture components to be inferred from the data.
Articles by others on the same topic
There are currently no matching articles.