Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 41 1 g Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
The number needed to treat is the reciprocal of the absolute reduction in the 12-week adverse-outcome risk. Using the counts rather than rounding the percentages first givesThis means about nine high-risk women would need to be offered the intervention to prevent one additional screen-defined case over that follow-up, under the trial's comparison. It is not a lifetime quantity or automatically an estimate for clinical-interview diagnoses. Calculating from the rounded difference gives approximately nine but need not give the same integer rounding; the exact counts explain the reported value.
For a confidence interval, first construct an interval for the difference between the two independent event proportions, allowing for binomial distribution sampling uncertainty. If both risk-reduction endpoints are positive, take their reciprocals and reverse their order to obtain an NNT interval. A bootstrap can instead resample women within their randomized controlled trial arms and transform the resulting risk-difference distribution. If the difference interval includes zero, the NNT confidence set extends through infinity and can include harm as well as benefit; it is not an ordinary bounded interval. The raw-outcome interval also relies on the missing-outcome assumptions discussed above.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 41 1 f Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14There was no clear documentation of initiation for women, givingThese women may not have received the intervention, although missing documentation is not proof that no contact occurred. Documentation of initiation also does not establish completion or full adherence.
Under intention-to-treat analysis, women retain their randomized arm regardless of actual uptake. Removing nonadherent women would condition on a post-randomization characteristic and could destroy the comparability created by randomization. The resulting estimand is the effect of offering the intervention under the trial's actual adherence pattern. Keeping nonadherent women in their arm does not itself solve missing-outcome problems: the reported 12-week denominators are smaller than the randomized totals, so the outcome analysis still needs an appropriate strategy and assumptions for losses to follow-up.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 41 1 e Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let indicate a depressed outcome and indicate the control arm. A logistic regression could specifywith containing prespecified baseline characteristics, including the stratification factor. Fit the coefficients by maximizing the likelihood for independent Bernoulli random variables . For equal covariate values the control-to-intervention odds ratio is . Thus an estimate produces the quoted adjusted ratio. An ordinary Wald confidence interval is obtained by exponentiating the endpoints of the coefficient's confidence interval.
The raw control-to-intervention odds ratio, using the actual counts, isUsing only the quoted percentages gives about , so both versions are approximately . The printed is not the usual whole-percentage rounding of ; using the counts avoids that small numerical inconsistency. The reversed intervention-to-control ratio is about .
The apparent surprise is a coding issue: with depression as the adverse outcome and intervention relative to control, protection would give an odds ratio below one. A ratio above one is favourable if the comparison is control relative to intervention, as above, or if the outcome has been recoded as absence of depression and intervention is compared with control. Both comparison and outcome must be specified. The adjusted ratio need not equal the crude one, even in a randomized trial: covariate adjustment and noncollapsibility of the odds ratio can change an odds ratio. Their close numerical values here do not prove that the regression adjustment was unnecessary.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 41 1 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The research nurses should be unaware of each woman's randomized allocation. Blinded outcome assessment reduces the possibility that knowledge of receiving peer support changes how questions are asked, how answers are interpreted, or how a clinical diagnosis is recorded. It is especially useful for interview-based and partly subjective outcomes.
The mothers and volunteers would generally know whether calls took place. A mother might mention her volunteer, or a nurse might infer allocation from the conversation or consult records revealing it. This can break assessor blinding even when the allocation list is hidden. Standardized outcome interviews, separate intervention records and asking participants not to disclose allocation can help. Outcome assessment blinding is distinct from allocation concealment at recruitment, and does not prevent participants' own awareness from affecting reported symptoms.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 41 1 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The primary outcome addresses the main prespecified question; the secondary outcomes involve several additional comparisons. Testing each at would increase the chance of at least one false positive across them. The smaller secondary significance level makes their individual tests more conservative, reducing multiple testing problems.
This is a design distinction between confirmatory and additional outcomes, not a claim that secondary outcomes are intrinsically less important. A level of per secondary test does not by itself establish a particular bound on the familywise error rate unless the whole testing plan and number of tests are specified. Likewise, having two primary measurements still needs a clear prespecified reporting and multiplicity strategy.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 41 1 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Specify the expected control-group event probability at the chosen follow-up time, the intervention probability or smallest clinically important absolute reduction to detect, the primary test's significance level and whether it is one- or two-sided, the desired statistical power, and the allocation ratio. Statistical power is the probability of rejecting the null hypothesis under that specified alternative; its complement is the Type II error probability.
For two independent binary-outcome groups, these probabilities determine the response variances needed by the sample-size calculation. Also specify how much loss to follow-up is anticipated when converting the required evaluable sample into a recruitment target. Here the design is balanced and the stated primary significance level is . A target statistical power such as or and the anticipated event probabilities cannot be recovered from the sample size alone, so they should not be invented. The recruitment inflation allows for attrition rather than changing the target effect.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 41 1 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use separate randomization lists for women with and without a self-reported history of depression. Within each stratum, the central service could assign intervention and control in a ratio using randomly permuted blocks, preferably with concealed and varying block sizes. This is stratified randomization; the internet service can retain allocation concealment because the recruiting staff do not know the next assignment.
History is plausibly prognostic for the outcome. Keeping its distribution similar between arms reduces the risk of a chance imbalance in that important baseline factor and can improve precision. It also allows a comparison within each history stratum. Stratification does not guarantee balance of every other covariate, and staff must not be allowed to choose assignments. The regression model can retain history as a baseline covariate, respecting the design.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 6 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Both EM algorithm and data augmentation exploit a latent completion , but they use it differently. EM takes a conditional expectation of the complete-data log-likelihood and then maximizes over the parameter, producing a deterministic sequence of point estimates when the M-step is uniquely specified.
In Bayesian data augmentation, choose a prior distribution and targetAlternate the Gibbs sampler updatesThese are stochastic draws from full conditional distributions, not an expectation followed by maximization. Their invariant law is the augmented joint posterior, and discarding gives posterior inference for , including uncertainty rather than only an MLE. A sampled completion followed by maximization would instead be a stochastic EM variant. Individual likelihood values along a data-augmentation chain need not increase: the chain is designed to sample a posterior, not to ascend the likelihood.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 6 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14EM likelihood monotonicity makes EM an ascent method, not a global-optimization theorem. If the log-likelihood is bounded above along the iterates, its nondecreasing values converge. That alone does not show that the parameters converge, nor that any limiting parameter is a global maximum-likelihood estimator. Under additional regularity, accumulation points can be stationary; local maxima, other stationary points or flat sets can depend on initialization. Multiple starting values and comparison of the achieved observed likelihoods are therefore useful.
The upper-bound hypothesis is substantive. In a finite mixture model with a freely shrinking normal-component variance, placing one component at an observed value can make the likelihood unbounded while other components cover the remaining observations. In that situation monotonicity provides no finite maximum to converge to. EM may also improve very slowly, and a small change in likelihood alone is not proof of an accurate global solution. The guarantee in part (b) is nondecrease, not strict increase at every iteration.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 6 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write and . Assume the likelihoods are positive and the expected log likelihoods used in the step are finite. On the support where , let . Integrating over that support givesIt is an equality when the candidate joint density has no additional mass outside the old support. Concavity of the logarithm and the Jensen inequality now implyThus the argument does not silently require an identical support at every parameter. The M-step selects a value whose right-hand side is nonnegative, proving EM likelihood monotonicity:When the conditional densities allow finite divergence, the same calculation has the informative exact formThe Kullback-Leibler divergence is nonnegative, since . This also explains why an increase of the surrogate objective guarantees an increase of the observed objective, while equality of the two likelihoods is possible.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 6 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The observed-data likelihood function integrates out the latent variable:Choose an initial parameter with positive likelihood. At iteration , the E-step of the EM algorithm forms the entire expected complete-data log-likelihoodThe expectation is under the conditional missing-data law at the old parameter, while the argument remains free. The M-step then choosesThe observed data stay fixed throughout. This is not obtained merely by substituting the conditional mean of into a nonlinear log-likelihood: the expectation of all required complete-data terms must be taken. A generalized EM step only requires , which suffices for the monotonicity proved next. Exact maximization assumes that an admissible maximizer exists.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 5 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Tune the proposal scale using pilot runs on a grid of candidate values. After allowing for initial transients, compare the effective sample size of a Markov chain per unit computation time for representative functions, such as both coordinates and a quadratic function. Equivalently inspect their integrated autocorrelation time, using . Choose a useful scale and keep it fixed for the production run. Another pilot criterion is the average squared accepted displacement, possibly in coordinates standardized by the target covariance, which balances move size and rejection.
Acceptance alone is not an efficiency criterion. As , proposals are almost the current state, so acceptance tends to one while exploration becomes arbitrarily slow. Very large scales propose mostly low-density states and produce long sequences of identical values. The proposal scale and random-walk Metropolis efficiency trade-off requires both movement and acceptance; neither maximizing nor merely reporting the acceptance probability guarantees a useful sample. With strong correlation, an isotropic proposal also struggles with the target's narrow direction; covariance-scaled proposals can improve this geometry beyond tuning one scalar variance.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 5 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-20
Codex 0 Created 2026-10-03 Updated 2026-10-20Use the random-walk proposal specified by its centre and covariance: for the current state draw independently standard normal and setIts properly normalized density of the proposal distribution isIt is symmetric: . This is a centred-at-the-current-state proposal, rather than an unshifted draw from the density notation in the source. The random-walk Metropolis algorithm consequently needs only the target ratio. Put . ThenAn independent uniform decides the move; on rejection both coordinates remain at their previous values. A proposal with lower is always accepted. This construction uses the joint density directly, without needing either conditional distribution. Its continuous positive proposal density supplies communication over the target support, and the holding probability avoids a deterministic periodic transition pattern.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 5 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For a target probability density function and a proposal distribution with density , the Metropolis–Hastings algorithm starts in the target support and repeats: propose , draw an independent uniform , and move to ifOtherwise retain . A zero reverse-proposal density makes the acceptance zero. Unknown multiplicative constants of cancel. For distinct states,which is symmetric in the states. Together with the probability of holding at the current state, this proves detailed balance and invariance of . Successive values form a dependent Markov chain; convergence from arbitrary initial states additionally needs the appropriate irreducibility and aperiodicity, not just this invariant-density identity.
The Gibbs sampler updates a coordinate using its full conditional distribution while keeping the others fixed. For coordinate , write and . Its proposal replaces by . The MH ratio, interpreted on this one-coordinate proposal space, isThus every Gibbs coordinate update is an MH update with acceptance one. A random choice of coordinate gives a mixture of these invariant kernels; a deterministic sweep gives their composition. Both preserve . The latter composition need not be reversible, so the special-case statement is about the coordinate kernels, not a claim that every entire systematic sweep is one reversible MH kernel.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 4 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14There is a genuine normalization error in the printed function. Write independently, and . The internal sum produces a scalar; taking its mean does not divide by . The literal returned value is thereforeSince and , its expectation isIt does not estimate unbiasedly unless , and no fixed control variate coefficient removes this bias. In particular the actual call with returnsThis is an instance of summing before taking a mean changes Monte Carlo normalization.
The intended corrected method replaces the sum by a sample mean:It uses symmetry to write the tail as , then Monte Carlo integration on a bounded interval, and finally a mean-zero control variate. For the intended estimator is , whose summands are smooth and bounded. Keeping the average normalization, andDifferentiating this quadratic gives the Cauchy tail control variate on a bounded interval coefficientHere , , so . AlsoConsequentlyThe negative sign is consistent with decreasing and increasing. One may estimate the covariance and variance using a separate pilot sample and fix the resulting coefficient for a fresh sample. This coefficient minimizes the literal function's variance as well, but its missing factor of still leaves the bias above.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 4 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For with uniform on ,Thus has a Pareto distribution and is the importance sampling proposal, concentrated on the required tail. The target tail integrand is , so its importance weight isThe function returns . Since , it is an unbiased estimator. For its second moment,An antiderivative is , so the integral is . Independence of the proposals givesThis is importance sampling of a Cauchy tail, with weights between and . Their narrow range explains the much smaller variance than the indicator estimate, without appealing to nonexistent Cauchy moments.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For independent standard Cauchy distribution draws , the code averages the indicators . Each is a Bernoulli random variable with parameterHence it is an unbiased estimator of that tail probability, and independence givesThe variance is finite even though the underlying Cauchy draws have no finite mean: the variables being averaged are bounded indicators, not the Cauchy values themselves.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 3 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For , use the unnormalized normal density . Its ratio region isThe bound on is one because is maximized at zero. To bound , maximize for . Its derivative vanishes at , giving . Thus the normal ratio-of-uniforms envelope is , .
Draw independent , set and , and accept precisely whenreturning . Equivalently compare logarithms to avoid underflow. Since , the region area is and the rectangle area is . ThereforeIt is independent of the normal scale. In the diagram the vertical coordinate is normalized by , so the same shape works for every positive scale.
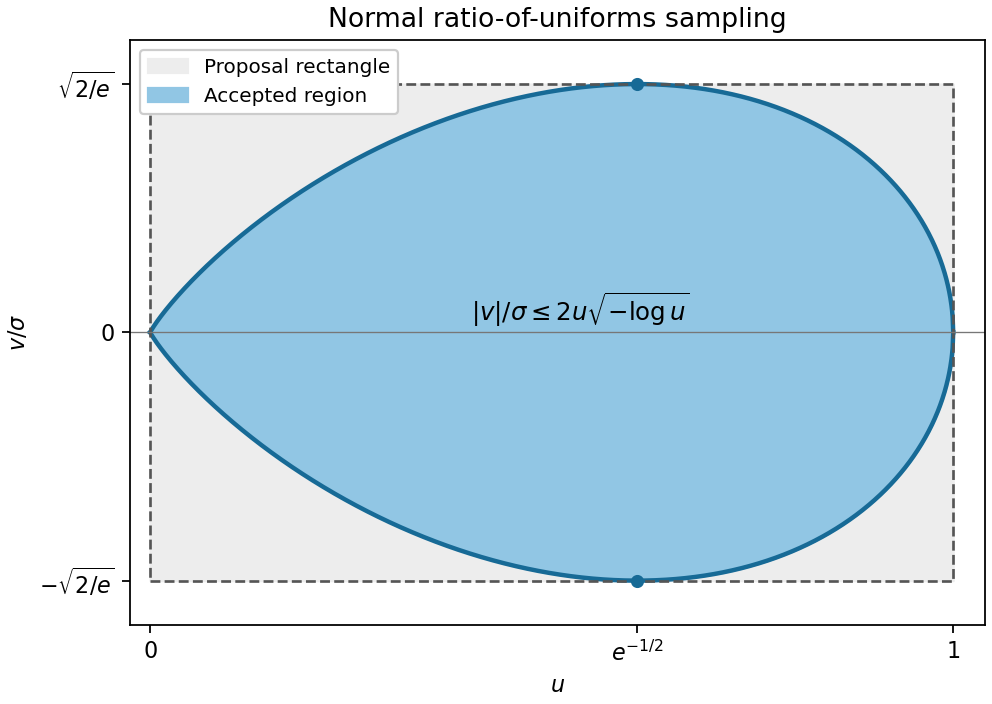
Normal ratio-of-uniforms region and its minimum axis-aligned rejection rectangle
. Details. Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 3 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The region usually has a curved boundary, so sampling uniformly inside it directly is inconvenient. Rejection sampling replaces it by an easily sampled envelope, usually a rectangle. Choose finite bounds withThen up to null boundaries. A general rectangle algorithm uses only independent uniform deviates: draw on , set , , and return if ; otherwise repeat. If a numerical generator returns , discard that draw before division. No knowledge of is required to run the method. Its acceptance rate is the ratio of the two areas:More generally the same area ratio applies to any finite-area envelope sampled uniformly. A change in the proportionality constant of scales both ratio coordinates and their areas consistently.
Finite rectangle bounds are a real condition, not a consequence of integrability alone. For instance is integrable, but is unbounded. A finite-area envelope for a ratio-of-uniforms region gives a general extension: choose a finite-area open envelope containing , decompose it up to null boundaries into countably many disjoint rectangles, and select a rectangle with probability proportional to its area using a uniform draw and cumulative probabilities. Use two more uniforms to sample within it, then apply the same acceptance test. This samples the envelope uniformly and has acceptance . Such envelopes exist for every finite-area measurable ; obtaining usable bounds or an effective rectangle decomposition is density-specific. The finite-rectangle version above is the usual practical implementation.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 40 3 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let be proportional to the target probability density function, with . Define the ratio-of-uniforms method through the regionDraw uniformly with respect to area on and return . To prove its law, change variables from to . The Jacobian determinant is , and the allowed interval for is . ConsequentlyThe joint density of is therefore on that interval. Integrating out givesFor an already normalized density, and the region has area . The name refers to the two coordinates of a uniformly sampled region; drawing two unrelated uniforms on arbitrary intervals and taking their ratio would not give the target law.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact