The Bayesian model evidence is the prior predictive distribution evaluated at the data . For a statistical model with a normalized prior density , its marginal likelihood isThis is an expected value of the likelihood function under the prior distribution; for discrete statistical parameters, replace the integral by a sum. For continuous observations, is a probability density function value with respect to a specified data reference measure, rather than a probability of one exact observation. Comparisons must use the same data and reference measure. The same normalizes the within-model Bayesian posterior and supplies the between-model comparison in a Bayes factor.[ref]
Bayes Factors by Robert E. Kass and Adrian E. Raftery. Kass and Raftery, Bayes Factors (1995), section 3.1, p. 776, equations (1)–(2): integrating over parameter priors
A normalized prior distribution makes the Bayesian model evidence an average, so it cannot exceed the largest likelihood function value on its support. A broad prior distribution can assign little mass to values that predict the data well, even when one value gives an excellent fit. The worked uniform-alternative binomial Bayes factor below makes the difference between averaging and maximum likelihood estimation explicit.
For a normalized uniform prior on , Bayesian model evidence is . It averages the likelihood over the prior range. Extending a well-placed interval into low-likelihood regions reduces that average, but moving or widening a poorly placed interval can improve it. A model prior is separate: posterior model odds equal the evidence ratio multiplied by prior model odds.
If , integrate the two exponential branches at . An interval of half-width centred at has . An interval entirely below the peak has . These expressions show quantitatively how fit location and prior width combine.
A prior predictive check simulates parameters from the prior distribution and observations from their sampling model, then examines whether those observations are plausible before conditioning on data. This reveals unintended information from apparently broad priors, especially after nonlinear transformations or when scales and correlations are coupled. It differs from a posterior predictive check, which uses the posterior distribution.
Let be a proper prior density, let for prior-almost every parameter, and let . For posterior draws , the harmonic mean estimator isThe identity follows by cancelling in the posterior density. The variance of is often infinite, making the estimate unstable even when an ergodic average is consistent.[ref]
Bayes Factors by Robert E. Kass and Adrian E. Raftery. Section 4.3, pp. 779–780, equation (11) and reciprocal-likelihood instability
The support qualification matters. If , cancellation instead gives . For a uniform prior on and , the evidence is , but every posterior likelihood value is one and the displayed estimator is always one. An improper prior also leaves the absolute evidence normalization undefined.
A Bayes factor measures how data change the relative support for two specified statistical models. Write for their Bayesian model evidence and define the direction explicitly:For positive finite , a value above one favors over ; a value below one favors over . Reversing the comparison gives , the opposite direction used in some formulas below.
For mutually exclusive, exhaustive with positive prior probabilities, divide their two Bayes' theorem formulas. Their common data normalizer cancels, leavingThe Bayes factor therefore multiplies prior odds into posterior odds. It is evidence conditional on the specified statistical models and their within-model prior distributions; it is not . Model prior probabilities supply a separate input.[ref]
Bayes Factors by Robert E. Kass and Adrian E. Raftery. Kass and Raftery, Bayes Factors (1995), section 3.1, p. 776: posterior odds, prior odds, and direction of the Bayes factor
For an original stipulated example, consider ten independent and identically distributed Bernoulli trials, with heads as success. Compare with , both fixed before seeing the data. Take to be one particular ordered sequence containing eight heads and two tails. The likelihood function under either point model is , soIf , the prior odds for against are . Hence the posterior odds are , andEqual model prior probabilities would instead give . The same Bayes factor can thus accompany different posterior probabilities. These statements condition on the two-model comparison; they do not establish that either statistical model describes a real coin.
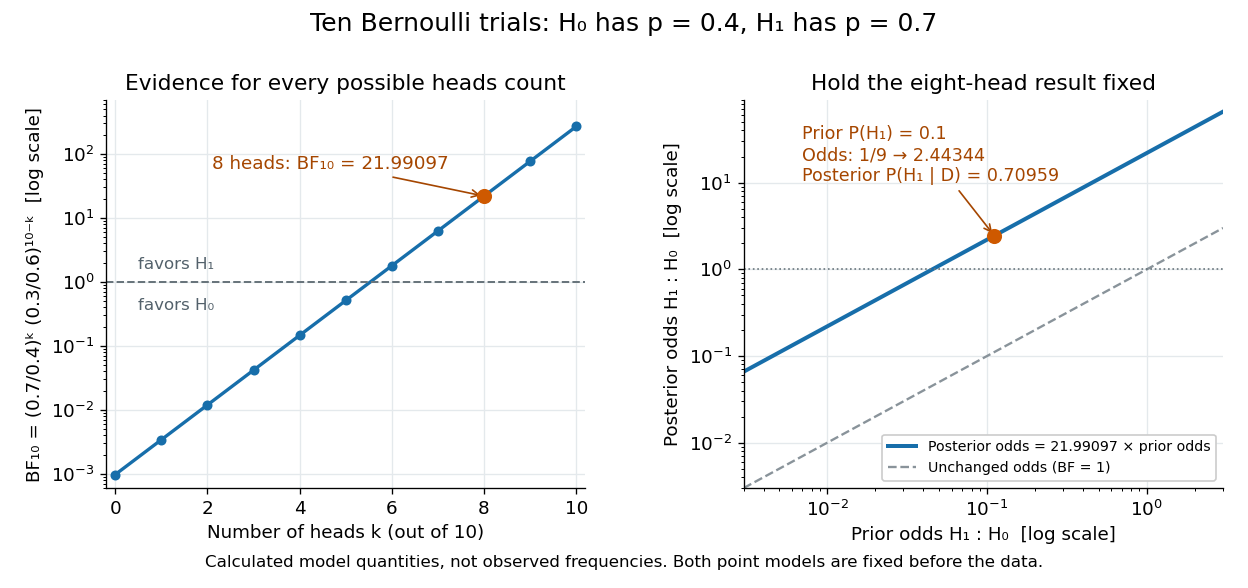

Using the heads count instead of the ordered sequence changes the sample space. The binomial distribution assigns it mass . The same binomial coefficient multiplies both models' Bayesian model evidence and cancels in their Bayes factor. Mixing an ordered-sequence numerator with a count denominator would introduce an erroneous factor of .
Fix the candidate statistical models, their parameter prior distributions, and model prior probabilities before using the current data for this update. The Bayes factor is useful because it separates evidence from model prior odds, but it still depends on the parameter prior distributions. An improper prior has an arbitrary multiplicative normalization: multiplying its kernel by multiplies its formal marginal likelihood by , even if the within-model posterior distribution is normalizable. Without a separately justified convention, the ordinary Bayes factor is then undefined up to arbitrary constants.[ref]
Bayes Factors by Robert E. Kass and Adrian E. Raftery. Kass and Raftery, Bayes Factors (1995), sections 5.2–5.3, pp. 782–783: prior sensitivity and undefined multiplicative constants
For a random sample with known and prior distribution with , compare to . The prior odds are one by symmetry. Normal-normal conjugacy gives a normal posterior distribution withIts negative and nonnegative masses are and , whereSince the Bayes factor is the posterior odds divided by the prior odds,Here is the cumulative distribution function of the standard normal distribution. The ratio decreases with the sample mean. For any threshold , the inequality is equivalent to and hence toFor , the quantile is , and the equivalent posterior probability threshold for is . The symmetry and proper normalization of the two hypothesis-conditional priors are essential to replacing the Bayes factor by the posterior odds directly.
For two models with finite positive prior odds, a sequence of data with identical conditional likelihoods under both models has Bayes factor one. The posterior odds therefore equal the prior odds. This requires equality of the probability model for all the data considered, not merely that both models fit a selected data set.
For a binomial distribution count, compare a point null with the uniform alternative prior distribution on . The alternative Bayesian model evidence isso the exact Bayes factor favouring the point null is . With standardized deviation , the local normal distribution approximation is . At fixed the frequentist p-value remains approximately constant, while the factor grows like . This demonstrates the prior-width mechanism behind the Jeffreys-Lindley paradox for a Gaussian point null in a discrete sampling model.
For a separate original example, change the point null to and take to have a uniform prior , fixed before the ten Bernoulli trials. Here is drawn once under and shared by all ten trials: they are independent conditional on . For one particular ordered sequence with eight heads and two tails, the Euler beta function givesThus the Bayes factor for the uniform alternative against the point null isThe binomial distribution count formulation gives and . Their ratio is again ; these count masses must not be combined with the ordered-sequence masses above. The general formula at the start of this article puts the point null in the numerator, so it equals here.
In contrast, maximum likelihood estimation gives : differentiating the log-likelihood yields , and the endpoints have zero likelihood. Its peak-to-null likelihood ratio isThis peak is chosen after seeing the data, so it is not the Bayes factor of the prespecified . The Bayesian model evidence for averages over its entire uniform prior; it is smaller than the peak. It is also smaller than . Against the same null, a point alternative fixed at would give a Bayes factor about , greater than . An integrated alternative need not outperform a point alternative.
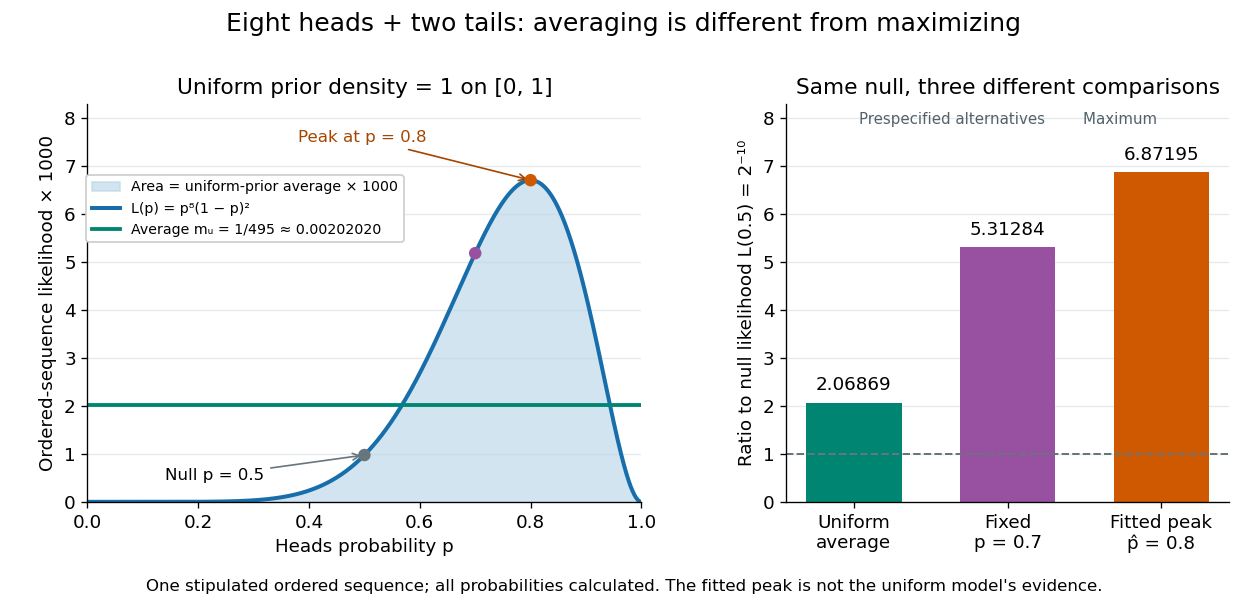

For a general proper beta distribution prior distribution with , the same ordered-sequence marginal likelihood is . This follows by substituting the normalized prior density into the integral, and shows exactly where the parameter prior distribution changes the Bayes factor. Holding the parameter prior distributions fixed while changing model prior odds leaves that Bayes factor unchanged.
A Gaussian practical-null mixture compares a narrow centered normal distribution prior with a wider centered normal distribution prior. Neither component is a point mass. With observed mean and prior precisions , its model predictive variances are , and the Bayes factor isThe overall posterior density is a Bayesian model averaging mixture with component means . A wide-prior penalty can favor the practical null near zero; its dominance depends quantitatively on both prior scales and the observation, not merely on the observation being of order .
Compare an unrestricted model with parameters to . Suppose the likelihoods agree under that restriction, the priors are proper, and the nuisance prior under equals the conditional prior under . Using compatible density versions with , Bayes' theorem givesIndeed, the numerator of the marginal posterior density at is .
This ratio concerns densities in the unrestricted model, not a posterior atom at the null. A separately chosen nuisance prior under the null can invalidate the simple ratio; matching marginal nuisance priors is insufficient when and are prior-dependent. Density values on a measure-zero restriction also require an agreed continuous or otherwise specified version.[ref]
Bayes Factors by Robert E. Kass and Adrian E. Raftery. Section 4.3, p. 780, conditional-prior qualification following the density-ratio identity
Articles by others on the same topic
There are currently no matching articles.