For , a Poisson random variable has probability mass functionThe exponential function series verifies normalization. At , define with certainty. The equality of mean and variance is a distinguishing model property, though it does not by itself characterize the law.
When counting events in a homogeneous Poisson process, distinguish its rate from the distribution parameter: an interval of duration has . A rate measured per minute times a duration measured in minutes gives a dimensionless expected count. This process assumes independent increments, a constant rate, and a negligible chance of multiple events relative to interval length in a sufficiently short interval. A rate alone does not establish a Poisson distribution. See Bertsekas and Tsitsiklis, chapter 6 summary, pages 46-47.
For a constructed arrival model with events per minute over minutes, . The mean and variance are both three, andThe probability of at least one event is . These results describe the specified process, not every arrival mechanism with the same average rate.
The Poisson limit theorem, often called the law of rare events, connects this law to the binomial distribution. Keep fixed and let for integers . For each fixed nonnegative integer and sufficiently large ,There are more opportunities, each less likely to succeed, while the mean stays and the variance approaches . For , the probability of three successes is at , at , and at , approaching the Poisson distribution value .
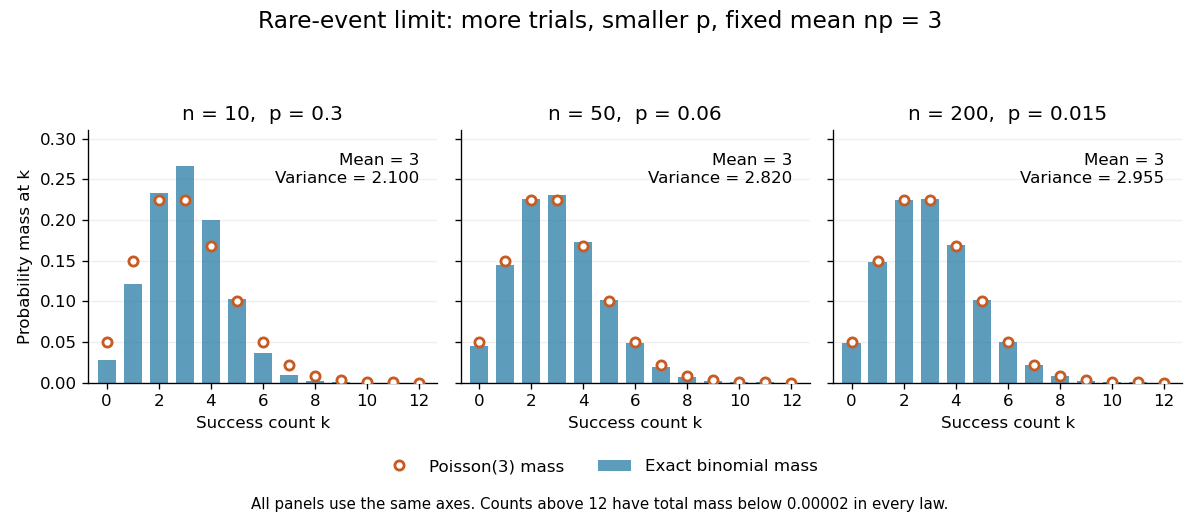
The panels show the same count scale and the same Poisson distribution reference. At , is not especially small and the difference is visible. No universal trial-count cutoff guarantees an adequate approximation for every event.
The independence assumption matters even when every success is rare. For , if all indicator random variables equal one shared Bernoulli random variable of parameter , their sum is zero with probability and with probability . Its mean is three, yet its zero-count probability tends to one, not . Some dependent counts still admit approximation through the Stein-Chen method, but this requires additional control of dependence.
For historical orientation, the BnF records Poisson's original probability treatise, Recherches sur la probabilité des jugements, as published in Paris in 1837. This bibliographic fact alone does not establish when the modern distribution terminology arose. See BnF record of Poisson's 1837 treatise.
When a Poisson distribution is observed in cells , the last cell probability is a tail sum, not the probability of exactly . With and , telescoping derivatives give . Thus an interior maximum-likelihood estimate solves . Substitution of the estimate into these cell probabilities supplies fitted expected counts for a likelihood-ratio test. With cells and one regular fitted parameter, the asymptotic chi-squared distribution has degrees of freedom. Replacing every grouped tail observation by changes the data model and generally does not give the grouped maximum likelihood estimate.
For with , insert its probability mass function into the expected value:The exponential series shows finiteness for every real . Differentiating this moment-generating function gives mean and variance both . Taking the logarithm gives the cumulant-generating function , so every positive-order cumulant is also .
If has a Poisson distribution with parameter , then the ordinary factorial has finite expectation exactly when . Indeed, its nonnegative expectation series is , since cancels the denominator of the probability mass function. The geometric series gives the formula and proves divergence for . This differs from a falling-factorial moment of fixed order, which is finite for every finite Poisson distribution parameter.
The distribution of for independent Poisson random variables with means is the Skellam distribution. Its characteristic function is , its mean is and its variance is . For equal means ,This is the fixed-time law of a symmetric Poisson difference process.
// Target: markov-process.bigb
A mixture of Poisson distributions over a nonnegative random intensity. With exposure and prior density , its probability mass function is . A gamma mixing distribution gives a negative binomial distribution. Counts sharing the same latent intensity are conditionally independent, but generally dependent after mixing.
If has Poisson mean , conditional expectation and the law of total variance give the display. A positive variance of the random mean prevents the unconditional count from being Poisson. For Poisson parents of density and offspring mean , the count in has excess variance , which is positive for a bounded positive-area set and a nontrivial model.
For a mixed Poisson distribution with known exposure , multiply the unnormalized posterior density by and compare its integral with the next probability mass. The factors give the displayed identity whenever . Both mass probabilities have the same exposure . For a future conditionally independent unit-exposure Poisson distribution count, this is also its posterior predictive expected value. It holds for arbitrary proper mixing distributions, with integrals taken against the prior measure when there is no density.
The information entropy of a Poisson distribution is strictly increasing for . Given , take independent and . Their sum has Poisson distribution with mean , so entropy monotonicity under independent addition gives . All these information entropies are finite, and excludes equality.
// Target: probability-and-statistics.bigb
The Stein-Chen method compares an integer-valued count with a Poisson distribution by solving the Poisson Stein equation and estimating its expectation at the count. For sums of indicator random variables, dependency neighborhoods expose local overlap errors. This gives total variation distance bounds without having to compute the entire count distribution.
Let and , where each indicator random variable is independent of all indicators outside jointly. Write and . For a test-event solution of the Poisson Stein equation, independence givesTelescoping each difference and using bounds the total variation distance by that factor times . Directed dependence neighborhoods are allowed. If , the count is identically zero.
For indicators with means , let contain and suppose is independent of the entire family outside . Put , and . The Poisson Stein equation and its bound give the displayed total variation distance estimate. Stronger Stein factors can improve the bound when is large.
For indicator test functions , the equation has a solution with . One proof uses an immigration--death process with immigration rate and per-particle death rate one. Its potential satisfies its generator equation, and . Coupling two additional initial particles bounds the second difference of by .
For with Poisson distribution of mean , the equality proves the identity by summation. For an independent random sum of independent claims with this count, exchangeability of the summands gives , where on the right is independent of and has the severity law. These identities hold for nonnegative measurable functions, and for integrable signed functions. They obtain moments without assuming that a positive exponential moment exists.
A Poisson distribution of parameter conditioned to lie in . It is the occupancy law of a unit-resource loss network. Its mean is the carried load of an Erlang loss resource, . Differentiating the mean with respect to gives its variance, which is positive for and ; this proves strict monotonicity of the carried load.
A model with for a nonnegative random intensity. Conditional expectation and total variance give and , explaining overdispersion. A Poisson-gamma mixture gives the negative binomial distribution.
For a uniform prior distribution on with , conditionally independent Poisson distribution observations have sufficient count . Their Bayesian posterior density is proportional to on that bounded interval. The displayed posterior mean is the Bayes estimator under squared error loss, and is generally not the affine Bühlmann credibility estimate.
When the random intensity is with having an exponential distribution of rate , the mixed count is the sum of independent Poisson distribution and support-zero geometric distribution counts. The Poisson parameter is and the geometric success probability is . At the law is geometric.
For the shifted-exponential Poisson mixture, the displayed relation holds for , initialized by and . It follows by differentiating the probability generating function and comparing coefficients. Nonnegativity follows from the independent Poisson-geometric convolution of independent random variables representation.
For the zero-truncated Poisson distribution, is the unique integrable nonrandomized unbiased estimator of . Indeed unbiasedness gives , and power series coefficients force the parity values. Its variance is ; clipping it to gives mean squared error , strictly smaller for .
The sum of independent Poisson random variables is Poisson, with parameter equal to the sum of their parameters. This follows by multiplying their probability generating functions .
For Bernoulli random variables , which need not be independent, put , , and . ThenThe dependence penalty is the total correlation. The proof compares the joint Bernoulli law with the product of Poisson laws of means , then applies the data processing inequality for relative entropy to addition.
A Poisson observation model represents a nonnegative count as conditionally Poisson with a mean supplied by an underlying process or regression model.
A Poisson observation is an integer-valued count modeled by a Poisson distribution of specified intensity, possibly conditionally on a latent field. Independent Poisson observations motivate Poisson data fidelity through their log-likelihood.
A zero-inflated Poisson distribution is a mixture of a point mass at zero and a Poisson distribution. If the Poisson component has weight and mean , then its mean is and its variance is .
A zero-inflated Poisson regression specifies a structural-zero probability and a susceptible-component Poisson distribution mean . In this parametrization,The mean is . Logistic predictors for and logarithmic predictors for allow covariates to affect component membership and count intensity differently. A susceptible individual can still generate a zero count; susceptibility is not equivalent to an observed positive response.
In a zero-inflated Poisson regression, Bayes' theorem separates structural zeros from susceptible zero counts. A positive count rules out the structural-zero class; a zero raises its posterior probability according to the displayed formula, but usually does not determine class membership with certainty. This same probability supplies the E-step of the EM algorithm for zero-inflated Poisson regression.
A logarithmic count-component contrast multiplies the susceptible mean by , while a zero-logit contrast multiplies the structural-zero odds by . If the baseline zero predictor is , the marginal mean ratio isThus the count ratio alone is not a population-average effect when a covariate changes both components. With interaction terms, the relevant count contrast must first include the interactions for the stated reference group.
The expectation-maximization algorithm introduces for a structural zero. Its E-step gives at positive counts and at zero. The M-step maximizes a logistic log-likelihood with fractional responses and a Poisson log-likelihood with weights . With only a binary predictor, write for group size, and ; the explicit updates are and . Log and logit group contrasts recover the regression coefficients, with boundary values interpreted through limits.
If has a Poisson distribution, then as . The Poisson central limit theorem standardizes by mean and variance ; the cutoff tends to zero. Squeezing between fixed nearby cutoffs and using continuity of the standard normal distribution function gives the limit.
For each group , let independent cell counts have Poisson means . Conditional on their total , the cells have a multinomial distribution with probabilitiesIncluding a free group main effect in the Poisson log-linear model makes its profiled likelihood for the remaining parameters proportional to the corresponding multinomial likelihood. The two fits therefore give the same fitted proportions and likelihood-ratio comparisons.
For positive group totals, the improper prior on an independent Poisson baseline yields the multinomial likelihood kernel after integration. This prior is flat in . A proper finite-variance log-rate prior generally introduces an additional coefficient-dependent factor.
A mean-zero normal distribution prior of variance on the log baseline multiplies the multinomial kernel by the displayed correction, up to a constant independent of coefficients. The factor is not constant in , so the posterior equivalence is approximate. Dominated convergence makes it tend to one as tends to infinity.
Articles by others on the same topic


The Poisson distribution is a discrete probability distribution that expresses the probability of a given number of events occurring within a fixed interval of time or space, assuming these events occur with a known constant mean rate and independently of the time since the last event. It is particularly useful for modeling the number of times an event occurs in a specific interval when the events happen independently.