
Laplace regression Created 2026-09-24 Updated 2026-10-18
For linear regression with fixed predictor vectors , assume conditionally independent responses with a common scale :Each conditional median and mean is . The log-likelihood function is , so maximum likelihood estimation minimizes the sum of absolute regression residuals:This is least absolute deviations. With only an intercept, it reduces to the Laplace location and scale maximum likelihood problem, so a sample median is a fitted intercept. Provided the minimum , the scale estimate is ; the conditional standard deviation is . If the scale is denoted instead of , the conditional standard deviation is .
Minimizing a sum of absolute losses does not automatically give a unique coefficient vector. Even an intercept-only fit to an even sample size can have an interval of solutions, and redundant predictor columns can introduce further nonuniqueness. If a fit makes every regression residual zero, the joint likelihood function is unbounded as , so there is no finite joint maximum-likelihood estimate with positive scale.
The linear growth of absolute loss limits sensitivity to an extreme response at fixed predictors compared with squared-error loss. It does not protect against every outlier: an extreme predictor can have large regression leverage. The numerical example above changes a response in an intercept-only problem, and makes no general claim of immunity to such predictor changes.
Laguerre polynomial Created 2026-09-24 Updated 2026-10-18
Finite Laguerre contour solution Created 2026-09-24 Updated 2026-09-24
A finite contour based at an integrable branch point, or a closed contour around an integer-order pole, gives a solution analytic at . It is therefore a constant multiple of the unique Frobenius power-series solution there.
Binomial-shadow arithmetic lemma Created 2026-09-24 Updated 2026-10-06
Let be the lower-shadow size prescribed by the binomial representation in the Kruskal-Katona theorem. ThenInduction using Pascal's identity proves the inequality and drives the standard ground-set induction for the theorem.
Finite model property of intuitionistic propositional logic Created 2026-09-24 Updated 2026-09-24
Every intuitionistically underivable proposition has a finite rooted Kripke countermodel. Filtration and witness pruning bound the model in terms of the number of subformulas.
Unravelling of a Kripke model Created 2026-09-24 Updated 2026-09-24
Filtration of a Kripke model Created 2026-09-24 Updated 2026-09-24
Kripke completeness theorem for intuitionistic propositional logic Created 2026-09-24 Updated 2026-09-28
A proposition is derivable in intuitionistic propositional logic exactly when it is forced at every world of every intuitionistic Kripke model.
Total length lower bound for a decipherable binary code Created 2026-09-24 Updated 2026-10-14
Kernel density estimation Created 2026-09-24 Updated 2026-10-14
Let be real independent and identically distributed random variables with unknown probability density function , let , and choose a nonnegative, unit-integral kernel for density estimation and a smoothing bandwidth . The kernel density estimator isPlace a bump at every observation and add their contributions. Each bump has area , so for every realized statistical sampleThe change of variables is . Summing the unweighted bumps would give area ; summing just would give area . Those raw sums do not have the normalization of a probability density function.
Unlike a histogram, the construction does not require choosing bin origins, and a Gaussian density kernel gives a smooth curve. Its appeal is that identical local contributions can combine into a probability density function with several peaks without first choosing their number. This makes kernel density estimation useful for exploring an unknown probability distribution and estimating interval probabilities, while the smoothing bandwidth controls how much detail is visible.
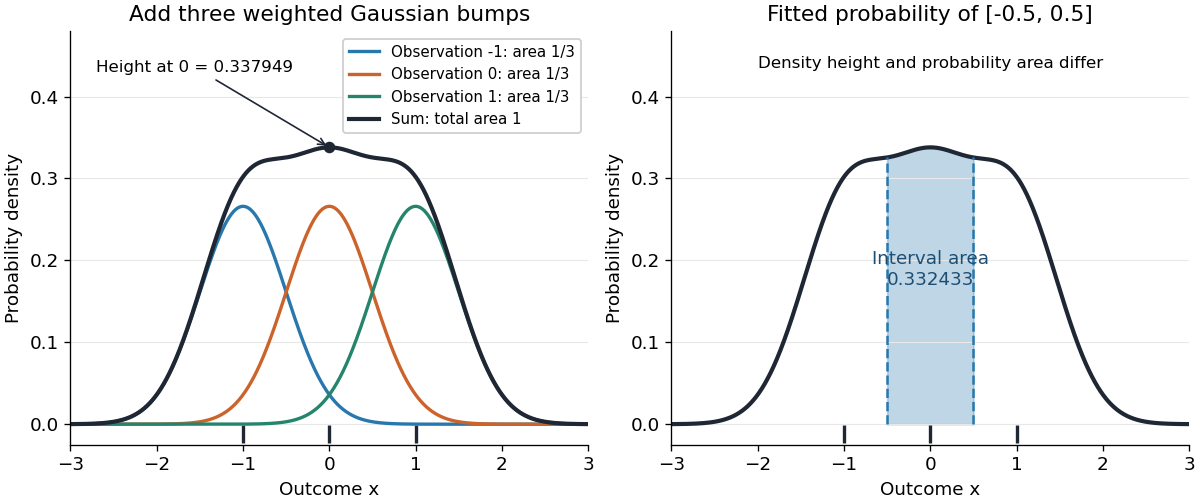

Before the statistical sample is observed, is a random function; afterwards it is a fitted probability density function. It is an estimator of the unknown , not the true probability distribution. For fixed , its expectation is the convolution , generally different from , and repeating the sampling changes the fitted curve. The exact mean integrated squared error of a kernel density estimator separates this smoothing bias of an estimator from sampling variance. Allowing signed kernels of order ell retains the formula but can lose nonnegativity.
Nisan-Szegedy junta theorem Created 2026-09-24 Updated 2026-10-14
Friedgut junta inequality Created 2026-09-24 Updated 2026-09-24
Nonexplosion from recurrent visits to a slow state Created 2026-09-24 Updated 2026-09-24
If the jump chain visits a state of finite holding rate infinitely often, the sum of its independent positive holding times at that state diverges almost surely, preventing explosion.
Invariant-measure transfer between a jump chain and a CTMC Created 2026-09-24 Updated 2026-09-24
For holding rates , a measure satisfies exactly when is invariant for the jump chain. Thus when normalization is possible.
Reflected nearest-neighbour random walk Created 2026-09-24 Updated 2026-09-24
On , let the chain jump from every to with probability and to with probability , and jump from zero to one. It is recurrent exactly when ; at it is null recurrent.
Nilpotent Jordan block Created 2026-09-24 Updated 2026-10-06
Jeans escape flux Created 2026-09-24 Updated 2026-09-24
Jacobian determinant Created 2026-09-24 Updated 2026-10-14
The Jacobian determinant is the determinant of the square Jacobian matrix. Its absolute value is the local volume-scaling factor in the change of variables formula.
The Jacobian matrix and determinant describe respectively the linear derivative and its signed volume factor.
Jacobi convergence for a symmetric positive-definite tridiagonal matrix Created 2026-09-24 Updated 2026-09-29
If is symmetric positive definite and tridiagonal, set . Thenis positive definite. Applying the Householder-John theorem to and proves that the Jacobi iteration converges.
Angular momentum decomposition in three-body Jacobi coordinates Created 2026-09-24 Updated 2026-09-24
There are unlisted articles, also show them or only show them.