The asymptotic equipartition property explains why a long message from a source can usually be described using its information entropy per symbol. Individual messages can have very different probabilities, but the messages carrying almost all the total probability have similar logarithmic costs per symbol. The Bernoulli typical-set example makes the distinction between an individual message and a large collection explicit.
For independent and identically distributed random variables on a finite alphabet, let be their probability mass function and . ThenHere means the probability mass of the realized word, evaluated under the source law. The product rule for independent random variables turns its information content into a sum:The strong law of large numbers gives the limit. Zero-probability symbols do not occur; on the positive-probability support of a finite alphabet, these information costs are finite. The corresponding typical set consists of words whose cost per symbol is within a chosen tolerance of .
For a strictly stationary process with a finite alphabet, the constant-limit extension requires ergodicity. The Shannon-McMillan-Breiman theorem then replaces the one-symbol information entropy with the information rate. Stationarity without ergodicity in an information source shows why stationarity alone is insufficient.[ref]
6.441 Information Theory (Spring 2016 lecture notes) by Yury Polyanskiy and others. §8, Theorem 8.1 and Corollary 8.2, printed p. 90: stationary ergodic sources and typical sets
Take an IID random variable source of bits with . Its binary entropy isA word of length containing ones has probability . Its information content per symbol isThus weakly typical sequences for this biased source have near . With tolerance bits per symbol, the exact condition isFor , this includes exactly . There are words with each count: a type class with that many possible orderings. Summing the counts and their probability masses givesThese are fewer than one percent of the possible words, yet they carry nearly 64 percent of the probability. The most likely individual word is all zeros, with probability ; it is outside this typical set. No contradiction is involved: the type classes near ten ones each contain many more individual words.
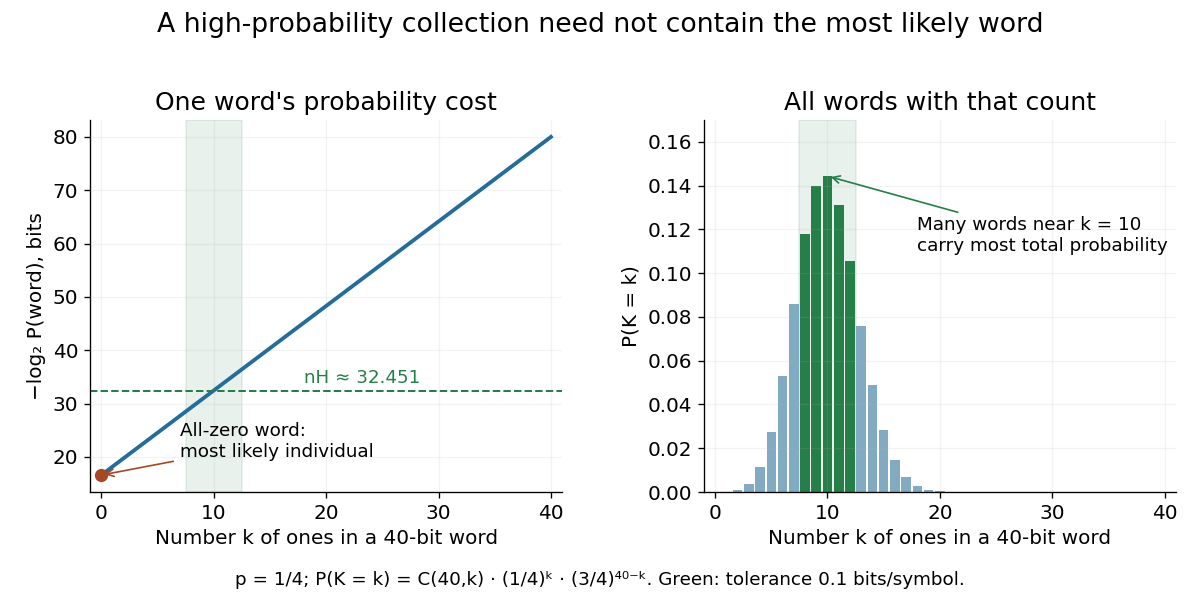
The most likely individual word differs from the counts carrying most probability
. The left plot gives the information content of one word with each number of ones. The right includes the binomial coefficient counting every such word, giving the exact binomial distribution of the count. Both use , ; the green band marks the typical set with tolerance bits per symbol. Details.The count has binomial distribution with mean and variance . The information content per symbol is an affine function of , so its variance isChebyshev's inequality therefore gives the finite-sample lower boundThe bound is often loose, but it proves that every fixed positive tolerance eventually captures nearly all the probability. Direct summation of the binomial distribution's probability masses gives . A finite sample does not need to have a nearly full typical set: the 40-symbol example above captures only about .
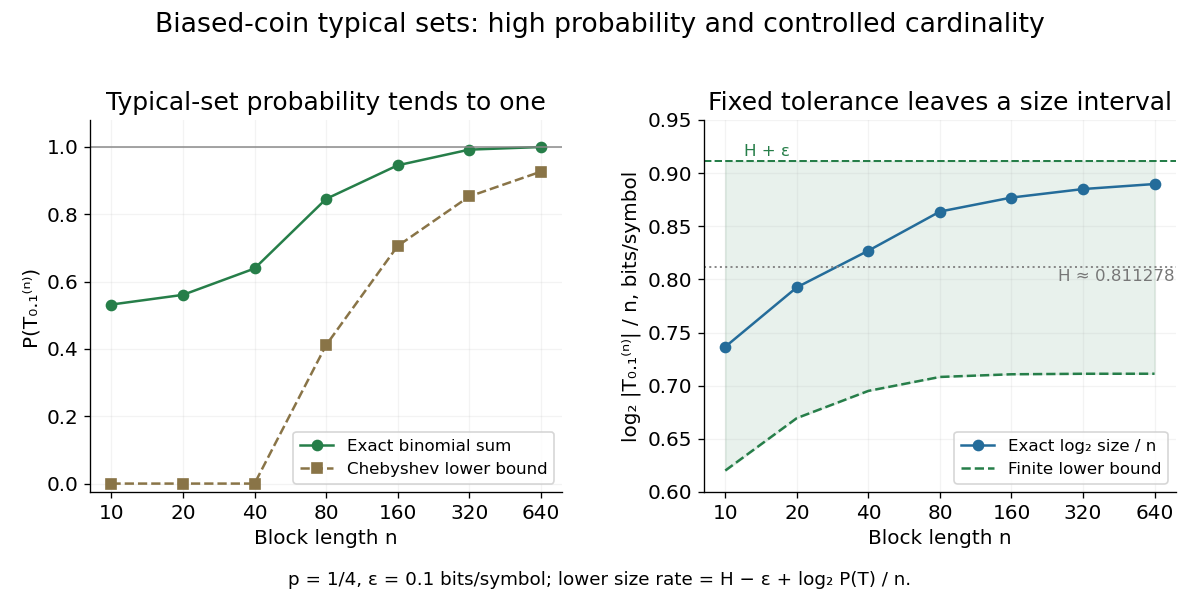
Longer biased-coin messages concentrate in typical sets with controlled size
. The left plot compares exact typical set probabilities with the lower bound from Chebyshev's inequality. The right shows and its finite-sample bounds. The tolerance stays fixed; the curve is not asserted to converge to exactly . All points are exact finite-model calculations. Details.The typical sequence theorem turns a probability concentration into a coding construction. Assign one binary number index to each weakly typical sequence, plus a reserved index for every word outside the set. The decoder recovers every typical word exactly; the reserved index has one predetermined output. The block code usesbits and has reconstruction-error probability at most .
For this example and , needs 34 bits but permits error up to about . At , 570 bits suffice and the error bound is about . These are existence calculations for an explicitly enumerated collection, rather than claims about an efficient practical encoder. The reduction comes from protecting the whole high-probability collection, rather than just its single most likely member.
Choose one of two regimes once, with equal probability: a source of independent and identically distributed random variables with one-bit probability , or one with one-bit probability . Keep the chosen regime forever. The resulting source is a strictly stationary process, because shifting a block does not change either component law. It is not an ergodic stationary process: its limiting empirical frequency identifies the regime.
The source's information rate isConditioning on the single regime bit changes any block's information entropy by at most one bit, so dividing by the block length proves this rate. However, the limiting realized information content per symbol is approximately in the first regime and one in the second. The alternative component's likelihood ratio decays exponentially along a typical path from the chosen component, at a rate given by the positive relative entropy between the two Bernoulli distributions. The mixture therefore has two possible pathwise limits, not one limit equal to the averaged information rate.
In A Mathematical Theory of Communication by Claude Shannon (1948, section 7), Claude Shannon explains that the common symbol counts in a long independent message make its negative logarithmic probability approximately the message length times the source entropy. Theorem 3 separates an exceptional collection of small total probability from messages with this normalized information cost; Theorem 4 relates the number needed to accumulate a fixed probability to the entropy. The finite-state source setting matters to the historical statement.[ref]
For an IID source, the epsilon-typical set consists of words satisfying . Its probability tends to one, and its cardinality is at most .
Let be the weak typical set of a finite alphabet independent and identically distributed source with Shannon entropy , and let be any sets with . The asymptotic equipartition property and union bound give . Every word in the intersection has probability mass between and . Summing these bounds givesFor every fixed , the first probability eventually exceeds , proving the title bound. A sample mean within a fixed positive tolerance of the expected value supplies by the strong law of large numbers.
For a memoryless classical information source, the typical set consists of positive-probability words with . The weak law of large numbers applied to proves its probability tends to one. Every typical word has probability between and . Summing the lower bound gives the displayed cardinality upper bound; if the set has probability at least , summing the upper bound gives cardinality at least .
To compress at any rate , choose , assign one fixed-length binary index to each typical word, and reserve one additional index for all atypical words. At most bits suffice for all large . Decoding inverts the typical-word indices and makes an arbitrary output for the reserved index. The reconstruction error is at most the probability of the atypical set and tends to zero.
For an IID random variable source with probability mass function , a word is weakly typical when . It has probability on the scale . The weak law of large numbers makes the typical set probable, but does not make every word in it representative: for a uniform source every possible word is weakly typical.
For a typical set of probability at least ,The upper bound sums the lower probability bound for each word; the lower bound sums the upper probability bound and uses the set's total probability. These bounds turn the asymptotic equipartition property into exponential estimates of source-coding dimension.
For a finite-alphabet IID source and fixed , the smallest set of length- strings carrying probability at least has size . The typical set bounds give the upper estimate. For the lower estimate, any such set intersects the typical set in probability bounded away from zero, while each typical string has probability at most .
// Target: probability-and-statistics.bigb
For a finite-alphabet IID random variable source, a strongly typical word has empirical symbol frequencies within the chosen tolerance of every , and contains no zero-probability symbols. Unlike a weakly typical sequence, this definition controls the individual symbol counts. Both definitions give sets whose probability tends to one for fixed positive tolerance.
Articles by others on the same topic



The Asymptotic Equipartition Property (AEP) is a fundamental concept in information theory that describes the behavior of large sequences of random variables. It essentially states that for a sufficiently large number of independent and identically distributed (i.i.d.) random variables, the joint distribution of those variables becomes concentrated around a typical set of outcomes, which have roughly the same probability. Formally, if \(X_1, X_2, \ldots, X_n\) are i.