Solutions to all six questions of the 12 December 2019 Statistics Core examination. Oxford examination release ZIP, member
Digital Social Research Statistics Core/2019 Michaelmas a14564w1.pdf. All seven numbered figures and the unnumbered output for Question 1 are available. The printed group means and overall mean in Question 1 cannot describe one complete sample; that inconsistency is kept explicit. Calculations below use the supplied summaries and counts, without inventing individual records.Conditional on the printed two-group test output, the male-coded group has higher mean efficacy by about 1.034 scale points, with a 95% confidence interval of about 0.785 to 1.282 points. This is strong evidence against equal population means under the test's assumptions. It does not establish a causal effect, and the accompanying overall mean is inconsistent with the group summaries.
Here the coding identifies group 0 as male and group 1 as female in this dataset. The counts are 1215 and 1251, respectively, or approximately 49.27% and 50.73% of 2466 observations. These are sample compositions, not evidence that the sample represents every population of interest. The continuous efficacy scale runs from 0 to 16, with higher scores indicating stronger efficacy. Its printed sample median is 10 and its quartiles are 8 and 12, so its interquartile range is 4 points. The printed overall sample mean, 9.348, requires the separate consistency qualification below.
Let and denote the two population means. The null hypothesis is , and the alternative hypothesis is the two-sided test . The two sample means giveThe positive sign means higher mean efficacy in group 0, given this coding; it does not say that every member of that group has higher efficacy than every member of group 1.
Welch's t-test estimates uncertainty from the two groups separately rather than assuming equal population variances:The printed implies a standard error of approximately points. The noninteger 2277.4 statistical degrees of freedom comes from the Welch approximation; it is not a count of fractional observations. Using the corresponding Student t-distribution gives the displayed p-value, approximately . The test and interval calculations agree to the precision of the printed numbers.[ref]
Student's t-Test in the R documentation. Arguments and Details: two-sided default and unequal-variance Welch calculation; Value: estimates, statistic, degrees of freedom and interval
A p-value is the probability, under the null hypothesis and the assumed sampling model, of a test result at least as incompatible with equal means as the observed result. It is not the probability that the null hypothesis is true, the probability that the finding is a chance mistake, or the size of the mean difference. At a prespecified significance level such as , this result rejects the equal-mean null hypothesis; it also rejects at 1%. A Type I error is rejection when that hypothesis is true, and a valid level- procedure controls its long-run probability. A Type II error is failure to reject a false hypothesis; statistical power is the probability of rejection under a specified alternative. Neither error probability for this one realized claim is supplied by its p-value.
The 95% confidence interval comes from , with critical value about 1.961. Its positive endpoints support the same direction and exclude zero. The frequentist 95% statement concerns coverage over repeated samples, not a 95% posterior probability assigned to this fixed interval. Reporting the difference in scale points supplies an effect size; its practical importance also depends on what a point means substantively. A very small p-value alone does not answer that question.
The inferential calculation requires independent observations and an appropriate sampling model. With these large groups, approximately normal sampling distributions of the means can be more plausible than normality of individual bounded scores, but a large sample size does not correct dependence, clustering, selection bias or measurement problems. The output does not establish random assignment or remove possible confounding, so the estimated difference is an association.
There is a material source inconsistency. For exhaustive groups with complete outcome data, the sample mean must be the sample-size-weighted mean of the group means:which cannot round to 9.348. Figure 7 independently reports all 2466 efficacy values present and again gives 9.348; Question 6 refers back to the same continuous scale. The pooled-mean compatibility under rounding rules out explaining the discrepancy by the displayed decimal precision. Thus the two-group test supports the stated conclusion if its own group summaries and test fields are trusted, while the overall mean cannot simultaneously be accepted as a coherent summary of those groups. No unprinted exclusion or uniquely correct replacement mean is established.
All three frequency tables describe 2466 valid observations with no reported missing values. The sample is overwhelmingly White, Medium is the most common efficacy category, and disagreement with the technology-failure statement is more common than agreement. These statements describe the sample rather than establish population composition or causal relationships.
In a frequency table, a count gives the number of observations in a category, and a percentage divides that count by the full sample total. A valid percentage instead uses the total with an observed value of that variable. Here the two denominators coincide because every table reports zero missing values. A cumulative percentage adds categories in the displayed order; its substantive meaning depends on whether that order is meaningful.
The ethnicity counts are 77 Asian, 57 Black and 2332 White respondents, or 3.12%, 2.31% and 94.57%. Ethnicity is a nominal categorical variable: the displayed order is not a low-to-high ethnic scale. Its cumulative percentages are bookkeeping for that listing rather than an interpretable ranking. The two minority groups are small relative to the White group, which will matter for the precision and expected cell counts of the stratified comparisons.
For the three-category efficacy measure, 908 observations are High, 972 Medium and 586 Low, giving 36.82%, 39.42% and 23.76%. Medium is the mode, and 76.24% fall in the combined High-or-Medium categories. This is an ordinal categorical variable, but the table does not imply equal numerical distances between categories. Its order is descending efficacy, High then Medium then Low. Therefore the cumulative 76.24% refers to that upper portion of the scale, not to the proportion at or below Medium under an ascending convention. The cutpoints used to form these categories are not supplied and need not be invented to interpret their frequencies.
For
techfail_chr, 336 strongly disagree, 922 disagree, 490 are neutral and 718 agree: 13.63%, 37.39%, 19.87% and 29.12%. The wording concerns not trusting technology because it fails when needed. Thus moving toward Agree means more distrust, not more trust. Combining the two disagreement categories gives , versus 29.12% agreement and 19.87% neutrality. Adding the separately rounded displayed percentages gives 51.02%; the difference is ordinary rounding error. There is no displayed strongly-agree category, so its frequency cannot be inferred or added to the agreement count.The technology percentages add to 100.01%, including the printed valid-total figure. The integer counts still sum exactly to 2466; rounded percentages need not sum exactly to 100%. Finally, three separate univariate frequency tables say nothing by themselves about which efficacy categories the trusting or distrusting respondents occupy. That requires the joint information in the later contingency tables.
Greater technology distrust is associated with lower efficacy in the overall sample. The omnibus evidence against independence is strong, while the unsigned association magnitude is modest: on 6 statistical degrees of freedom, and Cramér's V about 0.148. The observational study does not establish that changing trust would cause efficacy to change.
Rows identify the technology response and columns identify efficacy. Each body percentage is a within-row conditional probability estimate, not a column percentage. For example, of those who strongly disagree with the distrust statement have High efficacy, whereas of those who agree do. The difference is about 21.69 percentage points. High efficacy decreases across all four rows: 49.40%, 42.41%, 31.02%, 27.72%. Low efficacy is 20.54% in the strongly-disagree row, 18.00% in Disagree, 21.43% in Neutral and 34.26% in Agree. Thus the overall pattern is clear without claiming that every category changes monotonically: the low-efficacy proportion initially falls, and the Medium proportion peaks at 47.55% among neutral respondents.
For the Pearson chi-squared test of independence, the null hypothesis says that the two categorical variables are independent, equivalently that the efficacy distribution is the same in every technology-response row. With row totals and column totals , the expected frequency under that hypothesis is , andAll twelve expected frequencies exceed 79, with minimum about 79.844, so sparse expected cells are not the concern here. Under independent sampling and the usual large-sample calibration, the very small p-value rejects independence at conventional significance levels. This is an omnibus finding: it does not provide a separate adjusted significance test for every pair of row percentages.[ref]
Pearson's Chi-squared Test for Count Data in the R documentation. Details: product-marginal null hypothesis and asymptotic chi-squared calibration
The likelihood-ratio test of independence in a contingency table uses . The supplied with 6 statistical degrees of freedom gives . Its displayed 0.000 is rounded, not an exact zero. It corroborates the omnibus finding. The generalized phi coefficient is , the contingency coefficient is about 0.205, and Cramér's V is . These are unsigned measures of association strength rather than three additional significance tests; they do not describe causal effects or percentages of variance explained. Their magnitude and the small p-value answer different questions, especially with a large sample size.
The ordinal measures use the displayed order: increasing row index means increasing distrust, while increasing column index means decreasing efficacy. There are 882033 concordant pairs and 552543 discordant pairs. Hence Goodman and Kruskal's gamma isIts positive sign therefore means that increasing distrust tends to accompany movement toward lower efficacy. Under an ascending efficacy order its sign would be negative, by sign reversal under reversal of one ordinal ordering. Goodman and Kruskal's gamma ignores tied pairs; it is not a claim that 23% of efficacy variation is explained. The displayed pair counts partition all unordered pairs correctly, including ties. Somers' D for efficacy given technology is about 0.151, Kendall's tau-b about 0.158, and Stuart's tau-c about 0.163. Their different denominators handle ties or table dimensions differently, so their differing magnitudes do not constitute disagreement about the direction.[ref]
DescTools documentation for gamma, Somers' D and lambda. GoodmanKruskalGamma and SomersDelta, Details: tied-pair exclusions and the directional denominator
[ref]Ordinal association measures in the DescTools documentation. KendallTauB and StuartTauC: tie and table-size adjustments
Goodman and Kruskal's lambda concerns the proportional reduction in errors when predicting a most frequent category, not ordinal movement. Without technology information the modal efficacy category is Medium, producing errors. Choosing a separate modal efficacy category in each technology row yields errors. Thus . In the reverse prediction direction the reduction is , matching the other printed lambda. The improvement in modal classification is small even though independence is decisively rejected. Both the conditional percentages and these distinct summaries support a real sample association; ethnicity and other possible confounders still require attention before any causal account.
There are descriptive ethnic differences in the distribution of technology distrust, but the omnibus evidence is borderline and the unsigned association is small. The printed Pearson test just rejects independence at 5%, while the likelihood-ratio test does not; neither establishes a strong ethnic pattern or a causal effect.
Read the body percentages within each ethnic group. Strong disagreement with the distrust statement occurs among 24.68% of Asian respondents, 10.53% of Black respondents and 13.34% of White respondents. Agreement occurs among 27.27%, 21.05% and 29.37%, respectively. Neutral responses are 20.78%, 26.32% and 19.68%. Thus Asian respondents are especially likely to be in the strongly-disagree category, while Black respondents have the largest neutral share. The mode for Black and White respondents is Disagree; Asian respondents have a tie between Disagree and Agree at 21 observations each. The small group totals, 77 and 57, mean that a few observations can materially change the minority-group percentages.
The Pearson chi-squared test of independence has , statistical degrees of freedom and . Under its sampling assumptions, this is a nominal rejection at a prespecified 5% significance level, but not at 1%. The minimum expected frequency is about 7.766, so this particular table has no expected cell below five. The alternative likelihood-ratio test of independence in a contingency table gives and , printed as 0.074. These are different test statistics, not contradictory versions of the same calculation. Their different threshold decisions show that the evidence is close enough to the conventional boundary to warrant qualification rather than selection of the more favourable label.
The generalized phi coefficient is about 0.071, the contingency coefficient about 0.071 and Cramér's V about 0.051. They indicate a small overall unsigned association. This does not erase the particular descriptive percentage differences, and a small p-value is not a measure of their substantive size. Conversely, failure of the likelihood-ratio test to reject at 5% is not evidence that every ethnic group has exactly the same population response distribution.
Ethnicity is a nominal categorical variable, with no natural rank Asian–Black–White. Therefore the printed Goodman and Kruskal's gamma of 0.079, Somers' D of 0.058, Kendall's tau-b of 0.022 and Stuart's tau-c of 0.009 have no invariant substantive ordinal interpretation here. Permuting the ethnicity labels can change the ordinal pair comparisons without changing the underlying observations or their nominal association. These values are not evidence for an ethnic hierarchy; Cramér's V and the actual within-group percentages are appropriate summaries for this question.[ref]
DescTools documentation for gamma, Somers' D and lambda. GoodmanKruskalGamma and SomersDelta, Details: ordinal-scale requirement
Both directional values of Goodman and Kruskal's lambda are zero. Knowing ethnicity does not improve the number of correct modal predictions of technology response: Disagree remains a modal category within every ethnic group, including the Asian tie. In the reverse direction, White is the most frequent ethnicity within every technology-response column, so knowing technology does not improve modal ethnicity predictions either. Zero lambda therefore coexists with unequal conditional distributions and a nonzero Pearson chi-squared statistic; modal prediction discards changes that do not change the most frequent category. The supported conclusion is a small, weakly evidenced nominal association, with its descriptive pattern and uncertainty stated explicitly.
The White stratum retains the overall distrust–lower-efficacy pattern, the Asian stratum shows a stronger but irregular version of it, and the Black stratum has an opposite descriptive ordinal direction. This supports replication in the dominant stratum together with possible specification by ethnicity in the elaboration model. Sparse minority tables and different significance labels do not by themselves establish a population statistical interaction.
Each table fixes ethnicity and compares the efficacy conditional distributions across technology responses. The body percentages use the technology-response row total within that stratum. The same labels, coding direction and efficacy order apply as before. The strata contain 77, 57 and 2332 observations; they sum to 2466 and their cells reproduce the overall table exactly. Consequently the comparison is genuinely a stratification of the supplied overall counts, rather than a comparison of unrelated samples.
For Asian respondents, High efficacy is 78.95% among those who strongly disagree with the distrust statement, falling to 23.81% among those who disagree, 18.75% among neutral respondents and 19.05% among those who agree. The strong-disagreement versus agreement contrast is about 59.90 percentage points, based on 15 of 19 versus 4 of 21 respondents. This is a large descriptive contrast, but the rest of the table is not a simple monotone progression: Low efficacy peaks at 47.62% in Disagree, versus 10.53% in Strongly disagree, 18.75% in Neutral and 23.81% in Agree; Medium efficacy exceeds 57% in the last two rows. The striking first row is part of a more irregular categorical pattern.
The Asian Pearson chi-squared test of independence gives , 6 statistical degrees of freedom, . The likelihood-ratio test gives , ; its displayed 0.000 is a rounding convention. Cramér's V is about 0.430, compared with 0.148 overall. The generalized phi coefficient is 0.608 and the contingency coefficient 0.519. Two of twelve expected frequencies are below five, with minimum 4.156. This is a modest sparse-cell warning rather than a reason to delete the observed cells, but asymptotic calibration should still be qualified and could be checked by an exact or fixed-margin Monte Carlo test.
The Asian Goodman and Kruskal's gamma is about 0.323, from 1025 concordances and 524 discordances, so its displayed-order direction agrees with the overall association. Somers' D for efficacy given technology is about 0.226, Kendall's tau-b 0.241 and Stuart's tau-c 0.253. These stronger ordinal summaries do not imply that every individual row transition is monotone. Goodman and Kruskal's lambda is about 0.362 for predicting efficacy from technology and 0.286 in the reverse direction: the technology row changes the modal efficacy prediction sufficiently to reduce its errors by about 36.2%. This is a reduction in modal-classification errors, not a fraction of efficacy variance explained.
For Black respondents, High efficacy is 0 of 6, or 0%, in Strongly disagree; 8 of 24, or 33.33%, in Disagree; 2 of 15, or 13.33%, in Neutral; and 7 of 12, or 58.33%, in Agree. Low efficacy is 16.67%, 25.00%, 20.00% and 8.33%, respectively. The strongest-disagreement versus agreement High-efficacy contrast is therefore percentage points, opposite to the Asian and White contrasts. The zero observed High count in the first row does not prove zero population probability, especially with only six respondents in that row. These percentages are compatible with a reversed tendency, but considerable sampling uncertainty is unavoidable.
The Black Pearson chi-squared test of independence gives , 6 statistical degrees of freedom and . The likelihood-ratio test gives , , also above 5%. Thus neither nominal test rejects at 5%; this does not establish exact independence. Eight of twelve expected frequencies are below five, with minimum about 1.158, making the usual large-sample calibration particularly questionable. An exact conditional analysis or Monte Carlo test would be more defensible for a calibrated inferential claim; no uncomputed simulated p-value is asserted.[ref]
Pearson's Chi-squared Test for Count Data in the R documentation. Details: fixed-margin sampling for simulated contingency-table tests
The Black Cramér's V is about 0.308, the generalized phi coefficient 0.435 and the contingency coefficient 0.399. An unsigned magnitude of this size can coexist with a nonsignificant test in a small sample. There are 254 concordances and 457 discordances, giving Goodman and Kruskal's gamma about , Somers' D about , Kendall's tau-b about and Stuart's tau-c about . Their negative signs agree with the reversed displayed-order direction. Goodman and Kruskal's lambda is about 0.107 for efficacy given technology and zero for technology given efficacy. In the latter direction, Disagree remains a modal technology category within every efficacy column, so modal prediction gains nothing despite the changed conditional percentages.
For White respondents, High efficacy decreases from 48.55% in Strongly disagree through 43.10% and 32.03% to 27.45% in Agree. The extreme-row contrast is about 21.11 percentage points, from 151 of 311 versus 188 of 685. Low efficacy is 21.22%, 17.10%, 21.57% and 35.04%, respectively. This closely resembles the overall distribution, including the fact that the Low category is not monotone at every step. The White Pearson chi-squared test of independence gives , 6 statistical degrees of freedom and ; the likelihood-ratio test gives , . All expected frequencies exceed 74, so sparse cells are not the problem for these nominal tests.
The White Cramér's V is about 0.152, the generalized phi coefficient 0.215 and the contingency coefficient 0.210. Goodman and Kruskal's gamma is about 0.236, Somers' D 0.155, Kendall's tau-b 0.162 and Stuart's tau-c 0.167: close to the overall ordinal summaries and in the same direction. The two values of Goodman and Kruskal's lambda are about 0.061 for efficacy given technology and 0.062 for technology given efficacy. They again indicate only a small improvement in modal prediction. The large sample size helps explain why the White test has a much smaller p-value than the smaller strata, without implying that its association magnitude is the largest.
The original figure below plots selected empirical conditional probabilities from all the cells. It gives the opposite small-stratum pattern and the dominant White pattern a common scale; it is not a reproduction of a source figure, an estimated continuous trend or a display of uncertainty intervals.
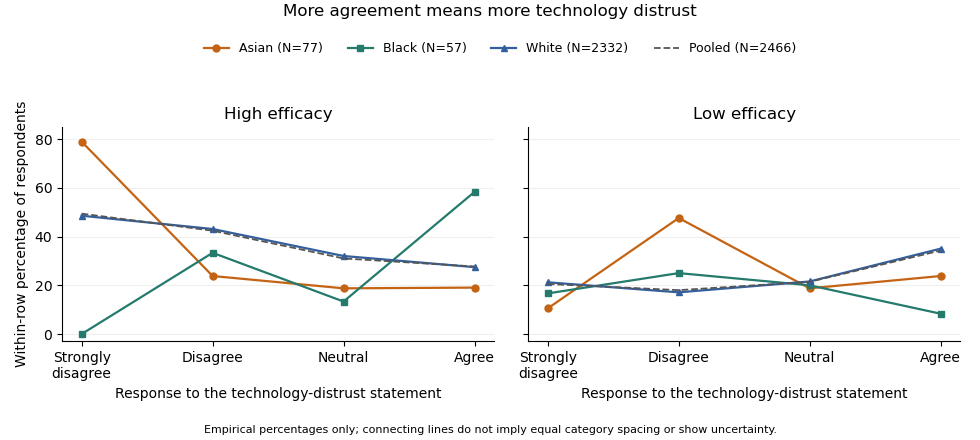
Efficacy distributions across technology-distrust responses: contrasting ethnic strata and the pooled sample. Lines only connect the four ordered categories; group sizes and sparse cells limit inference.
Details. 
The elaboration model asks how the original association changes when a third variable is held fixed. If the association disappeared throughout the strata, an explanation by the control variable might be plausible, subject to a credible causal ordering. Here it persists in the White group, which supplies 94.57% of the sample, and is stronger on several descriptive measures in the Asian group. Therefore ethnicity does not simply explain away the relationship. The White result is a replication of the broad pattern; the reversed Black direction and the Asian shape suggest descriptive specification or possible effect modification. The output supplies no temporal or causal design that would distinguish an actual causal mechanism from other confounding, measurement differences or sampling variation. It also does not demonstrate a Simpson's paradox in which the association reverses in every stratum: that is not what the displayed tables show.
The predominance of White respondents explains why the pooled pattern resembles theirs. By the law of total probability, each technology row's efficacy distribution is a mixture over ethnicity, using the ethnic proportions within that technology row. Those weights need not equal the overall ethnic proportions. As an optional descriptive comparison, standardization with common weights using the overall ethnic shares gives High-efficacy proportions of about 48.38% in Strongly disagree and 27.90% in Agree, a 20.48-percentage point contrast, compared with the crude 21.69-point contrast. This explicitly defined adjustment leaves the broad contrast intact; it is not a causal estimate and does not turn the three different stratum patterns into one common effect.
Finally, a significant test in one group and a nonsignificant test in another is not itself a test that the groups' associations differ. A formal statistical interaction requires a directly specified heterogeneity test or model on a chosen effect scale. The omnibus tests also address whole categorical distributions, whereas gamma and the High-efficacy contrast describe particular ordered features. Multiple stratum tests create a multiple testing issue if used to select a discovery. The defensible result is an association that survives stratification in the dominant group, with important descriptive heterogeneity that merits a direct, sparse-cell-aware investigation rather than an assertion that ethnicity causes the difference.
The fitted age slope is very small and negative, about efficacy points per year, with no conventional evidence against a zero linear slope: , . The model explains only about 0.0367% of the observed efficacy variation. These results concern a linear association, not proof of no possible age relationship or a causal effect of ageing.
The descriptive statistics report 2466 observed ages and efficacy scores, with no missing values for either variable. Age ranges from 14 to 97 years, with sample mean 52.689 years and sample standard deviation 19.064 years. Efficacy ranges from 0 to 16, with sample mean 9.348 and sample standard deviation 3.176 scale points. The standard deviations use different units and should not be compared as though their numerical ratio measured relative substantive variability. The efficacy mean retains the conflict with Question 1's group summaries; that conflict is not resolved by this separate regression output.
A simple linear regression models , where is efficacy and is age in years. Ordinary least squares chooses the coefficients to minimize the residual sum of squares. From the printed coefficients the fitted line isHolding to this model, ten additional years correspond to fitted scale points. For example, the fitted mean is about 9.453 at age 20 and 9.261 at age 80, a difference of about points. These are fitted means, not exact predictions of individual scores. The line does not imply that every person's efficacy falls at that rate, nor that cross-sectional age differences identify within-person changes over time.
The intercept is the predicted mean at age zero, about 9.517. Since zero is outside the observed 14–97 age range, its direct interpretation requires extrapolation. The printed standard error of 0.188043 and yield the extremely small displayed p-value for a zero intercept. That test does not test whether age is a useful predictor. Recentring age at its observed sample mean would put the intercept near , the fitted mean at a substantively relevant reference age. This agrees with the rounded overall efficacy mean.
The age standard error is 0.003356 points per year. The coefficient divided by this standard error gives , agreeing with the printed t value. Estimating an intercept and one regression slope from 2466 observations leaves residual statistical degrees of freedom. Under a correctly specified normal linear model, the Student t-distribution provides the stated two-sided p-value. At 5%, or 1%, it does not reject . The p-value is not a 34.2% probability that age has no effect, and nonrejection does not establish a practically negligible effect size.[ref]
Summarizing Linear Model Fits in the R documentation. Value: coefficient estimate, standard error, two-sided t and p columns; residual degrees of freedom
A 95% confidence interval calculated from the printed estimate and standard error is approximatelyor about points per decade. It includes zero and gives the scale of slopes compatible with these summaries and assumptions. Assessing a practically negligible effect would require an explicit substantive tolerance and an appropriate equivalence test, not simply the fact that . A nonlinear association could also coexist with a near-zero overall linear slope.
The coefficient of determination is , meaning that the fitted line explains about of the sample's centred efficacy sum of squares compared with an intercept-only fit. This is not 36.7%, a fraction of people whose efficacy is predicted correctly, or the proportion of efficacy caused by age. The adjusted coefficient of determination, approximately , is slightly negative because its penalty for estimating the extra coefficient exceeds the tiny improvement in fit. It need not be constrained to be nonnegative and does not mean a negative amount of explained variation.
The overall on 1 and 2464 statistical degrees of freedom, with , tests the same zero-slope hypothesis as the age t test because there is only one predictor. The simple-regression output identities give and ; the printed numbers agree allowing their displayed precision. The signed Pearson correlation coefficient is consequently about . These are related summaries of the same weak linear association, not independent corroborating tests.
The residual standard error of 3.177 points estimates the typical unexplained error scale under the fitted model. It is close to the efficacy sample standard deviation, as expected when the line explains almost none of the variation. It is not a standard error of the slope or a guarantee that each individual's prediction error lies within 3.177 points. The residual summary spans roughly to , with sample median about 0.573 and central quartiles about and . An ordinary least-squares fit with an intercept has zero mean residual, not necessarily zero median residual. These few quantiles cannot establish normality, constant conditional spread, absence of outliers or linearity. The apparent last-decimal discrepancies among rounded error scales and other summary fields do not force an additional contradiction: their rounding intervals admit compatible regression summaries.
The conventional uncertainty calculations assume independent, mean-zero errors conditional on age, an appropriate linear mean, and homoscedasticity; normal errors give the usual exact finite-sample t and F calibration. Large samples can relax some distributional requirements but do not remove confounding, selection bias or dependence. A residual-versus-fitted plot could reveal curvature or changing spread, and a normal probability plot could assess error shape; neither plot can be reconstructed from the printed residual quantiles. A prediction interval for an individual includes residual variation and is wider than a confidence interval for the mean response. The supplied output supports a very weak, imprecisely signed linear association with little predictive gain from age alone, while leaving nonlinear, causal and design-based questions unresolved.
Articles by others on the same topic
There are currently no matching articles.