The Gram-Schmidt process turns a finite ordered family of linearly independent vectors in an inner product space over the real numbers into an orthonormal basis of their linear span. It keeps every successive linear span, so the first new vectors describe exactly the same directions as the first inputs. Its idea is geometric: remove the orthogonal projection onto directions already found, then divide the remaining vector by its norm. This makes a complicated basis easier to use without changing the vector subspace it describes.[ref]
Start with and . At step , use the previously obtained orthonormal set to defineThe sum is the orthogonal projection onto a finite-dimensional subspace , and is the orthogonal projection residual. Linear independence ensures : otherwise would already be a linear combination of earlier inputs. If the input family is linearly dependent, use only the retained orthonormal vectors in the sum and omit an input whenever its remainder is the zero vector; do not divide by zero. The retained outputs still form an orthonormal basis of the original linear span, but their number can be smaller than .
For a short verification, orthonormality makes every earlier inner product vanish:Also is minus a linear combination of earlier vectors, while is plus that same linear combination. These two inclusions, followed by division by a nonzero norm, giveThe argument also works in an inner product space over the complex numbers with the existing inner product convention, linear in the first argument: the coefficients remain . With the convention linear in the second argument, write instead.
For a first picture, take and in with the ordinary dot product. ThenSubtracting the diagonal component leaves an orthogonal direction; dividing by its norm makes its length one. If the second input were instead, its orthogonal projection would be the entire input and , revealing linear dependence.
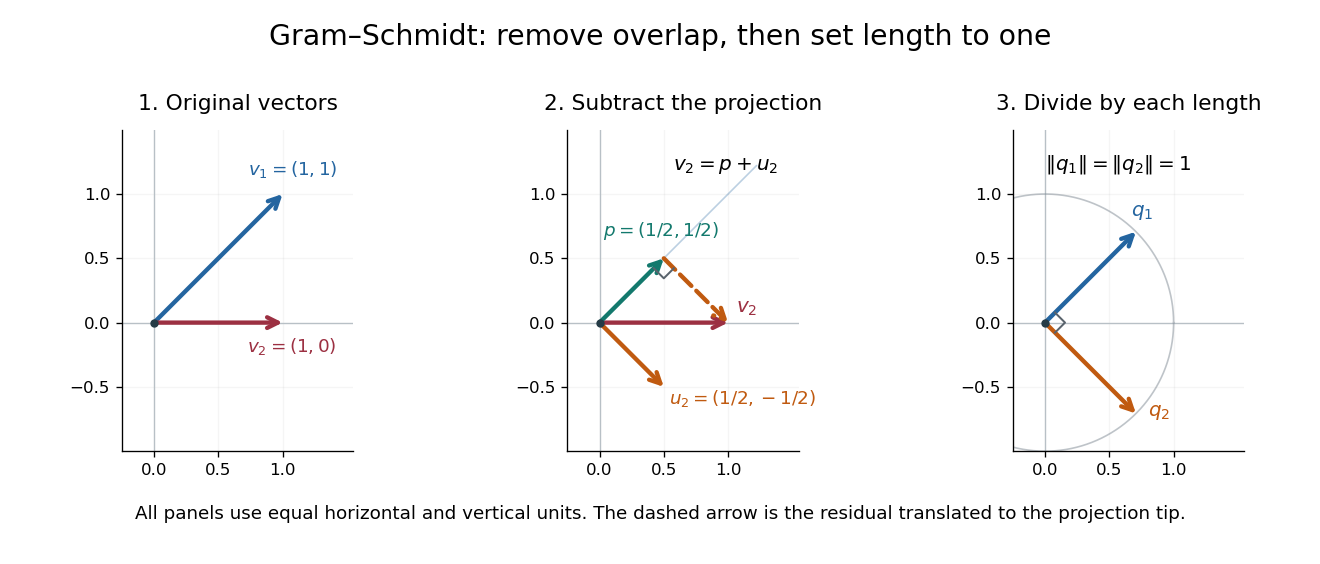
Gram-Schmidt orthogonalization in : input vectors, subtraction of an orthogonal projection, and an orthonormal basis
. Details. For a full three-dimensional calculation, use the ordinary dot product and the input vectorsThe first two steps giveAt the third step, the inner products are and . ConsequentlyThe three numerator vectors have pairwise dot products and squared Euclidean norms . Thus the displayed outputs are indeed an orthonormal basis, and the three nonzero remainders also confirm linear independence of the inputs. Keeping the removed coefficients produces the QR decomposition below.
An immediate reward is a reusable orthogonal projection: once an orthonormal basis of a vector subspace is known, any vector hasFor the linear span of just the first two inputs in the three-dimensional example, gives . Its orthogonal projection residual is , visibly in the missing orthogonal direction. This is the geometry behind the linear least-squares problem.
The formulas above describe exact arithmetic. With floating-point arithmetic, subtracting an orthogonal projection nearly equal to the input can leave a small remainder; dividing by its small norm can magnify existing roundoff error. The Classical Gram-Schmidt and Modified Gram-Schmidt arrangements agree in exact arithmetic but can give different rounded results. Exact linear dependence and a small computed remainder therefore require different judgments in a numerical implementation.[ref]
https://nhigham.com/wp-content/uploads/2023/10/high95m.pdf. Higham, The Test Matrix Toolbox for Matlab, §8, p. 22
For a linearly independent ordered family in a real inner product space, require each unit vector to lie in the span of the first inputs and be orthogonal to all earlier inputs. That orthogonal part of the successive span is one-dimensional. Subtracting the earlier orthonormal components gives its nonzero generator . Every possible unit choice is therefore . Since , the positive normalization fixes the sign uniquely. This distinguishes uniqueness of the normalized ordered construction from the many possible orthonormal bases of the whole space.
Classical Gram-Schmidt computes all orthogonal projection coefficients from the original input , then subtracts their sum as in the displayed Gram-Schmidt process formula.
Modified Gram-Schmidt starts with and, for each retained orthonormal vector in order, replaces by . Each orthogonal projection coefficient uses the current remainder. In exact arithmetic, subtracting earlier orthogonal directions does not change the inner product with , so the final equals the Classical Gram-Schmidt remainder ; then divide by if it is nonzero.
A reduced QR decomposition of an matrix over the real numbers with full column rank, , writes , where is with orthonormal columns and is a upper triangular matrix with positive diagonal. Applying the Gram-Schmidt process to the columns of constructs and records the coefficientsThis last column identity is exactly the matrix multiplication . The upper triangular matrix records that the th input uses only the first new directions, while its positive diagonal records the norms of the nonzero orthogonal projection residuals. Since , one also has ; denotes the transpose and the identity matrix. Over the complex numbers, use the conjugate transpose in these identities.
For the three-dimensional Gram-Schmidt process example, the exact matrices areFor example, the last column reconstructs asThe diagonal entries are approximately . Each is a norm of the new direction before it was scaled to length one.
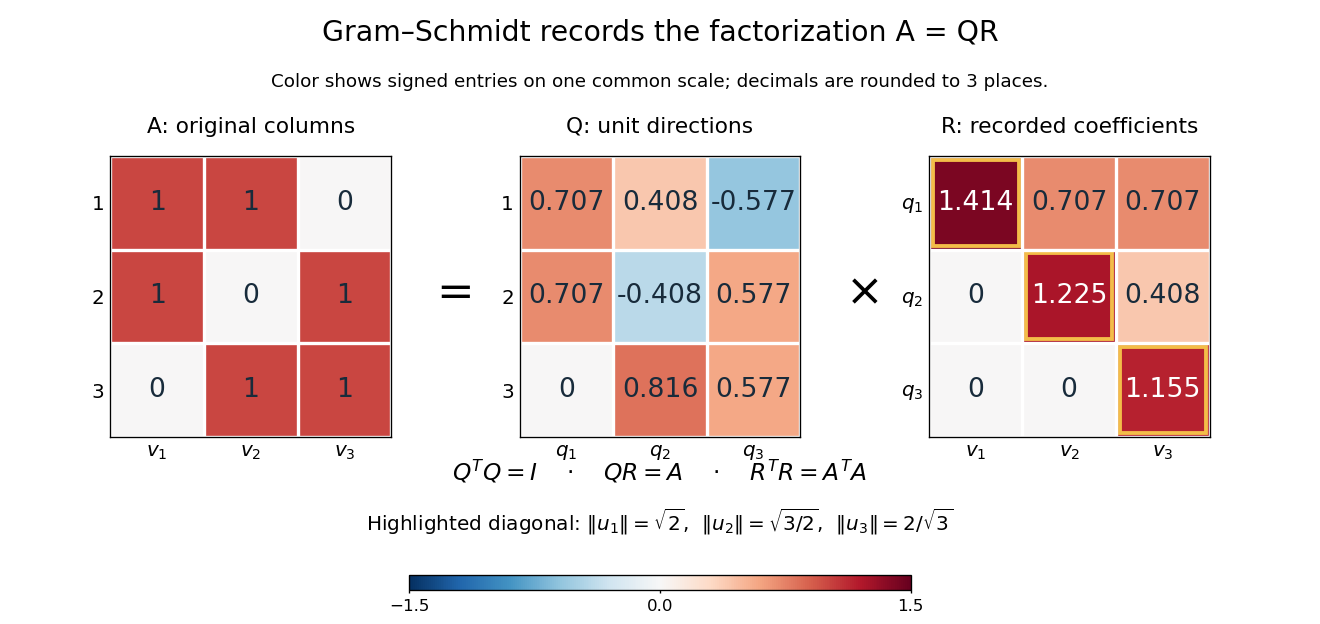
The computed QR factorization: input matrix , orthonormal columns of , and the upper triangular matrix of orthogonal projection coefficients
. Details. For a linear least-squares problem, the orthogonal projection of onto the column space of is . Hence the minimizing coefficients solve the linear system by back substitution. Let consist of the first two columns of the example; its reduced factors are and the leading block of . For , the linear system isThus , agreeing with the orthogonal projection computed above, and the minimum Euclidean norm of is . The QR decomposition separates building an orthonormal basis from recovering coefficients in the original basis.[ref]
https://ocw.mit.edu/courses/18-065-matrix-methods-in-data-analysis-signal-processing-and-machine-learning-spring-2018/resources/lecture-9-four-ways-to-solve-least-squares-problems/. Strang, MIT 18.065, Lecture 9: Four Ways to Solve Least Squares Problems
Let with and square invertible upper triangular . The normal equations for linear least squares reduce from to the system in the title. It is solved by back substitution. The geometric identity proves existence and uniqueness of the minimizer. For tall , is an orthogonal projection, not the identity on the entire observation space.
Let be block diagonal with blocks . If a real invertible matrix commutes with , its QR decomposition , with orthogonal and upper triangular with positive diagonal, has both and . Indeed , so is orthogonal and upper triangular in blocks. Orthogonality forces its off-diagonal blocks to vanish. Its diagonal blocks are . For with , this block is . Orthogonality of its columns forces , and hence each block is the identity. Thus , proving the claim.
If a real -by- matrix has full column rank, with , then is positive-definite. Its upper-triangular Cholesky decomposition , with positive diagonal, is unique. Defining gives and . Any other such factorization yields another Cholesky factor of , so its and then its must agree. This proves existence and uniqueness; it does not assert that forming is the most numerically stable algorithm.
For a full-column-rank matrix , extend the thin QR decomposition to an orthogonal matrix . Thenso maps the column space of onto the first coordinate directions. Successive Householder transformations construct the same reduction without first forming a full orthogonal basis.
A linear least-squares problem minimizes over . If has full column rank, orthogonality reduces it to the upper-triangular system formed from the leading block of and the leading entries of .
For a symmetric bilinear form , the same projection formulaproduces a -orthogonal basis whenever the chosen pivots are nonzero. Reordering the input vectors can avoid a zero pivot when a suitable anisotropic vector remains.
Articles by others on the same topic



The Gram–Schmidt process is an algorithm used in linear algebra to orthogonalize a set of vectors in an inner product space, most commonly in Euclidean space. The primary goal of this process is to take a finite, linearly independent set of vectors and transform it into an orthogonal (or orthonormal) set of vectors, which are mutually perpendicular to one another or normalized to have unit length.