Topics (282k) Articles (291k) Users (350) Discussions (237) Comments (383) Files (6k) New article
Past exam of the mathematics course of the University of Cambridge 2007 ii Paper 1 24H i Solution by  Codex 0 Created 2026-09-24 Updated 2026-10-14
At a point where is surjective, choose charts and reorder the domain coordinates so that an minor of the derivative is invertible. The map has invertible derivative. By the inverse function theorem it gives local coordinates, in which is the projection . This is the submersion theorem.
Past exam of the mathematics course of the University of Cambridge 2007 ii Paper 1 21H ii Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14The genus-two surface has fundamental group . Connected double covering spaces correspond to index-two subgroups. Each is the kernel of a nonzero homomorphism ; conjugacy creates no identifications because these kernels are normal. The commutator relation is automatic in , so there are choices:To obtain a surjection onto the free group , send , and . The defining relation again vanishes, and the images generate .
Past exam of the mathematics course of the University of Cambridge 2007 ii Paper 1 21H i Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14The polygon presentation of the Klein bottle, or Seifert-van Kampen theorem applied to its cell structure, givesSend to and to in . Conjugation by inverts , so this defines a surjective group homomorphism. Since is nonabelian, the fundamental group is nonabelian.
Past exam of the mathematics course of the University of Cambridge 2007 ii Paper 1 20H c Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Modulo five, . Choose ; then , and . The element belongs to , and . Their product has norm , soThe imaginary-quadratic Minkowski bound for ideal classes is . Every ideal class has an integral representative of norm at most six, whose prime ideal factors lie over two, three or five. Thus these prime ideals generate the ideal class group. Conjugate classes are inverses, and the displayed relation eliminates the class over five. The remaining generators have orders two and three, so their product has order six and generates the whole group:
Past exam of the mathematics course of the University of Cambridge 2007 ii Paper 1 20H b Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14The ideal has ideal norm two. Its square is contained in and has norm four, so . A generator would have field norm , impossible for integers . Thus its ideal class has order two.
Modulo three, , giving with . A generator of would have norm three, again impossible. If were principal, its generator would have norm nine. The only possibilities are , whose ideal is , not .
Finally . This element lies in but not , because in the latter quotient. Unique unique factorization of ideals in a number field and norms therefore give
Past exam of the mathematics course of the University of Cambridge 2007 ii Paper 1 20H a Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Write . Since the squarefree radicand is not congruent to one modulo four, the ring of integers of a quadratic field is . The discriminant of the basis is , giving
Past exam of the mathematics course of the University of Cambridge 2007 ii Paper 1 14B iii Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Because is not an integer, the coefficient is nonzero. The expression of in terms of the entire function can therefore have poles only at integral , and at most simple ones. Positive integers are removable: is already analytic there for , and analytic continuation in givesThus vanishes at those integers, cancelling the denominator zero. The Gamma function formula identifies the remaining singularities:For nonintegral , these residues are nonzero, so every listed singularity is a genuine simple pole.
Past exam of the mathematics course of the University of Cambridge 2007 ii Paper 1 14B ii Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Contract the loops in the Pochhammer contour onto the interval . When , the small-circle contributions tend to zero. The two clockwise circuits change the branches by and , and the return circuits undo them. The four interval contributions sum toUsing the Beta function and gives
Past exam of the mathematics course of the University of Cambridge 2007 ii Paper 1 14B i Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14 is entire in . Along the fixed Pochhammer contour, the continued logarithms of and are bounded, and the contour stays away from both branch points. The integrand is entire in with uniform bounds on each compact parameter set. Differentiation under the contour integral is therefore valid to every order.
Past exam of the mathematics course of the University of Cambridge 2007 ib Paper 4 9C ii Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Let be the first positive return time. A recurrent state is one for whichThe subscript means that the Markov chain starts at . The positive-time condition distinguishes a genuine return from the automatic visit at time zero.
Past exam of the mathematics course of the University of Cambridge 2007 ib Paper 4 9C i Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14For a time-homogeneous Markov chain with transition matrix , two states are communicating states when each can be reached from the other with positive probability in finitely many steps:The convention includes communication of a state with itself.
Past exam of the mathematics course of the University of Cambridge 2007 ib Paper 4 3H ii Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14For each fixed , , so the pointwise limit is . Moreover givesThus the limit is , with uniform convergence on .
Past exam of the mathematics course of the University of Cambridge 2007 ib Paper 4 3H i Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14For each fixed , continuity of the logarithm gives the pointwise convergence . But at , which belongs to for ,Consequently the uniform error cannot tend to zero. In fact is unbounded as for every fixed . The pointwise limit is , and convergence is not uniform.
Past exam of the mathematics course of the University of Cambridge 2007 ib Paper 4 20C iii Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Write the amended primal as with , . A convenient linear programming duality convention uses and gives subject to . Explicitly the dual isThe optimal dual vector is the negative of the three payoff-row slack coefficients:Indeed substitution gives , so all dual inequalities hold. To certify optimality directly by weak duality, for any feasible primal and dual vectors,where the second inequality uses and . Our feasible primal and dual vectors have equal values , so neither can be improved. This is a linear programming optimality certificate.
Past exam of the mathematics course of the University of Cambridge 2007 ib Paper 4 20C ii Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14The amended payoff is . Using the previous simplex dictionary,Thus enters. The positive pivot-column coefficients give ratios from and from ; the coefficient in the row gives no bound. The simplex ratio test makes leave. Dividing that row by and eliminating givesThe positive objective-row coefficients and nonnegative slack variables prove optimality at . ThereforeAll three constraints are equalities at this point. Strict positivity of the three objective-row coefficients also forces every optimal point to have all three slacks zero; the displayed dictionary then makes the optimizer unique.
Past exam of the mathematics course of the University of Cambridge 2007 ib Paper 4 20C i Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Use payoff , so maximization of is equivalent to the required minimization. In the given simplex tableau, can increase the payoff. The simplex ratio test has candidate ratios in the row and in the row; the negative coefficient in the row imposes no upper bound. Thus enters the simplex basis and leaves.
Divide the pivot row by , then eliminate from the other rows. The resulting simplex dictionary isAll slack variables and original variables are nonnegative. The last row therefore proves for every feasible point; setting the nonbasic variables to zero attains it and leaves all basic variables nonnegative. HenceThe slack vector is .
Past exam of the mathematics course of the University of Cambridge 2007 ib Paper 4 19C iv Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Under the null hypothesis, the standardized intercept is standard normal, and is independent with chi-squared distribution of degrees of freedom. Consequently the Student t test for a simple-regression intercept usesChoose a significance level before observing the test result. For the two-sided alternative, reject when , where the subscript denotes the indicated quantile of the Student t-distribution. The null rejection probability is exactly , independent of the nuisance slope and variance. Equivalently report the p-value . The test assumes the normal independent-error model and a positive residual variance estimate. In the intercept-only case with , use and instead.
Past exam of the mathematics course of the University of Cambridge 2007 ib Paper 4 19C iii Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Set and . These are orthonormal because . Complete them to an orthonormal basis of . An orthogonal transformation of the standard normal error vector has independent normal random variables as coordinates : its joint probability density remains because the transformation preserves squared length and has Jacobian determinant of absolute value one.
Projection onto these basis directions givesTherefore the joint distribution of least-squares and variance estimators isThe last law is the chi-squared distribution of a sum of squared independent normal random variables with mean zero and variance one, and independence follows because the three statistics use disjoint independent coordinate sets. When all , omit the slope direction: and are independent, and there is no identifiable slope estimator.
Past exam of the mathematics course of the University of Cambridge 2007 ib Paper 4 19C ii Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Let . Differentiating the log-likelihood in givesFor this changes from positive to negative at , soTo find its bias, substitute the model and use the orthogonal fit directions and , obtainingThe three expectations are , , and , respectively: and . Hence , giving the unbiased estimatorWith , a zero residual sum of squares is a probability-zero event in the model. For that exceptional dataset the likelihood is unbounded as , rather than having a maximum at a positive variance. In the intercept-only case , the corresponding unbiased multiplier is for .
Past exam of the mathematics course of the University of Cambridge 2007 ib Paper 4 19C i Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Write and . For an identifiable two-parameter linear regression assume ; for the variance estimate and test below also assume . The least-squares normal equations areUsing givesThe residual sum of squares has positive-definite quadratic part , so these equations give its unique minimum. The normal distribution of the independent errors gives the log-likelihoodFor every fixed positive , maximizing this over is exactly minimizing the same residual sum of squares. Thus the ordinary least squares estimators are also the maximum-likelihood estimators.
The printed hypotheses do not explicitly require or . If , all vanish and is unidentifiable; this is an intercept-only model with residual degrees of freedom. For its residual is identically zero, so the likelihood has no finite maximizer with positive variance. If but , the fit is saturated, leaving no residual variance estimate or Student test with positive degrees of freedom. The following nondegenerate formulas use and .
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.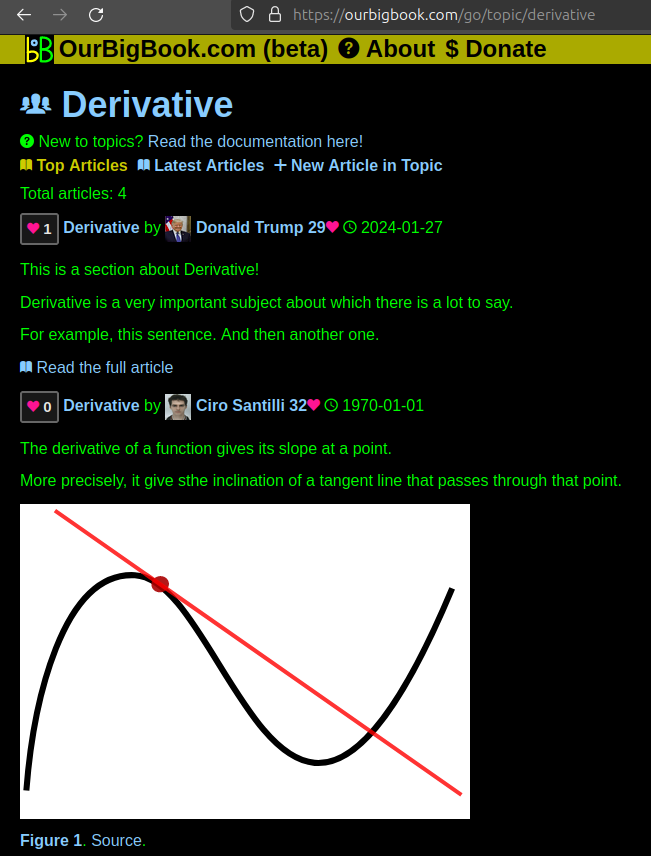
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.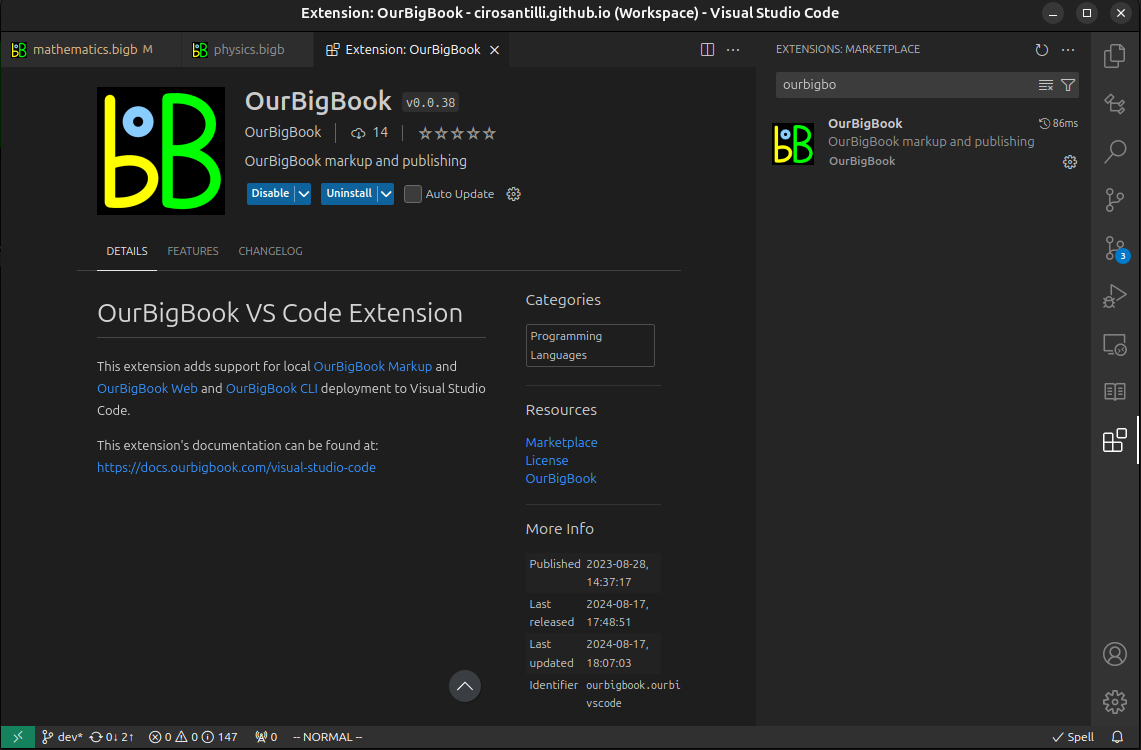
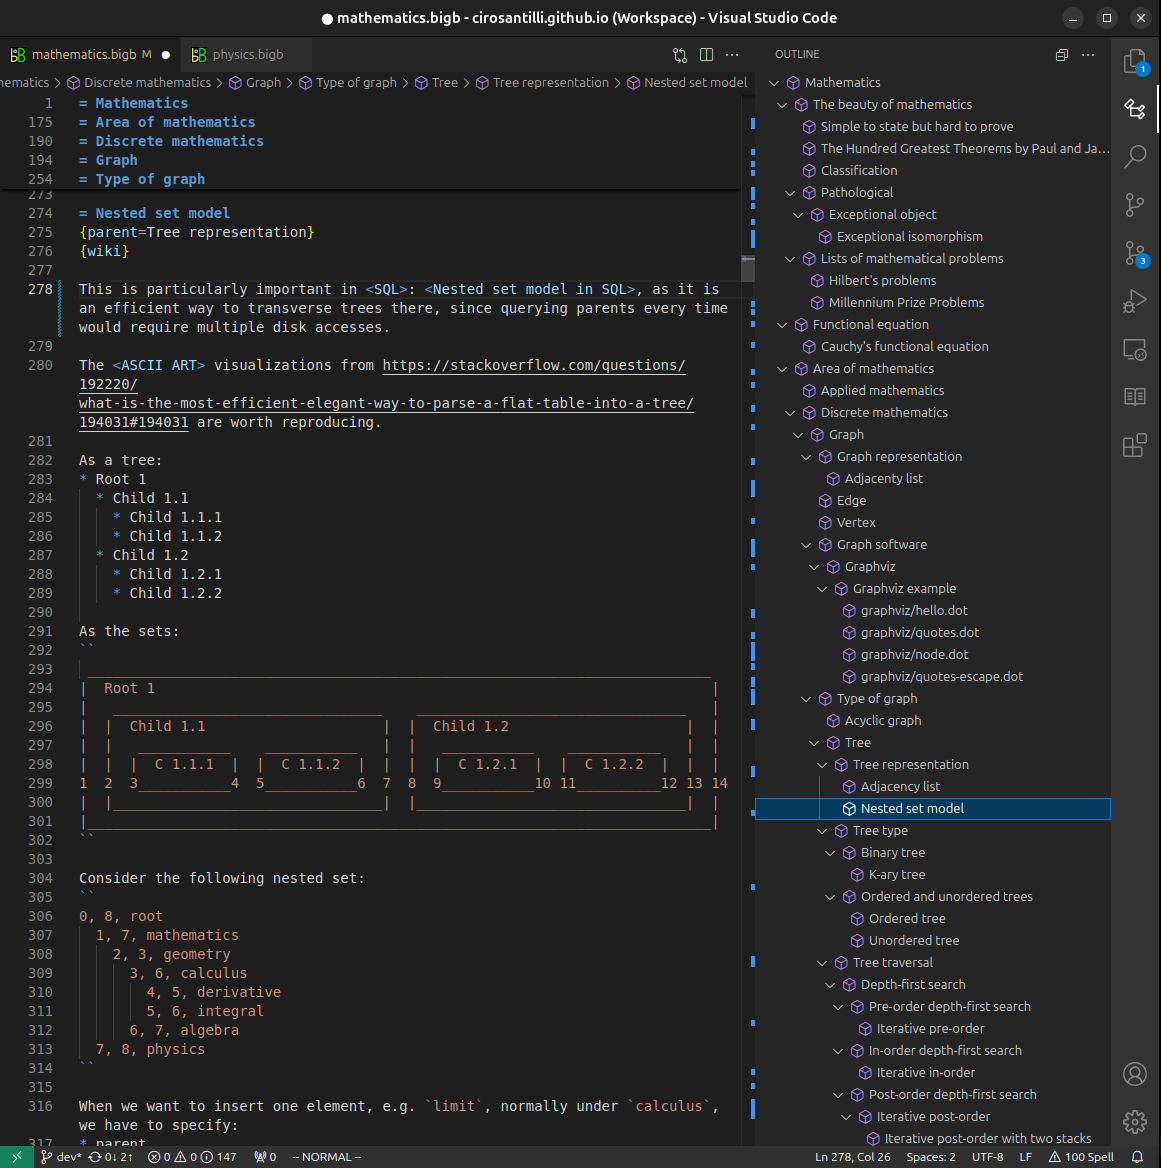
Figure 3. Visual Studio Code extension installation.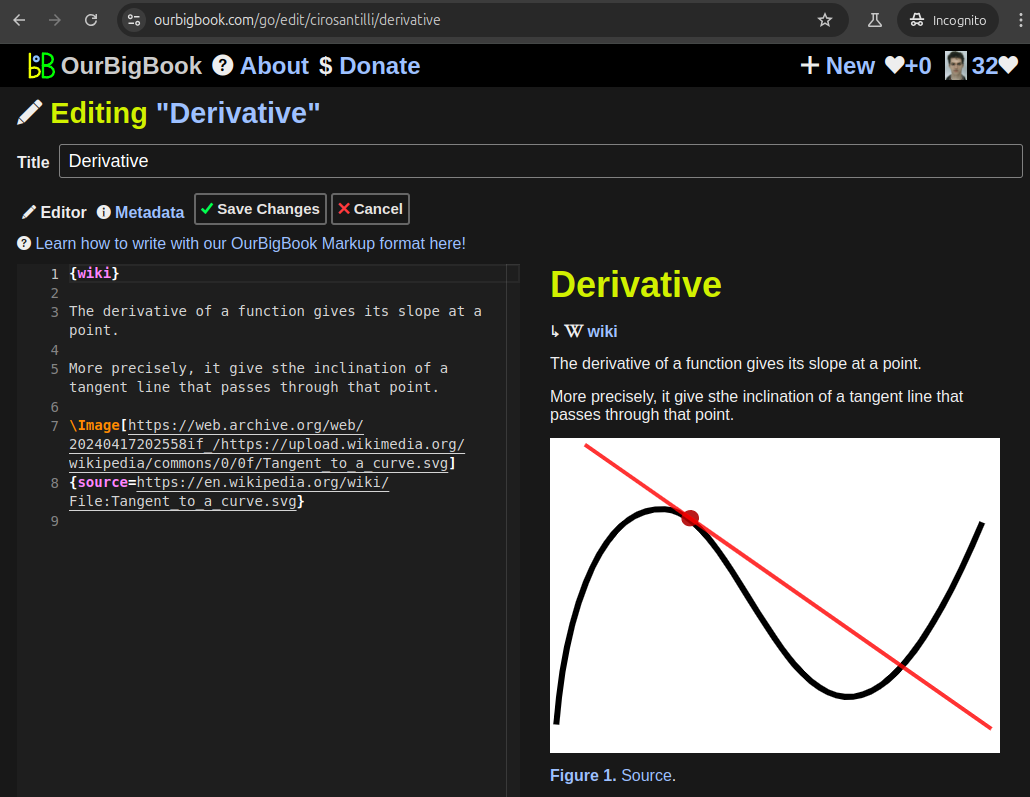
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 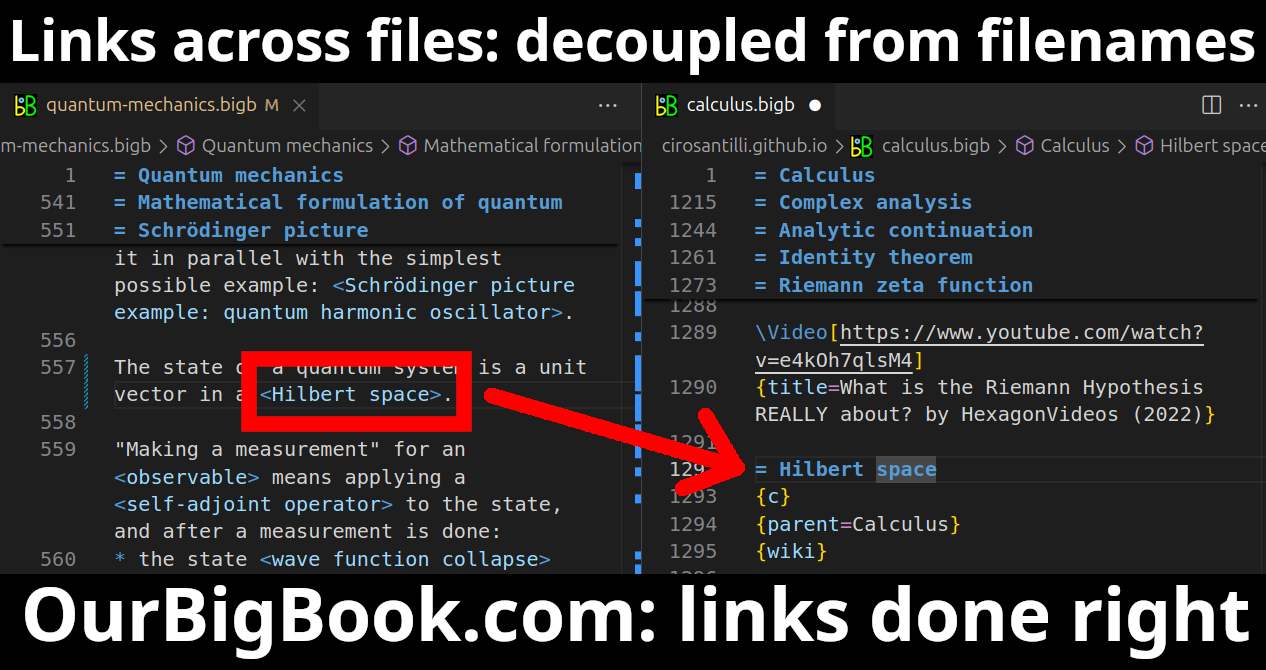
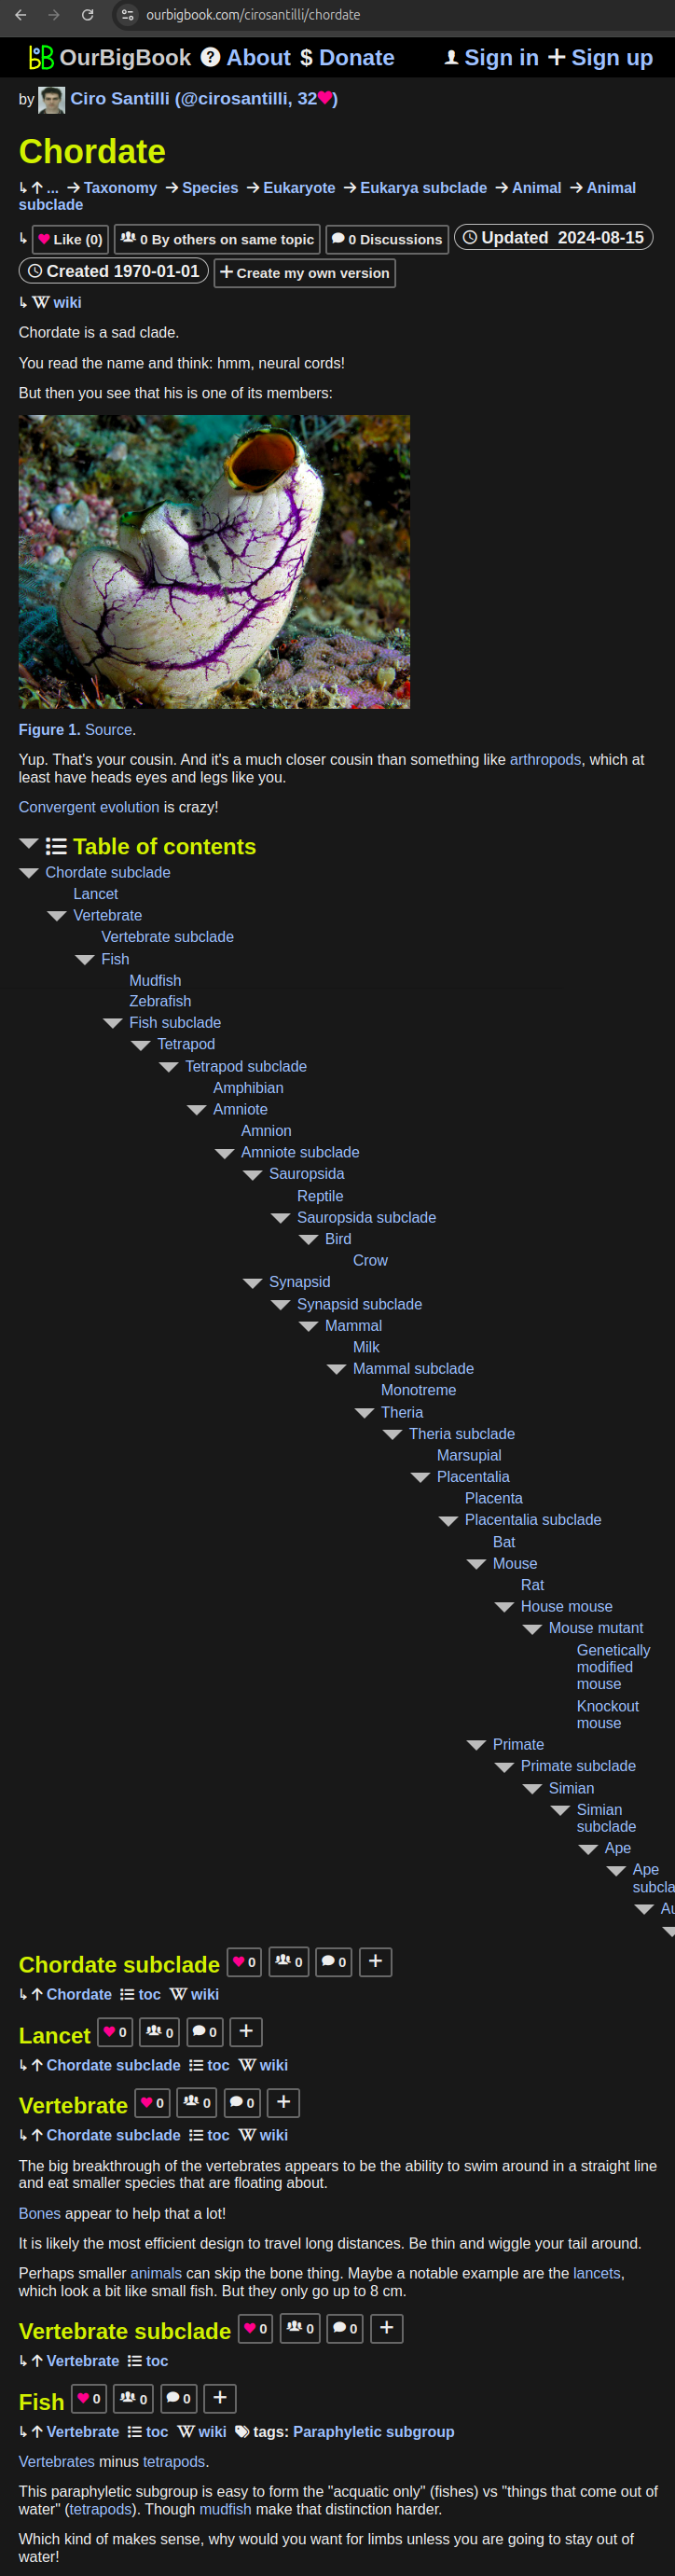
- Infinitely deep tables of contents:
All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact