Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article

Typical ambiguity is the schema asserting that every closed well-typed sentence is equivalent to its uniform type-raise. It is not an assertion that adjacent types have the same cardinality. To obtain finite satisfiability, color finite increasing rank selections by the truth values of the finitely many sentences concerned. The Ramsey's theorem gives a homogeneous rank set; two overlapping windows then have equal truth vectors, yielding the desired type-raise equivalences. The compactness theorem gives a first-order model of the entire schema.
A similarity ansatz assumes a profile invariant under a prescribed rescaling, commonly in the displayed power-law form. Substitution into a partial differential equation fixes compatible exponents and can reduce it to an ordinary differential equation for . Boundary conditions and conserved quantities must also be compatible with the scaling; the ansatz alone does not establish existence of a solution.
Partition each ordered integration simplex according to the number of times before the concatenation point. The integral over each resulting region factors into an initial iterated integral and a final iterated integral. Summing these factorizations proves the identity in the truncated tensor algebra.
For a continuous path of bounded variation, integrate successively over the ordered simplex using Riemann-Stieltjes integrals. These integrals form the levels of its path signature. Appending the final integration variable gives the differential recursion .
For a noncritical least-period- cycle of , the multiplier sign is . A positive multiplier gives two symmetry-related period- cycles of the odd quadratic Lorenz map; a negative multiplier gives one period- cycle. Their multipliers are respectively and . Distinct points of a quadratic-map cycle cannot have the same absolute value, since the map is even and acts bijectively on its cycle; this proves the asserted least periods.
// Target: dynamical-systems.bigb
Divisibility information by small primes cannot by itself reliably distinguish integers with an odd or even total number of prime factors. Consequently an upper-bound Selberg sieve can bound prime pairs and related sifted sets but does not supply a positive lower bound or the conjectured twin-prime asymptotic. This limitation concerns the information available to the sieve, not merely a choice of weight normalization.
// Target: number-theory.bigb
For homogeneous equations with integer coefficients of absolute value at most , map the box to its equation values. There are inputs and at most outputs. Taking makes the first count larger, since . The difference of two inputs with the same output is the required nonzero bounded integer solution. Clearing denominators also treats rational equations; expanding a number-field basis replaces each field equation by finitely many rational equations.
Choose a generator of the multiplicative group of the quadratic finite field extension. Its shifts define distinct exponents modulo . Equality of two sums of exponents gives . Since are independent over the prime field, and , so the unordered pairs coincide. Thus the exponents form a Sidon set in the cyclic group. Taking integer representatives preserves the Sidon property. Primes within below give representatives in an interval of length .
For a Sidon set , put and let count points in a window of consecutive integers. Each point occurs in windows, so . Cauchy-Schwarz gives . Each positive difference occurs at most once and contributes windows, giving the upper bound . Thus . Taking gives the displayed estimate, which combines with the Bose-Chowla Sidon construction to determine the asymptotic maximum.
The stochastic SI model with susceptible fraction , initial limit , and total infection rate has deterministic limitThe Poisson time-change representation of a Markov chain writes as its integrated drift minus a centered Poisson error. On its clock is at most . The Poisson maximal concentration bound makes every fixed error tolerance have summable probabilities in , so the Borel-Cantelli lemma gives uniform error decay almost surely. The Gronwall inequality transfers that decay to , because the drift is Lipschitz continuous. The assertion is for fixed finite intervals and does not claim approximation over times growing with .
The Dijkstra algorithm solves the single-source shortest path problem in a finite graph with nonnegative edge weights, finding distances to all reachable vertices. Start with tentative distance and elsewhere. Repeatedly choose the unfinalized vertex with least tentative distance, declare that label permanent, and perform edge relaxation on its outgoing edges. For an undirected graph, inspect both directions. A finite tentative distance always records the cost of a discovered graph path, but can improve before finalization.
In our example, finalizing discovers at , at , and at . Choose next: edge relaxation through lowers to and to . Choose : edge relaxation through lowers to . Finally choose . The permanent distances are therefore , , , ; the evolving tentative distances were and .
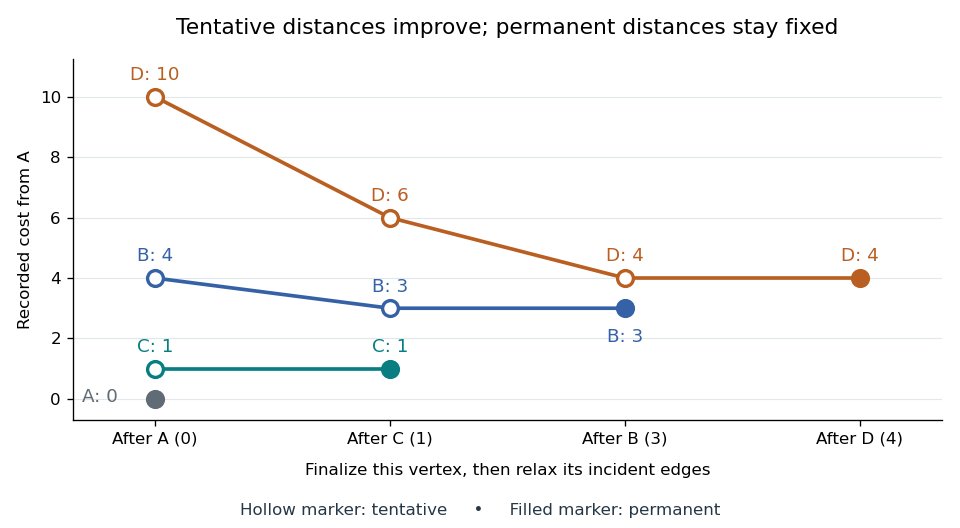
Tentative distances fall until the Dijkstra algorithm makes each label permanent
. Details. Store a shortest-path predecessor whenever edge relaxation improves a label. The final table contains enough information to reconstruct routes, rather than merely their costs:
| Vertex | Distance from | Shortest-path predecessor | Finalization order |
|---|---|---|---|
| None: source | |||
Following shortest-path predecessors backwards gives ; reversing the order gives . If only this destination matters, stop when is finalized. Stopping when is first discovered would incorrectly return . If the smallest remaining tentative distance is , all remaining vertices are unreachable.
Why is the permanent choice safe? Suppose the selected vertex had a cheaper graph path. Let be the first unfinalized vertex on that graph path. Its preceding vertex was finalized, so edge relaxation has already offered a label no larger than that prefix's cost. Nonnegative remaining edge weights make the whole cost at least this prefix's cost; selection gives . A cheaper graph path would contradict these comparisons. Zero weights are allowed; ties can be resolved arbitrarily. This is the reason the label-setting shortest-path algorithm works, rather than a lucky feature of the drawing.
Negative weights break that reasoning. In a directed graph with costing , costing , and costing , the Dijkstra algorithm would finalize at before discovering the cheaper cost . The Bellman-Ford algorithm handles negative edge weights when no relevant negative directed cycle exists.
With an adjacency list and an indexed binary heap implementing a priority queue, the time complexity is for , using Big O notation. Each vertex is extracted at most once, each edge is inspected once per direction, and each successful edge relaxation decreases a heap key in time. This assumes constant-cost arithmetic and comparisons; exact computation with very large weights adds their representation cost. The queue uses space beyond the graph. Simply scanning all remaining vertices gives instead.[ref]
https://algs4.cs.princeton.edu/44sp/DijkstraSP.java.html. Princeton, DijkstraSP implementation
[ref]https://algs4.cs.princeton.edu/code/javadoc/edu/princeton/cs/algs4/IndexMinPQ.html. Princeton, indexed binary heap operations
The 1959 paper presents the shortest path problem as its second problem, after the minimum spanning tree problem, and grows known shortest routes in increasing distance order.[ref]
https://www.cs.yale.edu/homes/lans/readings/routing/dijkstra-routing-1959.pdf. Dijkstra, A note on two problems in connexion with graphs, pp. 269–271
In his later recollection, Dijkstra dated the shortest-route discovery to 1956: a demonstration for the ARMAC computer used a simplified Dutch railway map and printed the route between towns. A practical request became an enduring algorithm because the same distance rule applies to any suitable graph.[ref]https://garfield.library.upenn.edu/classics1983/A1983QA19900001.pdf. Dijkstra's recollection, published in 1983
The Bellman-Ford algorithm solves the single-source shortest path problem in a finite directed graph with finite real edge weights, allowing negative weights. It repeatedly applies edge relaxation, so an improved tentative distance can improve its neighbours on a later visit. This makes it a label-correcting shortest-path algorithm.[ref]
BellmanFordSP.java. Algorithms, 4th edition by Robert Sedgewick and others; Robert Sedgewick and Kevin Wayne, BellmanFordSP.java, signed-weight single-source solver and queue-based relaxation
If no negative-cost directed cycle is reachable from the source, at most complete passes suffice for all distances; a further check detects a reachable negative-cost directed cycle.[ref]Lecture 17: Shortest Paths III: Bellman-Ford. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; MIT 6.006, Lecture 17, pp. 3–4: complete-pass algorithm, proof and reachable-cycle corollary
There are two orientations to keep distinct. The usual single-source problem asks for distances from , extending routes along outgoing directed edges. The Bellman inequalities above instead concern distances to a sink , prepending incoming directed edges to known routes. The All-to-one Bellman-Ford recurrence below preserves that convention. Reversing every directed edge, with its weight unchanged, converts one problem into the other.
Here is an original single-source example with source , vertex set , and precisely these directed edges:The negative edge is harmless: this directed graph has no directed cycle. Its best route to is , of cost . The other routes to cost through and through .
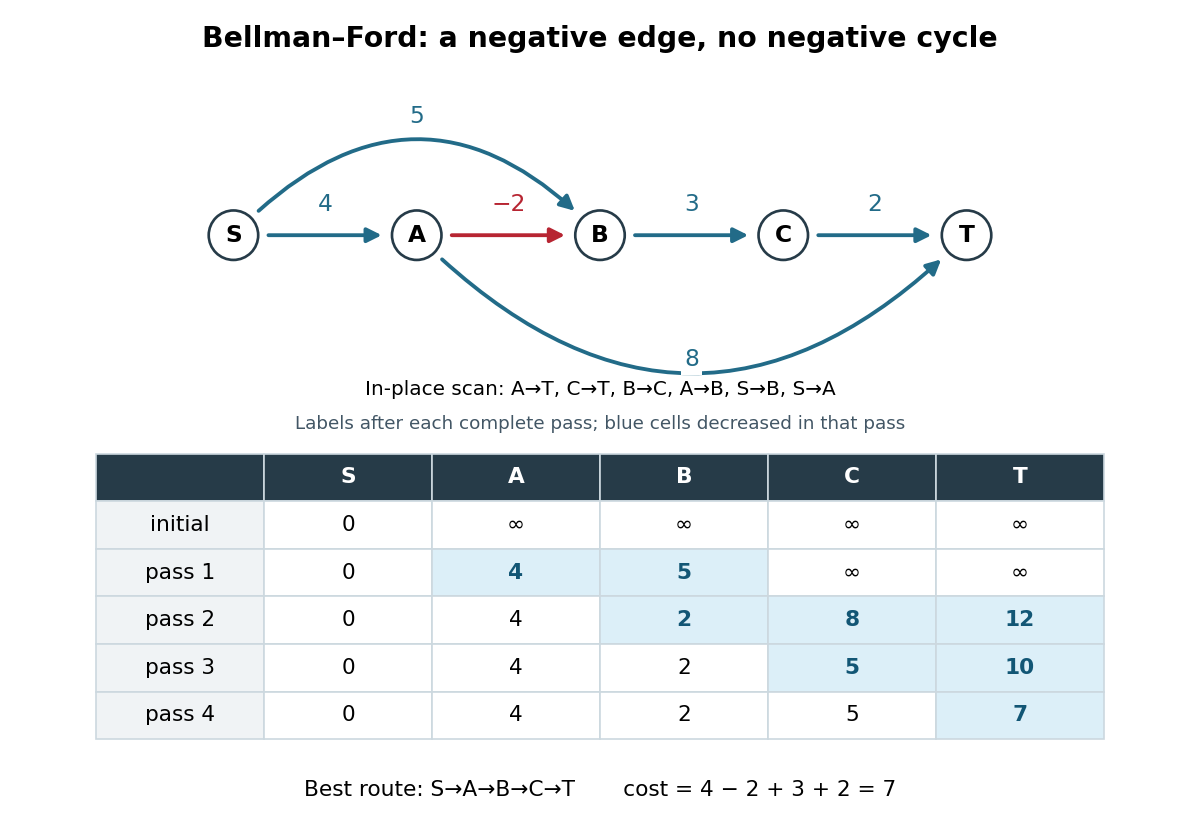
Initialize and the other tentative distances to . In each pass apply single-source edge relaxation, , scanning in the order , , , , , . Skip a candidate with . The figure records labels after each complete pass and uses current labels immediately: it is an in-place trace. In pass 2, still uses , giving ; only later does lower to . Pass 3 carries that improvement to , and pass 4 carries it to . The final labels in order are ; the final shortest-path predecessors are for respectively.
The scan order explains the delay. Scanning instead as , , , , , gives those same final labels in just one in-place pass. The Synchronous Bellman-Ford recurrence has a precise bound on the number of edges used by a recorded route; an in-place pass can propagate along several edges and need not have that interpretation. Both implementations have the pass guarantee under the stated no-reachable-negative-cycle hypothesis.
With a stored list of edges, complete-pass Bellman-Ford algorithm has time complexity and uses extra space for labels and shortest-path predecessors, using Big O notation and constant-cost arithmetic. The extra accounts for initialization even when is empty. A pass with no strict decrease permits early termination. A queue variant instead revisits outgoing edges of vertices whose labels improved; the authored implementation provides this alternative and has worst-case running time on its usual nontrivial instances.[ref]
BellmanFordSP.java. Algorithms, 4th edition by Robert Sedgewick and others; Robert Sedgewick and Kevin Wayne, BellmanFordSP.java, class documentation, constructor and relax method
For nonnegative weights, the Dijkstra algorithm and its existing distance-frontier figure explain how permanent labels can avoid these repeated passes; the existing edge relaxation figure illustrates one update at a time.An algorithm whose tentative distance labels may be revised repeatedly until all relevant Bellman inequalities hold. Bellman-Ford algorithm uses this approach: a label is an upper bound supplied by a discovered directed walk, and relaxing an directed edge can replace it with a shorter discovered directed walk. A finite label is not declared permanent merely because it has been processed.
The Bellman inequalities turn local directed edge checks into a global certificate for the shortest path problem. Here the convention is all-to-one: every journey ends at a fixed vertex , and is the cost of the original directed edge . Work in a finite directed graph with finite real costs. Write for candidate labels, normalized by , on the vertices that can reach . A feasible potential means precisely that these finite labels satisfyfor every directed edge within that set. These labels give lower bounds on costs to . A discovered directed path of cost instead gives an upper bound. The following constructed graph shows both bounds and the exact distances between them; its weights are illustrative costs, not measured travel data.
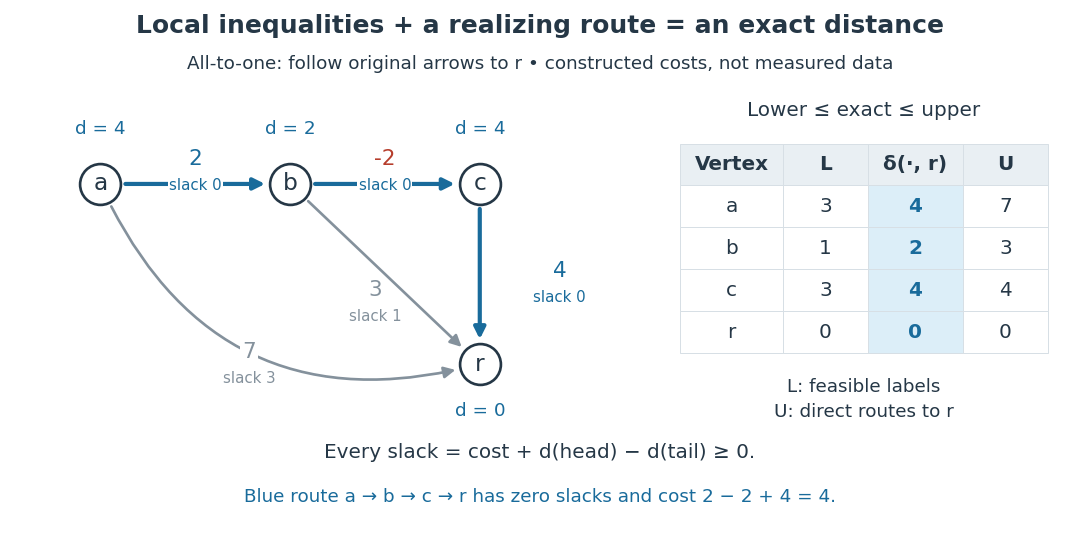
The arrows in the picture point toward the destination, whereas edge relaxation propagates an improved label in the opposite direction: an improved can lower . In the pictured graph, the directed paths from to cost , , and . Thus . The candidate in vertex order is feasible, but underestimates the exact distances . Merely satisfying the Bellman inequalities does not make a candidate exact.
Why do they give lower bounds? Along any directed path , successive substitution givesThe same calculation works for a directed walk, with repeated vertices allowed. Taking the infimum of route costs gives . A discovered route gives . If the bounds meet, , they certify an optimum without enumerating routes. Equivalently, check the Bellman inequalities for the proposed distances and exhibit directed paths realizing them. The authored Bellman-Ford algorithm implementation checks the corresponding single-source inequalities and equality on recorded route edges; reversing every directed edge gives this all-to-one convention.[ref]
BellmanFordSP.java. Algorithms, 4th edition by Robert Sedgewick and others; Sedgewick and Wayne, BellmanFordSP.java, optimality checks
For the exact labels in the picture, the slack is respectively on , , , , . Zero slack means equality; the zero-slack directed path realizes the cost . This is the useful beauty of the certificate: a few local inequalities rule out every cheaper journey, while one explicit journey attains the bound.
Keep unreachable vertices separate: when no directed path to exists, and a finite lower bound alone cannot certify that fact. Extended labels can use for finite , but never compute a slack as . If can reach a negative-cost directed cycle and then reach , repeatedly traversing the directed cycle makes route costs unbounded below: their infimum is , with no finite shortest directed walk. A finite feasible potential on such a directed cycle is impossible, since summing its Bellman inequalities would give . A negative-cost directed cycle that cannot reach does not affect distances to . These are statements about unrestricted directed walks; requiring a directed path with no repeated vertices is a different optimization problem when negative-cost directed cycles exist.[ref]
Lecture 17: Shortest Paths III: Bellman-Ford. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; MIT 6.006, Lecture 17, pp. 1 and 5: relevant negative cycles and simple paths
For the single-source convention, the same original directed edge instead gives with , a lower bound on distance from . The endpoint carrying the label on the left therefore changes with the direction of the problem.
An algorithm that makes each vertex's distance permanent once it is selected. With nonnegative directed edge lengths, the Dijkstra algorithm selects the unfinalized vertex with least tentative distance; a shorter route through another unfinalized vertex is impossible because its remaining route has at least that next tentative distance. For an all-to-one problem, incoming directed edges to the selected vertex are relaxed. Negative lengths can invalidate this finalization argument.
Let index at least two pairs of subsets of an -element ground set, with , , and exactly when . ThenChoose a witness for each pair. The intersection conditions make these witnesses distinct and exclude from both sets belonging to every other index. For distinct , the sets and are disjoint and both lie outside the entire witness set. Consequently .
For sharpness, choose disjoint fixed sets of sizes and let the remaining points be witnesses. Put and . This construction attains equality whenever there are at least two witnesses. The two-pair hypothesis cannot be dropped: a single pair satisfies the intersection condition, but for the proposed unrestricted bound would read .
For a finite ground set and an indexed set family, this zero-one matrix records membership of points in members. The diagonal entries of are member sizes, and its off-diagonal entries count pairwise intersections. For the Fano plane, either point-line orientation gives the identity , since every point lies on three lines and each distinct point pair lies on one line.
A Helly family of order is a set family for which every finite subfamily has nonempty total intersection whenever each of its subfamilies with at most members has nonempty intersection. Convex subtrees of a tree have Helly order two.
A singleton set has exactly one element.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact