Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article

A call stack stores active procedure calls and the information needed to resume each caller, such as its return location and local variables. A call adds a frame; returning removes that frame and resumes the previous call. When depth-first search uses recursion, a frame also records where its adjacency list scan paused. The active frames describe a graph path from the starting vertex to the current vertex; finished calls have left the call stack, although their vertices remain marked as discovered.
DPPH is a neutral organic radical used as a spin reference in electron paramagnetic resonance (EPR), also called electron spin resonance (ESR). Its unpaired electron remains bound within the chemical species: “free radical” does not mean a freely moving electron. The DPPH electron spin resonance experiment makes its magnetic moment observable.
For the normalized sRGB calculations here, relative luminance is the linear-light weighted sumwhere are decoded linear-light components, not encoded code values. This is the sRGB calculation specified in W3C's WCAG 2.2 definition of relative luminance. It places reference black at 0 and reference white at 1; it does not by itself specify an absolute display light level.[ref]
https://www.w3.org/TR/WCAG22/#dfn-relative-luminance. W3C, WCAG 2.2, definition of relative luminance: sRGB decoding and weights
For a neutral sRGB shade, , and the weights sum to 1, so . For a coloured pixel, relative luminance can be encoded as a neutral sRGB shade with all three encoded components . This preserves the specified while discarding colour differences; it is one precisely defined grayscale conversion, not a unique way to turn all colour images into grayscale.
A numerical value retained for reuse by memoization. It is usable only while the spreadsheet formula and all its relevant inputs remain valid. After changing
A1 from 3 to 5, following outgoing directed edges finds exactly B1,B2,C1,D1. Invalidate their cached cell values before evaluating another requested result; install the new input value for A1. The cached cell values of A2 and E1 remain valid because neither has a directed path from A1.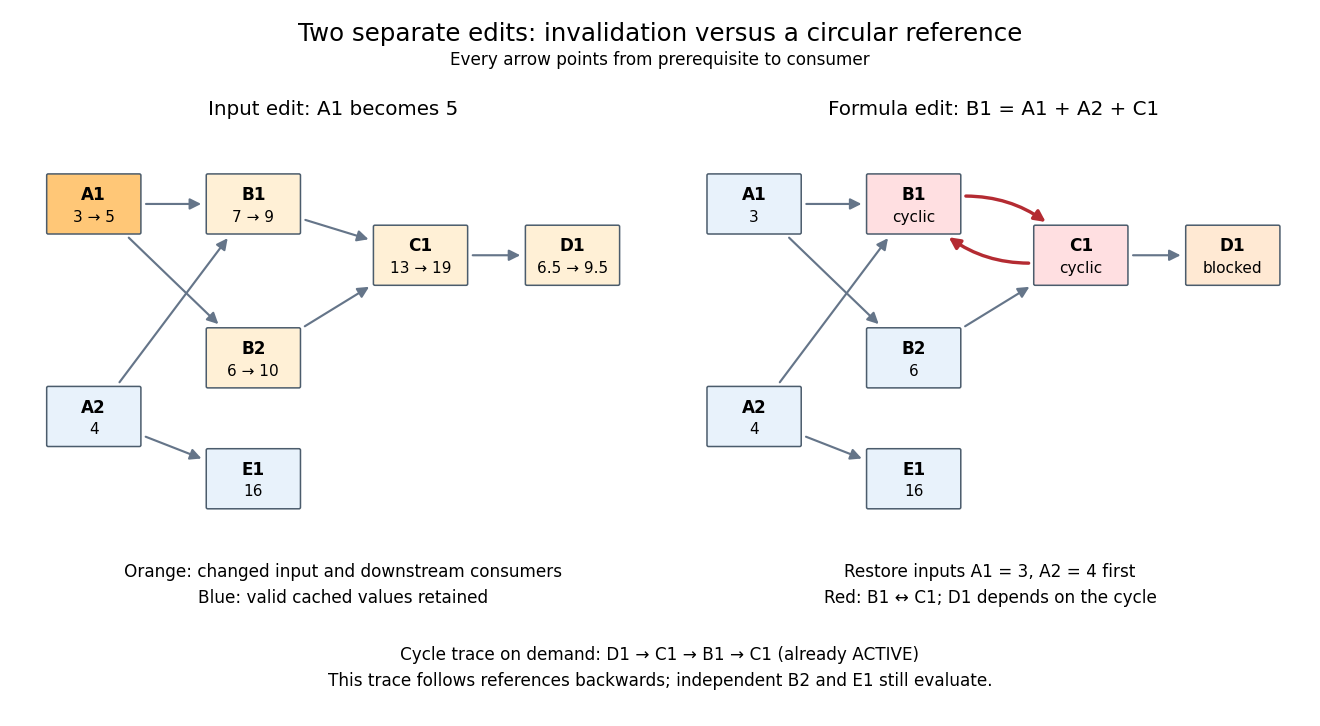
Downstream invalidation after an input edit, and a different formula edit creating a spreadsheet circular reference
. Details. One recomputation in the restricted topological order
B1,B2,C1,D1 gives . Four spreadsheet formulas are recomputed, while E1 stays at 16. Removing invalid values from the cache prevents a subtle error: a finished marker from the previous evaluation does not prove that the old value is correct after an edit. The affected set is conservative; a changed prerequisite might leave a consumer's value numerically equal, but this simple scheme still invalidates it. For a formula edit, update the incoming directed edges and corresponding outgoing consumer lists as well as invalidating the edited spreadsheet cell and its downstream consumers. Microsoft's documentation explicitly describes both direct and indirect dependents being marked for recalculation.[ref]Excel Recalculation by Microsoft. Dependence, Dirty Cells, and Recalculated Cells: paragraph beginning “When a structural change is made”; B1/A1 and C1/B1 dirty-cell example
For demand-driven evaluation, memoization combines with depth-first search. Each spreadsheet cell has one of three states:
UNSEEN means no valid cached cell value; ACTIVE means its evaluation is on the current call stack; FINISHED means a valid value is available. Initialize valid input spreadsheet cells as FINISHED. Start with all spreadsheet formulas UNSEEN, or retain only valid FINISHED entries after invalidation. The following original algorithm uses an ordered references list and an apply_formula operation for each spreadsheet formula:def value(cell):
if state[cell] == FINISHED:
return cache[cell]
if state[cell] == ACTIVE:
i = stack.index(cell)
raise CircularReference(stack[i:] + [cell])
state[cell] = ACTIVE
stack.append(cell)
try:
args = [value(p) for p in references[cell]]
cache[cell] = apply_formula(cell, args)
state[cell] = FINISHED
return cache[cell]
except Exception:
state[cell] = UNSEEN
raise
finally:
stack.pop()Requesting
D1 first makes D1,C1,B1 active, then reads the finished inputs A1,A2. B1 finishes at 7. Evaluating B2 reuses the finished value of A1 and finishes at 6; C1 finishes at 13 and D1 at . A later request for D1 immediately returns its cached cell value. The shared prerequisite A1 is not a directed cycle: it was finished before the second request. The crucial distinction is between a previously visited vertex and a still-active vertex. The exceptional path restores unfinished states while unwinding the call stack, so failed evaluations are not cached as successful results. MIT's depth-first search notes use stack-duration marks to distinguish an edge to an active ancestor and to detect a directed cycle.[ref]Lecture 14: Graphs II: Depth-First Search. Lecture 14: Graphs II: Depth-First Search, printed pp. 3–4: stack-duration marks and cycle detection
With adjacency lists and constant-time state/cache access, the structural work of a successful demand-driven evaluation is in big O notation, where and are the requested spreadsheet cells and their recursively reached prerequisites and references. Each reached spreadsheet formula is computed once; each reference is inspected once. This time complexity counts dependency bookkeeping separately from the cost of the arithmetic operations. Detecting a spreadsheet circular reference can additionally scan the current call stack once to report its witness.
The directed graph whose vertices are the spreadsheet cells and whose directed edges mean that the spreadsheet formula in references . Input spreadsheet cells have no prerequisites in this model. Retain both incoming references and outgoing consumers: depth-first search for evaluation follows incoming references backwards, whereas downstream invalidation follows outgoing consumers forwards. A directed path then expresses indirect dependence, and a directed cycle expresses a spreadsheet circular reference.
A mathematical expression stored in a spreadsheet cell, with references to other spreadsheet cells. In this example
=A1+A2 asks for addition, =2*A1 for multiplication, and =A2^2 for exponentiation. The evaluator in spreadsheet dependency evaluation assumes these spreadsheet formulas have already been represented by their ordered lists of referenced spreadsheet cells and operations on the resulting numbers; it does not execute arbitrary formula text.Copying a spreadsheet formula produces a new expression by adjusting its spreadsheet cell references. Copying only its displayed value produces a number instead. For example, copying the spreadsheet formula
=A2*B2 down one row gives =A3*B3; entering its former value in the next row would give neither the required relationship nor this example's correct subtotal .Einstein coefficients describe spontaneous emission, stimulated emission and absorption between atomic levels. With multiplying radiation energy density per frequency, thermal detailed balance gives and . Coefficients defined using mean specific intensity instead have a different normalization; specify the radiation convention.
The critical density of an atomic transition is the electron density at which its collisional de-excitation rate equals its spontaneous radiative decay rate. A multilevel atom requires summed competing rates rather than a single-transition ratio. This atomic density scale is distinct from cosmological critical density.
A radiative cascade is a sequence of downward photon-emitting transitions following excitation or recombination. Cascades feed lower excited levels and change their emitted line intensities. An effective recombination coefficient includes all relevant cascade paths under its stated optical-depth and density assumptions.
A species can encompass many biological populations. A biological population specifies a set of organisms in a place and time; a biological strain identifies a maintained variant or lineage, often in a laboratory. A species name, a local census and a biological strain designation therefore describe different things. Multiple independently maintained cultures can also share the same biological strain designation.
For example, a culture identified as Escherichia coli K-12 MG1655 specifies more than the species alone. Two flasks inoculated from that culture are separate experimental biological populations; the separate containers do not establish two species or two different biological strains. This is an original experimental bookkeeping example, not a claim that every biological strain name encodes a complete genotype.
Species delimitation infers the boundaries and number of species from evidence. No single arbitrary percentage of nucleotide sequence difference is a universal boundary. Divergence within an old, widespread species can exceed divergence between recently separated species; geography and multiple kinds of evidence matter. [ref]
Species Concepts and Species Delimitation by Kevin de Queiroz. pp. 884–885, “Alternatives to the Traditional Properties”: divergence cutoffs and geographic differentiation
An original counterexample to a universal percentage rule: an assay could examine a strongly conserved gene in one comparison and a rapidly changing nucleotide sequence in another. Equal percentages then answer different historical questions. Even the denominator needs specifying: all sites, aligned sites, or only a filtered region? A threshold is an operational rule for a stated assay and group of organisms, whose errors need evaluating. It is not a definition that automatically transfers to every species.
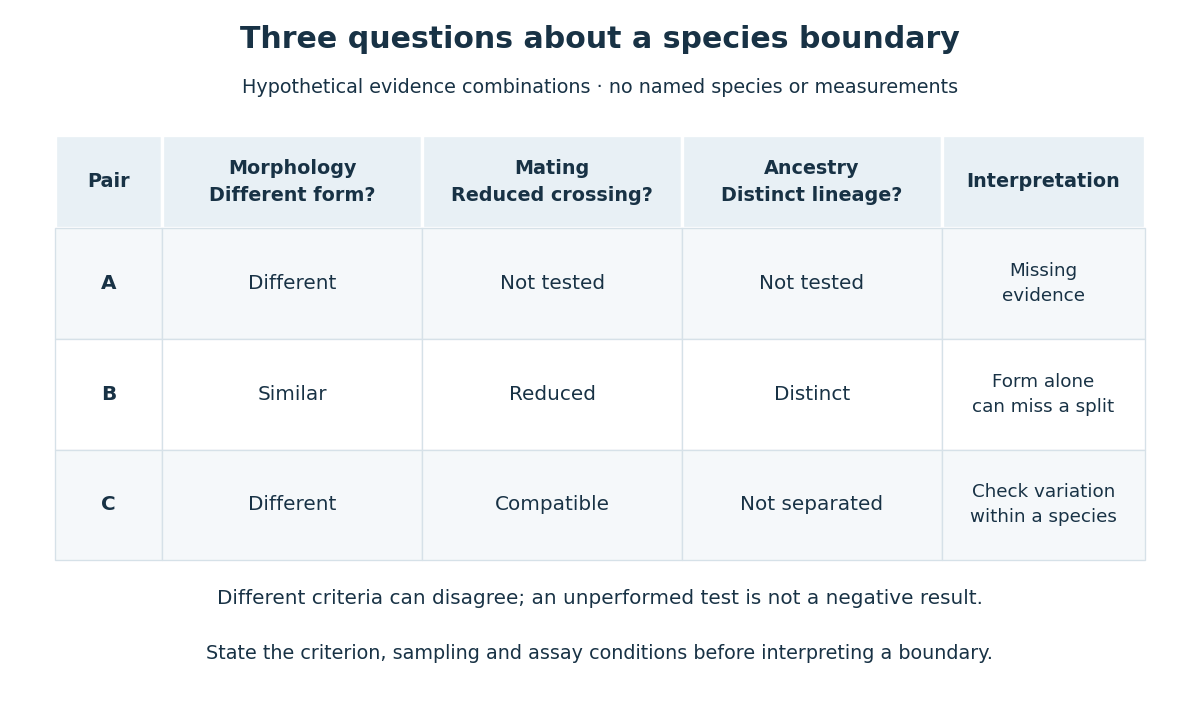
Contrasting operational evidence for species delimitation
. Original hypothetical comparison of morphology, mating and ancestry evidence. Each observation tests a different claim; the combinations are thought experiments, not a dataset or verdicts about named species. “Not tested” does not mean absent. Details.The diagram's hypothetical pair B has similar morphology but reduced mating and distinct ancestry evidence. A morphological species concept could miss that distinction. Pair C instead has different morphology but compatible mating and ancestry that fails to separate the samples. That combination calls for checking variation in phenotype within a species. Pair A has only a structural difference observed: the other criteria remain untested. These examples show why missing evidence, disagreeing evidence and agreeing evidence require different interpretations.
A species concept states what should make organisms members of the same species; an operational criterion states what observations will test that claim. Reproductive isolation, distinguishable morphology and ancestry inferred through phylogenetics answer different questions. In a lineage-based interpretation, they are evidence for separation of evolving biological populations, and need not appear together. [ref]
Species Concepts and Species Delimitation by Kevin de Queiroz. pp. 880–883, Table 1, Figure 1 and “Conceptualization versus Delimitation”: distinguish defining properties from operational evidence
Reproductive isolation consists of barriers that reduce gene flow through sexual reproduction. Distinguish premating isolation from barriers after mating. Barriers before fertilization also include incompatible gametes; barriers after fertilization can reduce offspring survival or fertility. [ref]
Biology 2e by Mary Ann Clark and others. §18.2, “Reproductive Isolation”, opening paragraphs, gametic barriers and hybrid inviability/sterility
An assay should state which step it measures. Observing fewer cross-group matings does not measure offspring fertility; observing fertilization does not demonstrate that the offspring will reproduce. These distinctions make a partial barrier informative without declaring completed speciation.
A massive particle is nonrelativistic when its speed is small compared with the speed of light. Its energy expansion is . The leading momentum-dependent term is the classical kinetic energy.
A relativistic massive particle is described by a timelike worldline with proper-time four-velocity . In signature its normalization is and its momentum is . The relativistic charged-particle action adds electromagnetic coupling, whose variation gives the Lorentz force.
The laws of physics have the same form in all inertial frames; uniform absolute motion cannot be identified by experiments confined to an inertial laboratory. The invariant vacuum speed of light is a separate postulate. Together they motivate the Lorentz transformations of special relativity.
Merge sort is a divide-and-conquer algorithm that sorts a finite array by splitting it into contiguous halves, sorting each half using recursion, and combining the two sorted arrays with the merge algorithm. An empty or one-entry array is returned immediately. For length , put the first entries on the left and the remaining on the right; the brackets are the floor function and ceiling function. Always choose the left head on equal keys to obtain stable sorting. This is the split, sort, combine structure taught in the MIT lecture notes.[ref]
Lecture 3: Insertion sort, merge sort. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; MIT 6.006 (2011), lecture 3: merge sort
Take the concrete input arrayThe tags identify the entries originally at indices and , counting from zero. Both keys are ; the tags are never compared. Reading downward in the figure follows the splits, then the returned sorted arrays. Arrows show dependencies; the level layout groups independent calls rather than giving their chronological execution order.
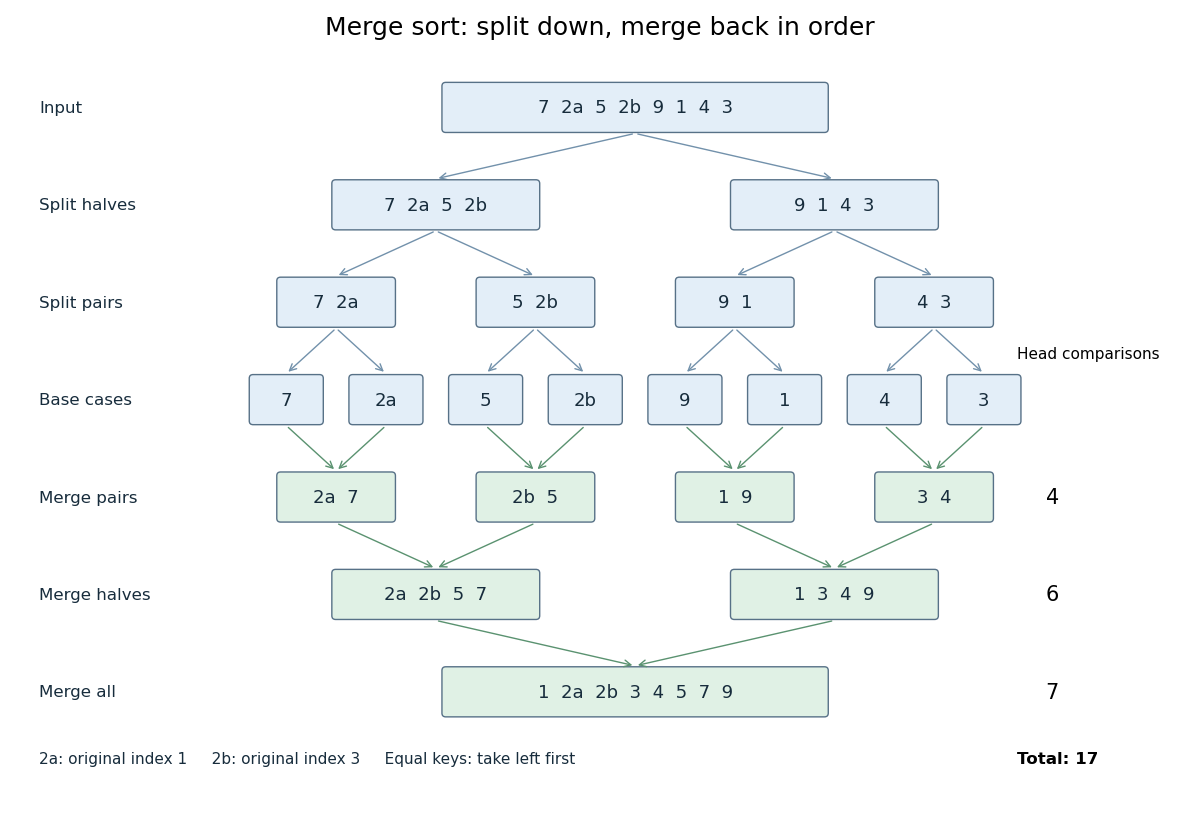
The first two halves are and . Their pairs split into one-entry base cases. Applying the merge algorithm gives the following fully worked return levels; each number in the last column counts only comparisons between two available heads.
| Returning level | Resulting sorted arrays | Head comparisons |
|---|---|---|
| Pairs | , , , | |
| Halves | , | |
| Whole array |
In the left-half merge algorithm, the head pairs are , and ; it takes , then appends . In the final merge algorithm, the head pairs are , , , , , and . It takes , then appends . Thus this precise version makes head comparisons and, ignoring identity tags, returns .
The elegance of merge sort is that it creates exactly the structure its next step needs: two smaller sorted arrays make the larger ordering inexpensive. Once the whole array is sorted, equal keys are adjacent and binary search can serve repeated queries. Stable sorting also retains information that the keys alone do not express. If the left-half merge algorithm instead takes the right head on the tie, it returns ; the keys are sorted but stable sorting has failed.
For time complexity, assume each key comparison, entry access and entry copy has constant cost. The merge algorithm processes entries in time. In Big O notation, the resulting recurrence relation isFor , the balanced levels contain entries each and there are returning levels. Each costs , so the worst-case time complexity is . For arbitrary , there are at most returning levels, each processing at most entries, giving the same bound. The worst-case number of head comparisons is also . Here is the base-two logarithm. The MIT notes give this level-by-level analysis for merge sort.[ref]
https://ocw.mit.edu/courses/6-006-introduction-to-algorithms-spring-2020/6d1ae5278d02bbecb5c4428928b24194_MIT6_006S20_lec3.pdf. MIT 6.006 (2020), lecture 3, page 5: merge sort analysis
The conventional array implementation uses a reusable buffer of entries for the merge algorithm, together with pending calls for recursion. Its auxiliary space complexity is therefore , beyond the original array. This bound describes that implementation. A linked list permits a merge algorithm that reconnects existing nodes; its storage accounting differs from copying array entries into a buffer.
For a short algorithm correctness outline, the empty and one-entry base cases are sorted. Assuming recursion correctly sorts both shorter halves, the merge algorithm returns all their entries in order. Equal keys within a half keep their relative order by the same argument applied to the smaller call; across halves, every left entry originally preceded every right entry, so taking left first preserves stable sorting. Both half-lengths decrease for , establishing termination.
Stable sorting preserves the original relative order of entries with equal keys. The entries may carry different names or other information even when their keys coincide. For example, sorting records by the numerical key gives : Ada remains before Cy. This is useful when a previous ordering contains information worth retaining, such as arrival order among equally ranked requests.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact