Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article

Radix sort sorts encoded sort keys a digit at a time. Its least-significant-digit version uses stable sorting on each successive digit, often by counting sort. For digits with possible values each, it takes time complexity in Big O notation, assuming constant-cost digit extraction and indexing. Stable sorting retains the ordering established by earlier digits when a later digit ties. Both digit access and the direct indexing in counting sort lie outside the comparison sort model, so these bounds do not contradict the comparison sorting lower bound.[ref]
Counting sort uses integer sort keys in directly as indices into an array of counts. Constant-cost counting and indexing give time complexity in Big O notation. To retain complete sorting records, cumulative counts locate their output ranges; filling each range from its end while scanning the input backwards gives stable sorting. Emitting bare sort keys from counts would discard associated data. The term matters when the key range is large.[ref]
11.2 Counting Sort and Radix Sort. Open Data Structures: An Introduction by Pat Morin; Theorem 11.7 and stability
For an original worked example, take complete sorting records and possible integer sort keys:The letters label the associated data, and are never compared. Both input and output array indices start at zero, so their valid positions are ; the count array has array indices . Stable sorting must produceThe equal-sort key groups retain and in arrival order. Counting sort prefix ranges explain where those groups belong; stable record placement in counting sort explains how to fill them without losing that order or the complete sorting records.
A comparison sort learns the ordering of sort keys only by comparing pairs. The keys are otherwise opaque: their numeric values, digits or encodings cannot choose an array index or a branch. It may move complete sorting records and retain previous answers. Merge sort and the adjacent-swap insertion sort are comparison sorts; counting sort and radix sort exploit additional information.
Insertion sort grows a sorted prefix of an array one entry at a time. In the adjacent-swap version, start with position , compare its current sort key with the preceding sort key, and swap the complete sorting records only when the right sort key is strictly smaller. Continue leftward until no swap is needed or the entry reaches position zero; then process original position . A tie stops the pass. This is the strict comparison and exchange rule in the authored implementation.[ref]
Take , where the subscript labels a complete sorting record and comparisons inspect only its sort key. Starting from index zero, the complete key-comparison trace is:
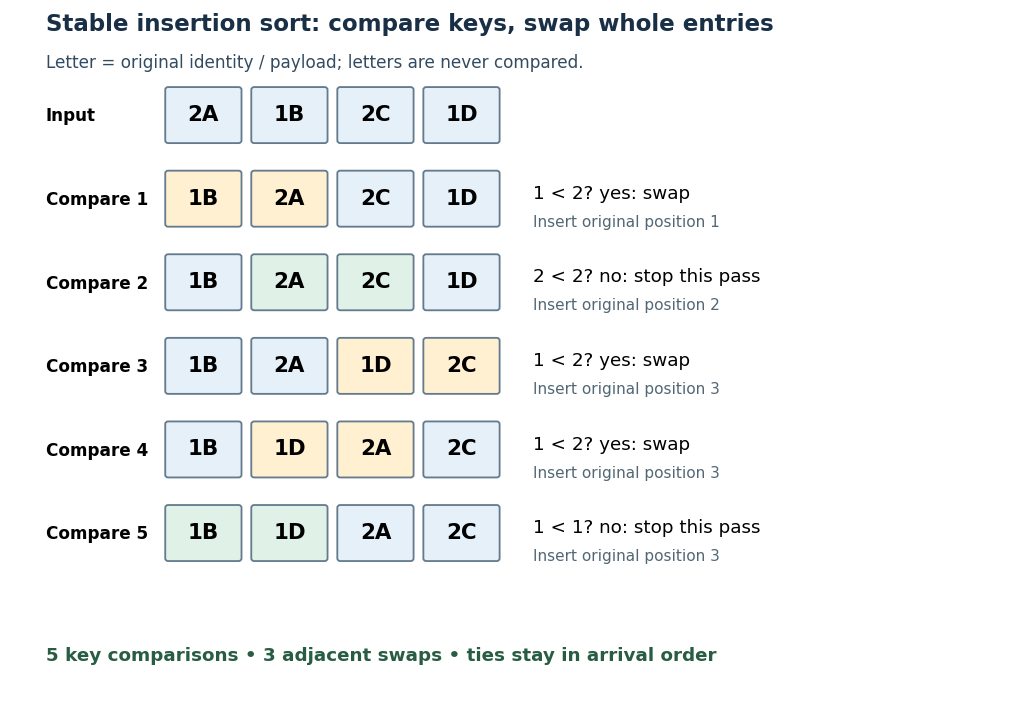
The loop invariant is that, before pass , positions satisfy sortedness and contain precisely the entries originally in that prefix. Moving the next entry left through strictly larger sort keys extends that prefix, and every swap retains sorting permutation preservation. Equal-key entries never cross, giving stable sorting. Each leftward step decreases the position, and each completed pass increases the prefix length, so the algorithm terminates.
With constant-cost key comparisons and swaps, reverse-ordered distinct sort keys cause comparisons and swaps. Thus worst-case time complexity is in Big O notation. An already sorted array needs only key comparisons for and no swaps. The adjacent-swap version uses constant auxiliary space complexity. Small or nearly sorted arrays can therefore make insertion sort useful despite its quadratic worst case.
The output of a sorting algorithm must be a permutation of the complete input sequence. For equal lengths , require a permutation of such thatEquivalently, the input and output have the same multiset of complete entries: each entry has the same multiplicity. Equality of the underlying sets is insufficient; and have the same set of values and the same length but different multisets. When tracking occurrences rather than contents, retain original identity labels to check that each one is moved exactly once. A swap preserves this multiset automatically; an overwrite need not.
For an output sequence of length , sortedness meansunder the chosen total order on sort keys. Its transitivity also gives whenever . An empty sequence and a one-entry sequence satisfy sortedness without any adjacent comparison. For longer sequences, checking adjacent pairs suffices; checking only the first and last sort keys does not. For example, passes an endpoint comparison but fails sortedness at . Sortedness alone says nothing about which input entries survived.
A sort key is the value extracted from a complete entry to determine its ordering. Model extraction as a function into a total order; compare and , while moving the complete entries. Ordering sorting records by an age field does not also compare their names. Repeated sort keys are allowed, so this induces equal-key groups even when the complete sorting records differ. Keep the sort key function and the comparison rule fixed throughout a sort; inconsistent comparisons need not admit any sorted result.
Dilution lowers a solute's concentration by adding solvent. For conserved amount of substance, molar concentration satisfiesBoth and are chemical solution volumes; is the final total, not the added solvent.[ref]
The proof is simply the definition applied before and after. Its useful assumptions are full transfer of the selected portion, no loss or gain of the counted solute, and complete mixing. An ideal chemical solution approximation is not required for this inventory equation. If chemical equilibrium redistributes dissolved chemical species, use a conserved analytical concentration or chemical element inventory rather than assuming each individual species is conserved. This conservation statement does not by itself preserve the pH: a chemical equilibrium may change as the chemical solution is diluted.
A solvent is the component designated as the medium of a chemical solution, commonly the component present in greatest proportion. Water is a common solvent, not a necessary one. A mixture of mostly ethanol with a little water can designate ethanol as solvent and water as solute. Chemical solutions can also be gas or solid mixtures; molecular nitrogen is the principal medium of ordinary well-mixed air. When proportions are comparable, state the convention explicitly.[ref]
The solvent is part of the final sample. Choosing it influences solubility and solvation; measuring its added volume alone does not determine the final chemical solution volume. Solvent and solute masses add in a closed account, whereas the final volume should be measured rather than inferred by adding pre-mixing volumes.
A solute is a component of a chemical solution distinguished from its solvent, typically present in a smaller proportion. There can be several solutes. A concentration must name both what is counted and the denominator: molar concentration uses amount of substance per final chemical solution volume; a solute-to-solvent mass ratio has another denominator.[ref]
“Added sodium chloride” and “dissolved sodium cations” describe different levels of the same inventory. Dissociation of an ionic compound changes the grouping of the particles; it preserves their chemical elements. A dissolved ion remains an ion, and dissolved sucrose remains molecular unless a separate chemical reaction occurs. Thus the name of the weighed solute need not be the name of every dissolved chemical species.
The concentration-based ionic strength is , where is each dissolved ion's concentration and its signed electric charge number. It has the same units as ; some formulas instead use the dimensionless ratio . All dissolved ions contribute, including those that balance the electric charge of a buffer solution's conjugate base. Ionic strength helps describe the interactions represented by activity coefficients. See Hippler and Metcalfe, activity coefficients and dimensionless ionic strength.
For a zero-mean stationary rough height, the mean first-order correction vanishes. At second order, the boundary derivative is . Averaging this expression using the power spectrum of surface height gives the displayed coherent reflection coefficient. Thus the root mean square height alone does not fix the coherent mean: the height correlation spectrum matters. For roughness varying slowly enough that in the integral, . A local random-height phase average needs this additional approximation and is not a general consequence of stationarity.
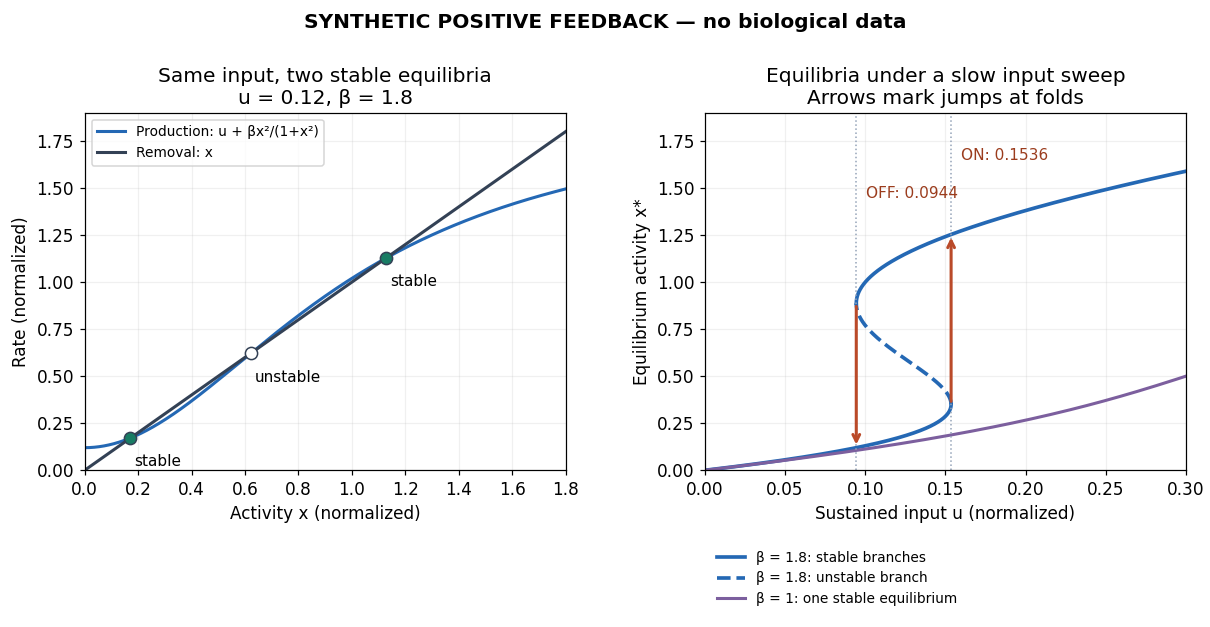
Positive feedback closes a causal loop whose net effect reinforces an initiating change. A loop with two inhibitory links can therefore have positive feedback. In signal transduction, a product that increases the activity of the enzyme making it illustrates reinforcement; the consequences depend on the full mathematical model, not just the loop sign. See signaling feedback.
A biological example is cell-cycle activation feedback. Cyclin B binds Cdc2, whose activity promotes activation of Cdc25; Cdc25 removes inhibitory phosphorylation from Cdc2, permitting further activation. Cdc2 also inhibits Wee1, an enzyme that inhibits Cdc2 through phosphorylation. That second return contains two inhibitions and therefore also has positive feedback. These are regulatory paths, not a claim that every connection is a single direct molecular encounter. [ref]
Reinforcement can preserve a decision after its initiating stimulus weakens: returning from the high state may require a lower input than entering it. The cell-cycle hysteresis experiment below tests this history dependence at matched cyclin B concentrations. A steep response alone is insufficient evidence of bistability, and finite observation times can make slow relaxation look like memory. A proposed switch must specify its input, readout and observation interval.
Negative feedback closes a causal loop whose net effect opposes an initiating change. In signal transduction, activation followed by a downstream inhibition of the earlier activating stage is one example of negative feedback. Loop sign alone does not establish asymptotic stability or complete signaling adaptation; see the worked signaling feedback example.
A useful biological example is chemotaxis feedback regulation: an Escherichia coli biological cell adjusts its response to a sustained attractant instead of remaining at its immediate response. Increased CheA activity promotes CheB phosphorylation; CheB reverses receptor methylation, opposing their activation. After attractant addition, reduced activity instead favors receptor methylation by CheR, restoring activity. This is a return from receptor activity to the machinery regulating that activity. The response need not return exactly at every dose. [ref]
A motivating measurement is the chemotaxis FRET assay. CheY and CheZ carrying yellow and cyan fluorescent tags were observed in immobilized Escherichia coli biological cells on a coverslip in a flow chamber. Adding and removing attractant changed the yellow-to-cyan emission ratio, reporting the association of phosphorylated CheY with CheZ. This measures a molecular readout upstream of motor behavior. Comparisons with biological cells lacking CheR, CheB, or both tested the dependence on receptor modification; these perturbations also change starting activity and sensitivity, so they are not pure changes of one feedback gain. [ref]
The later chemotaxis feedback regulation experiment used only the Tar receptor and nonmetabolizable methylaspartate, supplied and removed by flow. Long recordings separated slow recovery from incomplete signaling adaptation; correction for bleaching addressed drift in the optical readout. Activity recovered incompletely after sufficiently large additions, with detectable imprecision already at in that preparation. Restricting the receptor type and preventing consumption of the stimulus help interpret the perturbation, but limit transfer to other receptors and conditions. The readout infers CheA activity through CheY-CheZ association, rather than directly measuring every molecular step. [ref]
Negative feedback can also overshoot or sustain oscillations if its return arrives too late. The worked signaling feedback example gives the contrasting instantaneous case; the delayed negative feedback model below isolates the effect of timing. Loop sign describes causation, while asymptotic stability describes what happens to displacements over time.
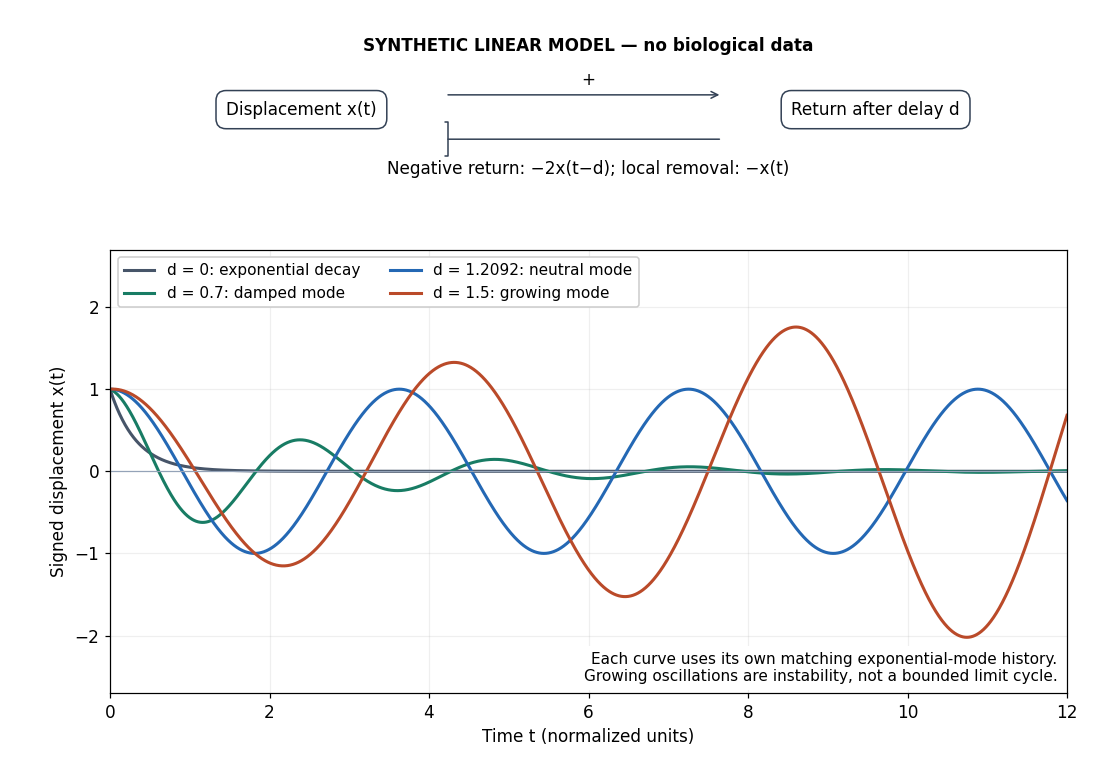
Negative feedback with an instantaneous or delayed return
. Original synthetic delay differential equation modes, not measured chemotaxis responses. All variables and time are normalized. The same negative return coefficient is used throughout; only its delay changes. Each curve has its own matching history. A growing oscillation signals instability of this linear mathematical model, not a bounded biological rhythm. Details.Noise is unwanted variation in a signal. Whether a component is unwanted depends on the measurement task: suppressing fast variation helps only when that variation is expendable. White noise provides one mathematical model; it does not describe every source of disturbance. A linear filter may reduce some noise while also altering the desired signal.
A discrete-time signal assigns a value to each of a discrete collection of times, often indexed by the integers. Regular sampling at rate gives , so a sinusoid with normalized frequency cycles per sample has physical frequency . Discreteness of time does not itself require the amplitudes to be quantized; rounding the values is an additional operation. The Nyquist–Shannon sampling theorem gives conditions for recovering a band-limited continuous signal from its samples.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact