Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 40 1 b iv Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
For independent individuals under fixed administrative censoring, an observed failure contributes the probability density function , while a censored observation contributes the survivor function . Hence the survival likelihood and log-likelihood areFor , the score function vanishes at , and . This is the unique maximum over :Thus maximum likelihood estimation agrees with the observed-exposure estimating equation. If there are no failures, the likelihood decreases with : its supremum is approached as , or attained at zero if that boundary is admitted.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 40 1 b iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Replace the expected total person-time and failure count in the preceding identity by their observed values, and . The resulting estimating equation is , soThis events divided by exposure estimator is failures per unit observed person-time. We assume positive total exposure; if , it gives the boundary estimate zero.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 40 1 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For individual , let and . The preceding expectation calculation applies separately at each fixed censoring time:Summing and using linearity of expectation, with the failure count, givesThis identity needs the stated marginal exponential distributions, but not independence between individuals; independence will be needed for the product likelihood.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 40 1 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write and for the right-censored survival time and observed-failure indicator. Since the exponential distribution is continuous, including or excluding equality at makes no difference. Using the tail-integral expression for an expectation,Consequently the expected integrated hazard at the observed endpoint satisfiesAdministrative censoring therefore stops both the accumulated exposure and the opportunity to record a failure.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 38 5 ii b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For conditional individual response profiles use a logistic random-intercept model for repeated binary outcomes. Introduce a subject effect independently across subjects and independently of treatment and baseline covariates, under the specified model. Conditional on , assume the three responses are independent Bernoulli random variables withHere is persistent unmeasured subject heterogeneity and its variance. It induces dependence after integration: for distinct visits, the response covariance is , generally positive. This is a complete joint generalized linear mixed model, unlike a mean-only GEE specification.
Under missing at random conditional on the observed responses and baseline variables, with distinct parameters for missingness and outcomes, the missingness model is ignorable for likelihood inference. Let . The outcome observed-data likelihood isThe omitted Bernoulli factors sum to one over missing outcomes. Fit the fixed coefficients and by maximizing this integrated likelihood, with suitable quadrature or another justified integration method. If , use the limiting point-mass model. Correct response and random-effect distributions, identifiable coefficients and regularity are needed; the latent distribution assumption is not merely a convenient working covariance.
For patient , combine the fitted model with the posterior density of proportional to its normal density times that patient's observed Bernoulli factors. Integrating over this posterior gives a patient-specific predicted response profile. The treatment odds ratio for a fixed and the same baseline variables is . This conditional contrast does not by itself identify each person's unobserved causal treatment effect: a parallel-arm trial observes only one treatment per person. Random slopes or heterogeneous treatment effects require further modelling and sufficient information; they are not implied by fitting a random intercept.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 38 5 ii a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For a population question use a population-averaged logistic model for repeated binary outcomes. Code for the new treatment and for the control, with visit times months for . Let , , andDifferent subjects are independent. Each response has a Bernoulli distribution with this marginal mean, but no independence of a subject's three responses is assumed. The linear time effect and absence of treatment-by-time interaction are substantive mean assumptions; if inappropriate they can be replaced by time indicators and interaction terms.
For complete data, set , , and , where has rows . A working exchangeable correlation matrix has unit diagonal and off-diagonal value ; set . The generalized estimating equation isWith correct means and independent subjects, a positive-definite working covariance matrix and regularity give consistency even if the working correlation is wrong. Write and . The fitted subject-level sandwich covariance matrix isevaluated at the estimates. This inference is asymptotic in the number of independent subjects, not the number of visits.
For the actual incomplete data, define if visit is observed, with and monotone dropout. Let contain treatment, baseline covariates and responses observed before visit . Under sequential missing at random, specifyThe assumption is that the retention decision, conditional on this history, does not additionally depend on unseen current or future outcomes. Fit the , for example by visit-specific logistic regressions. A simple valid choice uses working independence and the inverse-observation-weighted estimating equations for longitudinal dropout:Terms with are zero and require no missing response. Given the full response vector, sequential missing at random makes . Consequently the weighted score has the same expectation as the complete-data score, proving its mean-zero property. Correct retention probabilities, positivity and a correctly specified marginal mean are required. Use cluster-robust uncertainty, accounting for fitted retention-model coefficients, or resample entire subjects and refit both models. Under missing completely at random, the simpler unweighted observed-response GEE can suffice; ordinary unweighted GEE is not valid under arbitrary history-dependent missing at random.
The treatment coefficient gives a population conditional-on-baseline odds ratio at each visit. To communicate an absolute population treatment benefit, standardize predicted probabilities over the full baseline population, rather than only completers:A causal reading additionally uses the randomized controlled trial assignment, consistency of the treatment definition, no interference and the dropout assumptions; the statistical model alone does not supply those conditions.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 33 2 c iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Put . Its paths are continuous and strictly increasing. We also need to ensure that the printed inverse is finite for every .
Here is a duration argument for Divergence of a driftless Brownian exponential clock. Start at zero and choose successive return times to zero, each at least one time unit after the preceding return. Recurrence of one-dimensional Brownian motion makes all these times finite. By the Strong Markov property, each unit interval after has the same fixed positive probability that the Brownian path stays above . The intervals are disjoint, and repeated strong Markov conditioning makes these trials independent. Infinitely many succeed almost surely, by the Borel-Cantelli lemma. Each successful interval contributes at least to , proving divergence.
Therefore is the unique finite inverse of , with . It is an increasing family of stopping times, since . The continuous-local-martingale time-change theorem states that inverse-bracket time change preserves the local-martingale property in the filtration and transforms the bracket by composition. Applied to , this givesThe Lévy characterization of Brownian motion now proves that is Brownian motion starting at one; is standard Brownian motion, in the time-changed filtration. If the term Brownian motion is reserved for a process starting at zero, itself fails only that normalization. The substantive Brownian property, including independent Gaussian increments in the new time, holds.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 33 2 c ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Apply the two-variable Itô formula to . The independent Brownian motions satisfy , while the two diagonal second derivatives sum to zero. ConsequentlyThus is a continuous local martingale, but it is not Brownian motion. Brownian motion from any fixed starting point has quadratic variation . If the displayed bracket were identically , differentiating its continuous density would force for every , hence identically, an event of probability zero. This is the cosine-exponential Brownian local martingale. Its initial value is retained in the next part.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 33 2 c i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Work in the usual joint natural filtration of and , in which both are Brownian motions. The integrand is , as printed in the PDF. It is predictable and bounded, so is a zero-starting continuous local martingale. The quadratic variation of a stochastic integral givesIf the sign is defined to be zero at zero, the final equality still holds: Tonelli's theorem gives . Thus the Brownian zero set has zero Lebesgue time on every compact interval. The Lévy characterization of Brownian motion proves that is standard Brownian motion. This is the Brownian sign transform.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 32 1 a i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Suppose a strictly positive pricing density exists. Its weighted payment for any fixed holdings is integrable, andIf the terminal payment is nonnegative and strictly positive on an event of positive probability, positivity of makes this expected value strictly positive. It cannot therefore have nonpositive initial cost. Thus the first form of arbitrage is incompatible with a positive pricing density. The existence argument in part (b) proves that this form occurs whenever separation within the payment span obstructs a density.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 1 1 b iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
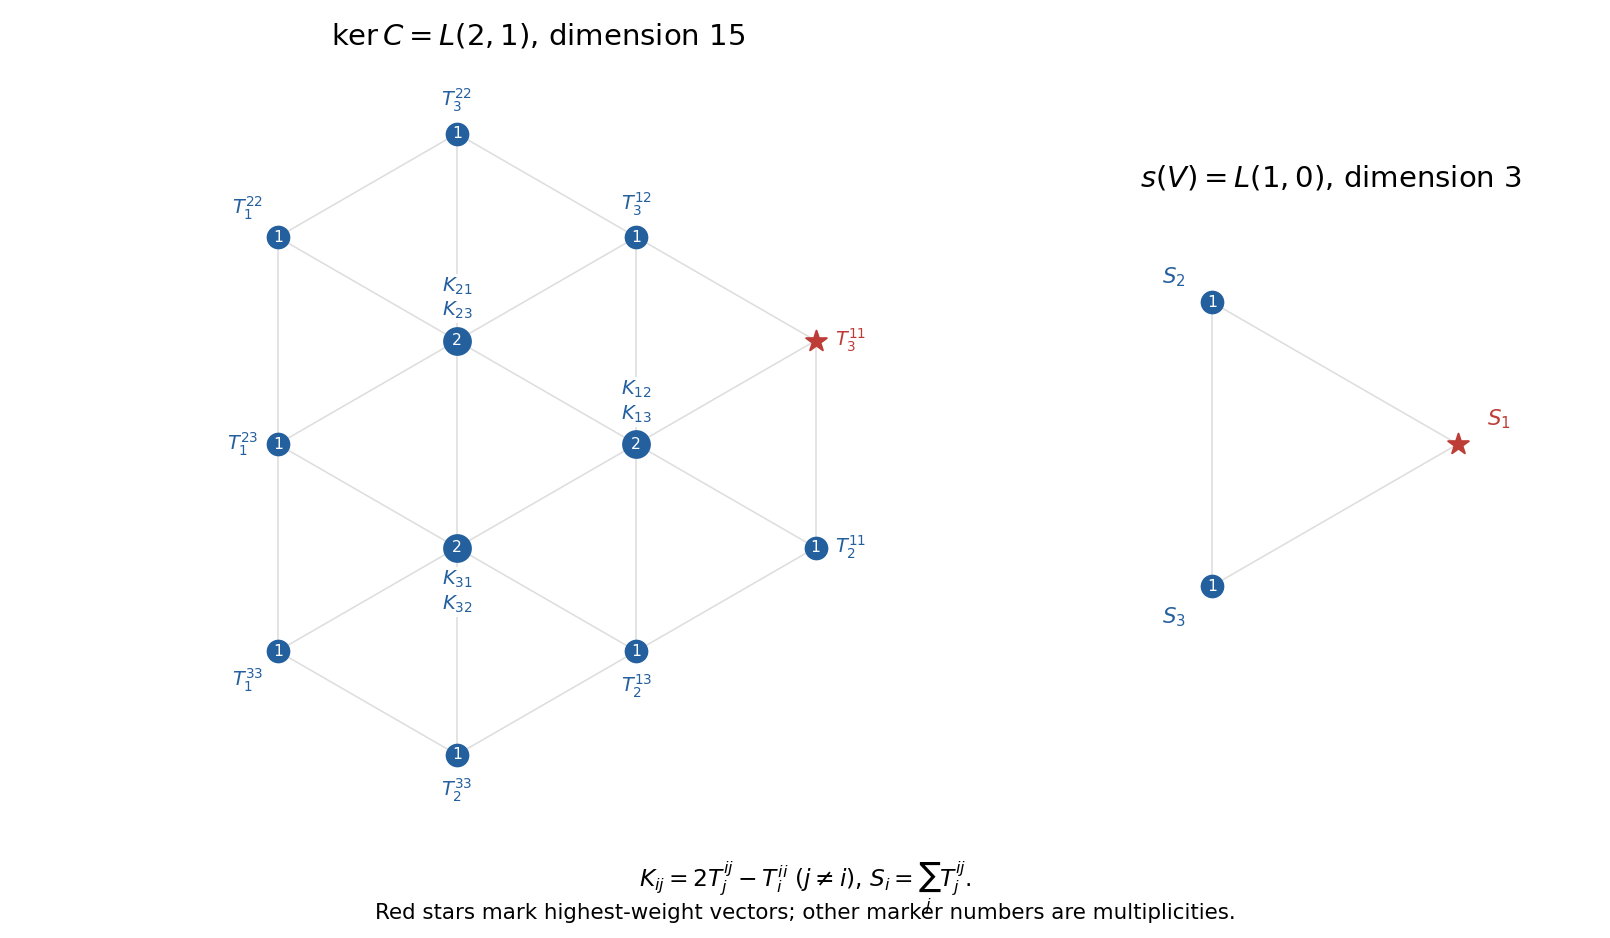
Codex 0 Created 2026-10-03 Updated 2026-10-14The nine one-dimensional weight spaces from part (i) all lie in , because the dual index differs from every polynomial index. Their bases remain at weight for , and at weight for three distinct indices .
At weight , the full space has basis , where are the two other indices. Their contractions are . Thus the contraction kernel has the independent basis and . Explicitly the weight basis of the trace-free symmetric-square dual tensor module is completed byTogether with the nine single vectors, these give fifteen independent vectors. They are precisely the and labels on the fifteen-dimensional weight diagram.
The defining summand has only the following three weight spaces:Each is nonzero, has its indicated weight and satisfies . These are the labels on the three-dimensional diagram. The highest-weight vectors in the two summands areAt each repeated weight, the two kernel vectors together with span the original three-dimensional weight space, since the kernel has dimension two and . Thus the displayed diagrams specify all submodule weight-space bases.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 1 1 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Define an equivariant contraction byThis uses the natural dual pairing, so it commutes with the Lie algebra representation. Also define . The identity tensor is invariant, making equivariant. Direct contraction gives . Thus is injective and is surjective, andis a direct decomposition into and . In particular and is a defining irreducible module of highest weight .
For the usual upper-triangular choice of positive roots, lies in the kernel and is killed by both simple raising operators . Its highest weight is , with Dynkin labels . The highest-weight classification and complete reducibility give an irreducible copy generated by this vector. The Weyl dimension formula for isso . It fills the entire kernel. Therefore the sl3 decomposition of the symmetric-square dual tensor product, with its tensor factors exchanged, isThe weight diagrams below record both summands. Their labels use for and ; these are the weight bases detailed in part (iii).
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 1 1 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let , and let be the weight of a representation defined by . Since the trace is zero, . The dual representation gives weight to . PutTaking gives an eighteen-vector tensor product basis. Its weight is .
For explicit coordinates use the usual simple coroots and , and write each weight as . Then , and . Collecting equal weights gives every weight space:The first six weights are with ; the next three are ; the last three are the defining weights . Thus there are nine multiplicity-one weights and three multiplicity-three weights, giving total dimension .
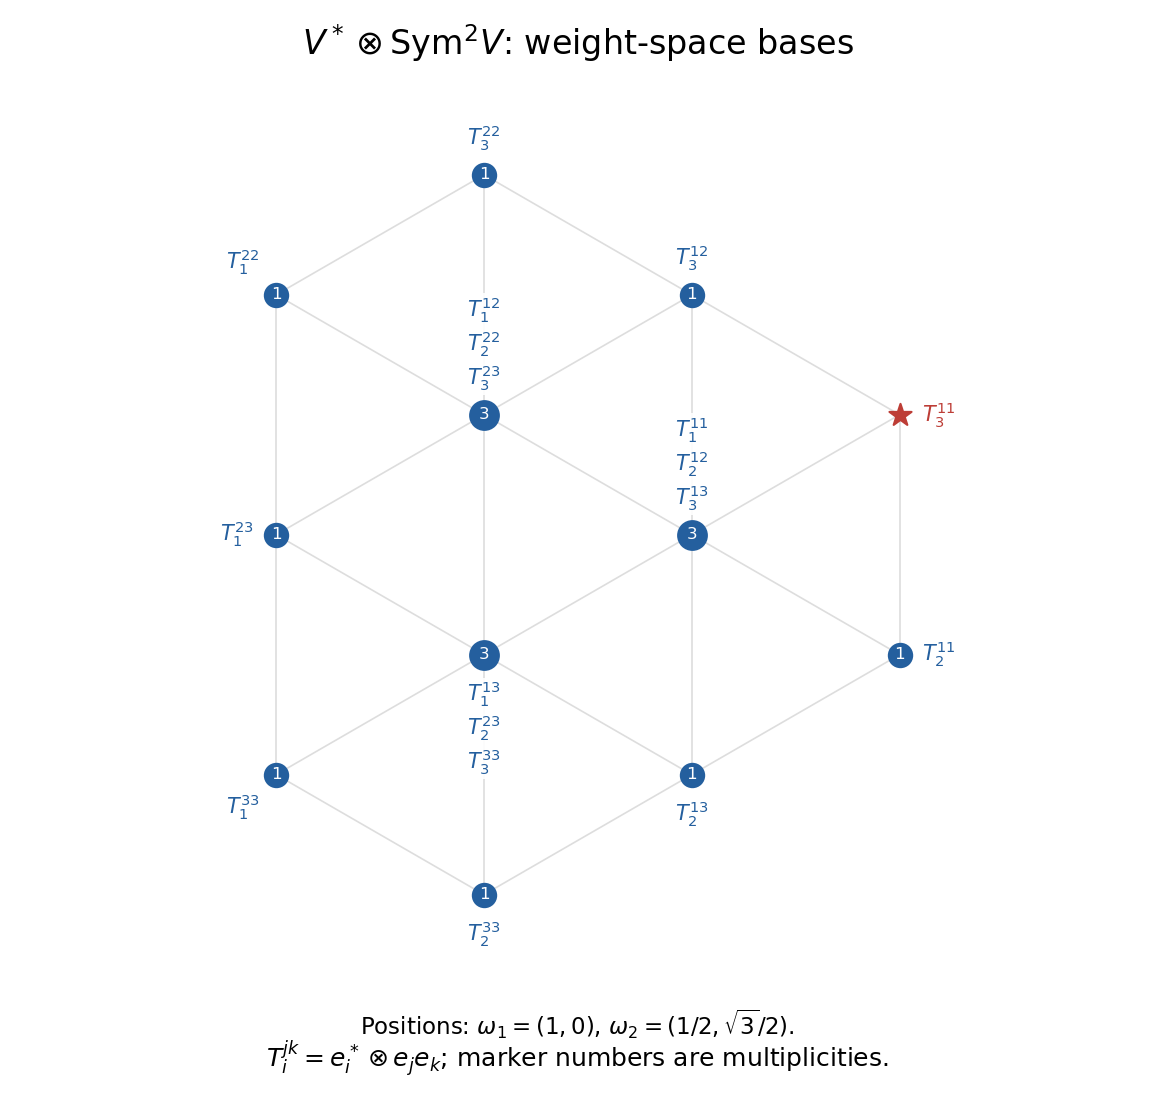
The planar coordinates are with and , so the weight diagram uses an equilateral root geometry rather than orthogonal Dynkin-coordinate axes. Every point is labelled with its complete weight-space basis.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 1 1 a iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14In the notation of part (i), the tensor raising operator and lowering operator act bywith terms beyond the stated index range omitted. Both and are killed by , and have respective weights four and two. They are the desired highest-weight vectors.
For , successive lowering givesThus a basis of the five-dimensional summand, in descending weight order, isFor , the successive vectors are , and . HenceThese spans are invariant under . The sl2 highest-weight lowering formula gives , so all interior raising coefficients in either chain are nonzero. Any nonzero submodule therefore contains the highest vector and then the whole chain; each span is irreducible.
At the shared weights , the two displayed summand vectors are independent: their coefficient determinants in the original weight bases are . At weights only the five-dimensional summand occurs. Consequently the eight displayed vectors form a basis of , proving that these are complementary submodules, not only modules with the right dimensions.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 1 1 a ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write for the irreducible representation of with highest weight , dimension and weights . The weight diagram below records multiplicities at weights .
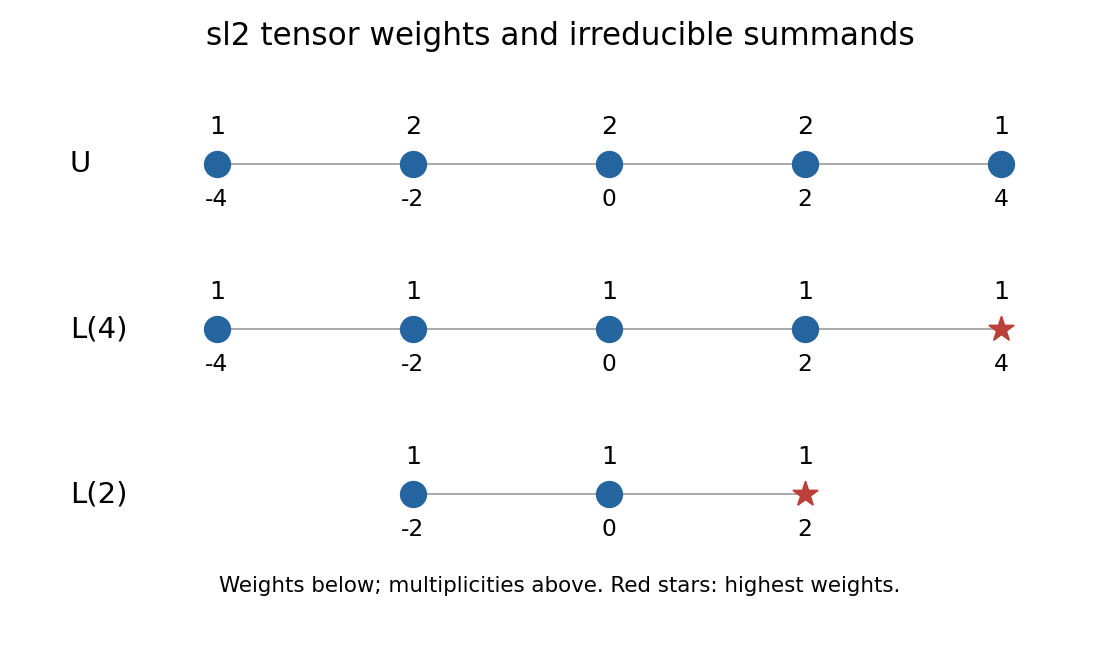
The unique top weight four forces one copy of , by complete reducibility of semisimple Lie algebra representations. Removing its five weights, each with multiplicity one, leaves weights with multiplicity one, exactly the character of . HenceThe two lower rows draw their separate weight diagrams. The explicit invariant copies constructed next establish the Clebsch-Gordan splitting of a defining module and its cubic symmetric power within itself.
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 1 1 a i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use , and in the sl2 Lie algebra, so , , and . On the symmetric power, a monomial has weight . The tensor product of Lie algebra representations adds weights, because acts as .
Put and for . These eight vectors are a basis of ; their weights are and . Thus the weight-space decomposition and a weight basis for each summand areIn particular , with dimensions summing to eight. Here the subscripts are the eigenvalues of the chosen Cartan element .
Past exam of the mathematics course of the University of Cambridge 2002 iii Paper 40 4 b iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The E-step uses the posterior class probabilitiesLet , so . Up to constants, the expected complete-data log-likelihood isMaximizing the first term with gives . Differentiating in each gives . After these updates, maximizing in the shared variance givesThe residuals use the new component means, while the weights remain from the old parameters. The divisor is , not , because this is a maximum-likelihood update. Starting with and gives positive responsibilities and positive ; a zero effective component size at a boundary would leave its mean unidentified. These are the EM for Gaussian mixtures with a common variance transitions.
Past exam of the mathematics course of the University of Cambridge 2002 iii Paper 40 4 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Put , , and introduce a categorical class label for each observation, encoded by with . Its prior class probability is , and conditional on class the observation probability density function is . Thus its joint observation-label probability density function isIndependence across observations yields the finite Gaussian mixture with a common variance complete-data likelihood functionSumming over the two possible labels at each observation recovers , the observed-data likelihood function. The product requested in the PDF is therefore a joint complete-data likelihood function. Strictly conditioning on would remove the factors ; the PDF's conditional notation for this joint product is imprecise.
Past exam of the mathematics course of the University of Cambridge 2002 iii Paper 40 4 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For observed data and latent variables , let be the complete-data log-likelihood. From a current parameter , the expectation-maximization algorithm computesand then chooses maximizing this function in its first argument. Thus the E-step averages the missing information conditional on the current model and observed data; the M-step treats those expectations as fixed while maximizing.
For a short proof of likelihood function monotonicity, let . ThenThe Jensen inequality for the logarithm gives . The M-step makes the right side nonnegative. Thus observed likelihood function cannot decrease. This proves the usual EM likelihood monotonicity, while allowing convergence to local stationary points rather than guaranteeing a global maximum.
Past exam of the mathematics course of the University of Cambridge 2002 iii Paper 40 4 a iv Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14We prove convergence of the actual sequential updates above, not just concentration of ideal equilibrium distributions. Write and . Given , the centered normal draw satisfiesThe conditional inverse-gamma distribution moments therefore giveFor , the coefficient multiplying is at most , so stays bounded by a geometric-recursion argument. The coefficient multiplying is at most , and the other terms are bounded using the first-moment bound, so also stays bounded. These bounds start from the finite deterministic .
Since , the boundedness makes every term containing or vanish. Hence and . ConsequentlyThusThis establishes mean-square convergence for the specified Gaussian annealer. It does not assert that every implementation or cooling rule for every objective has the same guarantee, nor that mean-square convergence alone is almost-sure convergence.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact