
At sample size 100, keep essentially the same numerical confidence interval, but treat its calibration as approximate. For independent heights with finite, nonzero variance, the central limit theorem makes the sample mean approximately normally distributed, and the sample variance consistently estimates the population variance. Hence the studentized sample mean is approximately standard normal even without a normal distribution for individual heights.
Using the permitted cutoff 2 givesA Student t-distribution cutoff gives a similar approximation for large sample size, but its justification at fixed sample size is no longer exact. Extreme skewness or influential outliers could make 100 observations insufficient for accurate coverage probability; abandoning normality alone supplies no specific numerical correction. The sampling with replacement assumption still precludes a finite population correction.
The independent uniform choices from the student list describe sampling with replacement. Under the stated independent normal distribution model for the heights, the population variance is unknown and the given cm is the sample standard deviation . The exact pivotal quantity isThus the exact 95% Student t confidence interval isusing . The supplied approximation instead gives a normal approximation for large sample sizeThis latter confidence interval is approximate even under normality because it substitutes the sample standard deviation for the unknown population value. There is no finite population correction under the specified independent selections. Interpreting the finite student list literally as a discrete population makes normality an idealized model; it does not justify changing the stated sampling design.
It is single-linkage clustering. Its intercluster distance is the smallest cross-pair Euclidean distance. Successive nearby points can join around the ring and within the dense central cloud before any edge crosses the gap between them. Equivalently, at a threshold below the between-group gap but above the lengths needed to connect each group, the single-linkage clustering components are precisely the central group and the ring.
Complete-linkage clustering uses the largest cross-pair Euclidean distance. Opposite points on the ring are far apart, so an intact ring has a large diameter. That rule favors compact pieces and can attach a ring segment to the center before all ring segments join. The visible gap and short links within each group explain why single-linkage clustering recovers the two intended clusters in cluster analysis in this example; it is not a universal guarantee for arbitrary noisy rings.
With two distinct centroids, K-means clustering assigns points on opposite sides of their nearest-centroid decision hyperplane, which in two dimensions is a straight line. This constraint explains the typical outcomes in the three source plots; exact assignments depend on initialization and the realized points.
Dataset A: one cluster in cluster analysis contains most of the horizontal cloud and the bottom of the vertical cloud; the other contains the upper part of the vertical cloud. The two visually elongated groups are poorly matched to squared Euclidean distance from their centroids. Points at the lower end of the vertical group can be closer to the horizontal group's centroid, so the two original shapes need not be recovered intact.
Dataset B: a roughly straight cut divides the ring and generally the central cloud between the two clusters in cluster analysis. A Voronoi cell for either centroid is a half-plane; it cannot select a surrounding ring while excluding its center. The cut's direction can vary because the geometry is approximately rotationally symmetric.
Dataset C: the two dense lower clouds typically receive different centroids. The much smaller upper cloud is absorbed into one or divided between both clusters in cluster analysis, according to the nearly vertical separating line. With , the objective usually benefits more from separating the two large clouds than from spending one centroid on the sparse third group. These are typical qualitative outcomes, rather than guarantees about every initialization.
Complete-linkage clustering defines the dissimilarity between clusters in cluster analysis as . Remove point 6 and first merge 1 with 4 at height . The distances from to 2, 3, 5 are respectivelyThe next merge therefore attaches 2 at . Now the distances from to 3 and 5 are and , whereas . Merge 3 and 5 at . The final distance between the two remaining clusters in cluster analysis is the largest cross-entry, . Thus the dendrogram has merges
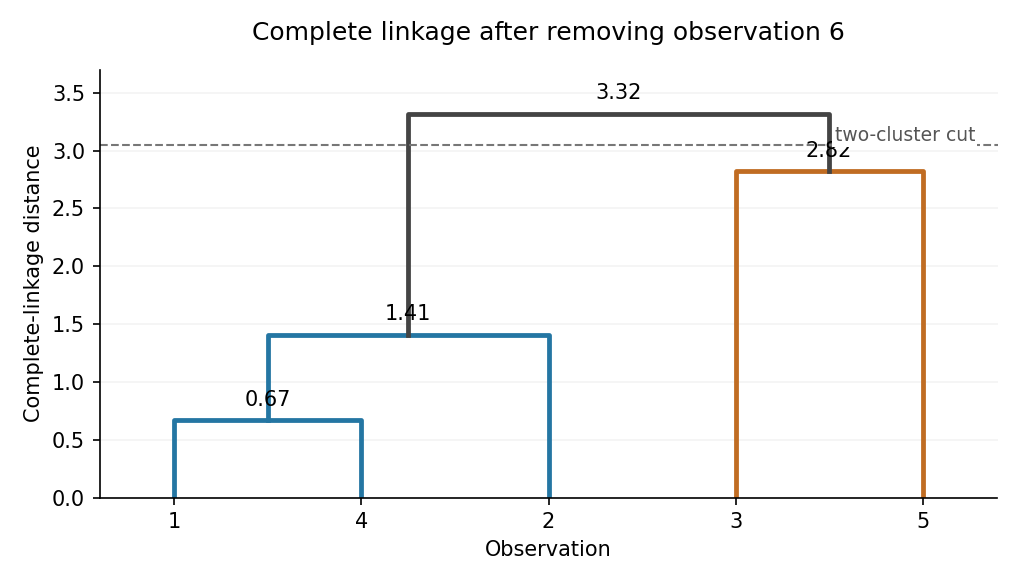

Cutting strictly between heights and gives the two clusters in cluster analysisThe figure is an original drawing of these computed merges.
Every Euclidean distance obeys the triangle inequality. The three recorded entries , and violate it:At least one of must be incorrect. Two are in the final row as required. The gap is far larger than any possible rounding of entries to two decimal places.
Compute fitted responses and regression residuals . A conventional residual plot shows against or ; plotting against observation order additionally looks for runs. One checks for curvature, changing spread and other structure rather than random scatter around zero.
An ordinary residual plot need not reveal this failure of independence. The errors have constant mean zero, constant variance one and zero pairwise covariances, so the usual trend and changing-variance clues need not appear. A visually patternless residual plot cannot validate independence; fitted regression residuals themselves also share the fitted coefficients even when the true errors are independent.
There is detectable dependence in the magnitudes. The Gaussian fourth moment is , giving for every adjacent pairFor , the product is ; for , it is , with the same expected value 3. Large magnitudes tend to occur together. A lagged plot of squared regression residuals or a test directed at dependence in their squares is more informative. Thus recognition is possible with suitable diagnostics, but is not guaranteed by the standard residual plot requested here.
The least-squares estimators depend only on the observed responses and design, so the formulas in i still hold. Their variances and covariance need only the error covariance matrix, now . ThereforeFor example the first formula follows from , and the second from . The formulas remain the same as before with ; this calculation does not establish independence or a normal distribution for the estimators.
Independence of the centered standard normal random variables gives for every . AlsoFor nonadjacent indices, the underlying sets of variables are disjoint, so the errors are independent and have zero covariance. For adjacent indices with ,The first adjacent pair separately gives . HenceThese adjacent products of independent Gaussian variables are uncorrelated random variables even though adjacent errors share a factor and are dependent.
For the random vector , its covariance matrix isIts diagonal entries are variances, and its off-diagonal entries measure pairwise covariance. Finite second moments make every entry well defined.
They need not be independent. For a counterexample take , , , and independent errors taking with equal probability. ThenEach centered estimator is zero with probability , but they are never both zero. Their zero events therefore violate independence.
A sufficient additional assumption is that the errors have a common normal distribution. The two estimators are then Jointly Gaussian, being linear combinations of the independent Gaussian random variables. Their zero covariance, established in iii, implies independence of uncorrelated jointly normal variables. Normal errors are a sufficient condition here, not a claim that no other error probability distribution could ever work.
Here . By linearity of covariance and independence,Thus the two estimators are uncorrelated random variables.
The centered design gives . By independence of the errors, their off-diagonal covariances vanish. Thus variance additivity for independent random variables givesA larger spread of predictor values decreases the slope variance for fixed error variance.
Differentiate the ordinary least squares objective in a. Its normal equations for linear least squares areUsing and givesThe Hessian matrix of the objective in is , which is positive-definite, so this is its unique global minimum. For the observed estimates, replace by .
For a geometric distribution on positive integers, the probability generating function is . Conditional averaging over the red die yieldsAs a power series, its exact domain of absolute convergence isIndeed the slowest decaying component has failure probability , so . At , the terms of the power series fail to tend to zero; outside that disk they grow. All six component series converge inside it. In particular, the probability generating function is defined on the usual real interval , with . The rational expression beyond the convergence disk is only an algebraic continuation, not the defining expected value.
By the law of total probability,Bayes' theorem therefore gives the conditional probability mass functionThe six probabilities sum to one. A small red outcome is more likely after an immediate success because more white faces can meet its threshold.
Let denote the red die. Conditional on , each white roll succeeds independently with probability . Consequently has the geometric distribution on and expected value . The law of total expectation givesThis is rolls; the averaging must be over conditional expected values, not over success probabilities before taking a reciprocal.
On the product support , the joint probability density function factors asThe equality also holds outside the support with both sides zero. The probability density function factorization criterion proves that and are independent random variables.
Obtain each marginal density by integrating the joint probability density function over the other variable:Each marginal density is zero off its displayed interval and has total integral one.
A joint probability density function integrates to one. HeresoThis value also makes the probability density function nonnegative everywhere.
There are unlisted articles, also show them or only show them.