Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Autocovariance
Autocorrelation Created 2026-09-28 Updated 2026-10-14
The autocorrelation function of a real weakly stationary process with positive variance is its normalized autocovariance:It is dimensionless, with , , and by the Cauchy-Schwarz inequality. It is unchanged by replacing with for fixed . This makes autocorrelation useful when comparing records measured on different scales. The ACF is a property of the model; the sample autocorrelation function estimates it and will generally not reproduce theoretical zeros exactly.
An AR(1) with coefficient has autocorrelations at lags one through three. With these become : the same diminishing magnitude, alternating in sign. An MA(1) with instead has lag-one autocorrelation and zero at every higher lag. Equal numerical coefficients in an autoregressive model and a moving-average model do not mean equal dependence. See Bartlett, lecture 3: theoretical ACFs and prediction.
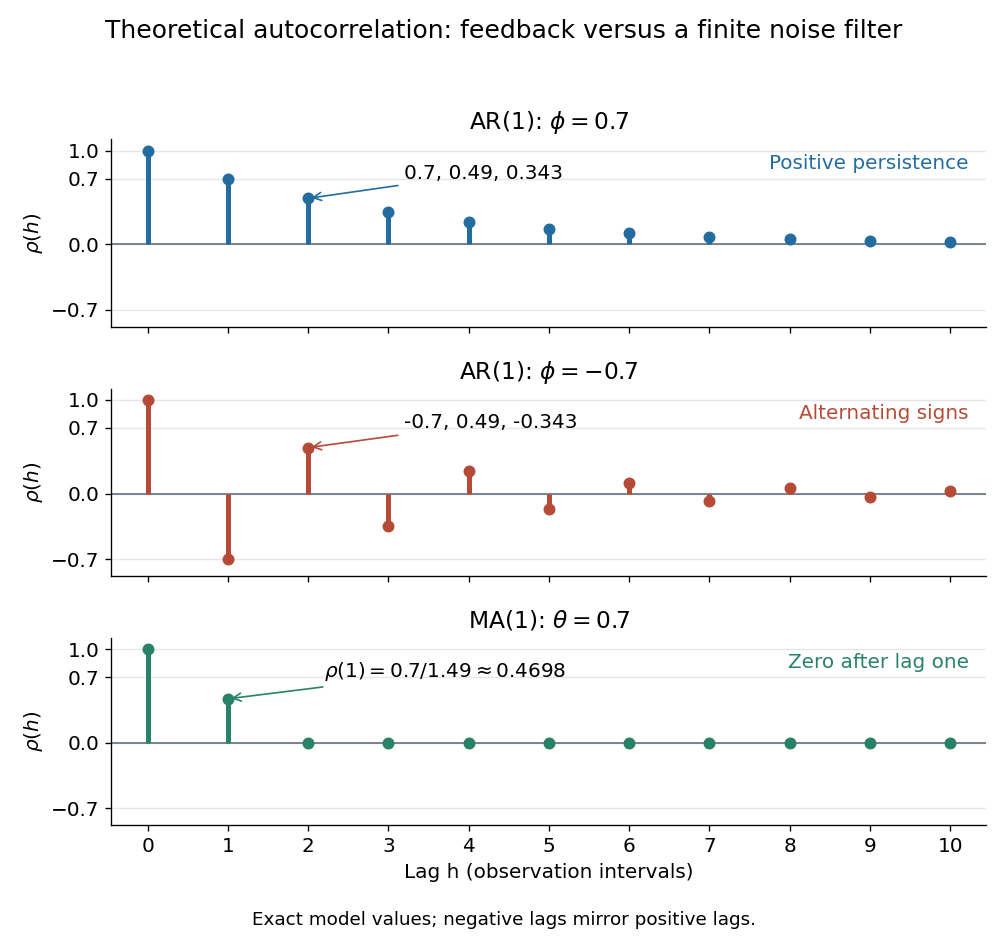
Theoretical autocorrelation: AR(1) with coefficients 0.7 and -0.7, compared with MA(1) with coefficient 0.7
. Details. 
The bars show exact model autocorrelations, not estimates from the illustrated sample paths in time series. The AR(1) retains a diminishing trace of a disturbance at arbitrarily large lags; the MA(1) stops sharing driving noise after lag one. A zero autocorrelation means uncorrelated random variables, and does not generally imply independent random variables. For a Gaussian process it does imply independence of the two coordinates.
There is a direct prediction interpretation. Among affine predictions based on just , the best linear predictor of is , with mean squared prediction error . Thus negative autocorrelation is also useful predictive information. A prediction using the whole observed past can do better; best linear prediction from a finite past describes that problem. Interpreting the affine prediction as a conditional expectation requires additional assumptions, such as a joint normal distribution.
Autocovariance Created 2026-09-28 Updated 2026-10-14
The autocovariance measures how two observations of the same stochastic process vary together. For a real weakly stationary process of mean , it isWeak stationarity removes dependence on the absolute time . Without it, the covariance function generally needs two time arguments. Lag zero is the variance, ; symmetry of real covariance gives . Positive values favor deviations from the mean in the same direction; negative values favor opposite directions. The units are the square of the observation units. See Bartlett, lecture 2: autocovariance examples.
For example, if with centered unit-variance white noise, expanding the product leaves only matching noise times. Thus , , and for . This MA(1) has a positive lag-one autocovariance because adjacent observations share one disturbance. Rescaling every observation by multiplies every autocovariance by , while leaving autocorrelation unchanged.
The autocovariance is useful beyond comparing pairs: it determines the variance of any finite linear combination of observations. For the sample mean ,Each separation occurs in pairs. For the preceding MA(1) and , this is , compared with for four uncorrelated random variables of the same variance. This is the finite-record counterpart of the long-run variance of a stationary process.
Autocovariance of an AR(1) process 2026-10-14
For the stationary causal AR(1) with , matching terms in its infinite moving-average representation gives, for ,Symmetry of the autocovariance extends this to negative lags. Dividing by gives the autocorrelation . The geometric series explains both the enlarged stationary variance and the diminishing memory: all past disturbances contribute to the present, but their squared weights have a finite sum. At , the process reduces to shifted white noise and all nonzero-lag autocorrelations vanish. See Bartlett, lecture 4: AR(1) representation and mean-square convergence.
Autocovariance of an MA(1) process Created 2026-10-07 Updated 2026-10-14
For the MA(1) , centered white noise givesOnly products of noise values with matching time indices have nonzero expectation. At lag zero there are two squared weights, and ; at lag one there is one shared noise term with weight product ; at higher lags there are none. The calculation needs zero covariance between distinct noise values, not independence. This tridiagonal finite covariance structure makes the finite-sample innovations of an MA(1) process particularly simple.
The lag-one autocorrelation can never exceed in magnitude, since . For , replacing by leaves the entire ACF unchanged. For example and both give ; rescaling the latter noise variance by also matches every autocovariance. Moving-average root reflection explains this ambiguity and why a stable invertibility convention helps identify a representation. Equality of second-order laws need not imply equality of all joint probability distributions unless the processes are Gaussian processes. See Bartlett, lecture 6: equivalent representations and covariance of ARMA processes.
For a causal autoregressive moving-average model driven by independent white noise, multiply its recursion by and take covariance. When , all driving white noise values in its moving-average term occur strictly after , so their covariances with vanish. The resulting homogeneous tail recurrence has the same characteristic roots as the autoregressive model recursion. Distinct roots of modulus below one give exponential autocovariance decay.
Existence of a time-series spectral density 2026-10-07
A weakly stationary process has a time-series spectral density precisely when its spectral measure of a stationary time series is absolutely continuous with respect to Lebesgue measure. Absolute summability of its autocovariances is sufficient and yields a continuous Fourier-series density. It is not necessary for existence; for a general integrable density, Fejér sums give an recovery formula.
Lag of a time series 2026-10-14
A lag of a time series is a separation between observation indices. In an equally spaced time series, lag compares observations three intervals apart: for hourly readings this is three hours, while for daily readings it is three days. Positive and negative lags describe the same separation in opposite directions. The autocovariance and autocorrelation of a real weakly stationary process are even functions of lag.
Local-level state-space model 2026-10-14
The latent state follows a random walk, while observations add independent measurement noise. If the two noises have variances , the differences have autocovariances at lag zero, at lag one, and zero at larger lags. For , write and . The differenced process is an invertible moving-average model with coefficient and innovation variance . Its level has a unit root.
Long-memory time series 2026-10-06
A weakly stationary process can have very slowly decaying autocovariance, for example with and . Its sample mean can require a normalization different from . Long memory is dependence over long lags, rather than a changing marginal distribution.
Long-run variance of a stationary process 2026-10-06
With absolutely summable autocovariance, the asymptotic variance of the sample mean satisfiesThe sum is signed, rather than a sum of absolute values. It can be zero: the first difference of strong white noise has telescoping partial sums. A central limit theorem needs further dependence assumptions.
Moving-average process of order one Created 2026-09-28 Updated 2026-10-14
A moving-average process of order one has the formwith centered white noise of finite positive variance . Each disturbance enters the current observation with weight and the next observation with weight , then leaves the filter. It is a weakly stationary process for every real : the mean is and the autocovariance of an MA(1) process depends only on lag. Strong white noise additionally makes it a strictly stationary process. No restriction is needed for stationarity.
For a worked observation calculation, take , , and consecutive noise values , , . Then and ; the same disturbance appears in both. If , the variance is , the lag-one autocovariance is , and the lag-one autocorrelation is . All higher-lag autocorrelations vanish, as shown in autocorrelation.
An MA(1) is useful for brief dependence caused by overlapping disturbances or measurements. Its name refers to a weighted moving sum of noise; its weights need not be positive or sum to one, and it differs from the data smoother in seasonal extraction by a centred moving average. Under strong white noise, observations more than one interval apart depend on disjoint independent noise families and are independent. Under weak white noise, the same cutoff establishes only uncorrelated random variables.
Invertibility of a moving-average model is a separate question: can the specified driving noise be recovered by a stable linear filter of present and past observations? For an MA(1) the answer, with the absolutely summable filter convention, is exactly :Thus gives a stationary MA(1) that is not invertible in this sense. At it is still stationary, but the inverse coefficients are not absolutely summable. The case is simply shifted white noise. See Bartlett, lecture 5: MA(1) and stable invertibility.
Noncausal stationary autoregression 2026-10-06
A weakly stationary process satisfying an autoregressive model can depend on future driving white noise. For with , the convergent in the sense of mean-square convergence solution is . Its autocovariance is . This is different from a causal time series.
Past exam of the mathematics course of the University of Cambridge 2002 iii Paper 40 5 Solution Created 2026-10-03 Updated 2026-10-14
For a weakly stationary process with finite second moments, let and , independent of . If , its autocorrelation function is . Given observations , one usual sample autocovariance function isThe correlogram plots against lag . The partial autocorrelation function at lag is the correlation between and after linearly projecting each onto the intervening observations. Its sample version can be calculated by solving the Yule-Walker regression equationsthen taking the last coefficient . Equivalently, use the corresponding residual correlation from the sample regressions, with a consistent covariance convention.
For a minimal causal autoregressive model of order , the population partial autocorrelation function is zero after lag , while the autocorrelation function follows an exponentially decaying or damped oscillatory tail. For a moving-average model of order , its autocovariance and hence autocorrelation are zero after lag , because observations farther apart share no driving-noise terms; its partial correlations usually tail off. These order identification by autocorrelation cutoffs patterns suggest AR or MA candidate orders. Sample cutoffs are approximate and should be judged with sampling uncertainty and residual diagnostics; the familiar white-noise bands near are a null approximation, not universal confidence limits for a dependent series.
For the trend problem, write a symmetric estimator asReproducing arbitrary constant and quadratic trends requires and ; the linear-trend condition holds automatically by symmetry. These constraints follow by expanding for a trend . Thus , . Since the errors are uncorrelated and the estimator is unbiased, its mean squared error isThe strictly convex quadratic is minimized at , giving the five-point symmetric quadratic trend smootherThis weighted moving average allows negative coefficients; a convex average could not cancel the quadratic moment.
For three points, symmetry gives weights . Unbiasedness for every quadratic requires and , so the only solution is . Thus there is no nontrivial three-point quadratic-preserving smoother. The literal claim that there is no unbiased estimator at all is false, since is unbiased with error variance . This is the three-point quadratic reproduction forces the identity filter distinction.
For seasonal extraction by a centred moving average, use the additive decomposition , where has period and its values over one period sum to zero. An average covering a full period removes the seasonal component and approximately retains a slowly changing trend. If is odd, take the centred length- average; if is even, centre it by averaging two adjacent length- averages, giving half weights at the two endpoints. Subtract this trend estimate from the data, average residuals within each seasonal phase over different cycles, and centre the resulting phase estimates to sum to zero. For a multiplicative decomposition, use ratios and normalize the phase estimates to average one.
Successive moving averages compose by convolution of their weights. Even an initially uncorrelated noise series becomes correlated: for weights , the filtered noise has covariance . Further smoothing changes this covariance again and can turn random variation into apparently persistent patterns while obscuring genuine short-scale features. Spectrally, repeated use of a transfer function multiplies the spectrum by after applications, so repeated smoothing is not harmless repetition of the same estimate.
In simple exponential smoothing, choose and update . Iteration gives , so older observations receive exponentially decreasing weights. Forecast for every . This is appropriate for a locally stable level with no persistent trend or seasonality.
For a local linear trend, double exponential smoothing supplies level and slope. Holt's linear trend method usesAnother standard convention is Brown's double exponential smoothing: smooth twice with the same gain, and , then put , and forecast . These variants handle a nonseasonal trend; seasonal effects need separate modelling, and a long-horizon linear extrapolation assumes the current local slope persists.
Past exam of the mathematics course of the University of Cambridge 2002 iii Paper 40 6 Solution Created 2026-10-03 Updated 2026-10-14
A linear filter of a stationary time series with real coefficients satisfying is . Its filter generating function is the Laurent series , absolutely convergent on , and its filter transfer function is . For a one-sided filter this is a power series; a general two-sided filter need not converge on a larger annulus.
The filter theorem states that if is second-order stationary, then exists in mean square, is second-order stationary, and has mean and covarianceIts spectral measure of a stationary time series is . In particular, if has a time-series spectral density in the convention , thenTo prove existence, the norm of a tail of the filter is at most times the sum of the omitted , which tends to zero. Hence finite partial sums converge in . Expectations and covariances pass to the limit, and the covariance double sum is absolutely convergent because . Its formula depends only on , proving stationarity. Insert the spectral representation of and interchange sums and integration; the bound justifies the interchange. The resulting factor is . This proves the spectral statement, including the spectral density transformation under a linear filter without assuming that the input autocovariances are absolutely summable.
For an autoregressive moving-average model, use real polynomials normalized by and first work with the reduced noise-driven representation. If has no zero on the unit circle, the rational function has a Laurent expansion in an annulus containing that circle, with absolutely summable coefficients. Filtering the white noise with it gives a stationary solution. Its time-series spectral density isConversely, for coprime , a unit-circle zero of would make this ratio nonintegrable, since the numerator does not vanish there; thus there is no finite-variance stationary noise-driven solution. A stationary solution can use a bilateral filter when autoregressive roots lie inside the unit circle. The stronger causal condition, meaning dependence only on present and past noise, requires every zero of strictly outside the unit disk. Common factors must be handled before applying these conditions; a cancelled unit-root factor can also allow additional deterministic stationary components, which are outside the minimal noise-driven convention.
Identifiability means that different admissible parameters cannot produce the same stationary process law. In this zero-mean Gaussian setting, its law is determined by its covariance, equivalently its spectrum. Unrestricted ARMA coefficients are not identifiable from that law: if a moving-average factor has root inside the disk, then on ,Reflecting the root outside and multiplying the innovation variance by preserves the spectrum, and therefore the Gaussian law. Common polynomial factors and arbitrary overall scaling give further redundancy. A regular canonical identifiable parameterization requires constant coefficients one, coprime polynomials of their stated minimal orders, all zeros of both and outside the closed unit disk, and .
Here is a proof of canonical identifiability of Gaussian ARMA models. Suppose two such models have equal spectra and write their innovation standard deviations as . The ratio and its reciprocal are analytic on a neighbourhood of the closed unit disk, with modulus one on its boundary. The maximum modulus principle applied to both makes throughout the disk, so is constant. Its value at zero is the positive number , forcing and . Therefore ; coprimality and the normalization at zero force equality of both polynomials. This proves the claimed parameter uniqueness within that canonical class.
In this class, is analytic on a disk of radius greater than one. Its Taylor series coefficients are absolutely summable, soThis is an invertible time-series representation, proved by composition of the stable filters. Causality makes orthogonal to past observations; invertibility makes past noises recoverable from past observations. Their closed past linear spans agree, so this noise is the linear innovation and the one-sided expansion is the Wold representation. Mere stationarity without the stated canonical restrictions does not imply invertibility of the originally written noise representation.
For this one-sided canonical representation, . Comparing coefficients gives the ARMA coefficient recursionsThus for exactly the range asked for,The characteristic rates are reciprocals of the zeros of . Partial fractions therefore express the tail as sums of , where and the degree of is at most one less than the corresponding root multiplicity. Hence the coefficients decay exponentially, with possible polynomial and damped oscillatory factors. If , they instead vanish after . For a noncausal or noninvertible original specification, the Wold coefficients refer to the canonical spectral factor; using the original driving noise as the Wold innovation without checking these restrictions would be incorrect.
The autocovariance is . Analyticity of on a disk of radius gives for a slightly smaller radius than its first pole, and consequently . Moreover, multiply the ARMA equation at time by and take expectations. For , all noises with are later than and orthogonal to it. For this givesThe covariance tail therefore has the same characteristic exponential rates and multiplicity patterns as the filter coefficients, subject to possible cancellation of amplitudes. Pure moving averages have an exact covariance cutoff.
For the final process, factor the polynomials:The common factor has its zero at , so it can be cancelled as a stable filter. Explicitly, let ; the original equation gives . The second moments of are uniformly bounded because those of and are. Iterating gives , whose norm tends to zero as , so in mean square. ThusSumming the covariance series givesThe process is a causal stationary autoregressive process of order one, with alternating-sign geometric correlations, and is invertible. The displayed ARMA(2,1) description is nonminimal because of its common factor; its minimal identifiable class is ARMA(1,0).
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 43 5 Solution Created 2026-10-03 Updated 2026-10-14
Write and . The discrete Fourier transform coefficient is . Alternatively, by the given orthogonality relations, the harmonic obtained by linear least-squares projection has coefficients and . Thus the source's periodogram is the squared amplitude of a fitted harmonic, scaled as power per unit angular frequency:It measures how much of the centered record varies at frequency . For odd , Fourier Parseval identity givesThe positive-frequency spacing is , so summing the power ordinates times this spacing estimates the total variance. The factor corresponds to the one-sided spectral density on ; the usual two-sided periodogram is half as large.
If the observations are Gaussian white noise with common variance , the harmonic sums are jointly normally distributed. Their means are zero even with a nonzero constant series mean, because each sine and cosine sums to zero. Orthogonality givesUncorrelated coordinates of a multivariate normal distribution are independent. Therefore all and are independent standard normals, andSince the chi-squared distribution with two degrees of freedom has mean two and variance four,Here is the one-sided white-noise spectral density. Its exact unbiasedness is accompanied by a nonconcentrating distribution: along Fourier frequencies tending to any interior frequency, has the same nondegenerate exponential law at every . It therefore does not converge in probability to one, proving failure of statistical consistency, not just nonvanishing variance.
For a general stationary process, exact finite-sample unbiasedness is not implied. Expanding the Fourier square instead giveswhere is the autocovariance function. Under suitable short-memory regularity this tends to at frequencies . The periodogram is thus generally asymptotically unbiased, while the exact assertion above is for white noise.
Use local periodogram smoothing to reduce variance: average neighboring ordinates with weights summing to one, where but . At an interior frequency the shrinking frequency window makes the bias tend to zero for smooth , while averaging many weakly dependent ordinates makes the variance of order . For white noise with equal weights, the ordinates are exactly independent and the variance is exactly . For a general process, impose suitable short-memory and fourth-order dependence assumptions, such as a stationary Gaussian model with sufficiently summable autocovariances. These conditions, together with smoothness, give a consistent smoothed estimator. Boundary frequencies require an appropriately one-sided or reflected window.
Smooth spectral density alone is not enough. For example let , where is a nondegenerate random variable constant throughout the record, independent of independent unit-variance Gaussian , with . The unconditional autocovariance is zero off lag zero and its one-sided spectral density is the smooth constant . Nevertheless a long local average estimates the realized , not that deterministic unconditional value. This nonergodic example explains why a dependence/ergodicity condition accompanies the smoothing argument.
For the turning point test of randomness, the null is independent identically distributed continuous observations. Let be one if is a strict local maximum or minimum among , for , and set . Three ranks are equally likely; the middle observation is an extremum in four of the six orders, giving and . ThereforeIndicators more than two positions apart depend on disjoint observations and are independent. For neighboring indicators, both are one precisely when four observations alternate up-down-up or down-up-down. By the probability-integral transform, use four independent uniforms. The first pattern has probabilityhere , , with the two outer inequalities having probabilities and . The reverse pattern has the same probability, so and .
At separation two, the triples share only one endpoint value . Conditional on it, their other observations are independent. The probability that either triple's central observation is a turning point isIt follows that , so this covariance is . Combining all terms for givesThe standardized count is approximately standard normal for large , by a central limit theorem for bounded 2-dependent indicators. A two-sided randomness test rejects for large absolute values ofToo few turns suggests persistent movement, while too many suggests alternation. Exact rank-permutation calibration is possible at small . Ties invalidate the continuous-rank probabilities unless their handling is specified. The test probes this feature of randomness; nonrejection does not establish independence.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 47 1 Solution Created 2026-10-03 Updated 2026-10-14
A real weakly stationary process has finite second moments, a time-independent mean , and autocovariance function depending only on the lag. Use the angular-frequency conventionThe time-series spectral density is nonnegative and integrates to . The displayed Fourier series is ordinarily justified by . More generally, weak stationarity gives a spectral measure of a stationary time series, not necessarily a spectral density. If a spectral density exists without this summability, its Fourier inversion can be understood using Fejér sums, which converge in and at its Lebesgue points. Thus spectral density existence should not be inferred from weak stationarity alone.
A white noise process has mean zero and . Neither independence nor a normal distribution is needed for this second-order definition. Its autocovariance function is zero at nonzero lags, soFor a real absolutely summable filter , the series defining has mean-square convergence: its tails have norm at most . Its mean is , andThe sum is absolutely convergent, since by the Cauchy-Schwarz inequality. It depends only on , proving that the output is a weakly stationary process. Substitute the spectral integral for and interchange the sums and integral, justified by and . This givesBecause the coefficients are real, the two factors are complex conjugates. Hence the spectral density transformation under a linear filter isFor complex coefficients the same formula holds with the conjugate-covariance convention.
Applying this result to the order-two moving-average model yieldsEquivalently, its nonzero autocovariances are , and , together with .
For the order-one moving-average process, invert its filter by a geometric series. The required coefficients areThey are absolutely summable for . Direct cancellation giveswith mean-square convergence. Thus the inverse filter recovers exactly the original white noise process, including its variance; it is an invertible time-series representation.