In executable Haskell, the algebraic data type declaration uses This is a preorder traversal of a full binary tree, including the leaves. Structural induction proves correctness: the leaf of a rooted tree case has precisely one output, and the fork case concatenates the correct preorder traversals of its two subtrees after its own marker.
data, rather than the printed type. A leaf of a rooted tree contributes False; a fork contributes True followed by its left and right subtrees in that order.data Tree = Leaf | Fork Tree Tree
preorder :: Tree -> [Bool]
preorder Leaf = [False]
preorder (Fork l r) = True : (preorder l ++ preorder r)An equivalent version avoids repeatedly copying the left list through list concatenation:Its strengthening is
preorder t = walk t []
  where
    walk Leaf rest       = False : rest
walk (Fork l r) rest = True : walk l (walk r rest)walk t rest = preorder t ++ rest. Each vertex constructs one list cell, so this version has linear time complexity. The concise result isFor parts (b)–(e), use array indices as tree handles. This also makes the shared storage in part (d) type-correct: both pending handles and output markers occupy integer cells. Zero denotes a leaf of a rooted tree; a positive handle denotes a fork whose children are in Initialize
nodes[t-1]. Only finite acyclic structures are admitted. An allocated fork's children are themselves valid handles.CONST MaxForks = 100000;
TYPE Tree = INTEGER;
Node = RECORD left, right: Tree END;
Arena = ARRAY MaxForks OF Node;
VAR nodes: Arena;
used: INTEGER;
PROCEDURE NewFork(left, right: Tree): Tree;
BEGIN
ASSERT(used < MaxForks);
nodes[used].left := left; nodes[used].right := right;
INC(used);
RETURN used
END NewFork;
PROCEDURE Preorder(t: Tree; VAR out: ARRAY OF INTEGER;
VAR count: INTEGER);
PROCEDURE Visit(p: Tree);
BEGIN
IF p = 0 THEN
out[count] := 0; INC(count)
ELSE
out[count] := 1; INC(count);
Visit(nodes[p-1].left); Visit(nodes[p-1].right)
END
END Visit;
BEGIN
count := 0; Visit(t)
END Preorder;used := 0 before constructing any trees; NewFork allocates within this arena. The fixed capacity is an implementation parameter and may be replaced by a dynamically allocated arena. The returned prefix out[0..count) encodes Boolean values by and . This encoding is part of the chosen representation, not a conversion of a pointer into a Boolean value.The recursion invariant is that
Visit(p) appends exactly the preorder traversal of the subtree represented by p. If the full binary tree has forks, it has leaves; henceEach occurrence is visited once, using linear time complexity and a call stack bounded by the height of a binary tree. The arena is the input representation, not an extra copy made by the traversal.Use an explicit stack of handles. Push the right subtree first, so that the left subtree is removed first by the LIFO stack.The loop invariant says that the already written prefix, followed by the preorder traversals of the pending subtrees in top-to-bottom stack order, equals the entire required output. Popping a leaf of a rooted tree transfers one marker to the prefix. Popping a fork transfers its marker and replaces its remaining work by left then right subtree work. Both preserve the loop invariant. The number of as-yet-unwritten vertices decreases by one per iteration, proving termination.The time complexity is linear in the output length. The maximum stack size is at most one plus the height of a binary tree.
PROCEDURE PreorderIter(t: Tree; VAR out: ARRAY OF INTEGER;
                       VAR count: INTEGER;
                       VAR stack: ARRAY OF Tree);
VAR top: INTEGER; p: Tree;
BEGIN
  count := 0; top := 1; stack[0] := t;
  WHILE top > 0 DO
    DEC(top); p := stack[top];
    IF p = 0 THEN
      out[count] := 0; INC(count)
    ELSE
      out[count] := 1; INC(count);
      stack[top] := nodes[p-1].right; INC(top);
      stack[top] := nodes[p-1].left; INC(top)
    END
  END
END PreorderIter;Let be the final output length, the number of emitted markers, and the number of pending handles. Each pending subtree contributes at least one future marker, soStore output from the low end and the stack from the high end of the same array. A pop frees one cell before the next write. For a fork, the two pushed children each account for at least one of the remaining markers. Thus the two regions never overlap.The loop invariant includes
PROCEDURE PreorderShared(t: Tree; VAR out: ARRAY OF INTEGER;
                         VAR count: INTEGER);
VAR top, cap: INTEGER; p: Tree;
BEGIN
  cap := LEN(out); count := 0;
  top := cap-1; out[top] := t;
  WHILE top < cap DO
    p := out[top]; INC(top);
    IF p = 0 THEN
      out[count] := 0; INC(count)
    ELSE
      out[count] := 1; INC(count);
      DEC(top); out[top] := nodes[p-1].right;
      DEC(top); out[top] := nodes[p-1].left
    END
  END
END PreorderShared;count <= top, with pending handles in out[top..cap) and final markers in out[0..count). The preceding accounting proves every intermediate write also respects array bounds. This uses the integer handle representation chosen in part (b). Simply putting a pointer into a genuinely Boolean-typed cell would not be valid Oberon.Maintain a cursor to the first unread marker. A fork consumes its own marker and then two complete encodings, in left-to-right order.Start with
PROCEDURE Decode(VAR code: ARRAY OF INTEGER;
                 VAR pos: INTEGER): Tree;
VAR marker: INTEGER; left, right: Tree;
BEGIN
  marker := code[pos]; INC(pos);
  IF marker = 0 THEN RETURN 0 END;
  ASSERT(marker = 1);
  left := Decode(code, pos);
  right := Decode(code, pos);
  RETURN NewFork(left, right)
END Decode;pos := 0; t := Decode(code, pos), with sufficient unused arena space. The valid-input precondition ensures that every read exists and every fork has two encoded subtrees. Evaluating the two recursive calls in separate statements fixes their order.Structural induction shows that decoding reconstructs the same binary tree shape and leaves the cursor just after its encoding. The tree handles need not coincide with the original handles: the abstract tree does. The result isThe time complexity is linear in the encoding length, with call stack space bounded by the height of a binary tree.
With the fixed array On success, , , and . On failure there is no occurrence; the output indices are unspecified. Thus
f visible to the procedures, use a Boolean result for success and two output array indices:TYPE Search = PROCEDURE(x: INTEGER; VAR i, j: INTEGER): BOOLEAN;Use a linear search over every pair of array indices.For a worst-case lower bound, consider an input in which every inspected element differs from . If an element remains uninspected, changing just that element to gives an indistinguishable execution requiring the opposite answer. Therefore a correct exact search algorithm must inspect all elements in the worst case.
PROCEDURE SearchAll(x: INTEGER; VAR i, j: INTEGER): BOOLEAN;
VAR r, c: INTEGER;
BEGIN
  FOR r := 0 TO M-1 DO
    FOR c := 0 TO N-1 DO
      IF f[r,c] = x THEN i := r; j := c; RETURN TRUE END
    END
  END;
  RETURN FALSE
END SearchAll;The printed phrase “at least ” uses the upper-bound notation for a lower-bound claim. Its precise interpretation isThis is an adversary argument for access to arbitrary independent array entries.
Write , assuming . By monotonicity, is at least every value in the first row and at most every value in the last column. HenceThe same observation applies to the top-right corner of any remaining rectangular subarray of this monotone matrix.
Implement staircase matrix search from the top-right corner. In the following Oberon-style code, The loop invariant is that every occurrence not yet returned lies inInitially this is the whole array. If , every entry of row in the candidate rectangle is smaller than , so increasing discards no possible answer. If , every entry of column in that rectangle is greater than , so decreasing is safe. These conclusions follow from monotonicity even when repeated values occur.
& denotes short-circuit conjunction; all guarded accesses respect array bounds.PROCEDURE Staircase(x: INTEGER; VAR i, j: INTEGER): BOOLEAN;
VAR r, c: INTEGER;
BEGIN
r := 0; c := N-1;
WHILE (r < M) & (c >= 0) DO
IF f[r,c] = x THEN i := r; j := c; RETURN TRUE
ELSIF f[r,c] < x THEN INC(r)
ELSE DEC(c)
END
END;
RETURN FALSE
END Staircase;The loop variant decreases on every unsuccessful iteration. If a dimension becomes empty, the loop invariant proves absence. For positive dimensions the path inspects at most entries; an initially empty dimension causes no inspection. Thus
Monotonicity gives two excluded rectangles:Indeed the first entries are at most , and the second are at least . In particular, the entire splitting row contains no answer. The only remaining candidates are the upper-right rectangle and the lower-left rectangle . These are the exclusions guaranteed by the given adjacent inequalities; further comparisons may exclude more.
Use half-open rectangles . Split the longer dimension at its middle. If rows are the longer dimension, binary search the middle row for its first entry at least . Equality returns immediately; otherwise part (e) leaves only an upper-right and a lower-left rectangle. A middle-column split uses the transposed argument.The lower-bound binary search invariant says that entries before
PROCEDURE SearchRect(x, r0, r1, c0, c1: INTEGER;
                     VAR i, j: INTEGER): BOOLEAN;
VAR mid, lo, hi, k: INTEGER;
BEGIN
  IF (r0 >= r1) OR (c0 >= c1) THEN RETURN FALSE END;
  IF r1-r0 >= c1-c0 THEN
    mid := r0 + (r1-r0) DIV 2;
    lo := c0; hi := c1;
    WHILE lo < hi DO
      k := lo + (hi-lo) DIV 2;
      IF f[mid,k] < x THEN lo := k+1 ELSE hi := k END
    END;
    IF lo < c1 THEN
      IF f[mid,lo] = x THEN i := mid; j := lo; RETURN TRUE END
    END;
    IF SearchRect(x, r0, mid, lo, c1, i, j) THEN
      RETURN TRUE
    END;
    RETURN SearchRect(x, mid+1, r1, c0, lo, i, j)
  ELSE
    mid := c0 + (c1-c0) DIV 2;
    lo := r0; hi := r1;
    WHILE lo < hi DO
      k := lo + (hi-lo) DIV 2;
      IF f[k,mid] < x THEN lo := k+1 ELSE hi := k END
    END;
    IF lo < r1 THEN
      IF f[lo,mid] = x THEN i := lo; j := mid; RETURN TRUE END
    END;
    IF SearchRect(x, r0, lo, mid+1, c1, i, j) THEN
      RETURN TRUE
    END;
    RETURN SearchRect(x, lo, r1, c0, mid, i, j)
  END
END SearchRect;

PROCEDURE DivideSearch(x: INTEGER; VAR i, j: INTEGER): BOOLEAN;
BEGIN
  RETURN SearchRect(x, 0, M, 0, N, i, j)
END DivideSearch;lo are smaller than and entries from hi onward are at least , within the splitting row or column. At its end, either equality is found or the splitting line is strictly separated around . Endpoint cuts lo=c0, lo=c1, lo=r0, or lo=r1 are valid and merely make one candidate rectangle empty.The recursion invariant is that the current rectangle contains every still-possible answer assigned to that call. The discarded rectangles are excluded by monotonicity; both retained rectangles inherit monotonicity. Each nonempty child has a strictly smaller longest dimension after at most two levels, so the recursion terminates, including one-row and one-column cases. The concise construction is
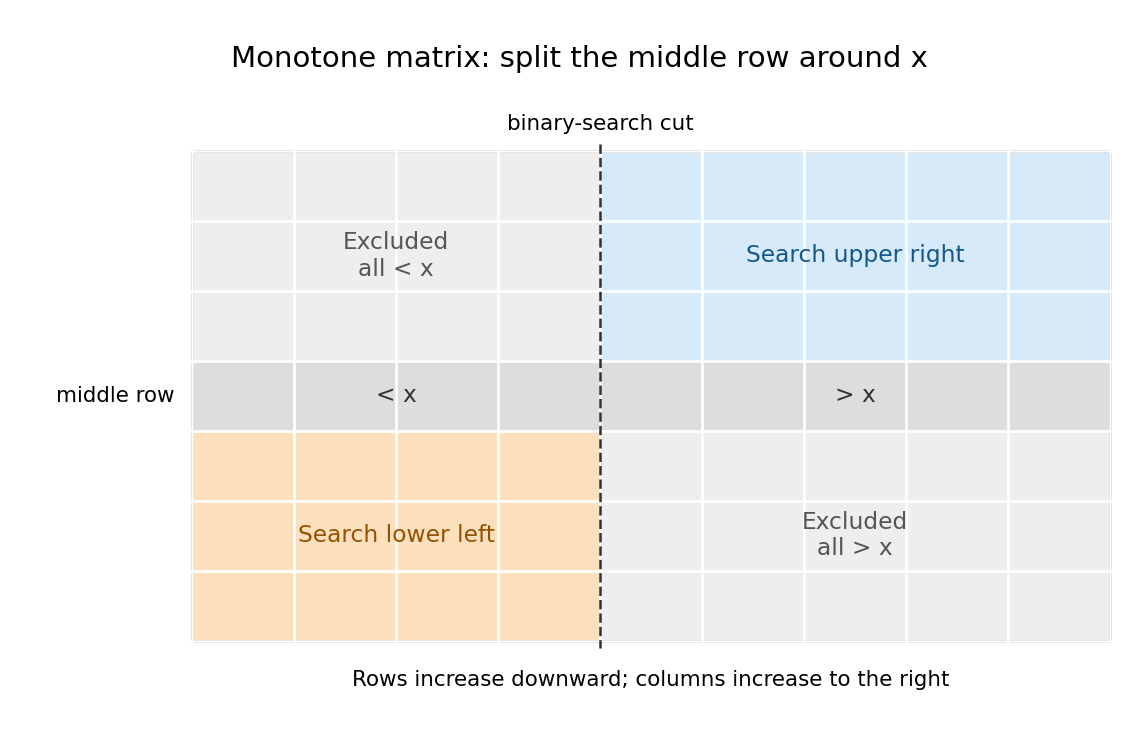
Two complementary rectangles survive a middle-row search
. For a monotone matrix, the middle row's binary search separates entries smaller than from entries greater than when no equality is found. The upper-left and lower-right rectangles are excluded by monotonicity; only the blue and orange rectangles require further search algorithm. Details.
For finite acyclic chains, define the abstraction function recursively byHere the list contains linked list nodes themselves. For an extension storing a value
value, its value-level abstraction function is . Finiteness and absence of a graph cycle ensure that these recursive definitions terminate. A dummy header node is excluded by applying to its tail.A dummy header node gives the first actual linked list node a predecessor, just like every other element. Linked-list deletion and insertion at the front can therefore update a predecessor's
tail with the same code used in the middle. An empty linked list is represented by a header whose tail is NIL.The representation invariant isEvery reachable non-
NIL pointer designates an allocated linked list node of the appropriate extension type. The header is not a data element. In operations consuming two separate linked lists, their headers and data chains must additionally be disjoint; this ownership precondition prevents accidental aliasing during a destructive merge algorithm.Reuse The traversal starts at the dummy header node, so after steps
p as q's header and allocate one new header for r. Cut after data elements, allowing .PROCEDURE Split(p: List; VAR q, r: List);
VAR n, k, i: INTEGER; last: Tail;
BEGIN
n := p.count; k := n DIV 2;
q := p; NEW(r);
last := q;
FOR i := 1 TO k DO last := last.tail END;
r.tail := last.tail; last.tail := NIL;
q.count := k; r.count := n-k
END Split;last precedes the suffix assigned to r. Cutting that link produces two finite disjoint linked lists. Their concatenated abstraction function is the original list, with order preserved, andBoth empty and singleton inputs work without special traversal cases. The time complexity is and only one header is allocated.Assume The loop invariant says that the segment from
less is a lawful strict comparison, for example a strict weak order, and the two input linked lists are disjoint and sorted by it. Allocate a result header and move existing data linked list nodes; do not copy their values.PROCEDURE Merge(less: LESS; q, r: List; VAR p: List);
VAR result: List; last, a, b: Tail;
BEGIN
NEW(result); result.count := q.count + r.count;
result.tail := NIL; last := result;
a := q.tail; b := r.tail;
WHILE (a # NIL) & (b # NIL) DO
IF less(b,a) THEN
last.tail := b; b := b.tail
ELSE
last.tail := a; a := a.tail
END;
last := last.tail
END;
IF a # NIL THEN last.tail := a ELSE last.tail := b END;
q.tail := NIL; q.count := 0;
r.tail := NIL; r.count := 0;
p := result
END Merge;result.tail through last is a sorted prefix of the desired merge algorithm, containing exactly the nodes already removed from the two unread chains. Every element of this prefix is no greater than either unread head. Choosing the smaller unread head maintains this property; choosing from q on a tie also gives stable sorting.At exit, at most one unread chain is nonempty, and its sorted suffix can be attached as a whole. Each original data linked list node occurs exactly once in the result, and its saved count is correct. Clearing the consumed headers prevents them from claiming ownership of the result's nodes.
Use merge sort, stopping before an empty or singleton linked list would be split.By induction on the length, each recursive call returns a sorted permutation of its input. Part (d) makes both child lengths smaller than the parent whenever the parent length exceeds one; part (e) combines the sorted children. No data linked list nodes are newly allocated or lost. Unreachable headers may be reclaimed by garbage collection.
PROCEDURE MergeSort(less: LESS; VAR p: List);
VAR q, r: List;
BEGIN
  IF p.count > 1 THEN
    Split(p, q, r);
    MergeSort(less, q); MergeSort(less, r);
    Merge(less, q, r, p)
  END
END MergeSort;At each level the total splitting and merge algorithm work is linear; approximately equal halves give logarithmic depth. ConsequentlyThere are header allocations over the whole execution; those allocations should not be confused with the logarithmic call stack bound.
Extend the data linked list node type by a real number field and compare that field through an Oberon type guard.Construct the data chain from Only data nodes reach
TYPE RealNode = RECORD (Node) value: REAL END;
     RealTail = POINTER TO RealNode;

PROCEDURE RealLess(p, q: Tail): BOOLEAN;
BEGIN
  RETURN p(RealTail).value < q(RealTail).value
END RealLess;RealTail nodes, retain the ordinary Header for its header, set its count correctly, and callMergeSort(RealLess, p)RealLess, so the header needs no real-valued field. Its precondition is that every data node has the RealNode extension. With ordinary real numbers, the comparison supplies a total order; machine values such as NaN must be excluded if the machine floating-point number type admits them.Represent the zero polynomial by ThusThe sentinel is a representation convention, not an assertion that the mathematical degree of the zero polynomial is an ordinary integer. In parts (b)–(e), algebraic correctness uses exact arithmetic on real numbers; ordinary floating-point arithmetic introduces rounding and needs an additional numerical policy if exact zero tests are to be replaced.
degree = -1, with an allocated one-element array whose element is zero. Its coefficient prefix is empty; the spare cell is merely convenient storage. For every nonzero polynomial, require degree >= 0, sufficient allocated capacity, and a nonzero leading polynomial coefficient.PROCEDURE Zero(VAR p: Poly);
BEGIN
p.degree := -1; NEW(p.coeff, 1); p.coeff[0] := 0.0
END Zero;
PROCEDURE Normalize(VAR p: Poly);
BEGIN
WHILE p.degree >= 0 DO
IF p.coeff[p.degree] # 0.0 THEN RETURN END;
DEC(p.degree)
END
END Normalize;Allocate a fresh coefficient array, add matching polynomial coefficients, and normalize to remove any cancellation of leading terms.The loop invariant says that every completed coefficient equals the corresponding coefficient of , treating missing coefficients as zero.
PROCEDURE Add(VAR sum: Poly; a, b: Poly);
VAR result: Poly; d, cap, i: INTEGER;
BEGIN
  d := a.degree;
  IF b.degree > d THEN d := b.degree END;
  cap := d+1; IF cap < 1 THEN cap := 1 END;
  result.degree := d; NEW(result.coeff, cap);
  result.coeff[0] := 0.0;
  FOR i := 0 TO d DO
    result.coeff[i] := 0.0;
    IF i <= a.degree THEN
      result.coeff[i] := result.coeff[i] + a.coeff[i]
    END;
    IF i <= b.degree THEN
      result.coeff[i] := result.coeff[i] + b.coeff[i]
    END
  END;
  Normalize(result); sum := result
END Add;Normalize changes no represented polynomial, and can reduce the result to the zero polynomial.Neither input coefficient array is changed. Output variables are separate from input record variables; the fresh result also remains safe when the two inputs share a coefficient array.Use polynomial convolution. If either input is the zero polynomial, return the zero polynomial immediately.Each pair of terms contributes , so the final polynomial coefficient of isWith exact arithmetic on real numbers, the product of the leading nonzero polynomial coefficients is nonzero, giving degree . The nested loops implement precisely this sum, preserve the input coefficient arrays, and take time for nonzero inputs.
PROCEDURE Mul(VAR prod: Poly; a, b: Poly);
VAR result: Poly; d, i, j: INTEGER;
BEGIN
  IF (a.degree < 0) OR (b.degree < 0) THEN
    Zero(result)
  ELSE
    d := a.degree+b.degree;
    result.degree := d; NEW(result.coeff, d+1);
    FOR i := 0 TO d DO result.coeff[i] := 0.0 END;
    FOR i := 0 TO a.degree DO
      FOR j := 0 TO b.degree DO
        result.coeff[i+j] := result.coeff[i+j]
                              + a.coeff[i]*b.coeff[j]
      END
    END;
    Normalize(result)
  END;
  prod := result
END Mul;Require a nonzero divisor. Polynomial long division repeatedly subtracts the multiple of that cancels the leading term of the current polynomial remainder. Use fresh arrays for both outputs.The loop invariant is the polynomial identity . Setting and replaces by and by , preserving this identity. The leading coefficient of that difference is exactly zero, so setting its stored value to zero and decreasing
PROCEDURE DivMod(VAR div, mod: Poly; a, b: Poly);
VAR q, r: Poly; cap, i, j, k, old: INTEGER; t: REAL;
BEGIN
  ASSERT(b.degree >= 0);
  cap := a.degree+1; IF cap < 1 THEN cap := 1 END;
  r.degree := a.degree; NEW(r.coeff, cap);
  r.coeff[0] := 0.0;
  FOR i := 0 TO a.degree DO r.coeff[i] := a.coeff[i] END;
  IF a.degree < b.degree THEN
    Zero(q)
  ELSE
    q.degree := a.degree-b.degree;
    NEW(q.coeff, q.degree+1);
    FOR i := 0 TO q.degree DO q.coeff[i] := 0.0 END;
    WHILE r.degree >= b.degree DO
      old := r.degree; k := old-b.degree;
      t := r.coeff[old]/b.coeff[b.degree];
      q.coeff[k] := q.coeff[k]+t;
      FOR j := 0 TO b.degree-1 DO
        r.coeff[k+j] := r.coeff[k+j]-t*b.coeff[j]
      END;
      r.coeff[old] := 0.0;
      DEC(r.degree); Normalize(r)
    END;
    Normalize(q)
  END;
  div := q; mod := r
END DivMod;degree implements its exact cancellation. Each iteration strictly decreases the degree of the polynomial remainder.At termination,The zero polynomial dividend, a lower-degree dividend, and a constant divisor are all covered. Division by the zero polynomial is undefined. The two output record variables must be distinct and separate from the input record variables; no input coefficient array is written. For , the work is .
Scan the polynomial coefficients from highest degree downward. Omit zero terms, omit coefficient magnitude one on nonconstant terms, print The representation invariant ensures a nonzero polynomial prints at least one term. Constant and retain their coefficients, whereas and omit magnitude one. Thus the requested example printsDifferent
- for negative terms, and print + only before a positive term after the first. A helper prints small integral magnitudes without a decimal suffix; other real numbers use Out.Real.PROCEDURE OutMagnitude(c: REAL);
VAR n: INTEGER;
BEGIN
IF c < MAX(INTEGER) THEN
n := ENTIER(c);
IF c = n THEN Out.Int(n, 0) ELSE Out.Real(c, 0) END
ELSE
Out.Real(c, 0)
END
END OutMagnitude;
PROCEDURE OutPoly(p: Poly);
VAR i: INTEGER; c, magnitude: REAL; first: BOOLEAN;
BEGIN
IF p.degree < 0 THEN Out.String("0"); RETURN END;
first := TRUE; i := p.degree;
WHILE i >= 0 DO
c := p.coeff[i];
IF c # 0.0 THEN
IF c < 0.0 THEN Out.Char("-")
ELSIF ~first THEN Out.Char("+")
END;
magnitude := ABS(c);
IF (i = 0) OR (magnitude # 1.0) THEN
OutMagnitude(magnitude)
END;
IF i > 0 THEN
Out.Char("x");
IF i > 1 THEN Out.Char("^"); Out.Int(i, 0) END
END;
first := FALSE
END;
DEC(i)
END
END OutPoly;Out.Real implementations may use decimal or scientific notation for nonintegral coefficients; either denotes the appropriate real number. The number of coefficient inspections is linear in the stored polynomial degree.Apply overload selection followed by dynamic dispatch: method overloading chooses a signature from the receiver's static type and argument static types, then dynamic dispatch chooses an override of that signature using the receiver's runtime type. A
super call selects the inherited implementation; a call on the companion object B uses that object's own methods.[ref]Scala 2.11 expressions specification. Static overload resolution; this and super
The output, in order, isFor
f(x:X) in B
f(y:Y) in A
f(x:X) in A, g(x:X) in B
f(x:X) in ObjB, g(y:Y) in ObjB, h(y:Y) in B, h(z:Z) in C
f(y:Y) in C, m(a:A) in Y, k(x:X) in Ca.f(x), the argument's static type is X, selecting f(X); the receiver's runtime type B selects B.f(X). For a.f(z), the receiver's static type A exposes only f(X) and f(Y). The Z argument fits both, and f(Y) is more specific. B does not override that signature, so A.f(Y) runs. The additional overload B.f(Z) is invisible through a.For
c.g(z), the inherited instance B.g(X) calls super.f(x), which is A.f(X). For c.h(z), method overloading selects C.h(Z). Its super.h(z) calls B.h(Y), where the local parameter has static type Y. Consequently B.g(y) selects g(Y) on the companion object, whose only f signature is f(X).Finally,
c.k(x) calls x.m(this). The receiver x has runtime type Y, so dynamic dispatch enters Y.m(A). Inside that method, this has static type Y, selecting a.f(Y); the actual argument object is c, so dynamic dispatch reaches C.f(Y). ThereforeWrite each Scala trait linearization from most specific to least specific. Merge the parents' Scala trait linearizations right-to-left, removing a duplicate from the earlier portion when it also appears in the later portion. This retains every base once while respecting its required position after derived traits.[ref]For example, combining the final
CityMan, City, Earth, Man, Mammal, Animal, Describe

BirdMan, City, Earth, Man, Mammal, Bird, Animal, Describe

BatMan, Man, Gotham, City, US, Earth, Bat, Mammal, Bird, Animal, DescribeCity with Gotham does not put City before its derived trait Gotham; duplicate removal places it after Gotham. Similarly Mammal and Bird remain after Bat, despite their occurrence through other parents.Each Each line has a final comma and space, because every printed string fragment includes them. The essential result is
describe calls super.describe before appending its own label. Thus execution enters implementations along the displayed Scala trait linearization, and appends labels in reverse order when calls return. The three printed lines areDescribe, Animal, Mammal, Man, Earth, City,
Describe, Animal, Bird, Mammal, Man, Earth, City,
Describe, Animal, Bird, Mammal, Bat, Earth, US, City, Gotham, Man, Use the representation invariant that each input occurs at most once in
data. It is an immutable finite partial function, so extending or removing an input returns a new object. The source comment get(x) returns Some(x) contradicts both the type signature Option[U] and the input-output semantics: it must return Some(y) when .class PartialFn[T,U](val data: List[(T,U)]) {
require(data.map(_._1).distinct.size == data.size)
def get(x: T): Option[U] =
data.find(p => p._1 == x).map(_._2)
def add(x: T, y: U): PartialFn[T,U] =
new PartialFn[T,U]((x,y) :: data.filterNot(p => p._1 == x))
def remove(x: T): PartialFn[T,U] =
new PartialFn[T,U](data.filterNot(p => p._1 == x))
def compose[V](that: PartialFn[U,V]): PartialFn[T,V] = {
val pairs: List[(T,V)] = data.flatMap { case (x,y) =>
that.get(y).toList.map(z => (x,z))
}
new PartialFn[T,V](pairs)
}
}get returns an optional value rather than inventing a result outside the domain of a function. add removes any old pair for its input before inserting the replacement; remove retains exactly the other pairs. In compose, undefined intermediate outputs contribute an empty list; defined outputs contribute one pair. Hence uniqueness of input keys is preserved.The printed composition order is deliberately followed:This is the stated function composition, even though some libraries use the name
compose for the opposite order.A covariant type parameter may be produced but not consumed directly. Widen the output type of
add through a lower type bound. In compose, the first parameter of CoPartialFn is invariant, so replace its occurrence of U by a fresh type parameter W with lower type bound U.class CoPartialFn[T,+U](val data: List[(T,U)]) {
require(data.map(_._1).distinct.size == data.size)
def get(x: T): Option[U] =
data.find(p => p._1 == x).map(_._2)
def add[V >: U](x: T, y: V): CoPartialFn[T,V] = {
val old: List[(T,V)] = data.filterNot(p => p._1 == x)
new CoPartialFn[T,V]((x,y) :: old)
}
def remove(x: T): CoPartialFn[T,U] =
new CoPartialFn[T,U](data.filterNot(p => p._1 == x))
def compose[V, W >: U](that: CoPartialFn[W,V]): CoPartialFn[T,V] = {
val pairs: List[(T,V)] = data.flatMap { case (x,y) =>
that.get(y).toList.map(z => (x,z))
}
new CoPartialFn[T,V](pairs)
}
}List, Tuple2, and Option are covariant in their element/output parameters, so data, get, and remove are valid producers. The variance-position rule permits U in the lower type bounds; every value of U can be passed to that.get, since . No cast or mutation through a widened reference is needed.[ref]Scala 2.11 basic declarations and definitions specification. Variance Annotations: variance positions and lower-bound widening
The input-key representation invariant and the partial function semantics are unchanged.Because The lower type bound gives , so stored output values can be widened into
Set is invariant in the specified Scala library, even returning Set[U] would place the class's covariant type parameter in an invariant position. Introduce a fresh widened type for each lifting.class CoPartialFnExt[T,+U](data: List[(T,U)])
extends CoPartialFn[T,U](data) {
def forwardLift[V >: U](s: Set[T]): Set[V] = {
val ys: List[V] = this.data.collect {
case (x,y) if s.contains(x) => y
}
ys.toSet
}
def backwardLift[V >: U](s: Set[V]): Set[T] =
this.data.collect {
case (x,y) if s.contains(y) => x
}.toSet
}List[V] or passed to s.contains. Both exposed Set types use invariant method type parameters, not the class's U. Calling forwardLift[U] or backwardLift[U] when the concrete output type is known recovers the exact output universe; a broader admissible universe is also safe.For a partial function, the forward formula is understood only for inputs in its domain of a function. The implementations therefore computeThe conversion to a set removes repeated images. Inputs not in the domain of a function contribute nothing to either lifting.
The source comment saying that The iterator owns consumption of
hasNext checks whether the sequence is empty is read in the standard sense “whether another element exists”; the method must return true for a nonempty logical sequence. The example fixes the meaning: skip source elements and return the next one, repeatedly. Require . A lookahead iterator must determine whether a complete group of elements exists, since a short final group contributes no result.def skipIter[T](it: Iter[T], n: Int): Iter[T] = {
require(n >= 0)
new Iter[T] {
private var prepared = false
private var cached: Option[T] = None
private def prepare(): Unit = {
if (!prepared) {
var skipped = 0
while (skipped < n && it.hasNext) {
it.next(); skipped += 1
}
cached =
if (skipped == n && it.hasNext) Some(it.next())
else None
prepared = true
}
}
def hasNext: Boolean = { prepare(); cached.nonEmpty }
def next(): T = {
prepare()
cached match {
case Some(v) =>
cached = None; prepared = false; v
case None => throw new NoSuchElementException("skipIter.next")
}
}
}
}it; clients must not independently advance the wrapped source. A prepared Some(v) is exactly the next selected source element, and None means no complete group remains. Repeated hasNext calls use the cached decision, and next also works without a preceding hasNext. Using Option[T] avoids an invalid generic sentinel value, including when a valid element is null.For source elements , the result isThe extra storage is and each source element is consumed at most once.
hasNext may physically consume and cache source elements: an arbitrary iterator has no non-consuming length query.Use a history dynamic array and a cursor between elements. If the cursor is behind the history's end, The representation invariant is , with history exactly the prefix already consumed from the original source. The logical unread sequence is the history suffix starting at
next replays history; otherwise it pulls a new element from the source. prev moves the cursor left and returns the element crossed, so prev followed by next returns the same element twice and restores the cursor.def genBiIter[T](it: Iter[T]): BiIter[T] = new BiIter[T] {
private val history = scala.collection.mutable.ArrayBuffer.empty[T]
private var pos = 0
def hasPrev: Boolean = pos > 0
def hasNext: Boolean = pos < history.length || it.hasNext
def next(): T = {
if (pos < history.length) {
val v = history(pos); pos += 1; v
} else if (it.hasNext) {
val v = it.next()
history += v; pos += 1; v
} else {
throw new NoSuchElementException("BiIter.next")
}
}
def prev(): T = {
if (!hasPrev) throw new NoSuchElementException("BiIter.prev")
pos -= 1
history(pos)
}
}pos, followed by the source's remaining sequence. The logical backward history is the prefix before pos. Every operation preserves this model, including alternating backward and forward moves after source exhaustion.This bidirectional iterator uses storage after consuming distinct source elements. Replay and backward moves take constant time; appending has amortized time complexity under the usual dynamic array model. The input iterator must not be advanced separately.Adapt one machine update into one forward iterator element, then apply the skipping iterator of part (a) with and the bidirectional iterator of part (b). Require a positive step and reset once on construction.After forward results at the unexplored frontier, the returned value is the machine's value after exactly updates. A partial final block contributes no element, and
trait StateMachineIter[T] extends StateMachine[T] {
  def getBiIter(step: Int): BiIter[T] = {
    require(step > 0)
    val machine = this
    machine.reset()
    val everyUpdate = new Iter[T] {
      def hasNext: Boolean = !machine.shouldStop
      def next(): T = {
        if (!hasNext)
          throw new NoSuchElementException("StateMachine.next")
        machine.update()
        machine.getValue
      }
    }
    genBiIter(skipIter(everyUpdate, step-1))
  }
}update is never called after shouldStop becomes true. For the printed Add example, the first three observed states areBecause the state machine interface exposes no copy or rollback operation, determining whether enough updates remain generally requires executing them. Thus hasNext may advance the physical machine and cache the next observation. Backward traversal replays stored observations; it does not undo machine effects. This is a trace iterator, with the ordinary cursor semantics of part (b). Assume exclusive use of the machine while this iterator is active, and that returned values remain valid observations rather than mutable views overwritten by later updates.Each physical update is executed at most once. Previously observed values can be revisited without rerunning the machine, and repeated
hasNext calls do not perform duplicate updates once the next result is prepared.For The first is a discrete uniform distribution; the second is a Bernoulli distribution on Boolean values. Their exact mathematical probability mass functions areEach support contains exactly the positive-probability outcomes once, and the probabilities sum to one.
Uniform, require a nonempty integer interval. Compute its size in Long before converting to Double, avoiding integer overflow in u-l+1. For Flip, require , and omit zero-probability outcomes from the reported support.class Uniform(l: Int, u: Int) extends FiniteDist[Int] {
require(l <= u)
private val size = u.toLong - l.toLong + 1L
def getDom: List[Int] = {
val result = List.newBuilder[Int]
var x = l.toLong
while (x <= u.toLong) { result += x.toInt; x += 1L }
result.result()
}
def getProb(x: Int): Double =
if (l <= x && x <= u) 1.0 / size.toDouble else 0.0
}
class Flip(p: Double) extends FiniteDist[Boolean] {
require(0.0 <= p && p <= 1.0)
def getDom: List[Boolean] =
if (p == 0.0) List(false)
else if (p == 1.0) List(true)
else List(true, false)
def getProb(x: Boolean): Double = if (x) p else 1.0-p
}Double approximates these exact values by floating-point arithmetic. Materializing a huge support is limited by available memory; the Long calculation keeps its cardinality and endpoints arithmetically correct.Reject the empty string, because the given formula would divide by zero and no normalized probability distribution exists on its empty observed support. Remove repeated characters from The probability mass function is an empirical probability distribution:Every character occurrence contributes exactly once to the total count, so the probabilities sum to one. Absent characters have count zero. For
getDom, but include all their occurrences when computing probability.class DistFromString(s: String) extends FiniteDist[Char] {
require(s.nonEmpty)
private val chars = s.toList
private val dom = chars.distinct
def getDom: List[Char] = dom
def getProb(x: Char): Double =
chars.count(c => c == x).toDouble / chars.length.toDouble
}"Scala", the support is List('S','c','a','l'), with probabilities respectively. Here Char means the language's UTF-16 code unit, matching the supplied interface rather than assuming one Unicode code point per element.Define an implicit conversion in the scope where client code uses the added methods:Then, for example,The Scala compiler can convert the receiver to
import scala.language.implicitConversions

implicit def stringToDist(s: String): DistFromString =
new DistFromString(s)val support = "Scala".getDom
val p = "Scala".getProb('a')DistFromString when the requested member is absent from String. The conversion must be imported or otherwise visible, and constructing the finite probability distribution retains the nonempty-string precondition of part (b).For the product of finite probability distributions, enumerate the Cartesian product of the two supports and multiply the two probability masses.Each pair appears once because both original supports have no duplicates. Exact probabilities are positive on that support, and normalization follows by finite distributivity:For the pushforward of a finite probability distribution, sum all masses in each fiber of a function; simply overwriting repeated image values would lose probability.Assume the given finite probability distributions are fixed and
def product[T,U](d: FiniteDist[T], d2: FiniteDist[U]): FiniteDist[(T,U)] =
  new FiniteDist[(T,U)] {
    private val dom = for (x <- d.getDom; y <- d2.getDom) yield (x,y)
    def getDom: List[(T,U)] = dom
    def getProb(p: (T,U)): Double = d.getProb(p._1) * d2.getProb(p._2)
}def image[T,U](d: FiniteDist[T], f: T => U): FiniteDist[U] =
new FiniteDist[U] {
private val weighted = d.getDom.map(x => (f(x), d.getProb(x)))
private val dom = weighted.map(_._1).distinct
def getDom: List[U] = dom
def getProb(y: U): Double =
weighted.foldLeft(0.0) { case (total, (z,p)) =>
if (z == y) total+p else total
}
}f is a pure total function on the source support. Distinct image values form exactly the positive-mass support. The fibers partition the original support, provingFor example, sending a discrete uniform distribution on to parity produces masses and , not four distinct outcomes. Exact algebra establishes the finite probability distribution laws; Double computes approximations, with the usual possibility of rounding and floating-point underflow for very small products. Articles by others on the same topic
There are currently no matching articles.