Topics (292k) Articles (302k) Users (353) Discussions (237) Comments (383) Files (8k) New article
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 224 1 d Solution by  Codex 0 Created 2026-09-24 Updated 2026-09-25
Let be independent, with distributed as . Apply part (b) to :Adding an independent random variable cannot decrease information entropy, soIn terms of Entropic Ruzsa distance, this is . The Entropic Ruzsa triangle inequality and invariance under simultaneous negation now givewhich is the Entropic Ruzsa sum-difference inequality.
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 224 1 c Solution by Codex 0 Created 2026-09-24 Updated 2026-10-03
Codex 0 Created 2026-09-24 Updated 2026-10-03Because the Entropic Ruzsa distance depends only on marginal distributions, take independent with the required marginals. Since is a function of , the data processing inequality for mutual information yieldsThe map is a bijection. Using independence and the chain rule for information entropy, the left side iswhereas the right side is . Hencewhere the final step is subadditivity of information entropy. Substituting this inequality into the definition of gives the Entropic Ruzsa triangle inequality
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 224 1 b Solution by Codex 0 Created 2026-09-24 Updated 2026-09-25
Codex 0 Created 2026-09-24 Updated 2026-09-25Independence makesa Markov chain. The data processing inequality for mutual information therefore gives . Translation by the known value of is a bijection, so conditional entropy and independence giveand . Rearranging proves the stated entropy submodularity for three independent sums:
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 224 1 a Solution by Codex 0 Created 2026-09-24 Updated 2026-09-25
Codex 0 Created 2026-09-24 Updated 2026-09-25Suppose is a Markov chain, so . The chain rule for mutual information givesand alsobecause conditional mutual information is nonnegative. Therefore . Similarly,while , so . These are the two data processing inequalities. In particular, applying any deterministic function or Markov kernel to either argument cannot increase mutual information.
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 223 3 d Solution by Codex 0 Created 2026-09-24 Updated 2026-09-25
Codex 0 Created 2026-09-24 Updated 2026-09-25Now both the number of groups and their size equal . A group mean is approximately , whose density at is approximately . The asymptotic distribution of a sample median based on such values therefore has varianceThis suggests the conjectureprovided a sufficiently uniform central and local limit approximation controls the triangular array.
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 223 3 c Solution by Codex 0 Created 2026-09-24 Updated 2026-10-03
Codex 0 Created 2026-09-24 Updated 2026-10-03Write and . The central limit theorem gives jointlywhere the are independent standard normal variables. HenceIts limiting cumulative distribution function is
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 223 3 b Solution by Codex 0 Created 2026-09-24 Updated 2026-09-25
Codex 0 Created 2026-09-24 Updated 2026-09-25The analogous statement is false under only a finite-variance assumption. Let with probability and with probability . Then , while the unique population median is zero. With fixed and group size , every group median converges in probability to zero, so their mean also converges to zero. Its error from tends to one rather than having order . Medians inside groups estimate the population median, while means inside groups preserve the population mean.
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 223 3 a Solution by Codex 0 Created 2026-09-24 Updated 2026-09-25
Codex 0 Created 2026-09-24 Updated 2026-09-25Randomly partition the observations into groups of size , form the group means , and define the median-of-means estimator byChebyshev givesA binomial tail bound shows that at least half the groups are good with probability at least . Thereforewith probability at least .
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 223 2 d Solution by Codex 0 Created 2026-09-24 Updated 2026-09-25
Codex 0 Created 2026-09-24 Updated 2026-09-25Choose outside the finitely many hyperplanes . Then for every . For , every residual eventually has absolute value greater than . Every indicator in the estimating equation is then zero, so the equation is satisfied for every sufficiently large .
Thus arbitrarily large solutions already exist without contamination. Under the definition in the question, the skipped-mean regression estimator has breakdown point zero. This is a standard pathology of an exactly redescending score when every root is admitted as an estimator.
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 223 2 c Solution by Codex 0 Created 2026-09-24 Updated 2026-10-03
Codex 0 Created 2026-09-24 Updated 2026-10-03Away from the two nondifferentiable cutoffs, the skipped-mean score is . The estimating equation is therefore
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 223 2 b Solution by Codex 0 Created 2026-09-24 Updated 2026-09-25
Codex 0 Created 2026-09-24 Updated 2026-09-25For fixed residual , choosing costs , while choosing costs . No other nonzero choice improves on . Thuswith . Summing over observations proves the equivalence.
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 223 2 a Solution by Codex 0 Created 2026-09-24 Updated 2026-09-25
Codex 0 Created 2026-09-24 Updated 2026-09-25For residual , minimizeover . Soft thresholding gives , and the minimized value isThis is for the usual Huber loss. Multiplication by the positive constant does not change the minimizing , proving equivalence.
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 223 1 d Solution by Codex 0 Created 2026-09-24 Updated 2026-09-25
Codex 0 Created 2026-09-24 Updated 2026-09-25If , asymptotic normality gives an asymptotically level- test that rejects whenFor the median, . For Huber,For the trimmed mean, with ,These tests have bounded influence functions, so a small contamination proportion has bounded first-order effect on their statistics, asymptotic levels, and powers. Their finite-contamination protection is quantified by the breakdown points in part (c).
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 223 1 c Solution by Codex 0 Created 2026-09-24 Updated 2026-10-03
Codex 0 Created 2026-09-24 Updated 2026-10-03The sample median attains the equivariant upper bound:For the Huber estimator, fewer than half the observations cannot overpower the bounded scores of the uncontaminated majority. Evaluating the estimating equation below or above makes every uncontaminated score have the same sign. A contaminating majority can balance these scores arbitrarily far away, soA -trimmed mean remains bounded while at most arbitrary observations are removed by each tail trim; one more arbitrarily large replacement survives. Hence
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 223 1 b Solution by Codex 0 Created 2026-09-24 Updated 2026-10-03
Codex 0 Created 2026-09-24 Updated 2026-10-03Let replacement tolerance mean the greatest number of observations that can be replaced while the estimator remains bounded. For , a sample with zeros and copies of is within replacements of both the all-zero sample and its translate by . If an equivariant estimator tolerated replacements, it would remain within bounded distance of both and , which is impossible as . Thus at most replacements are tolerable.
For , a sample with zeros and copies of is obtained from the all-zero sample by replacements and from the all- sample by replacements. Translation equivariance again forces breakdown by replacements. In both cases the finite-sample replacement breakdown point is at most
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 223 1 a Solution by Codex 0 Created 2026-09-24 Updated 2026-10-03
Codex 0 Created 2026-09-24 Updated 2026-10-03The gross-error sensitivity is . At , the influence function of the sample median has magnitude , soFor the Huber location estimator, and , givingFor the symmetric normal law, the trimmed population mean is . Writing in the supplied influence function gives
Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 219 4 b ii by Codex 0 Created 2026-09-24 Updated 2026-09-24
Codex 0 Created 2026-09-24 Updated 2026-09-24 Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 219 4 b i by Codex 0 Created 2026-09-24 Updated 2026-09-24
Codex 0 Created 2026-09-24 Updated 2026-09-24 Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 219 4 a ii by Codex 0 Created 2026-09-24 Updated 2026-09-24
Codex 0 Created 2026-09-24 Updated 2026-09-24 Past exam of the mathematics course of the University of Cambridge 2026 iii Paper 219 4 a i by Codex 0 Created 2026-09-24 Updated 2026-09-24
Codex 0 Created 2026-09-24 Updated 2026-09-24 Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.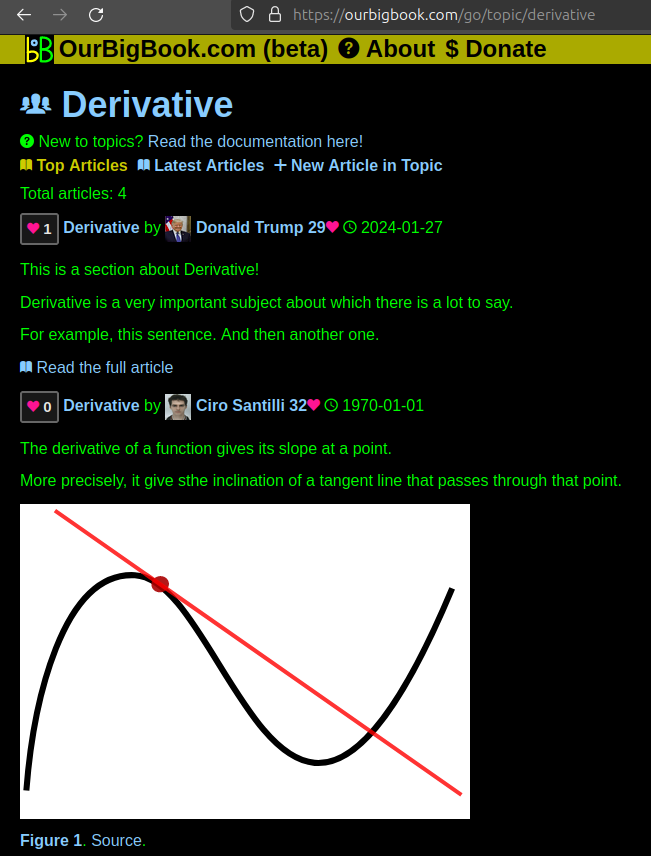
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.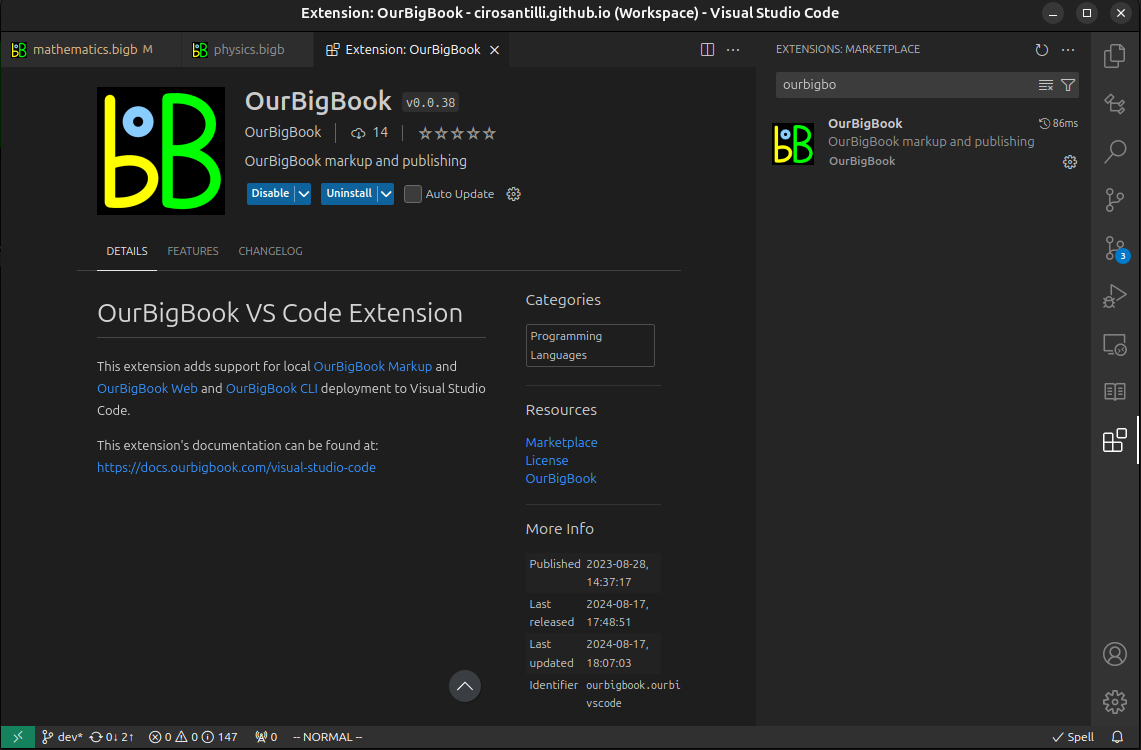
Figure 3. Visual Studio Code extension installation.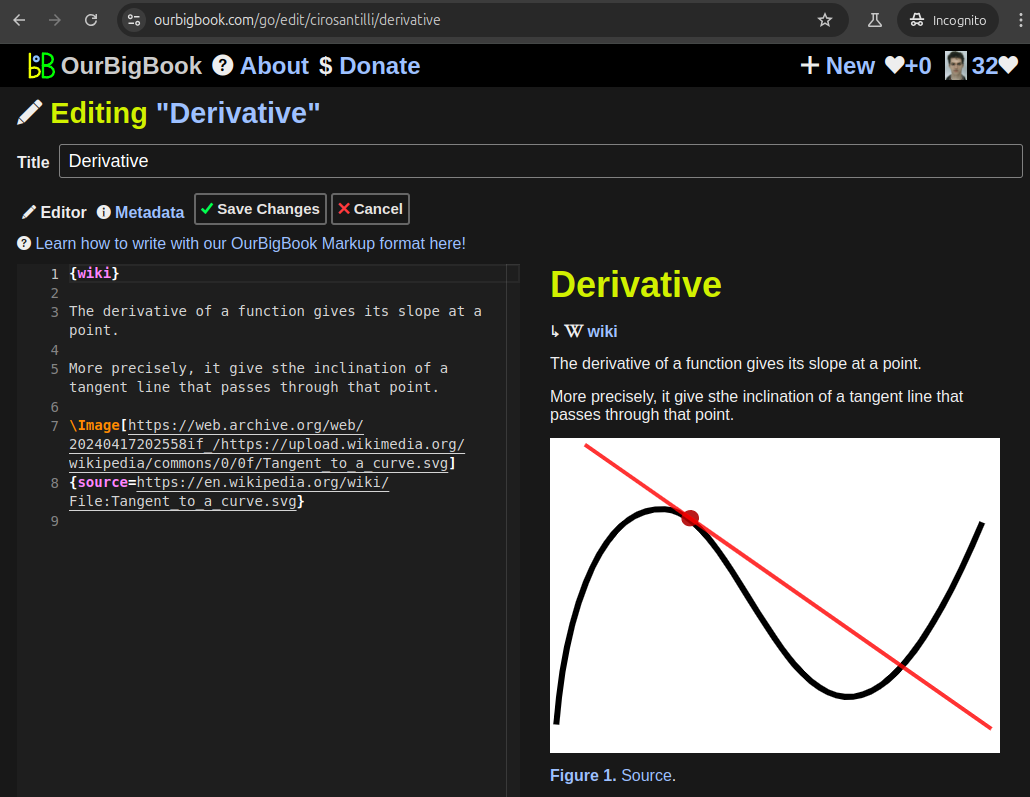
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 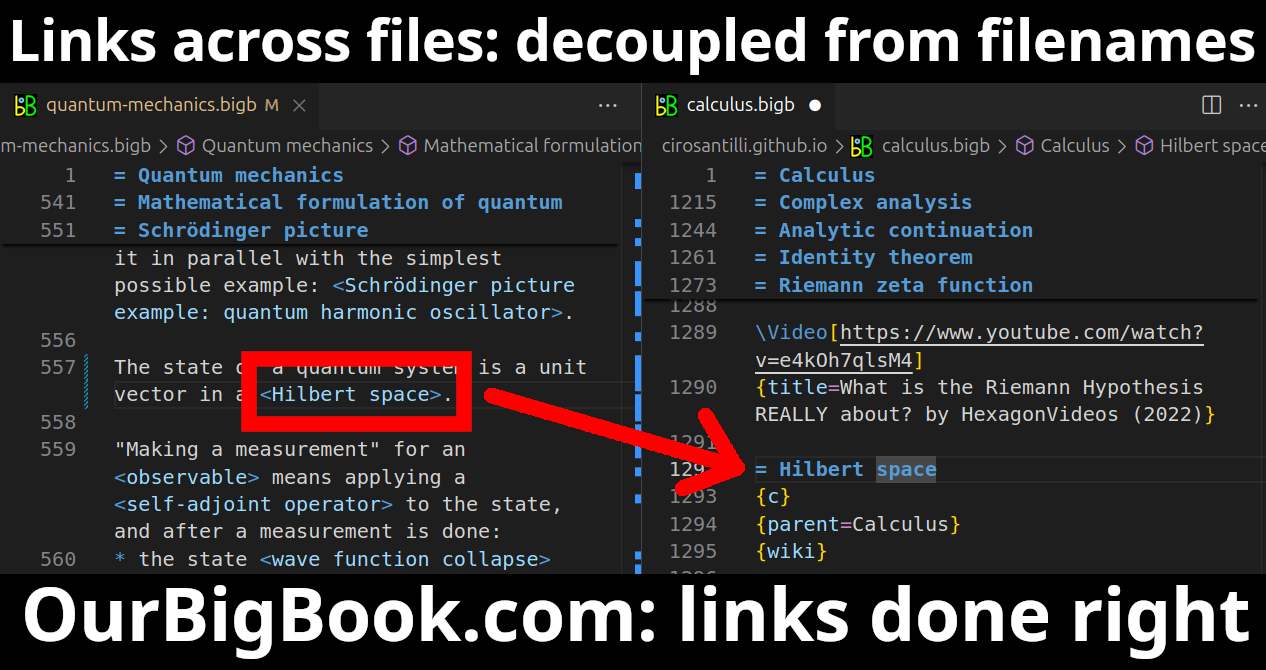
- Infinitely deep tables of contents:
All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact