Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article

A test cross crosses an individual with a homozygote for recessive alleles, allowing suitable offspring phenotypes to reveal transmitted gamete combinations.
Independent assortment means that transmission at different genetic loci has conditional independence given the parental genotype. With fair Mendelian segregation, a parent heterozygous at two genetic loci, , produces gametes with probability each. For example,Here labels an allele combination; it does not assert that the two genetic loci lie on the same chromosome.
The physical model is stochastic orientation of different homologous chromosome pairs toward the two poles of the spindle apparatus in meiosis I. One pair's orientation does not determine another's. For two pairs, one division can send together and together; another can send together and together. See The Process of Meiosis (§11.1, Metaphase I and Figure 11.5: random orientation of chromosome pairs).
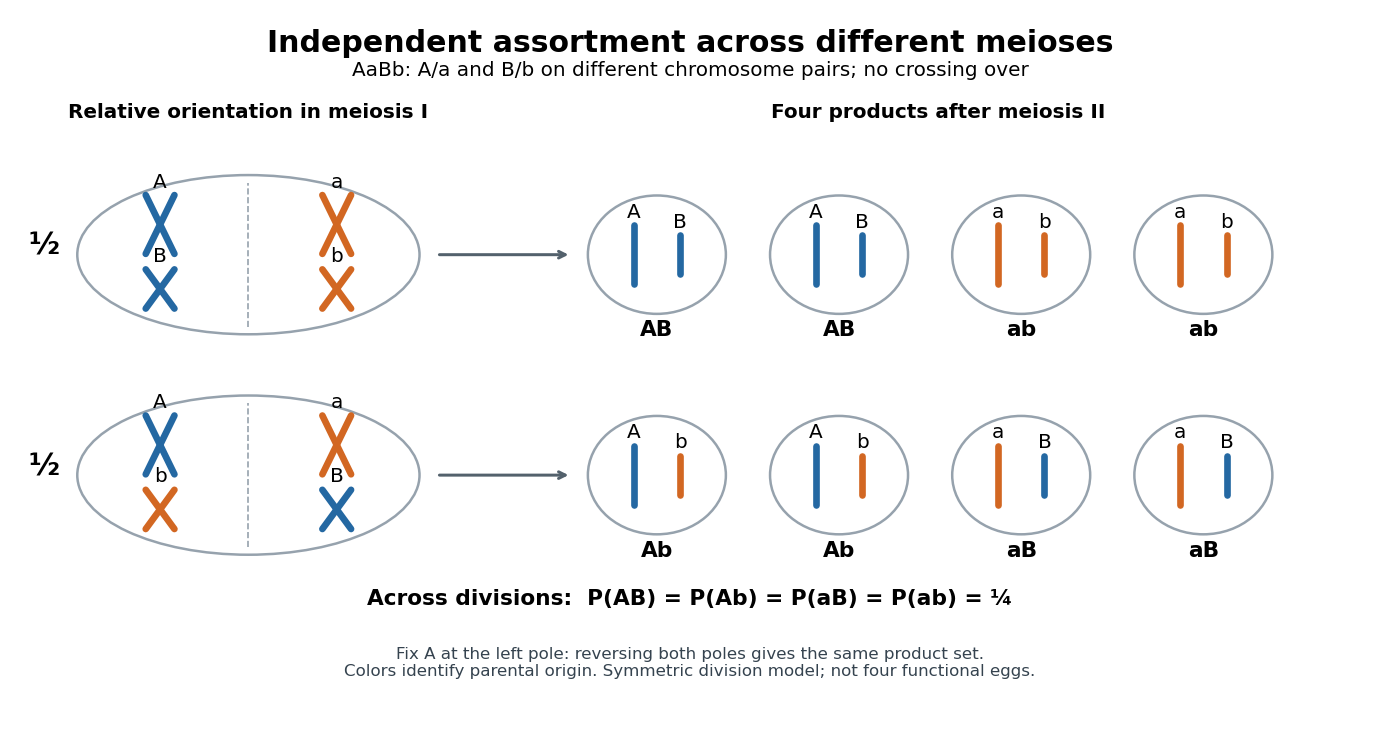
With distinguishable homologous chromosome pairs, there are choices of parental homologous chromosome origin for a product at a specified pole, each with probability under this model. For , enumerate , where M and P mark parental origins. Whole-pole reversal pairs complementary choices, leaving unordered partitions for . For there are four choices for a specified pole but only the two relative orientations drawn. This counts possible products across meioses, not eight different products of one division when . Identical alleles at scored genetic loci can also make different parental-origin choices observationally indistinguishable.
Independent assortment of different chromosome pairs does not imply independence of every pair of genes. Nearby genetic loci on the same chromosome can show genetic linkage. Chromosomal crossover can create new haplotypes, but does not automatically erase genetic linkage. See Laws of Inheritance (§12.3, Law of Independent Assortment and Linked Genes Violate the Law of Independent Assortment). In the ordinary fair two-locus model with parental haplotypes and recombination fraction ,Thus gives only the two parental haplotypes, while gives four equal probabilities. A recombination fraction of alone does not establish that the genetic loci lie on different chromosomes.
A motivating experiment appears in Experiments in Plant Hybridization by Gregor Mendel (§9, “The Reproductive Cells of the Hybrids”). In peas, hybrids for round versus wrinkled seeds and yellow versus green seeds were crossed reciprocally with constant wrinkled-green plants. The readout was visible seed shape and color: hybrid seed parents gave 31 round-yellow, 26 round-green, 27 wrinkled-yellow and 26 wrinkled-green; the reciprocal cross gave 24, 25, 22 and 27.
The apparatus was controlled pollination: opening immature flowers, removing stamens with forceps, and applying selected pollen to the stigma. Two-year trials established constant parental characters; greenhouse pots checked interference from insects in outdoor beds. Reciprocal crosses tested both transmission directions. These procedures are described in Experiments in Plant Hybridization by Gregor Mendel (§§2–3).
With complete dominance at both genetic loci, this test cross makes each phenotype report one hybrid gamete combination. The ideal expected values are and per class. The observations support four transmitted combinations, approximately equally frequent. They do not directly image chromosome orientation or prove independence for all genes; failed development and seed germination also limit the inference, as §9 notes.
An ordered sequence of memory references, recording repetitions as well as addresses. The example under memory cache records twelve reads in decimal physical addresses; the trace itself does not determine cache hits until cache line size, capacity, initial contents, placement and replacement are specified.
For a terminating pure function, a reusable entry must record its correct completed result, and equal memoization keys must imply equal results throughout the entry's memoization cache lifetime. Reusing that result must also preserve the behavior callers require. These conditions separate correctness from speed: a complete key can be correct even if it rarely repeats.
A procedure using deterministic computation can still have a required side effect. If a procedure returns and appends an audit record on every call, serving the second call from a table preserves the numerical answer but skips the second record. Likewise, if each call promises a fresh mutable list, returning the same stored mutable list changes observable sharing and allows a caller to damage later answers. Plain result reuse is unsuitable for those contracts.[ref]
functools — Higher-order functions and operations on callable objects (Python 3.14 documentation). Python documentation, functools.lru_cache: paragraph warning against functions with side effects, distinct mutable results, or impure time/random results
Completion matters for recursion. Suppose computing key needs key , and computing needs . A table containing only completed answers has no answer to return for the second ; remembering completed values does not make this directed cycle terminate. Marking a key
ACTIVE before descending detects re-entry, as in spreadsheet dependency evaluation, but detection is not a solution of the circular equations. If computation fails, clear its active mark and do not publish an unfinished value. The example using Fibonacci numbers avoids this issue through a strictly decreasing argument.The call counts above assume sequential execution and no eviction. Concurrent requests for an absent key can both begin evaluation before either publishes its result; keeping a table coherent alone does not ensure one body execution per key.[ref]
functools — Higher-order functions and operations on callable objects (Python 3.14 documentation). Python documentation, functools.cache and functools.lru_cache: thread-safe cache updates can still allow repeated evaluation before completion
Under constant-cost lookup and integer addition, Memoized Fibonacci evaluation has time complexity in Big O notation, retaining values. A hash table needs its own lookup-cost assumptions; an array indexed by avoids hash collisions in this example. Memoization removes repeated bodies, but also pays for keys, lookups and retained answers. A workload without reuse can pay those costs without saving evaluations.
The call stack remains. Left-first recursion descends through arguments before returning, giving simultaneously active frames for . Therefore the auxiliary space complexity includes frames as well as table entries in the constant-size-value model. An iterative bottom-up dynamic programming calculation removes these recursive frames; retaining only the two previous Fibonacci numbers suffices when only the final value is wanted, but discards the table useful for later requests.
Exact Fibonacci numbers do not remain constant-size values. For , the recurrence relation gives , so the representation of as a binary number has order bits. With ordinary addition costing order bit operations on such operands, the additions cost order bit operations in total. Retaining all values also requires order bits of value storage, before keys and frame overhead. The linear bound counts additions under its stated cost model; it is not a linear bound on exact integer arithmetic in bits.[ref]
Lecture 15: Recursive Algorithms (6.006 Spring 2020) by Massachusetts Institute of Technology, 6.006 course staff. MIT 6.006 Spring 2020, Lecture 15: Recursive Algorithms, printed p. 3, final three bullets: growing Fibonacci bit lengths and addition cost
The Fibonacci numbers give an exact example. For a nonnegative integer , their recurrence relation isTo obtain by direct recursion, evaluate and separately; computing also evaluates . The full call tree has 15 occurrences but just six distinct arguments, . Shared dependencies form a directed acyclic graph because every directed edge goes to a strictly smaller argument. Memoization evaluates a distinct argument on first demand; filling values in increasing argument order is the corresponding bottom-up dynamic programming calculation.[ref]
Lecture 15: Recursive Algorithms (6.006 Spring 2020) by Massachusetts Institute of Technology, 6.006 course staff. MIT 6.006 Spring 2020, Lecture 15: Recursive Algorithms, printed pp. 2–3, Fibonacci Numbers and Re-using Subproblem Solutions
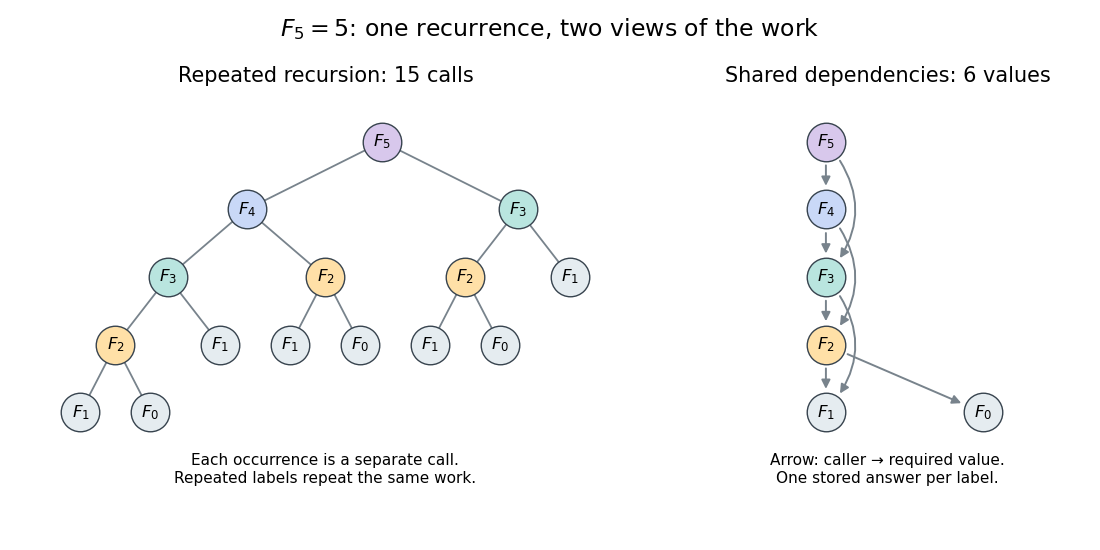
Repeated calls for Fibonacci numbers and their shared directed acyclic graph of dependencies
. The call tree contains 15 occurrences for . The dependency graph contains six distinct arguments and eight directed edges. Equal labels have equal colors; arrows in the right panel point from a caller to the value it requires. Details.Use an initially empty hash table
memo, shared by every recursive call. Count even the first evaluations of the two base cases, store only completed results, evaluate the left term first, and retain all entries. The following original procedure assumes a nonnegative integer argument:def cached_fib(n, memo):
if n in memo:
return memo[n]
if n < 2:
value = n
else:
value = cached_fib(n - 1, memo) + cached_fib(n - 2, memo)
memo[n] = value
return valueEvery self-call must pass through the memoization lookup. Wrapping only the outer call while leaving inner calls uncached retains the repeated work. Test membership rather than whether the stored value is nonzero: is a valid completed result.
For cold , the lookup arguments are . The first six are absent; the last three reuse completed answers. Results are stored on return in argument order , with values . Thus there are nine wrapper calls, six body evaluations and four additions. Repeating with the same table takes one wrapper call and no body evaluation. Requesting next evaluates only its body, reuses and , and stores : three wrapper calls, one body evaluation and two hits.
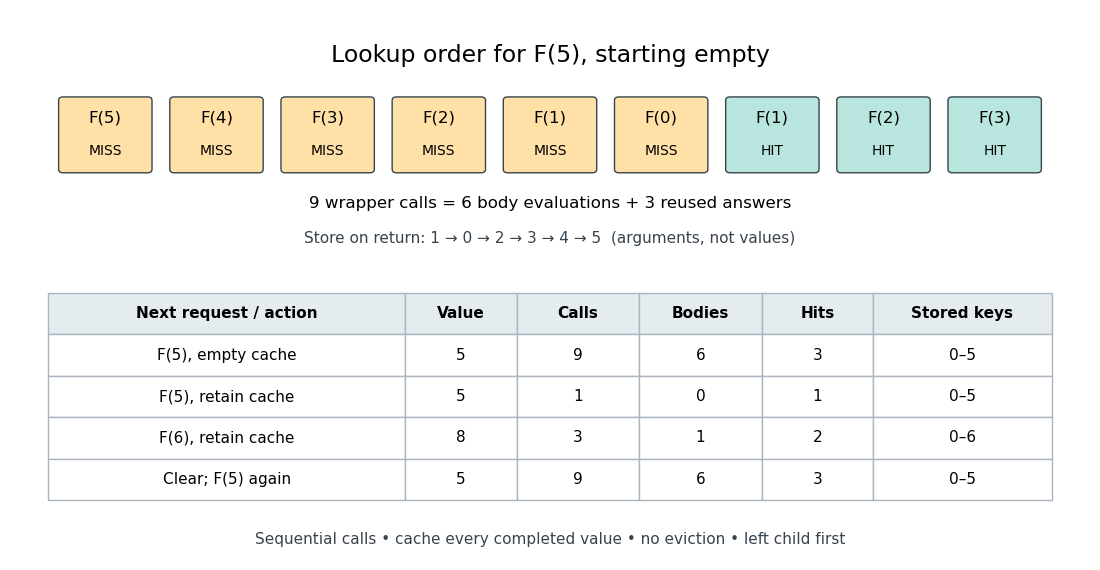
An exact memoization lookup trace and the effect of retaining or clearing its table
. The first row records cold lookup order. The table records successive requests with one retained table; clearing it before the final request restores the cold counts. Calls include lookups that immediately return stored values; bodies count only first evaluations. Details.The direct-call count satisfies and . Its exact solution is , as substitution into this recurrence relation verifies. With the specified memoization procedure, a cold call at evaluates distinct bodies, makes additions and makes wrapper calls. There are hits: each of the nonbase bodies issues two recursive calls, in addition to the initial call. The difference is between the number of occurrences and the number of distinct subproblems.
Overlapping subproblems occur when several parts of a calculation request the same smaller problem. Memoization can share its answer if the memoization key identifies that problem completely. For the Fibonacci numbers, both and require . In dynamic programming, the dynamic programming state plays the corresponding role of identifying a reusable continuation. Overlap explains potential savings; the recurrence relation and its base cases still need to be correct.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact