
Matrix-game optimization problem Created 2026-09-24 Updated 2026-11-05
For a finite two-player zero-sum game with payoff matrix to the row player, its mixed-strategy optimization problem isEvery column inequality says that the expected payoff against that pure column is at least . A randomized column gives an average of these payoffs, so the same guarantee holds against every mixed opposing strategy. The constraints on make it a probability vector. The corresponding minimizing linear-program dual gives the column player's security problem and the finite minimax value.
Laplace transform of a matrix exponential Created 2026-09-24 Updated 2026-11-05
Eddington luminosity Created 2026-09-24 Updated 2026-10-25
Balancing outward radiative acceleration against gravity givesIt is an approximate upper luminosity for a hydrostatic star of opacity .
Exponential Markov bound Created 2026-09-24 Updated 2026-10-14
Applying Markov's inequality to the positive random variable givesHere is the moment-generating function, and the useful bound requires it to be finite at the chosen . Optimizing over gives the Chernoff bound method: an exponential function weights large values more strongly before applying the same average-budget argument.
For example, let have the Poisson distribution with parameter one. Its expected value and variance are both one, and its moment-generating function is . At threshold four, choosing givesThis minimizes the exponent because its derivative is , with positive second derivative. The direct Markov's inequality bound is , and the two-sided Chebyshev's inequality bound, applied to a deviation of at least three from the mean one, is . The exact Poisson distribution tail probability is . These compare three valid bounds obtained from progressively different information; none is an exact tail probability formula for general random variables.
Gibbs sampler Created 2026-09-24 Updated 2026-11-05
A Gibbs sampler constructs a Markov chain by repeatedly drawing coordinates from their full conditional distributions given the current values of the other coordinates. For a two-coordinate target density , a sweep draws and then . Each update preserves the target joint law: retaining one marginal and resampling its exact conditional reconstructs the same joint density. Thus a sweep has the target as a stationary distribution. Convergence from arbitrary starts additionally needs suitable irreducibility and other conditions; disconnected support can trap a chain. Successive output samples are usually dependent.
Effective sample size of a Markov chain Created 2026-09-24 Updated 2026-11-05
For a stationary Markov chain observable with positive variance and absolutely summable autocorrelation function ,If the limiting integrated autocorrelation time , the leading variance is . Matching this to the sample-mean variance of independent observations defines .
This is an observable-specific variance comparison, not a literal count of independent retained states. Positive serial dependence reduces effective sample size; negative dependence can make it exceed . For a stationary AR(1) observable with coefficient , and the asymptotic effective sample size is . Estimated effective sample size also requires reliable estimation of the long-run covariance; it does not prove that all modes have been explored.
Random-walk Metropolis algorithm Created 2026-09-24 Updated 2026-10-20
Random-walk Metropolis proposes a symmetric increment from the current state and accepts a proposal from with probability .
Marked-state phase oracle from a single faulty identity-oracle query Created 2026-09-24 Updated 2026-11-05
Radial volume transform of a homogeneous Poisson point process Created 2026-09-24 Updated 2026-11-05
For a homogeneous Poisson point process of intensity in , mapping to , where is the unit-ball volume, gives a rate- Poisson process on . Mapping to instead gives rate .
Unbiased prediction-error identity for ordinary least squares Created 2026-09-24 Updated 2026-10-14
If is the rank- orthogonal projection onto a normal linear model's column space, thenAdding gives , so Mallows' is unbiased for independent-copy prediction error even when the projection model is misspecified.
Bias-variance decomposition for linear prediction Created 2026-09-24 Updated 2026-10-14
If are independent vectors and is a rank- orthogonal projection, thenThe first term is squared approximation bias, while is fitted-model variance and is irreducible new-response noise.
Magnetic-dipole spin-down Created 2026-09-24 Updated 2026-11-05
If a rigid body's inclined magnetic dipole rotates at angular speed , its radiated power is . Conservation of rotational energy then gives
Bruhat decomposition of SL2 over a finite field Created 2026-09-24 Updated 2026-11-05
This is the finite special-linear-group instance of the general Bruhat decomposition.
For the upper-triangular subgroup of andthe two double cosets are and , and , the diagonal subgroup.
Mackey irreducibility criterion Created 2026-09-24 Updated 2026-11-05
For a finite group , a subgroup , and an irreducible complex representation of , the induced representation is irreducible exactly when, for every nonidentity double coset representative , the restrictions of and its -conjugate to have inner product zero.
Power singularity integrability Created 2026-09-24 Updated 2026-10-14
Essential supremum Created 2026-09-24 Updated 2026-10-14
The essential supremum is the upper bound for a measurable function after disregarding null sets for a specified measure . Its definition iswith values allowed in the extended real number line. A supremum controls every value; an essential supremum controls values almost everywhere. It therefore depends on the chosen measure, as well as on the function. [ref].
For a worked example, use Lebesgue measure on and putIts supremum is ten, attained at . But its essential supremum is one: outside the singleton , which is a null set. Every candidate fails, because the interval has positive Lebesgue measure and includes values larger than ; changing one point cannot remove that interval. In particular, , while .
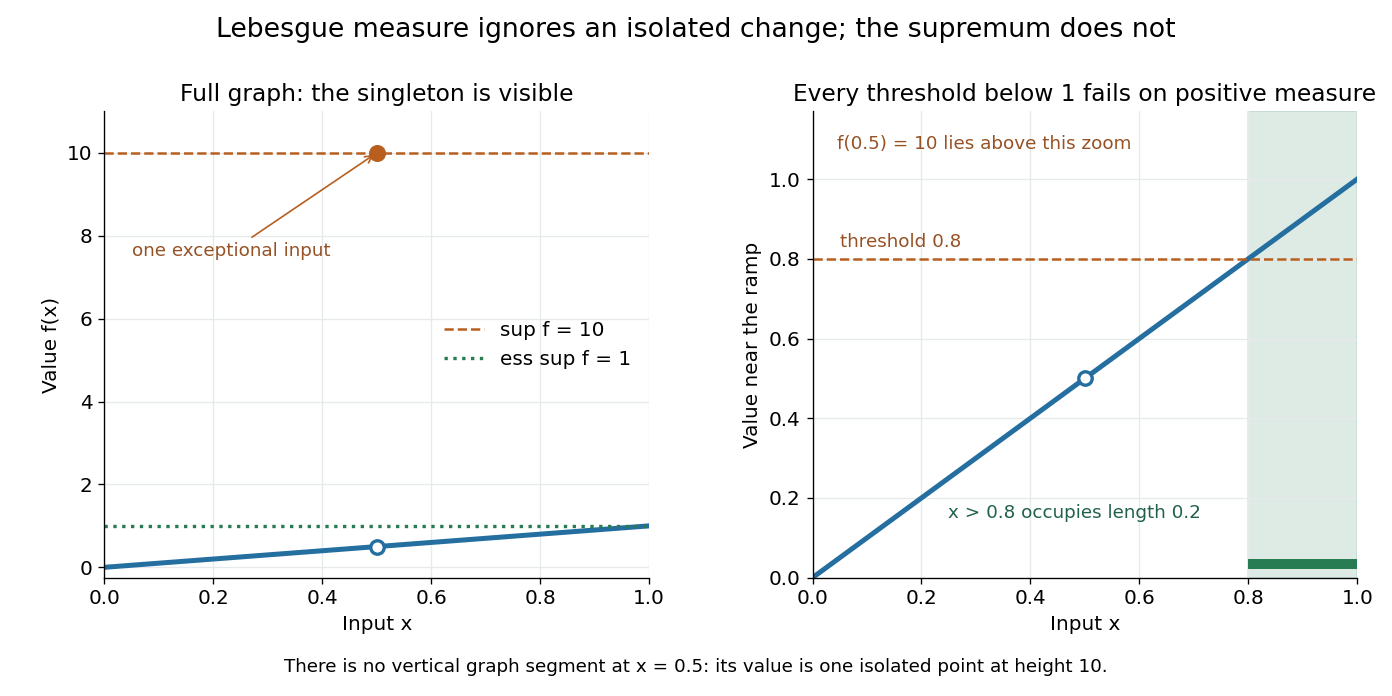

Why is this useful? Lebesgue integrals ignore changes on null sets, and Lp spaces identify functions that agree almost everywhere. The L-infinity norm uses so it respects that identification. For this nonnegative example the supremum norm is ten and the L-infinity norm is one; replacing by changes the former while leaving the latter unchanged. [ref].
The measure qualification is essential. For , the Dirac measure concentrated at the exceptional input, that singleton has measure one and this function has essential supremum ten. A set ignored by one measure need not be ignored by another. The lower counterpart is the essential infimum, with .
Kruskal-Katona theorem Created 2026-09-24 Updated 2026-10-06
Downward Lowenheim-Skolem theorem Created 2026-09-24 Updated 2026-09-24
Upward Lowenheim-Skolem theorem Created 2026-09-24 Updated 2026-10-31
If an -theory has an infinite model, then it has models of arbitrarily large cardinality. For a cardinal , add constants for and all inequalities . Every finite fragment is satisfiable in the given infinite model, so compactness gives a model with at least elements. Applying the downward theorem produces a model of exactly when .
Lopsided Lovász local lemma Created 2026-09-24 Updated 2026-10-06
There are unlisted articles, also show them or only show them.