
Chi-squared divergence Created 2026-09-24 Updated 2026-09-24
Kullback-Leibler divergence Created 2026-09-24 Updated 2026-10-14
The Kullback-Leibler divergence, also called relative entropy, compares two probability distributions in a specified order. In , observations follow and the comparison probability distribution is : the first argument supplies the averaging weights. For probability mass functions on a finite alphabet,Here is a random variable with probability distribution . For probability density functions relative to the same measure , replace the sum by . These formulas use natural logarithms unless stated otherwise. The expected value is under , even though appears in the denominator. [ref]
Take and on two outcomes. Direct calculation givesThe second outcome contributes negatively to the first sum: assigning it more probability than does makes its individual contribution negative. Nevertheless, relative entropy nonnegativity guarantees a nonnegative total. Reversing the arguments changes both the likelihood ratio and the averaging probabilities; taking an absolute value inside the logarithm would define a different quantity.
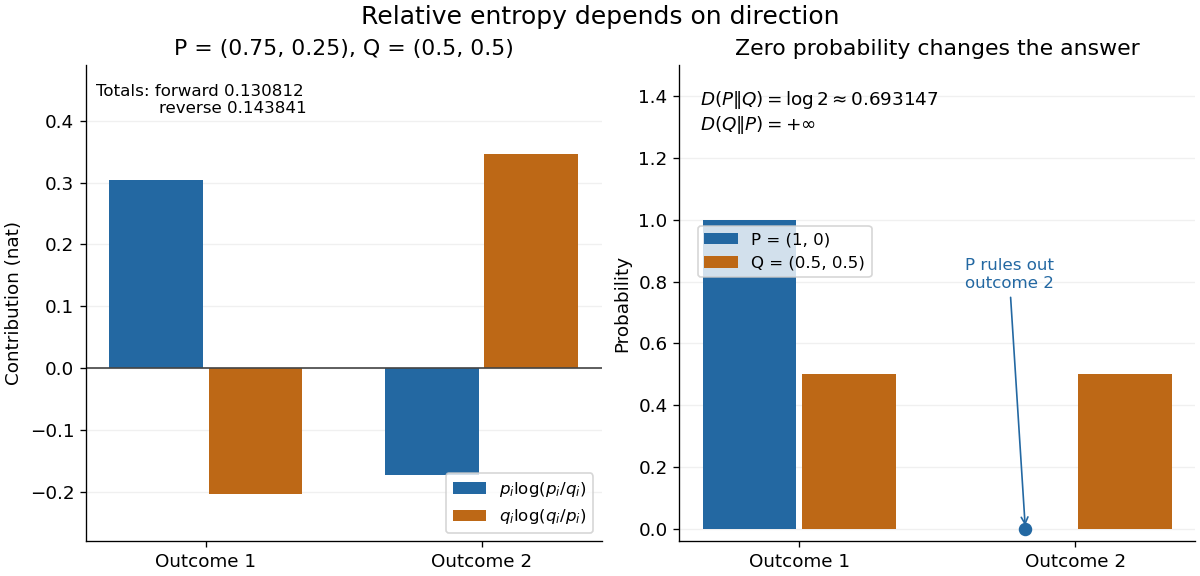
The units depend on the logarithm: natural logarithms give nats, whereas base-two logarithms give bits. Divide a value in nats by to obtain bits; the forward example is approximately bits. Changing the base rescales every Kullback-Leibler divergence by the same positive factor. Since the two calculated directions differ, Kullback-Leibler divergence is asymmetric and cannot be a metric. It also need not satisfy the triangle inequality. [ref]
https://web.stanford.edu/~kedart/ee376a_winter1617/Lecture_3.pdf. Tse, relative entropy, 2017, Section 3.3
The operational meaning is an expected penalty for using the wrong probability distribution. A prediction incurs log-loss when outcome occurs, the negative of the logarithmic scoring rule. Under , its expected value is the cross-entropy . Predicting with itself incurs information entropy , soThus Kullback-Leibler divergence is exactly excess expected log-loss, whenever these separate quantities are finite. [ref]
https://web.stanford.edu/class/ee276/files/previous_notes/lecture_2.pdf. Weissman, information measures, 2024, property 3
For lossless source coding, ideal codeword lengths similarly give excess expected length in bits per symbol. Actual prefix codes require integer codeword lengths; Shannon's source coding theorem explains how long blocks approach ideal per-symbol lengths. The interpretation concerns an average, not a fractional physical bit attached to every outcome. In our example, ideal coding with costs one bit per symbol, while bits; the difference is exactly the computed bits. [ref]
https://web.stanford.edu/~kedart/ee376a_winter1617/Lecture_3.pdf. Tse, information theory, 2017, Section 3.4
Zeros require explicit conventions. An outcome with contributes zero, including when ; the convention agrees with the relevant limit. If but , the Kullback-Leibler divergence is infinite: the predictor has declared impossible an outcome that can occur. On a finite alphabet, the probability support of must therefore be contained in the probability support of for a finite answer. For example, and give , but . For general probability measures, failure of absolute continuity of measures likewise gives infinity. Even does not guarantee a finite integral. [ref]
https://arxiv.org/pdf/1206.2459. van Erven and Harremoës, Rényi Divergence and Kullback-Leibler Divergence, 2014, Section II
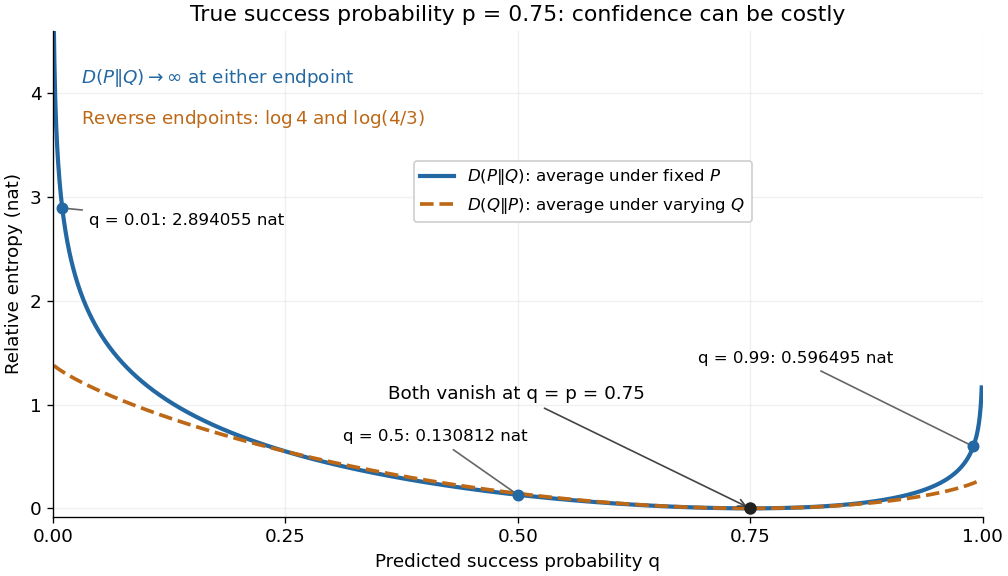
To see how confidently wrong predictions are punished, hold the true Bernoulli distribution parameter at and vary the predicted parameter . Its binary relative entropy isIt vanishes at , equals approximately nats at , and equals nats at . Both endpoints give infinity because both outcomes remain possible under . Predicting almost no successes is especially costly because successes actually occur three quarters of the time. The reversed binary relative entropy stays finite at the endpoints: its averaging probability distribution concentrates on just one outcome, and assigns positive probability to both.


For model selection, minimizing expected log-loss ranks candidate statistical models by , since is common to them. The true probability distribution is usually unknown, so one estimates predictive performance using fresh observations or cross-validation. Fitting and assessing on the same data can reward overfitting; a small fitted Kullback-Leibler divergence alone does not establish useful prediction.
In variational inference, a tractable trial probability distribution commonly minimizes against a target posterior distribution . Maximizing the evidence lower bound accomplishes this without evaluating the target's normalization constant. The averaging now follows : placing trial probability where the posterior distribution assigns almost none is strongly penalized. The chosen direction and trial family therefore matter. [ref]
https://www.cs.columbia.edu/~blei/papers/BleiKucukelbirMcAuliffe2017.pdf. Blei, Kucukelbir and McAuliffe, Variational Inference: A Review for Statisticians, 2017, Section 2.2
These comparisons do not by themselves establish causal inference. Two statistical models can reproduce the same observed probability distribution while predicting different responses to an intervention. Choosing the smaller Kullback-Leibler divergence therefore needs additional assumptions or experimental evidence before supporting a causal claim. [ref]
https://ftp.cs.ucla.edu/pub/stat_ser/r350.pdf. Pearl, Causal inference in statistics: An overview, 2009, Section 2
The original reference is S. Kullback and R. A. Leibler's 1951 paper [ref]
https://doi.org/10.1214/aoms/1177729694. On Information and Sufficiency
, published in The Annals of Mathematical Statistics 22(1), pages 79–86. Its title connects this comparison with sufficient statistics: the historical setting was statistical information, before today's widespread applications in prediction and variational inference. Set family Created 2026-09-24 Updated 2026-09-24
Frankl-Wilson theorem Created 2026-09-24 Updated 2026-09-24
Let be a prime number, let have elements, and suppose satisfies for distinct members while . The Frankl-Wilson theorem givesIts polynomial method in combinatorics turns modular intersection restrictions into linearly independent functions represented by square-free monomials of degree .
Set family shadow Created 2026-09-24 Updated 2026-09-24
Colexicographic order Created 2026-09-24 Updated 2026-10-03
For equal-size finite subsets and , precedes in colexicographic order when the largest element of their symmetric difference belongs to .
Lexicographic order Created 2026-09-24 Updated 2026-10-18
For equal-size subsets and of an ordered ground set, precedes in lexicographic order when the smallest element of their symmetric difference belongs to .
For finite sequences over a total order, lexicographic order compares the first differing sequence terms; the smaller term determines the smaller sequence. If one sequence is a proper prefix of the other, the shorter precedes its extension. For fixed-length tuples, this is the first-difference rule used by radix sort key encoding.
Exoplanet bulk-composition ternary diagram Created 2026-09-24 Updated 2026-09-24
Exoplanet habitability Created 2026-09-24 Updated 2026-09-24
Exoplanet habitability concerns whether planetary conditions could sustain liquid water and life, while recognizing that observability and habitability are distinct questions.
Exoplanet atmosphere Created 2026-09-24 Updated 2026-10-05
An exoplanet atmosphere controls the planet's spectrum, heat redistribution, chemistry, clouds, and atmospheric escape.
Finite fibres of the Euler totient function Created 2026-09-24 Updated 2026-09-24
For each positive integer , only finitely many satisfy . Indeed, every prime has , and the exponent of in is bounded because .
Multiplicativity of the Euler totient function Created 2026-09-24 Updated 2026-09-24
Euler theorem Created 2026-09-24 Updated 2026-10-06
Multiplication by a unit permutes the reduced residue classes modulo . Multiplying all classes before and after this permutation and cancelling their unit product proves .
Euler-Lagrange equations for two fields Created 2026-09-24 Updated 2026-09-24
Natural boundary conditions for a free endpoint Created 2026-09-24 Updated 2026-09-24
When the values of are free at both fixed endpoint locations, integration by parts leaves the boundary term . Since the endpoint variations are arbitrary, stationarity requires
Catenary Created 2026-09-24 Updated 2026-09-24
A catenary is a curve of the form . It is the equilibrium shape of a uniform flexible chain in a uniform gravitational field.
Beltrami identity Created 2026-09-24 Updated 2026-10-06
Integral momentum equation Created 2026-09-24 Updated 2026-09-24
Bernoulli equation Created 2026-09-24 Updated 2026-10-14
For steady inviscid flow, pressure, kinetic energy density, and conservative potential are constant along a streamline.
Clebsch-potential variational derivation of incompressible Euler flow Created 2026-09-24 Updated 2026-09-24
There are unlisted articles, also show them or only show them.