A statistic is sufficient for a statistical model when the conditional distribution of the full data given has a version independent of the unknown statistical parameter . Once is recorded, the remaining uncertainty about the data's arrangement can be generated without knowing . [ref]
Sufficiency (Stat 210a, Fall 2025) by Will Fithian. Sufficiency, Will Fithian, “Sufficiency”: definition
For data and statistic taking values in standard Borel spaces, express this precisely with one Markov kernel , common to every statistical parameter value:for each measurable event . Thus is a regular conditional distribution of given . Equality is only required outside a null set for the distribution of under each ; the choice of version matters on impossible conditioning events. For a continuous probability distribution, the event may have zero probability even at meaningful observations, so the definition uses a regular conditional distribution, rather than division by .
A sufficient statistic is a property of a specified statistical model, rather than of a formula for summarizing data in isolation. It need not be an unbiased estimator or even shorten the record: the full data is always sufficient. An estimator instead targets a quantity such as a mean. An ancillary statistic has a parameter-independent marginal probability distribution, whereas a sufficient statistic has a parameter-independent conditional full-data law. A minimal sufficient statistic permits the greatest reduction among sufficient statistics. A complete statistic satisfies a separate condition about zero expectations; a complete sufficient statistic must satisfy both conditions.
Let be fixed and known, and let be independent and identically distributed Bernoulli random variables with common success probability . Their joint probability mass function, on the binary sample space , isThere are arrangements with successes, so has the binomial distribution. For and , its exact conditional full-data probability mass function isThis conditional distribution is uniform over arrangements, with no dependence on : the sum is a sufficient statistic. [ref]
Sufficiency (Stat 210a, Fall 2025) by Will Fithian. Sufficiency, Will Fithian, “Independent Bernoulli sequence”: conditional pmf
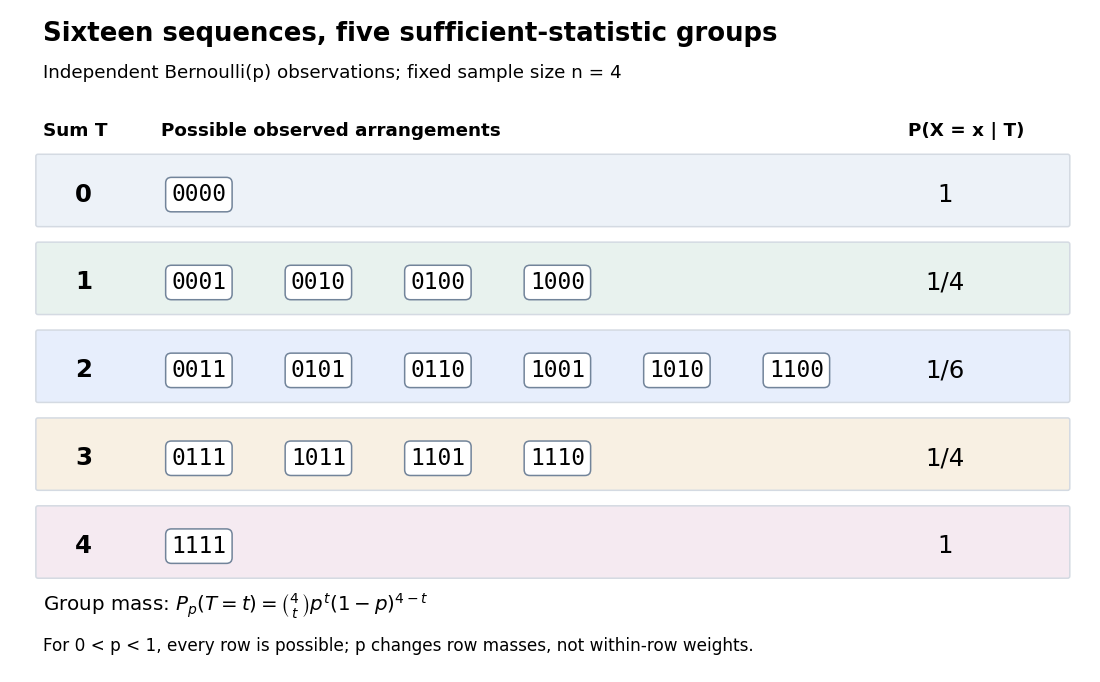
Four Bernoulli observations grouped by their sufficient sum
. All sixteen binary sequences are grouped by . Within each group the conditional distribution is uniform; changing changes the group's total probability, not the conditional weights within it. Details.For , the group sizes are and the within-group conditional probabilities are respectively . For example, leaves exactly , each with conditional probability . At , each such sequence has unconditional probability and the group has probability . At , these values are and ; at they return to and . The conditional weights stay in all three cases.
At the boundary , only has positive probability; at , only does. Dividing by on the other groups would divide by zero. Nevertheless, the same uniform-on-arrangements Markov kernel is a valid common version for the entire family : it gives the correct point mass on the one observed group at each boundary and assigns permissible versions on its unobserved groups. Define the joint probability mass function there by the original product of the one-trial Bernoulli probability mass functions, or use the limiting convention in the compact formula.
The sample mean is an unbiased estimator of and retains the sufficient statistic because is known. By contrast, is also an unbiased estimator of but, for , is not sufficient: the conditional success probability of the independent given is still . Thus unbiasedness does not imply sufficiency.
Sufficiency also does not imply completeness of a statistic. For , the full-data sufficient statistic admits the nonzero function with expectation zero for every . Nor does minimality imply completeness of a statistic: for and the restricted statistical model , is a minimal sufficient statistic since the likelihood ratio distinguishes its three values. Yet has expectation at both parameter values and is never zero. Changing the parameter family can change completeness of a statistic even while preserving sufficiency.
A sufficient statistic allows the observed likelihood function to be stored through a shorter record, up to a parameter-independent factor. For the Bernoulli sample sum as a sufficient statistic, writeThe second likelihood function belongs to the observed count; the first belongs to the observed sequence. Their absolute values differ by the binomial coefficient, but their likelihood ratios between any two interior parameter values agree. A maximum-likelihood estimator can therefore use just .
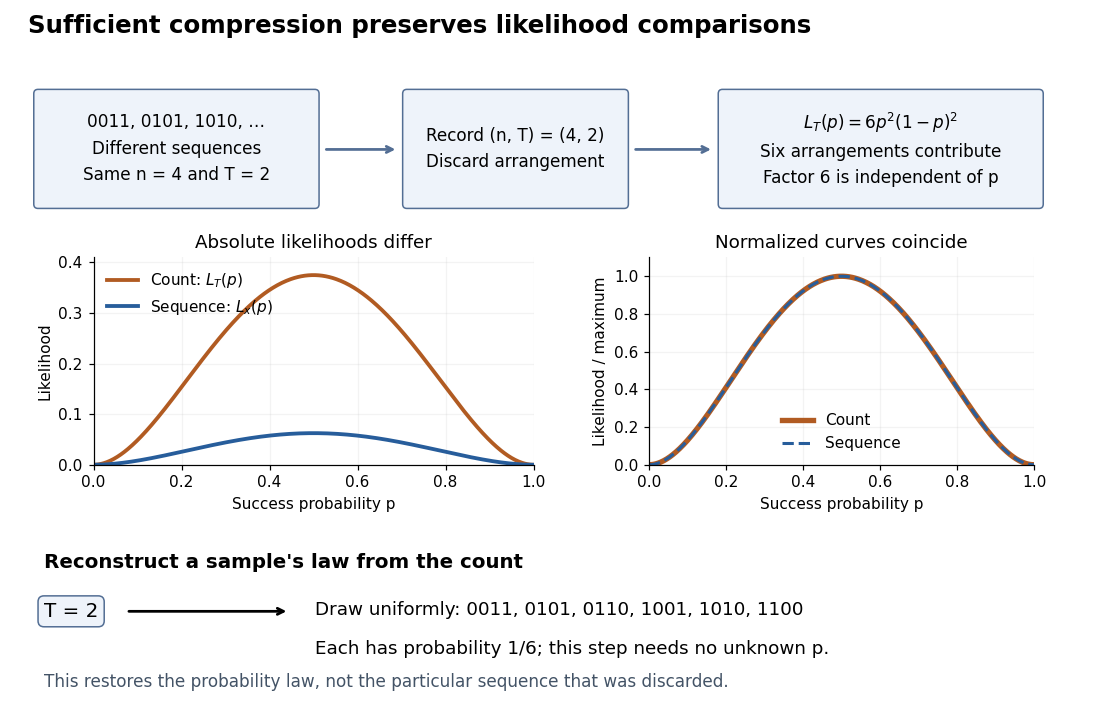
Sequence to count: sufficient compression preserves likelihood comparisons
. For , three example sequences share . Recording produces the count likelihood . Normalizing each curve by its maximum makes the two curves coincide. A reverse random draw from the six arrangements restores the full-data probability distribution, using no unknown . Details.This compression discards which arrangement actually occurred. To reproduce the original experiment's probability distribution, first draw from its binomial distribution and then draw uniformly from the arrangements with that sum. The second step is independent of , so it supplies no additional evidence about . It does not recover the particular discarded sequence. If the scientific question changes to time trends or statistical dependence between observations, the common- independent and identically distributed Bernoulli model may no longer apply, and the ordering can become informative.
A statistic is ancillary for a statistical model if its probability distribution is the same for every parameter value. Its marginal law carries no information about the parameter, but its observed value can identify the precision or configuration of the experiment. Fisherian conditional inference uses the conditional distribution of an informative statistic given the observed ancillary value. Ancillarity does not mean that the ancillary is independent of every informative statistic.
For independent observations uniform on , let and be the sample minimum and maximum, , and . For their joint density in is on , . Integrating over gives , independent of , so is an ancillary statistic. Moreover is uniform on . Consequentlyis an exact conditional confidence interval for . The realized range determines the appropriate precision, although the range is not itself evidence about the value of .
A maximal ancillary statistic has no strictly finer ancillary partition of the sample space, but different maximal ancillary partitions can exist. Let take values in , with probabilities on each equal pair and on each unequal pair, for . Both and have the Bernoulli distribution with success probability for every . Their joint law depends on , so combining them is not ancillary. Each partition is maximal: splitting one of its two-point cells singles out a point whose probability depends on . There is no common ancillary refinement, and conditioning on one ancillary choice need not specify a unique conditioning principle for all models.
For a parameter of interest and nuisance parameter , a partial ancillary for has a marginal law independent of , possibly depending on . This differs from a fully ancillary statistic, whose law is independent of both. For independent Poisson counts with means and , their total is Poisson with mean , while the first count conditional on the total is binomial with success probability . Conditioning on the total eliminates . A partial ancillary does not automatically eliminate a nuisance parameter; the conditional law must actually be free of that parameter.
For a sufficient statistic and parameter , a useful strong reduction requires the law of to be free of and the conditional distribution of given to be free of the nuisance parameter . In the discrete case it giveswhere sums to one on each fiber, sums to one over , and sums to one over separately for every fixed . Ordinary ancillarity, or just the law of being free of , does not by itself guarantee that conditioning removes .
A sufficient statistic is complete when every integrable function of it with expectation zero for every parameter is almost surely zero for every parameter. Full regular one-parameter exponential families with natural parameter ranging over an open interval provide a standard completeness result. Completeness makes an unbiased function of a sufficient statistic unique, giving the Lehmann–Scheffé theorem.
A complete sufficient statistic is independent of every ancillary statistic. To prove this, let be complete and sufficient, let be ancillary, and take any bounded measurable function . By sufficiency, has a parameter-independent version; by ancillarity, is independent of . Thus for every . Completeness gives almost surely. Choosing to be the indicator of each measurable event in the ancillary space proves independence. Completeness is essential: a sufficient statistic may itself contain a nonconstant ancillary, as in the minimum and maximum of a uniform location sample.
For independent observations with known variance, is minimal sufficient for . Factorization proves sufficiency, while the likelihood ratio for two samples is independent of exactly when their sums agree.
A sufficient statistic is minimal sufficient when it is a function of every other sufficient statistic, up to null sets. Its level sets form the coarsest sufficient partition of the sample space.
For independent samples uniform on with , the absolute maximum is a minimal sufficient statistic, since the likelihood is . The pair of sample minimum and maximum is a sufficient statistic but is not minimal: simultaneous sign reversal preserves and generally changes that pair.
Assume the full-data sample space and the range of the statistic are standard Borel spaces, is a measurable function, and the statistical model is dominated by one common sigma-finite measure . Write for its densities. Then is a sufficient statistic if and only if there exist nonnegative measurable functions and , with independent of , such thatThe statistical parameter can enter only through and the observed . [ref]
Sufficiency (Stat 210a, Fall 2025) by Will Fithian. Sufficiency, Will Fithian, “Factorization theorem”: common dominating measure and almost-everywhere factorization
For discrete data, take counting measure; for ordinary continuous data, take Lebesgue measure. Independence, identical sampling laws, smooth dependence on , and a fixed positive support of a probability distribution are not requirements of this theorem. Parameter-dependent support must nevertheless be included in , usually through an indicator function, and must fit the displayed factorization. The sufficient statistic for a symmetric uniform sample illustrates exactly this: its indicator function depends on the unknown scale through the observed absolute maximum. The null sets in the theorem concern versions of densities; the factors are not generally themselves normalized probability distributions.
For a discrete sample space, the cancellation behind the theorem is particularly transparent. On a group with positive probability, factorization givesConversely, multiply a common conditional probability mass function by to obtain the required factorization. For continuous data, a sum over a group is not a density integral over the original Lebesgue measure: the group may have measure zero. Use the regular conditional distribution formulation and the Fisher-Neyman factorization theorem instead of that discrete calculation.
For the normal sample sum with known variance, assume independent and identically distributed with fixed known variance . The joint probability density factors asThe Fisher-Neyman factorization theorem proves that the sum, and hence the sample mean, is a sufficient statistic for . Its remaining deviations have a joint Gaussian law independent of and are independent of . If both and are unknown, the sample mean alone loses information about variance; the pair is sufficient for the full statistical parameter.
A discrete counterexample shows why a sample mean is not automatically sufficient for arbitrary statistical models. Let be independent and identically distributed on withEach observation has mean one. The arrangements all give sample mean one, yetThis conditional probability is at and at . The conditional distribution therefore still depends on the unknown statistical parameter: this sample mean is not a sufficient statistic. The useful reduction depends on the family of full-data laws, even when its mean stays fixed.
Articles by others on the same topic



A **sufficient statistic** is a concept in statistics that refers to a statistic that captures all the information needed to estimate a parameter of a statistical model.