Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Breadth-first search
Adjacency list Created 2026-10-13 Updated 2026-10-20
An adjacency list represents a graph by keeping, for each vertex , a collection of the vertices reached by its outgoing edges. An array indexed by vertex identifiers can locate each collection; the collection itself may use a linked list or an array. In an undirected graph, each nonloop edge supplies an entry at both endpoints.[ref]
Graph.java. Graph.java, class documentation and fields: vertex-indexed adjacency collections; addEdge: entries at both endpoints
For a worked example, take the simple graphwhere denotes the unordered pair . Its adjacency lists, displayed in label order, areThus has three neighbours, although the graph has six vertices. Its list contains exactly the destinations available for a single step from ; no slots are reserved there for . The fourteen neighbour entries represent seven edges, with appearing as in 's list and as in 's list. The label order makes the example easy to read; an adjacency list need not be sorted.
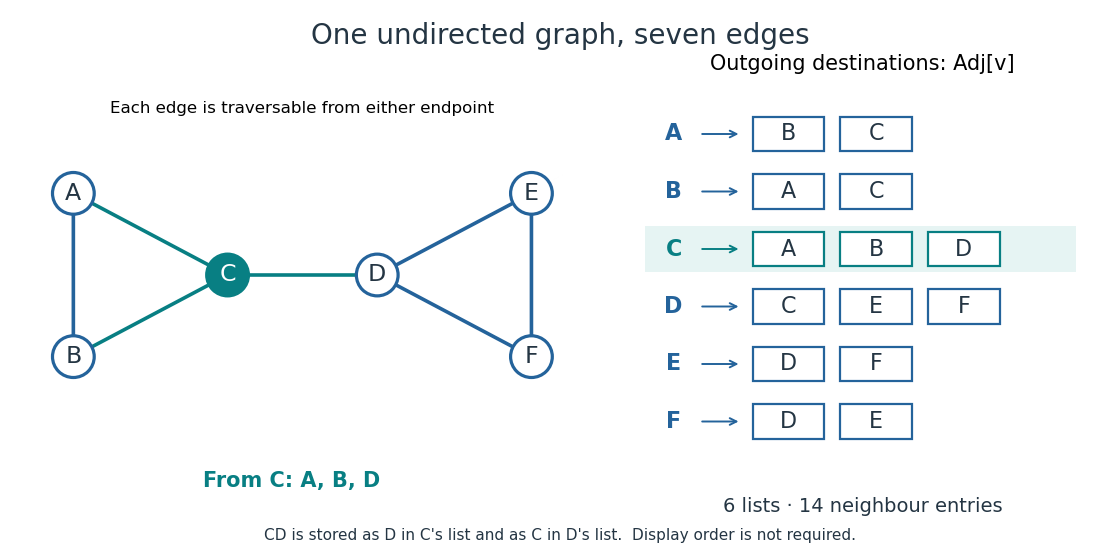
Seven undirected edges and their fourteen adjacency list entries
. Details. The useful idea is to store existing connections explicitly. Neighbour enumeration can then follow exactly the possible next steps, which is what breadth-first search and depth-first search need. In a sparse graph, most pairs of vertices have no edge; adjacency lists avoid reserving a separate adjacency matrix entry for every such absence. Whether this saves work depends on the question: neighbour enumeration and testing one proposed edge have different costs.
Binary search tree Created 2026-10-13 Updated 2026-10-14
A binary search tree stores key-value entries in a binary tree, with distinct keys drawn from a total order. At every vertex, all keys in its left subtree must be smaller than its own key, and all keys in its right subtree must be larger. Thus the entries represent a partial function from keys to values: a key has at most one associated value and may be absent. [ref]
Lookup starts at the root of a tree. Compare the target with the current key: equality returns its value, a smaller target continues into the left subtree, and a larger target continues into the right subtree. Reaching an empty subtree reports absence. The ordering rule justifies discarding the other subtree at every step; this is the algorithm correctness argument for lookup. It applies to the entire subtree, even if that subtree contains many vertices. [ref]
In the seven-key example, search for . At , the comparison selects the right subtree; at , selects the left subtree; at , equality ends the search. The visited keys are , three key comparisons. The right-child chain stores exactly the same keys and satisfies the same binary search tree rule, but lookup of visits , five comparisons. Searching for absent key visits in the first binary search tree and all seven keys in the chain before reaching an empty right subtree.
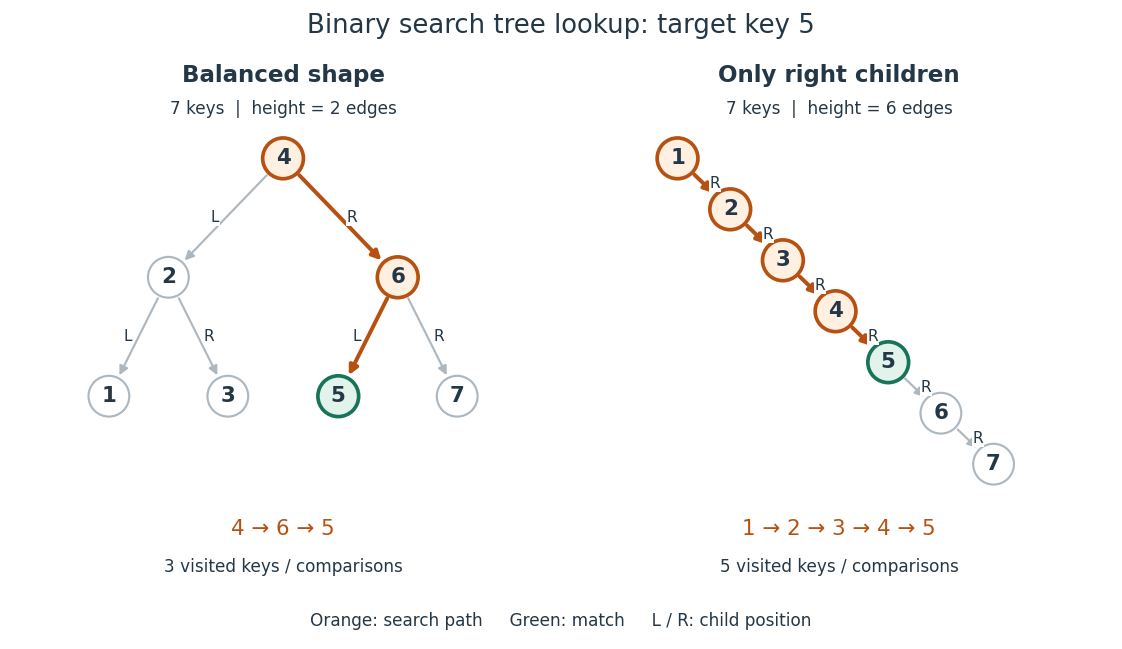
Lookup of key in two binary search trees containing the same seven keys
. Orange highlights visited keys and edges; green marks the match. The balanced shape has height of a binary tree and requires three visits, while the chain has height of a binary tree and requires five visits for this target. Details.For a nonempty binary search tree of height of a binary tree , lookup inspects at most vertices. Under constant-cost key comparisons and child-reference access, its time complexity is in Big O notation, usually written for . With entries, , giving worst-case lookup. If the shape is kept balanced so that , lookup takes for . The empty and one-entry cases take constant work. The worst-case linear bound also appears in Sedgewick and Wayne's ordinary, unbalanced implementation. [ref]
https://raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/BST.java. Sedgewick and Wayne, Algorithms: BST implementation, complexity contract and get method
In a shape with every level full, there are vertices, a geometric series. This explains how a small height of a binary tree can accommodate many entries. The binary search tree ordering rule alone does not guarantee this shape or logarithmic time complexity. Breadth-first search also gains no logarithmic key-lookup guarantee merely from having a binary tree: in the displayed balanced example, its left-to-right level order is , so it inspects six keys before finding , and an absent target requires all seven. Directed lookup uses the total order to choose one branch.
The ordering requirement includes every ancestor on the graph path from the root of a tree. Consider the smaller binary tree with root key , left child , right child , and right child under . Key must satisfy both , from its immediate parent in a rooted tree, and , from its position in the root's left subtree. Replacing by preserves all immediate parent-child comparisons, including , but violates . Lookup for would incorrectly go from to and then to an empty left subtree, overlooking the stored key.
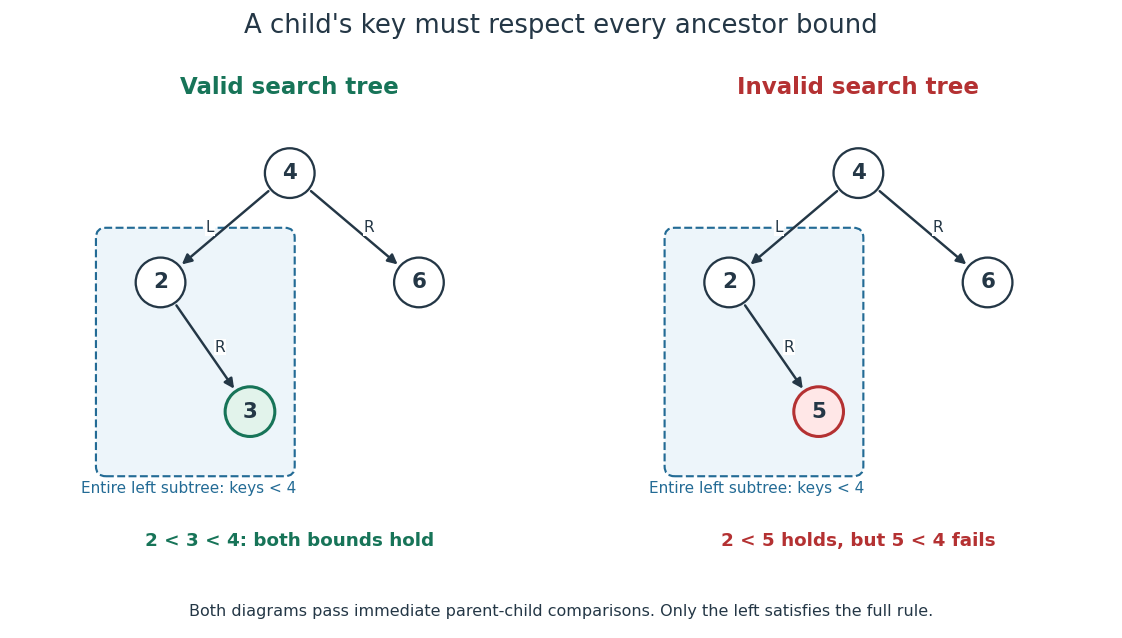
The binary search tree ordering rule constrains an entire subtree
. The valid example has . The invalid example passes immediate parent-child comparisons, but key lies in the left subtree of key and violates its inherited upper bound. Details.An inorder traversal visits a left subtree, then its own vertex, then a right subtree. On the valid small example its output is ; on the invalid example it is , exposing the descent from to . Both seven-key binary search trees yield . The theorem is that an inorder traversal of a finite binary search tree with distinct keys lists every key once in strictly increasing total order. For a short proof outline, use mathematical induction on the number of vertices: each smaller subtree produces its own sorted list, and the full ordering rule places every left key before the current key and every right key after it. Concatenating these three parts preserves strict order. Sedgewick and Wayne's
keys method uses this left-current-right order. [ref]https://raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/BST.java. Sedgewick and Wayne, Algorithms: BST keys method and inherited-bound isBST check
This combination is useful and attractive: one data structure supports directed lookup and ordered enumeration. An inorder traversal costs time complexity for entries, since it visits every vertex; balance accelerates lookup but cannot eliminate the work of outputting all keys.
// Destination: computer-science.bigb
Bipartite graph Created 2026-09-24 Updated 2026-10-14
A bipartite graph separates its vertices into two independent sets: every edge goes from one part to the other. Here is a finite simple graph and an undirected graph, with no self-loops and no repeated edges. The two parts satisfyThus neither part contains an edge. The parts need not have equal sizes, and some pairs across them may have no edge; requiring every cross pair gives a complete bipartite graph. The independent set and cross-edge definitions are equivalent.[ref]
The Basics (author-hosted chapter preview). Section 1.1, printed p. 3, independent vertices; Section 1.6, printed p. 17, bipartite and complete multipartite graphs
For example, the six-vertex cycle graph with edges has parts and . Drawing the same graph as a hexagon or in two columns changes neither its edges nor its bipartite property. An extra isolated vertex can go in either part.
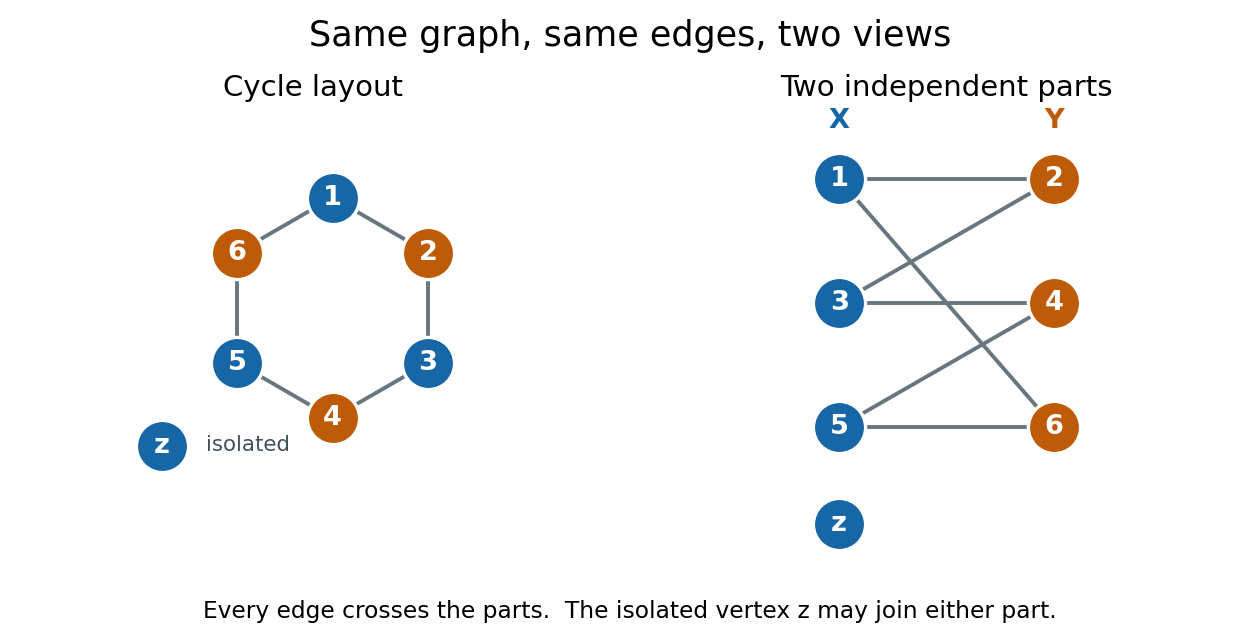
We allow either part to be empty. Consequently a graph with no edges is bipartite, even when ; choose , . Here "two colours" means two colours are available, with no requirement to use both. This convention explicitly includes the empty case, whereas definitions requiring two nonempty classes need an exception. For several connected components of a graph, choose the two parts separately in each graph component and take their unions. In a nonempty connected graph that is bipartite, fixing one vertex's colour forces all others along graph paths, so its two-colour assignment is unique up to swapping the colours. Each graph component, including an isolated vertex, can be swapped independently.
The two-colourability criterion for bipartite graphs identifies these parts with the colour classes of a proper vertex colouring: assign colour to and colour to , so adjacent vertices have different colours. More surprisingly, the odd-cycle characterization of bipartite graphs turns a global requirement into one precise obstruction:This statement is for the finite undirected graph and simple graph model above; a graph cycle has distinct vertices except for the repeated starting vertex. Along a graph cycle in a bipartite graph, colours alternate, so returning to the starting colour takes an even number of edges. Therefore any odd cycle, whether or not other edges join its vertices, prevents a bipartite split.[ref]
The Basics (author-hosted chapter preview). Section 1.6, Proposition 1.6.1 and proof, printed pp. 17–18
Breadth-first search supplies the converse constructively. Start an uncoloured vertex with colour , and use a FIFO queue to explore its graph component. When an edge first discovers , give the opposite colour to , record as its parent in a rooted tree, and enqueue . If both endpoints of any scanned edge already have the same colour, stop with a conflict. Restart from an uncoloured vertex until every graph component has been examined. If no conflict occurs, all edges cross the two colour classes, which are the required independent sets.[ref]
A conflict also explains the failure. In the rooted tree produced by breadth-first search, let be the graph distance from . The colour of is its distance's integer parity. An edge in an undirected graph satisfies , so equal colours force . Follow the two parent chains upward to their lowest common ancestor , discard the shared graph path from to , and join the remaining two graph paths with the conflict edge . The result is a genuine graph cycle withedges, an odd integer. The two branches have no shared vertices except , so this is more than a closed walk. This odd cycle is a certificate that anyone can check directly, using only its listed vertices and edges.
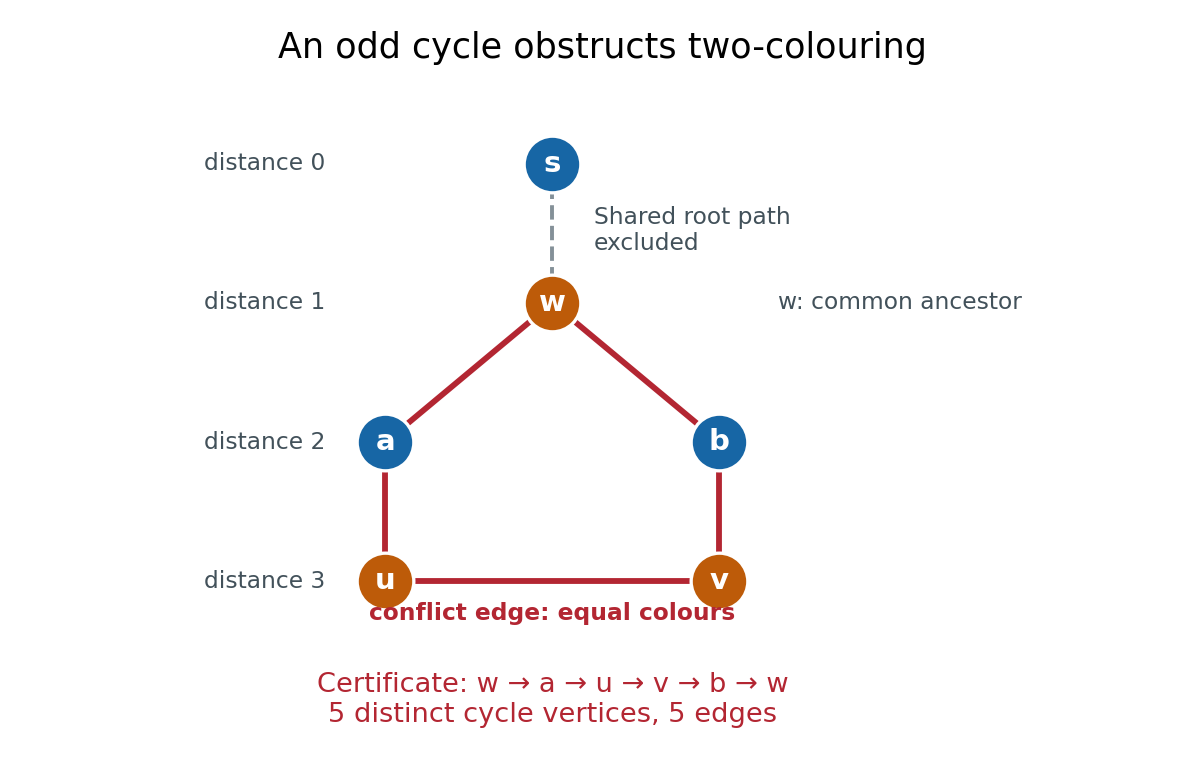


In the example, breadth-first search from gives , , and . The conflict edge closes the odd cycle , with five edges. The common edge is excluded. Thus the same procedure returns either two independent sets covering , or an explicit odd cycle. With adjacency lists and constant-time FIFO queue operations, its time complexity is in Big O notation, with additional storage.[ref]
The two parts often have a practical meaning: workers and jobs, with an edge exactly when a worker can perform a job. A matching in a graph chooses compatible worker–job pairs with no reused endpoint; merely being bipartite does not guarantee enough compatible pairs. Hall's marriage theorem characterizes when every worker can be matched, and the assignment problem adds costs to seek an optimal assignment. These connections make the bipartite structure useful after recognition, as the starting point for selecting edges under constraints.
Breadth-first exploration of a binomial random graph Created 2026-10-07 Updated 2026-10-14
During breadth-first search of let count unseen vertices, active vertices, and explored vertices. When start a new unseen root, recorded by ; otherwise . The newly discovered count is conditionally . Subtract its conditional mean to obtain a martingale difference . With , and , iteration givesThe last sum is a martingale. Positive over an interval means that the graph component under exploration does not finish there. Independently adding phantom children couples each component exploration below a binomial branching process with offspring law .
Breadth-first search Created 2026-09-24 Updated 2026-10-14
Breadth-first search is a graph search that explores successive layers of graph distance from a starting vertex . Here the graph is an undirected graph on a finite set of vertices, and distance counts edges, with no differing edge weights. Mark as discovered, assign , and place it in a FIFO queue. Repeatedly remove the front vertex and scan its adjacency list. Whenever a graph neighbour is still undiscovered, mark it immediately, record as its parent in a rooted tree in the discovery tree, assign , and enqueue at the rear. Marking on insertion ensures that another edge cannot enqueue the same vertex again. [ref]
https://raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/BreadthFirstPaths.java. Sedgewick and Wayne, Algorithms: BreadthFirstPaths queue and discovery rule
Use the same undirected graph as depth-first search, with vertex set and edgeswhere denotes the unordered pair . Start at and scan graph neighbours in lexicographic order of their one-letter labels. The diagram's generator computes the following layers and the parent in a rooted tree assigned to each discovered vertex; the source is the root of a tree and has no parent in a rooted tree.
| Graph distance from | Vertices in discovery order | Parent in a rooted tree in the same order |
|---|---|---|
| none | ||
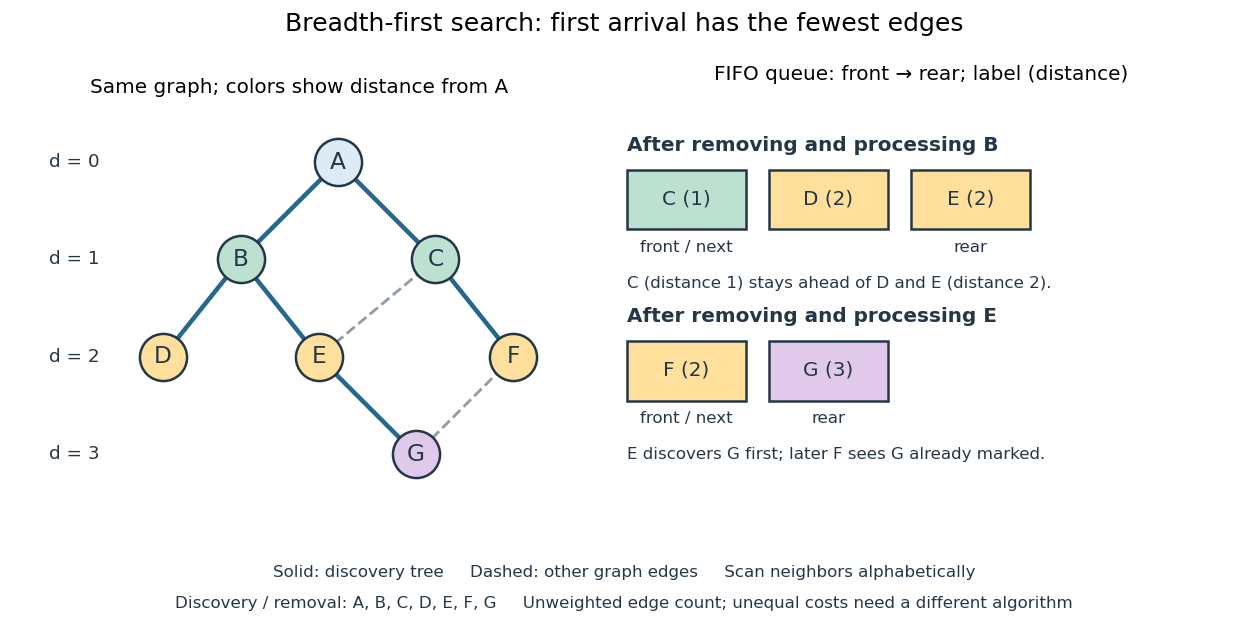

The discovery and removal orders both happen to be . After processing , the FIFO queue is : must be processed before the newer . Processing then skips the already discovered and enqueues , giving . Processing adds nothing. Processing discovers , giving ; later sees already marked and leaves its parent in a rooted tree unchanged. The discovery edges are , forming a rooted tree on all seven vertices even though the original graph contains graph cycles. The discovery tree contains six edges; it need not contain every examined edge.
First arrival is shortest because the FIFO queue keeps assigned distances in nondecreasing order, with entries from at most two consecutive layers. While processing distance , newly discovered vertices receive distance and join the rear. If an undiscovered vertex had a shorter graph path, its preceding vertex on that graph path would lie in an earlier layer and would already have discovered it. Thus is the minimum number of edges from to . This is a mathematical induction over the layers, not an assumption about the drawing. Following the parent in a rooted tree backwards at each step gives ; reverse that sequence to obtain the three-edge graph path . is another shortest graph path, but the specified graph neighbour order makes discover first. Changing that order can change the parent in a rooted tree without changing graph distances. [ref]
https://ocw.mit.edu/courses/6-006-introduction-to-algorithms-fall-2011/1208e162775f6f5cedfbb9f2b694ede0_MIT6_006F11_lec13.pdf. MIT 6.006, lecture 13: distance layers and shortest paths, pp. 4–6
The shortest-route guarantee concerns the shortest path problem measured by edge count. It also minimizes total cost when every edge has the same positive cost. With unequal edge weights, first discovery need not minimize total cost; nonnegative costs can instead be handled by the Dijkstra algorithm. Breadth-first search is useful for minimum-hop routes and for finding all vertices within a specified graph distance. Its FIFO queue finishes an older layer before the next one, whereas depth-first search uses a call stack or explicit LIFO stack to pursue one branch immediately.
With adjacency lists and constant-cost discovery checks, together with constant worst-case or amortized analysis cost for FIFO queue insertion and removal, the time complexity is in Big O notation. Every reached vertex is enqueued and removed once, each incident edge is scanned at most twice in an undirected graph, and initializing all marks and distances takes . The FIFO queue contains at most vertices; the example's maximum is three. Discovery marks, distances and the recorded parent in a rooted tree for each nonroot vertex also give auxiliary space complexity, excluding the graph. An array that shifts every entry on front removal can lose the linear time complexity; the FIFO queue abstraction alone does not make removal constant-cost. Ordering the adjacency lists is a separate preprocessing cost.
A single start reaches only its connected component of a graph. Unreached vertices retain distance and have no recorded parent in a rooted tree. Restarting at each still-undiscovered vertex, while preserving all discovery marks, produces a forest covering the graph; each new root of a tree gets distance zero, so these distances refer to that root of a tree, not to the original .
Breadth-first tree search 2026-10-25
The tree search version of breadth-first search explores action histories in nondecreasing length without automatically removing repeated states. A finite branching factor ensures that every finite depth contains finitely many histories, so the method is a complete search algorithm for goals reachable at finite depth. With equal positive action costs it is an optimal search algorithm for total action cost. It need not terminate on an unsolvable instance with an infinite search tree, and it need not optimize a terminal reward unrelated to depth.
Complete binary tree Created 2026-10-13 Updated 2026-10-14
A complete binary tree is a binary tree whose levels are full except possibly the deepest, which is filled from left to right with no gaps.[ref]
9.1 Binary trees. Data Structures and Algorithms, section 9.1.1: complete shape and binary heap example
Here a level groups vertices by their graph distance from the root of a tree. A binary heap uses this shape to maintain logarithmic height of a binary tree. Completeness differs from the two-children condition of a full binary tree.
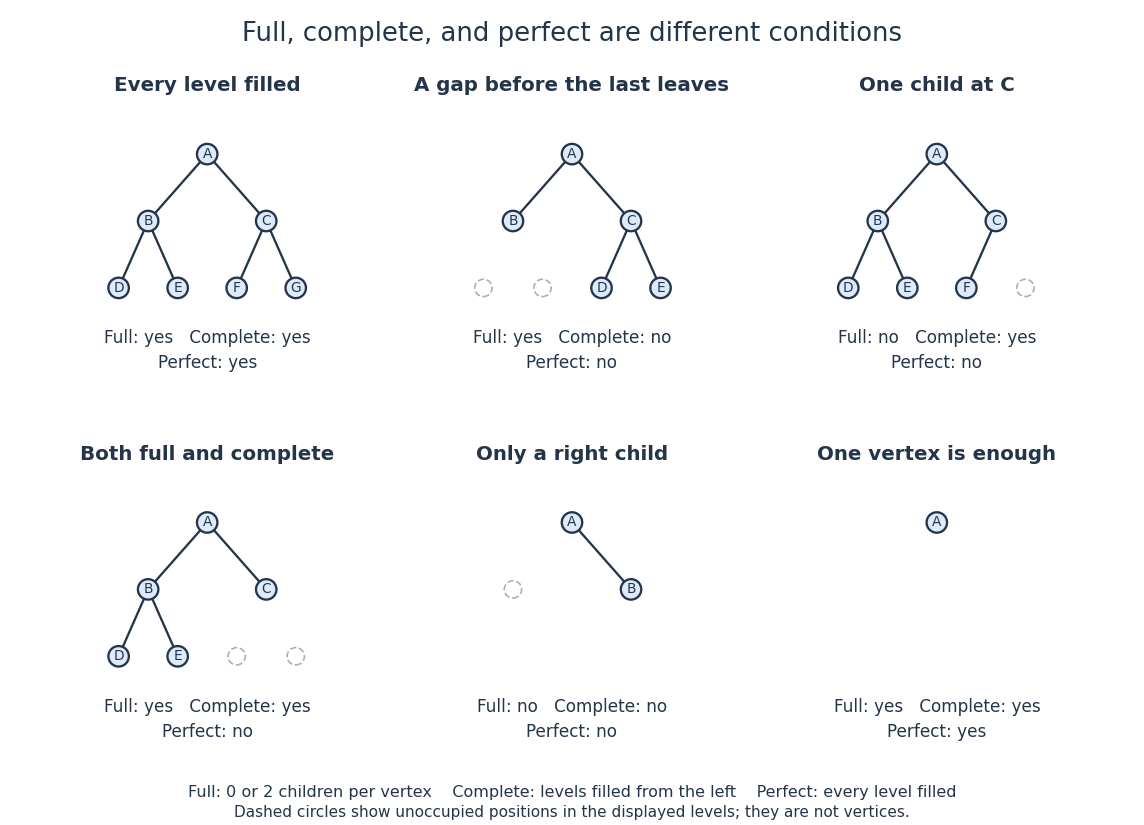
Full binary trees, complete binary trees, and perfect binary trees impose different shape conditions
. Each panel states all three properties. Outlined positions expose gaps in the last level. In particular, the five-vertex example in the lower left is both full and complete but is not perfect. Details.
For a six-vertex example, give two children in a rooted tree , give two children in a rooted tree , and give only a left child . The levels have vertices, and the last occupies its first three positions, so this is a complete binary tree. It is not a full binary tree, since has exactly one child. Moving to the right slot of preserves and height of a binary tree , but leaves a gap before and destroys completeness. Merely keeping the deepest vertices near the left side is insufficient; every earlier position must be occupied.
Number positions by the left-to-right level order of breadth-first search, beginning with root position . The children of position have positions and . A nonempty complete binary tree occupies exactly positions , so its height of a binary tree is : positions form level . This consecutive occupancy explains the compact array representation of a binary heap, while heap order is a separate condition on values. Neither completeness nor the binary tree definition supplies the binary search tree ordering rule.
Connected graph Created 2026-09-24 Updated 2026-10-14
An undirected graph is connected when every pair of vertices is joined by a finite graph path. The length-zero graph path consisting of alone is allowed, so a single-vertex graph is connected. We use the term here for nonempty graphs; conventions for the graph with no vertices vary. Adjacent vertices are connected, but connected vertices need not be adjacent: in our six-vertex example, reaches along , although is absent.
Allowing walks instead of graph paths gives the same test for a connected graph. Whenever a finite walk revisits a vertex, delete the intervening closed portion; repeating this leaves a graph path with the same endpoints. This simple shortening argument explains why revisiting locations cannot help decide reachability.[ref]
https://ocw.mit.edu/courses/6-1200j-mathematics-for-computer-science-spring-2024/mit6_1200j_s24_lec13.pdf. MIT, Connectivity and Trees, Theorem 1
Connectivity can conceal fragile connections. Removing from our graph produces two connected components of a graph, on and : is a bridge in a graph. Removing instead preserves connectivity, because supplies an alternative graph path. If edges represent communication links, this calculation says precisely which single link failure separates the two groups. It is a conclusion about this model, independent of the lengths in its drawing.
A tree is a nonempty connected graph without a graph cycle; equivalently, each pair of vertices has exactly one graph path between them. Delete and from our example. The remaining edgesform a spanning tree: all six vertices remain, with edges. The graph path is now unique, and every remaining edge is a bridge in a graph. Adding back creates exactly one graph cycle, . Thus graph cycles express alternative routes, while a tree retains just enough connections for reachability. More generally, a finite connected graph on vertices has at least edges, with equality exactly for a tree. One proof repeatedly removes an edge on a graph cycle, preserving connectivity, until a spanning tree remains.[ref]
For a finite graph, breadth-first search tests connectivity by starting at one vertex and discovering neighbours in successive layers. Starting at , the layers in our example are , , , . Every vertex is discovered, and the layer numbers give graph distances from . Recording one discovery edge for each new vertex constructs a spanning tree. This turns an existence question into both a concrete route and a certificate of connectivity.
Depth-first search Created 2026-10-13 Updated 2026-10-20
Depth-first search is a graph search that follows a branch as far as it can before returning to try the next unexplored branch. Starting at a vertex of an undirected graph on a finite set of vertices, mark as discovered. Scan its graph neighbours in a fixed order: for each undiscovered vertex, record the current vertex as its parent in a rooted tree in the discovery tree, mark the new vertex, and explore it immediately using recursion. Return when its adjacency list is exhausted. Discovery marks persist after return, preventing a graph cycle from causing repeated exploration. This branch-and-return rule is the maze exploration described in MIT's notes. [ref]
Use the same unweighted undirected graph as breadth-first search, with vertex set and edgeswhere denotes the unordered pair . Visit graph neighbours in lexicographic order of their one-letter labels, starting at . The discovery order, computed by the diagram's generator, isThe discovery edges in order are . They form a rooted tree spanning the reached vertices, with root of a tree . The other edges, and , remain in the original graph but never discover a new vertex. In particular, the graph cycle causes no repeated discovery.
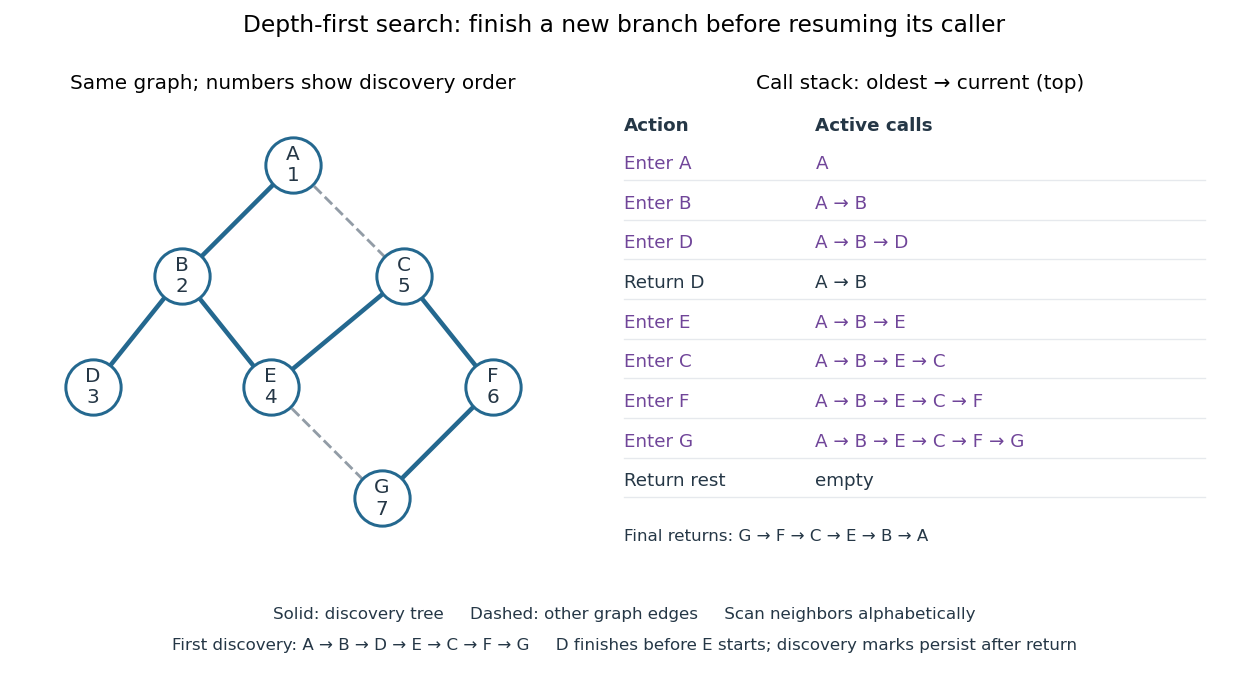

At there is no undiscovered graph neighbour, so its call returns to . The next call enters , then , then , then . Immediately after discovering , the call stack is , with on top; is still discovered but its call has finished. The maximum call stack depth is six, although seven vertices are discovered. Following the recorded parent in a rooted tree backwards at each step reconstructs a graph path; here the route from to is , using five edges. Breadth-first search instead finds , using three edges. Depth-first search establishes reachability but does not guarantee the fewest edges.
An explicit LIFO stack can replace recursion, but its entries and discovery rule must be specified. To reproduce this exact traversal, store one frame per active vertex, retaining the next position in its adjacency list. Advance the top frame by one graph neighbour; if that vertex is undiscovered, mark it and push its frame immediately; pop an exhausted frame. Pushing all undiscovered graph neighbours at once and marking them on push is a different iterative variant. Even pushing them in reverse lexicographic order does not generally reproduce the parent in a rooted tree relationships above: would already be marked while processing , so could not discover .
With an adjacency list representation, constant-cost discovery checks and frame operations, and the graph neighbours already ordered, depth-first search has time complexity in Big O notation. Each reached vertex is entered once and each incident edge is examined at most twice in an undirected graph; initializing all discovery marks costs . The call stack has depth at most , since no active vertex repeats. Discovery marks and the recorded parent in a rooted tree for each nonroot vertex also need auxiliary space complexity, excluding storage for the graph. Sorting adjacency lists to obtain a chosen order is additional work. [ref]
https://raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/DepthFirstPaths.java. Sedgewick and Wayne, Algorithms: DepthFirstPaths discovery marks and resource bounds
One start explores only its connected component of a graph. To cover a disconnected graph, start again at every still-undiscovered vertex while keeping all discovery marks; the discovery trees form a forest. Depth-first search is useful for reachability, constructing a spanning tree of a connected graph, and organizing the return steps needed by a depth-first traversal of a tree. For detecting a graph cycle in a simple graph that is an undirected graph, an edge to an already discovered vertex other than the current parent in a rooted tree closes a graph cycle; the immediate return edge to that parent in a rooted tree is not itself a graph cycle.
// Target: computer-science.bigb
Edmonds–Karp algorithm Created 2026-10-06 Updated 2026-10-14
This maximum flow algorithm repeatedly augments along a shortest residual path found by breadth-first search. Residual distances from the source never decrease. If the same arc becomes saturated again after being restored by a reverse augmentation, the distance to its tail has increased by at least two. Thus each arc is critical only times, yielding augmentations. Each search costs , so the total time is . Termination with no residual source-sink path supplies a max-flow min-cut theorem certificate.
FIFO queue 2026-10-13
A FIFO queue is a data structure with first-in, first-out behavior:
enqueue inserts at the rear, dequeue removes and returns the front, and peek inspects the front without removing it. Removal and inspection require a nonempty FIFO queue, or an explicitly defined empty-case result. Enqueue in that order, dequeue , then enqueue : the remaining sequence is , with next. A LIFO stack would remove the most recently inserted item instead. A FIFO queue models arrival-order service and supplies the next vertex for breadth-first search; a stochastic service model belongs to queueing theory. [ref]https://raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/Queue.java. Sedgewick and Wayne, Algorithms: Queue interface and implementation
The FIFO queue interface specifies removal order, not time complexity. A linked list with both front and rear pointers supports
enqueue, dequeue and peek in worst-case time under constant-cost pointer operations and allocation, as in Sedgewick and Wayne's implementation. A plain array that deletes its first entry by shifting the remaining entries takes time per such removal. An array with advancing front and rear indices can avoid these shifts; storage and resizing policies still need analysis. The two-list functional queue gives a different implementation with constant amortized analysis cost along a single sequence of uses. These representation choices matter when deriving the linear time complexity of breadth-first search in Big O notation.// Destination: computer-science.bigb
Kruskal component merging 2026-10-18
A disjoint-set data structure stores the current partition of a set of vertices into connected components of a graph. The operation returns a representative of the block containing . Two vertices are in the same block exactly when their representatives agree. For each candidate edge , compare and . Equal representatives mean reject; different representatives mean accept and perform , merging the two blocks. The representatives are bookkeeping choices, not preferred vertices of the minimum spanning tree.
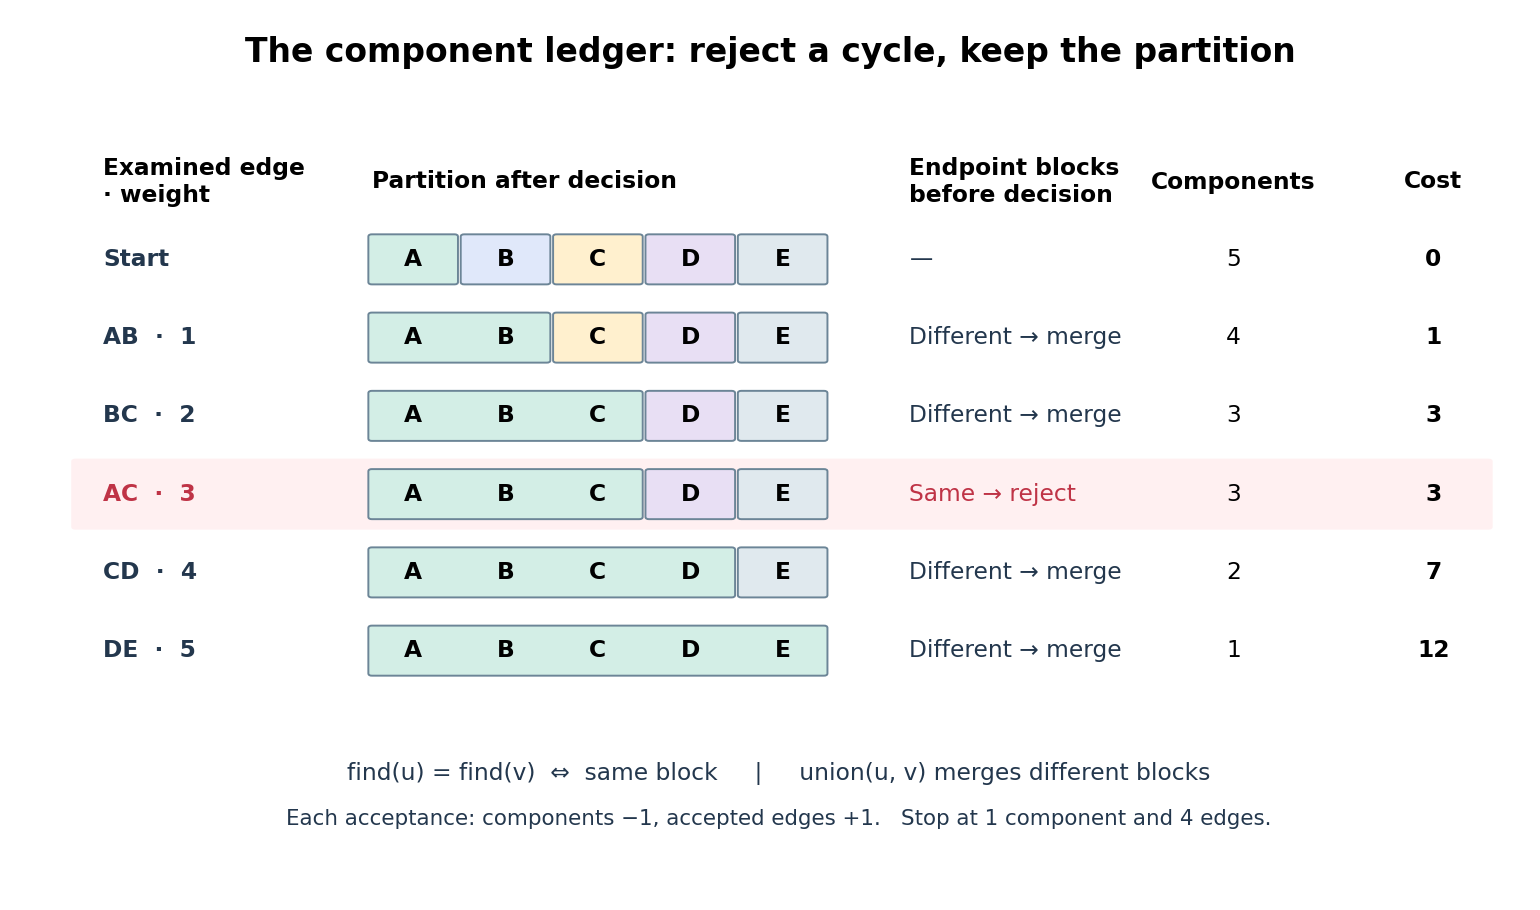
Connected components of a graph merge only when an edge is accepted
. The same example as a disjoint-set data structure ledger. Each coloured band is one block of the current partition of a set. The rejection of leaves both the partition of a set and the running cost unchanged. Bands show membership, not internal representative pointers. Details.
Every acceptance reduces the connected component of a graph count by one and increases the accepted edge count by one, preserving . Thus the ledger reaches exactly when . Only ten representative queries and four merges are needed for the five examined edges, counting two queries per examination and using the already found representatives for each merge. Neither breadth-first search nor reconstruction of a graph path is needed for these connectivity queries.
For and , comparison sorting algorithm takes time for , using Big O notation. One simple disjoint-set data structure implementation stores each block as a rooted tree and attaches the smaller block's root below the larger block's root. Whenever a vertex's depth increases, its block size at least doubles, so its depth is at most . Consequently each representative query or merge takes time. Initialization plus the scan costs ; including sorting algorithm gives , hence for a connected input with . These are operation bounds, not measured timings.[ref]
WeightedQuickUnionUF.java. Robert Sedgewick and Kevin Wayne, Algorithms, 4th edition, companion WeightedQuickUnionUF.java: class documentation and union method; union by size without path compression, linear initialization and logarithmic operations
For a graph on vertices with all edge weights in , every minimum-weight shortest path has the smallest possible number of edges. Indeed, positivity permits a simple optimum, and a simple -edge path weighs at most for , while any path with more edges weighs at least . A breadth-first search followed by weighted dynamic programming along increasing-hop edges therefore solves the single-source problem in time. Choosing an arbitrary breadth-first tree alone is insufficient: equal-hop routes may still have different weights.
Neighbour enumeration 2026-10-14
Neighbour enumeration reports the neighbours of a specified vertex. For a simple graph, scan its adjacency list and report each entry. With constant-time list access and work per entry, a list of length needs time in Big O notation, conventionally written for nonempty lists. Use vertex degree for an undirected graph and outdegree for a directed graph. Obtaining the list reference can take constant time; consuming it requires visiting every entry.[ref]
Digraph.java. Digraph.java, class documentation and adj: obtaining the collection versus iterating in time proportional to outdegree
In our undirected example, enumerating 's neighbours reads : three entries. Scanning row of the full adjacency matrix reads six entries, , to produce the same answer. In the directed variant, enumerating 's outgoing neighbours reads no neighbour entries, but still needs constant work to locate and recognize its empty list. For a multigraph, scanning lists enumerates incident edges with multiplicity; reporting only distinct neighbours additionally requires removing repetitions.
For a short time complexity argument, each reported entry requires at least one output operation, and one scan suffices. Across all vertices, the undirected entry count is by the handshaking lemma; the directed count is . A graph search that processes each vertex once and scans each of its entries once therefore does structural work, provided its visited-state access and FIFO queue or stack operations also have the required constant-time costs. With a full adjacency matrix, scanning every row instead inspects entries. This is how the representation enters the analysis of breadth-first search and depth-first search.
Write flow balance using the positive-inflow conventionRemove the lower bounds on network flow by writing , where only is nonzero. Then , and its required flow balance isIn the order , the lower-bound contribution is , soThe resulting flow network edge capacities areAdd a new source with an edge of flow network edge capacity , and a new sink with edges and of flow network edge capacities and . A feasible flow saturating these new edges is equivalent to a solution for : ordinary flow conservation in the enlarged flow network produces exactly the residual supplies and demands above. All source and sink edges must be saturated, requiring flow value .
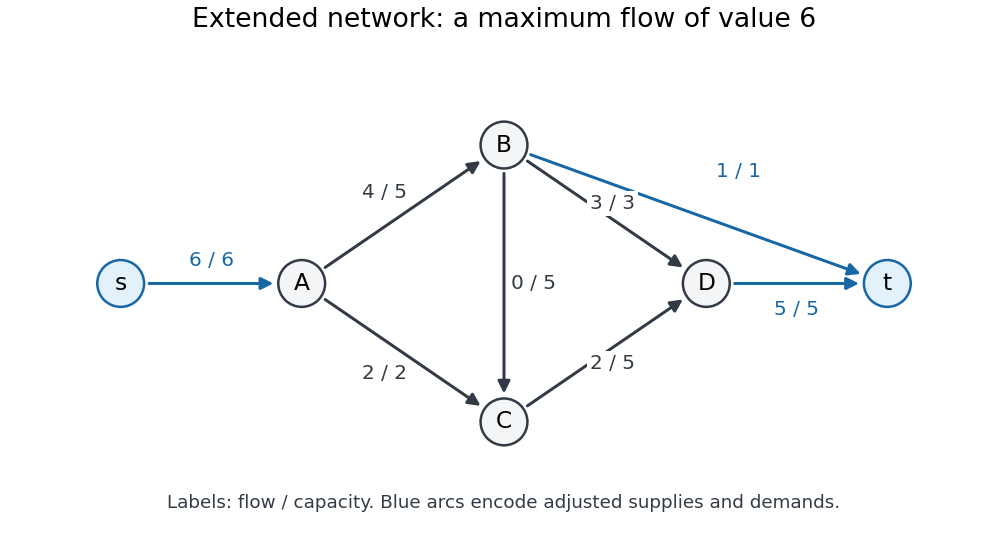
Extended flow network after removing the lower bound; labels show final flow divided by flow network edge capacity
. The auxiliary edges are blue. The displayed flow saturates the auxiliary source and sink edges, certifying that all adjusted demands are met. The original edge regains its four-unit lower bound only after this auxiliary problem is solved. Details.
Start the Edmonds–Karp algorithm at zero flow. Repeated breadth-first search in the residual network permits the following shortest augmenting paths; when paths tie, choose the one through first.
| Step | Augmenting path | Added flow | Total flow value |
|---|---|---|---|
The first augmenting path has three edges. Once is saturated, the next shortest possibilities have four edges, so steps and respect the breadth-first search rule. Each augmentation adds the usual backward edges to the residual network, though these particular augmentations need only forward edges. Now is saturated, so no further augmenting path exists. The cut of a flow network with source side has cut capacity , proving that the obtained flow is a maximum flow.
The original-edge values for are in the order . Restore the lower bound to obtainAll original capacity constraints hold, and meets its lower bound. The net inflows at are respectivelyThe original network therefore admits a feasible circulation with vertex demands.
The first assertion is false. Give the root a first child that is a goal state of cost ten and another child leading to many cheaper non-goal search nodes. Depth-first search can take the first child and stop immediately. A-star search with the admissible heuristic behaves as uniform-cost search and expands the cheaper non-goal search nodes before selecting that goal. Thus an admissible heuristic does not make A-star search expand fewer nodes than every possible depth-first search ordering. The latter need not return an optimal solution.
The second assertion is true under the usual finite-branching factor assumption. Breadth-first search orders by search depth, not path cost. Every finite depth contains finitely many search nodes, so a goal at finite depth is eventually reached even if some steps cost zero. Zero-cost steps can affect cost optimality, but do not obstruct this completeness argument. An infinite branching factor would invalidate the argument irrespective of step costs.
The third assertion is true as a worst-case black-box requirement, with a finite optimum assumed. If outgoing actions are known only by expanding a state, an unexamined reachable branch can conceal a sufficiently negative-cost action followed by a route to a goal. Its total cost can beat the current solution by an arbitrarily large amount. Without additional lower bounds or structural information, finding one cheap solution cannot justify stopping; exhaustive examination can be necessary. This does not assert that every already-described irrelevant state must be visited on every input. Moreover, a reachable negative-cost cycle in a graph that can still reach a goal can make costs unbounded below, in which case no finite-cost optimal solution exists at all.
Use the knight-variable representation and build a placement one knight at a time. The initial state is the empty placement. An action places the next knight on an empty square attacking no previously placed knight; the search transition model appends that square. The goal test is that knights have been placed. Each action adds exactly one, so any solution has depth .
Put . At depth , there are at most choices, hence branching factor at most . A coarse search tree size bound is . Keeping the shrinking choice count gives the sharper boundwhere is a falling factorial. This counts ordered placements before attack pruning.
For a full expansion down to depth , the number of depth- leaves is at most , or approximately when is small relative to . If denotes the number of legal unlabelled -knight placements, the exact number of legal depth- leaves is . There can also be earlier dead-end leaves: a legal placement may leave no further nonattacking square. Writing for the number of inclusion-maximal legal -knight placements, the fully explored pruned tree hasleaves. Its leaf count is still at most the unpruned , since each early leaf replaces a disjoint nonempty subtree of the unpruned tree. Breadth-first search that stops at its first goal can construct less of the last layer; if no solution exists, it exhausts the reachable partial placements.
Identifying different insertion orders changes the representation. With a state that is an unlabelled set of occupied squares and repeated-state elimination, the corresponding depth- state bound is , with legal goal states. The factorial and binomial bounds refer to these different representations, not competing counts of the same tree.
Backtracking assigns one variable at a time and abandons a partial assignment as soon as it cannot extend to a solution. With forward checking, placing a knight deletes its occupied and attacked squares from every remaining knight's constraint domain. An empty constraint domain rejects the branch immediately; stronger constraint propagation, such as arc consistency, can detect additional incompatibilities among future choices.
This combines early rejection with depth-first storage. It retains the current assignment and domain changes rather than the entire breadth-first layer of partial placements. A direct knight-variable implementation uses space for explicit domains, plus its assignment and restoration trail, instead of an exponentially large breadth-first search search frontier. Propagation has a computational cost and does not guarantee improvement on every input, but often prevents exploration of vast inconsistent subtrees.
The minimum remaining values heuristic selects an unassigned variable with the fewest currently legal values, exposing the likeliest failure first. The degree heuristic selects a variable constrained to the largest number of other unassigned variables, often breaking minimum remaining values heuristic ties. Degree is measured in the remaining constraint graph, not by counting assigned neighbors. In the symmetric knight-variable encoding the remaining degrees can all tie, so the heuristic need not discriminate there.[ref]
CS 188 constraint ordering and structure notes. §2.4, Minimum Remaining Values: choose an unassigned variable with the fewest valid remaining values
TODO: the classifications, chosen heuristic functions and least-cost outcomes for G1–G5 cannot be established from the corrupted original Figure 1. The missing edges, costs, priority labels and lower portions of the five search trees are required inputs. The surviving portions and the two heuristic function tables do not determine those answers. No reconstructed graph or invented expansion trace is assumed.
For a readable instance, depth-first search follows the deepest pending branch and breadth-first search expands by search depth; neither generally minimizes unequal edge costs. Uniform-cost search orders by path cost , whereas A-star search orders by . A displayed A-star search score would identify the estimate by subtracting the accumulated path cost. Under nonnegative costs and the usual terminating-search assumptions, uniform-cost search returns a least-cost goal state when testing goals on removal from the search frontier; A-star search additionally needs an admissible heuristic with appropriate reopening, or a consistent heuristic for the usual closed-set implementation. These rules explain how the missing information would be used, but cannot identify a particular damaged search tree.
Let the input words be , let be their common length, let be the finite alphabet, and let contain the dictionary words of length . Unequal input lengths immediately make the puzzle impossible because a mutation preserves length. A word ladder search problem can use the state space , with initial state ; including handles an input word not itself in the dictionary.
At word , an action is a position–letter pair with , and , permitted precisely when replacing by gives . The search transition model returns that , and the goal test is . If , the empty sequence is accepted; if and , no transition can reach .
Assign each permitted transition cost . A search node at search depth hasThus minimizing path cost is exactly minimizing the number of mutations. Uniform-cost search, with repeated states handled by graph search and the goal test on selection, finds a shortest word ladder if one exists. Because all costs are equal, breadth-first search gives the same optimal-length guarantee.