Original solutions to both sections, all eight questions and all thirty-two terminal parts of the Numerical Linear Algebra and Continuous Optimization paper sat on 5 June 2007. Source: released Mathematics papers,
Part C 2007 11.pdf. The relaxed-Jacobi printing error and omitted zero-point qualifications are addressed where they affect the arguments.The outer product has entries . Every column is a multiple of , and at least one column is nonzero because . Its column space is therefore exactly , giving .
A Householder matrix is , . With one has and , so . Thus it is an orthogonal matrix and is its own inverse.
To express an arbitrary orthogonal as a product of these reflections, argue by induction on its dimension. Its first column is a unit vector. If , take . Then and , so the corresponding reflection satisfies . If , no reflection is required. The resulting orthogonal matrix has first column ; orthogonality of its columns then makes its first row as well. It is consequently with orthogonal. Apply the induction hypothesis to and embed its reflections in the full space. In dimension one the only possibilities are , the empty product, and , itself a reflection. Reversing the performed transformations proves the Householder factorization of an orthogonal matrix, with at most the dimension many reflections.
A full real singular value decomposition iswhere has only diagonal entries, with . These are the singular values. The number of positive singular values is the matrix rank. The columns of are right singular vectors and those of are left singular vectors, giving orthonormal input and output coordinate systems.
For a rectangular diagonal matrix , define by transposing its shape and takingEntry by entry, and . For , orthogonality therefore givessince , and similarly . This candidate is the Moore-Penrose inverse. It also makes and symmetric, although those two extra conditions are not required by the question's stated definition. The two displayed conditions alone need not specify a unique generalized inverse.
Direct solution usually uses a pivoted LU decomposition : solve by forward substitution, then by back substitution. For a symmetric positive-definite matrix, the Cholesky decomposition iswith lower triangular and positive diagonal. It exploits symmetry, requiring about arithmetic operations rather than the leading for general elimination.
If has full column rank and its reduced QR decomposition is , , thenChoose the signs of so that has positive diagonal. Then is precisely the upper Cholesky factor of the normal-equation matrix , or is its lower factor. This identifies the factors; in computation, obtaining directly by QR decomposition avoids explicitly forming the normal equations, which square the condition number.
The matrix splitting produces . If the iterates converge to , passing to the limit yields , hence . Thus any finite limit solves the system; when is nonsingular it is the unique solution.
The iteration matrix is . For symmetric positive definite, its positive-definite square root giveswhich is symmetric when is symmetric. Let be the eigenvalues of . In its orthonormal eigenbasis the transformed error is multiplied by at each step. Therefore convergence to the unique solution for every starting vector is equivalent toSufficiency follows because each scalar mode tends to zero. Necessity follows by starting with a nonzero error in any mode whose multiplier has modulus at least one. Equivalently the condition says , by congruence of their quadratic forms.
Under the usual nonsingularity assumption, a symmetric that is not positive definite has a negative quadratic direction. Its congruent then has a negative eigenvalue, making an error multiplier . A starting error in that mode diverges, proving the final claim in that setting.
If singular matrices are permitted, the last claim needs qualification. A zero eigenvalue gives a persistent error mode, but the iterates may still converge to another solution of a compatible singular system. For example , , makes every iterate constant and already a solution, despite not being positive definite. Thus literal nonconvergence cannot be deduced from a zero eigenvalue alone.
A multigrid method alternates local error damping with correction on coarser grids. For clarity write times the five-point stencil and , incorporating Dirichlet boundary data into the right side. One two-grid cycle proceeds as follows.
- Apply a few smoothing sweeps, for example weighted Jacobi iteration with weight , to damp grid-scale oscillations in the error.
- Form the fine-grid linear-system residual and restrict it to the grid of spacing . An example is the full-weighting restriction stencil , centered at a coarse-grid point.
- Solve the coarse error equation , with homogeneous error boundary data. The coarse-grid operator may be the rediscretized Poisson operator at spacing , or the Galerkin coarse-grid operator with consistent transfer operators.
- Prolong the correction to the fine grid, for example by bilinear interpolation, and update .
- Apply a few further smoothing sweeps to damp oscillatory components introduced by interpolation.
The coarse solve is performed recursively, with a direct solve on the smallest grid, giving a V-cycle. Smoothing treats oscillations that are cheap for local relaxation to remove; coarse-grid correction treats errors that appear smooth on the fine grid. The scaling of the residual and coarse operator must agree if one instead uses the paper's unscaled stencil.
For homogeneous error boundary values, the tensor-product sine vectors form a basis. The sine addition formula gives , and similarly in the other coordinate. Hence the five-point matrix hasThere is a printing error in the displayed iteration. Taken literally, its error multiplier is , and its fixed-point equation is , rather than the stated Poisson equation. Thus the printed affine update cannot be used as a consistent relaxation for this system.
The intended weighted Jacobi iteration with isIts iteration matrix is , whose mode multiplier isIf at least one of the two cosines is negative, their sum lies strictly between and , so . Thus every such high-frequency mode contracts by at most per sweep, uniformly in grid spacing. This weighted Jacobi smoothing bound for the square Poisson problem justifies the corrected method as a smoother. The literal printed update also damps modes, but toward the wrong fixed-point equation.
The Krylov subspace is . Write with . For the exact solution, , soThis polynomial has degree at most and . It is the error-polynomial representation for a Krylov subspace method.
Every point in the affine search space is uniquely , since the columns of form a basis. Its linear-system residual is , so minimizing the residual is exactly the linear least-squares problem .
Use the standard starting choice and an orthonormal extended basis . If , then and orthonormality givesThe starting-vector choice is needed for this particular representation; an arbitrary orthonormal basis need not have those initial coordinates.
The Arnoldi iteration constructs the basis. At column , orthogonalize against , recording coefficients ; normalize the remaining vector with to get . This makes an upper Hessenberg matrix of size . The resulting GMRES algorithm starts from , grows this Arnoldi basis, solves the small least-squares problem, and sets . Its small residual norm provides the stopping test. Incremental Givens rotations efficiently update the small QR decomposition instead of solving it anew. Zero initial residual means the system is already solved; Arnoldi breakdown gives an invariant subspace and, for nonsingular , permits exact solution within it.
One restarted step chooses to minimize the new residual norm. Since ,and induction givesThese polynomials have degree at most one; a zero step gives the constant polynomial one.
In the specified example the first search space is spanned by . Writing , its squared residual norm is , uniquely minimized at . Thus restarted GMRES gives and stagnates forever, repeatedly facing the same minimization problem.
Without restarting, the first iterate is still zero, but . The second minimization finds the exact solution . This one-step restarted GMRES stagnation example shows how discarding the accumulated search space can prevent convergence even for a nonsingular two-dimensional system.
At the current point , a trust-region method approximately minimizes a local quadratic modelwhere is a symmetric Hessian approximation and is the trust-region radius. For a step with positive predicted decrease, compare the true and predicted reductions throughChoose fixed thresholds . If , the step is unsuccessful: reject it and reduce the radius. If , accept the successful step and normally retain the radius. If , the step is very successful: accept it and permit an increase in radius, especially when the step reaches its boundary. The ratio tests whether the local model is accurate enough to justify moving. An approximate subproblem solver should deliver at least the model decrease achieved at the Cauchy point.
The Cauchy point minimizes the model along the negative-gradient ray within the ball. For , write , . Thenwhose scalar minimum occurs at unless the ball cuts the ray short. ThereforeIf , its predicted decrease is . Otherwise it is . Thus every feasible step with satisfies the Cauchy decrease boundFor , take ; the bound reduces to zero.
The global optimality conditions for a quadratic trust-region subproblem with Hessian are: for some ,Here , so the shifted matrix is positive definite. If , choose and . If , the active boundary gives and . HenceThis is exactly the Cauchy point. Because the model is strictly convex, it is the unique global minimizer, including when .
The true quadratic has and the exact expansionSubtracting the model with Hessian yields . Since is symmetric positive definite and , its eigenvalues lie in , so . ThereforeIn fact the stated assumptions give a factor one-half better than the requested bound.
Write for the predicted decrease, assuming a nonstationary point and a step at least as good as the Cauchy point. When , part (ii) gives . Part (iv), using its weaker requested bound, then givesConsequently implies .
For the radius conclusion, use the standard update rules from part (i). Suppose no subsequence of the generated gradient norms tends to zero. Then some bounds those norms below eventually. If , eventually , so every subsequent step is very successful by the preceding estimate. The radius is then maintained or increased, contradicting convergence to zero. Hence a radius tending to zero forces a subsequence of gradient norms to tend to zero. The conclusion uses the trust-region update rules as well as the model estimates.
Use the optimization Lagrangian and let be the constraint Jacobian matrix. Under the standard regularity hypothesis , a local constrained minimizer satisfies, for some multiplier ,The second-order necessary condition isRegularity makes each such tangent vector the velocity of a feasible smooth curve. Twice differentiating the objective along that curve and using stationarity and the differentiated constraints gives the displayed nonnegative second derivative.
The regularity hypothesis is needed for these multiplier conditions to be necessary in this form. For example minimizing subject to has the unique feasible minimizer zero, but for every . The question does not explicitly state the qualification, so it must be supplied when using the usual KKT conditions.
The sequential quadratic programming step minimizes a quadratic local objective model while enforcing the first-order constraint expansion . When the iterate and multipliers are close to a regular solution and approximates the Lagrangian Hessian, the resulting correction approximates a Newton step for the nonlinear KKT conditions.
Full row rank of ensures that is solvable for every and that the multiplier of the quadratic subproblem is unique. A positive-definite makes the objective strictly convex and coercive on the affine feasible set, giving a unique global subproblem minimizer. In fact positivity on , rather than on every vector, is enough for uniqueness and boundedness on that set; full positive definiteness is a convenient stronger assumption.
Stationarity of the equality-constrained quadratic subproblem gives . Together with feasibility, this isMultiplying the bottom block row by gives a symmetric indefinite saddle-point matrix, with right side .
One solution strategy uses the Schur complement. From obtainThis is an positive-definite system when has full row rank; factor and solve with it rather than forming its inverse.
A second strategy uses a nullspace basis for . Choose one particular with , write , and solve the reduced systemThe reduced Hessian is positive definite. These range-space and nullspace reductions exploit different relative sizes of and .
Since is even, differentiating givesAt a stationary point define . Then , precisely the stationarity equation for the optimization Lagrangian. Bounded multipliers giveThus along any subsequence of stationary points with , a further subsequence of bounded multipliers converges to , and continuity yields and . These are the equality-constrained first-order conditions. Bounded multipliers alone do not establish convergence of the primal points; the precise conclusion concerns their finite cluster points. This is the power penalty multiplier limit.
Suppress the iteration subscript. From the quadratic subproblem, and . ThereforeWhen , the stated bound on makes . Consequentlyusing positive definiteness of . Thus every nonzero such SQP step is a descent direction for the penalty function. If , the quotient bound is unnecessary and the same conclusion follows for every . A zero step has zero directional derivative and is not a strict descent direction; it corresponds to an already feasible stationary point. This nonzero-step qualification is implicit in the requested conclusion.
For , the unit steepest descent direction is by the Cauchy-Schwarz inequality. The usual unnormalized direction is ; choosing its scale separately as a line-search step gives the same ray. It satisfies , so it is a descent direction. The first-order Taylor expansion then guarantees decrease for sufficiently small positive steps. The subsequent bounds use this unnormalized negative-gradient convention.
A Lipschitz gradient with constant gives the descent lemmaFor , this upper bound is at most whenever . Since is a descent direction, the right side is positive. Thus the Armijo condition holds throughoutAt it holds by equality. If the gradient Lipschitz constant can be taken as zero, the objective is affine and every positive step along a descent direction passes this sufficient-decrease test.
The backtracking line search starts with , tests the Armijo condition, and repeatedly replaces a failed step by , with fixed . It accepts the first step that passes. Backtracking makes an overambitious trial step small enough for a local linear model to predict the change reliably; part (ii) ensures finite termination. The Armijo condition guarantees a decrease of at least along a nonzero descent direction. Merely obtaining some decrease without this quantitative lower bound would not provide the convergence estimate in the following parts.
For , part (ii) simplifies to . If the initial step is accepted, . Otherwise the immediately preceding trial failed and hence exceeded . ThereforeThe fixed global Lipschitz constant and search parameters make this lower bound uniform across iterations. At , the zero update passes the first trial and the sequence can be kept stationary.
The Armijo condition with gives . Summing these inequalities telescopes toIf , these partial sums of nonnegative terms are bounded above by . The resulting series converges, so its terms tend to zero: .
Use the uniform lower step bound from part (iv):Thus . This is convergence to stationarity in the usual global convergence theorem for the steepest descent method. It does not itself prove that the iterates converge, or that any stationary limit is a global minimizer of a nonconvex objective.
Two reasons to prefer more advanced methods for smooth, high-accuracy optimization are:
- Slow progress on ill-conditioned problems. On an elongated quadratic level set, successive negative gradients can zigzag across the narrow valley. Convergence can be only linear with a factor close to one, and line search cannot remove the underlying poor scaling.
- Failure to retain curvature information. Each new step again uses only the current gradient. Newton's method and quasi-Newton methods exploit curvature to obtain substantially faster local convergence under suitable hypotheses, often compensating for their more expensive steps.
The question's blanket wording is too strong: the steepest descent method and related gradient algorithms are used in practice, especially when problem size, cheap gradients or simplicity make curvature-based alternatives costly. The objections describe limitations, not universal nonuse.
With , the Karush-Kuhn-Tucker conditions areUnder a suitable constraint qualification, such as the linear independence constraint qualification on active constraint gradients, they are necessary for a local minimum. Smoothness alone is insufficient. The sign convention here corresponds to constraints written as and a minus sign in the optimization Lagrangian.
Write the constraint as and its multiplier as . The KKT conditions becomeIf is positive definite, is positive definite for every , so is the only critical point.
For indefinite , the origin remains a critical point, contrary to an unqualified reading of the question. Every nonzero critical point is an eigenvector with , so its eigenvalue is nonpositive. A negative-eigenvalue vector must lie on the unit sphere, with multiplier equal to the negative of that eigenvalue. A nonzero vector in may have any norm at most one and has multiplier zero. Positive-eigenvalue directions do not satisfy the multiplier sign condition. These first-order critical points include saddles; the global minimum selects a unit vector in the lowest-eigenvalue eigenspace.
The logarithmic barrier isIts gradient is . Thus every nonzero stationary point satisfiesA fixed negative-eigenvalue branch exists for . The zero point is stationary for every as well, and it is not an eigenvector; at zero the displayed scalar need not be an eigenvalue of . Thus the claimed eigenvalue conclusion requires the nonzero-point qualification. This distinction is essential for the following Hessian analysis.
Put . Differentiating the barrier gradient givesAt a nonzero stationary point on the branch , . Choose an orthonormal eigenbasis of the symmetric matrix whose first vector is . On each of the remaining eigenvectors the rank-one term vanishes, so the corresponding Hessian eigenvalues areAlong , the first two terms cancel and the remaining eigenvalue isIf repeats, a transverse eigenvalue can be zero. If a lower eigenvalue than exists, a transverse eigenvalue is negative, identifying this stationary branch as a saddle rather than a minimum.
Along a fixed nonzero branch, and the radial Hessian eigenvalue grows like . The nonzero transverse eigenvalues stay fixed. If is simple, the ratio of the largest to smallest absolute eigenvalue therefore tends to infinity. If it repeats, the Hessian is already singular because of the zero transverse directions; there is no finite spectral condition number to begin with. These conclusions concern the nonzero branches: at the stationary origin , and the same blowup is not implied.
Ill-conditioning does not invalidate barrier minimizers as approximations to the constrained solution. Let . At radius , the smallest possible quadratic value is , so global barrier minimization reduces to minimizing for . For its unique minimizing radius satisfiesThus every limiting unit vector in that eigenspace solves the original problem, with objective . For the barrier minimizer is the origin instead. The increasing condition number concerns the numerical difficulty of small-parameter subproblems, which can call for scaling or a primal-dual interior-point method; it does not prevent the mathematical convergence just established. This is the quadratic-ball barrier eigenvalue branch.
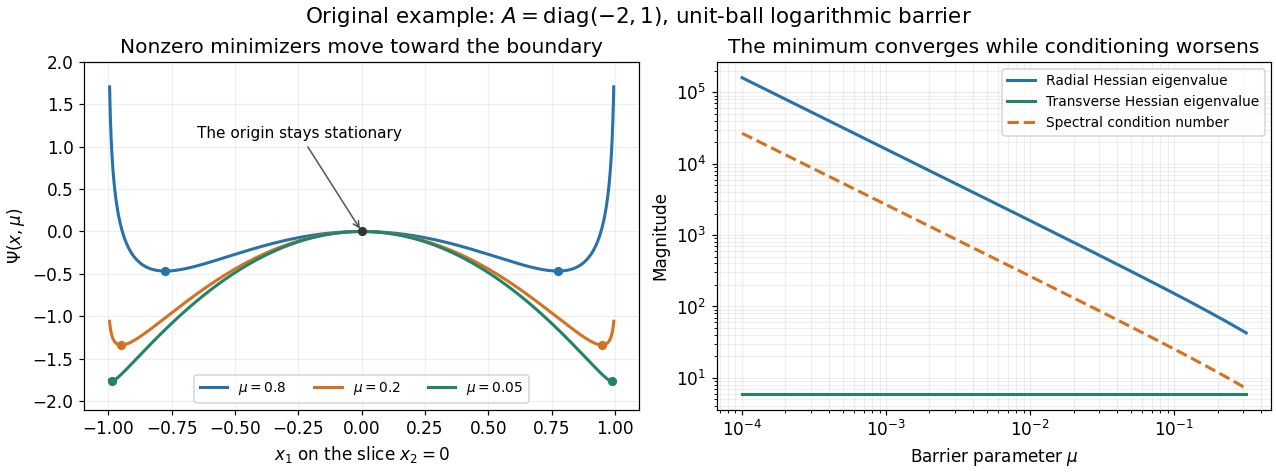
The nonzero barrier minimizers approach the unit sphere while their Hessian condition number grows; the origin remains stationary
. Details. 
Articles by others on the same topic
There are currently no matching articles.