For a fixed input, the random bits can change the path taken by a randomized algorithm, its output, or its running time. Specify the distribution of those choices and which guarantee is required: one-sided error permits mistakes of only one kind, whereas ZPP requires a correct answer and bounds the expected running time. Polynomial identity testing makes this distinction concrete: choosing different field elements changes whether a nonidentity is detected.
A uniform distribution on a finite set must be implemented faithfully. To choose uniformly from using fair independent bits, read three bits as a number from zero to seven, discard five through seven, and repeat until a permitted value appears. Each retained value has the same chance. Taking the three-bit number modulo five instead would give zero, one and two twice as many preimages as three and four, invalidating a calculation that assumes equal chances.
A balanced binary sequence of length has entries of each kind. Uniformly sample an -element subset of the positions and place the first kind there. If is a power of two, repeatedly draw uniform positions using fair random bits, reject previously selected positions, and stop after distinct positions. Each new position is uniform among those remaining, making every -element subset equally likely. The expected number of draws is , giving expected random bits.
Derandomization converts a randomized construction or algorithm into a deterministic one while preserving its desired guarantee. The method of conditional probabilities does this by maintaining a computable conditional expectation until all choices are fixed.
The method of conditional probabilities turns an expected value guarantee into a deterministic construction. For a maximization objective function, fix one choice at a time, always keeping the conditional expectation of the final value at least as large as before. Once every choice is fixed, that conditional expectation is the actual value. The useful ingredient is a way to evaluate the conditional expectations efficiently.
No actual random choices are needed during this construction. The probability distribution describes hypothetical completions used in the analysis; the algorithm compares their conditional expectations and commits deterministically. For maximum cut, this converts the random cut lower bound into a cut of a graph containing at least half the edges. A maximum cut can still be larger, as the conditional expectations cut example shows.
In a partially fixed two-colour edge coloring of a complete graph, complete all unassigned edges independently and fairly. For a fixed clique with unassigned edges, its conditional probability of becoming monochromatic is zero if both colours already occur; if a colour is fixed and no conflicting colour occurs; and if none is fixed. Sum these conditional probabilities over the cliques to obtain a computable conditional expectation. Fix each next edge to a colour that does not increase this conditional expectation, yielding a deterministic minimization construction.
Let be a real-valued objective function of finitely many choices, with finite expected value. Suppose a prefix has positive probability. Write . If the next choice is a fair bit, the law of total expectation givesAt least one child is at least this average. Choose a child with the larger value, using a fixed rule for ties. The resulting loop invariant is . At a complete assignment , there is only one completion left, so and therefore .
For a biased choice or more than two possibilities, use the corresponding weighted average:Some positive-probability child is at least the weighted average. For minimization, choose a child at most the current conditional expectation and reverse the invariant. The averaging identity is the same in both directions.[ref]
Discrete Probability by Jeff Erickson. Jeff Erickson, Discrete Probability, §1.2.2, printed pp. 6–7: conditional expectation decomposition and linearity; authorship stated on the author's Algorithms notes page
The word "probabilities" in the method's name also covers an indicator random variable for an undesirable outcome: keeping its conditional expectation, which is its conditional probability, strictly below one eventually forces that indicator to be zero. Optimizing an ordinary numerical objective function is the method of conditional expectations formulation used below.
Let be a finite undirected simple graph, with vertices and edges. A cut of a graph assigns each vertex a label zero or one; an edge crosses precisely when its endpoints have different labels. Its size is the number of crossing edges. A maximum cut maximizes that size.
For the analysis, assign independent fair bits to the vertices. For each edge , the indicator random variable has expected value : exactly two of the four equally likely endpoint assignments cross. Thus linearity of expectation gives the random cut lower bound:Linearity of expectation does not require the indicator random variables to be independent. What matters here is the stipulated distribution of the endpoint bits.
For any partial assignment , let count edges whose two endpoints are already fixed on opposite sides, and let count edges with at least one unassigned endpoint. Under the remaining independent fair bits,An edge with fixed equal labels contributes zero; fixed unequal labels contribute one. If one endpoint is unassigned, its fair bit disagrees with the fixed label with probability . If both endpoints are unassigned, their independent fair bits disagree with probability as well. Count each unresolved edge once, even when both endpoints are unassigned.
Process vertices in a fixed order. Evaluate the conditional expectation cut formula after setting the next label to zero and after setting it to one; retain the larger value, choosing zero on ties. The conditional expectation choice invariant ensures the final cut of a graph has size at least . This is a deterministic approximation algorithm for maximum cut.[ref]
Lecture notes on randomized approximation algorithms. CS 4820: Algorithms, Spring 2011; Cornell CS 4820, Lecture notes on randomized approximation algorithms, 2 May 2011, §1.1.2, printed pp. 2–3: conditional expectations, Algorithms 1–2 and the half-total-edge-weight guarantee; no individual byline stated
Consider the following original five-vertex simple graph, where denotes the undirected edge :Its seven edges give initial expected value . Use vertex order and choose zero whenever the two child conditional expectations tie.
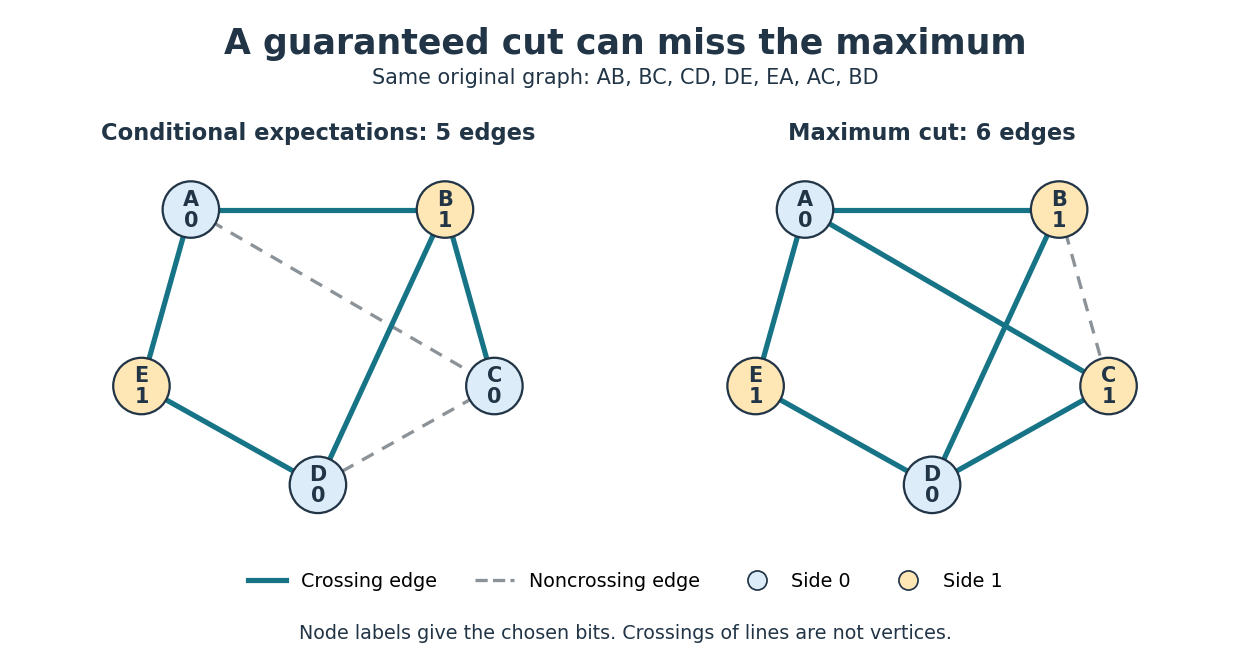

The complete decision ledger is below. A prefix lists fixed labels in vertex order; all later labels remain hypothetically independent fair bits. Each candidate entry is the conditional expectation of the final cut of a graph, including the contribution of unresolved edges.
| Prefix before choice | Next vertex | Set to 0 | Set to 1 | Chosen label | Retained conditional expectation |
|---|---|---|---|---|---|
| Empty | |||||
For example, after , edge is fixed crossing and the other six edges are unresolved, giving . Setting fixes crossing and noncrossing, leaving four unresolved edges: . Setting instead fixes crossing and noncrossing, giving the same conditional expectation.
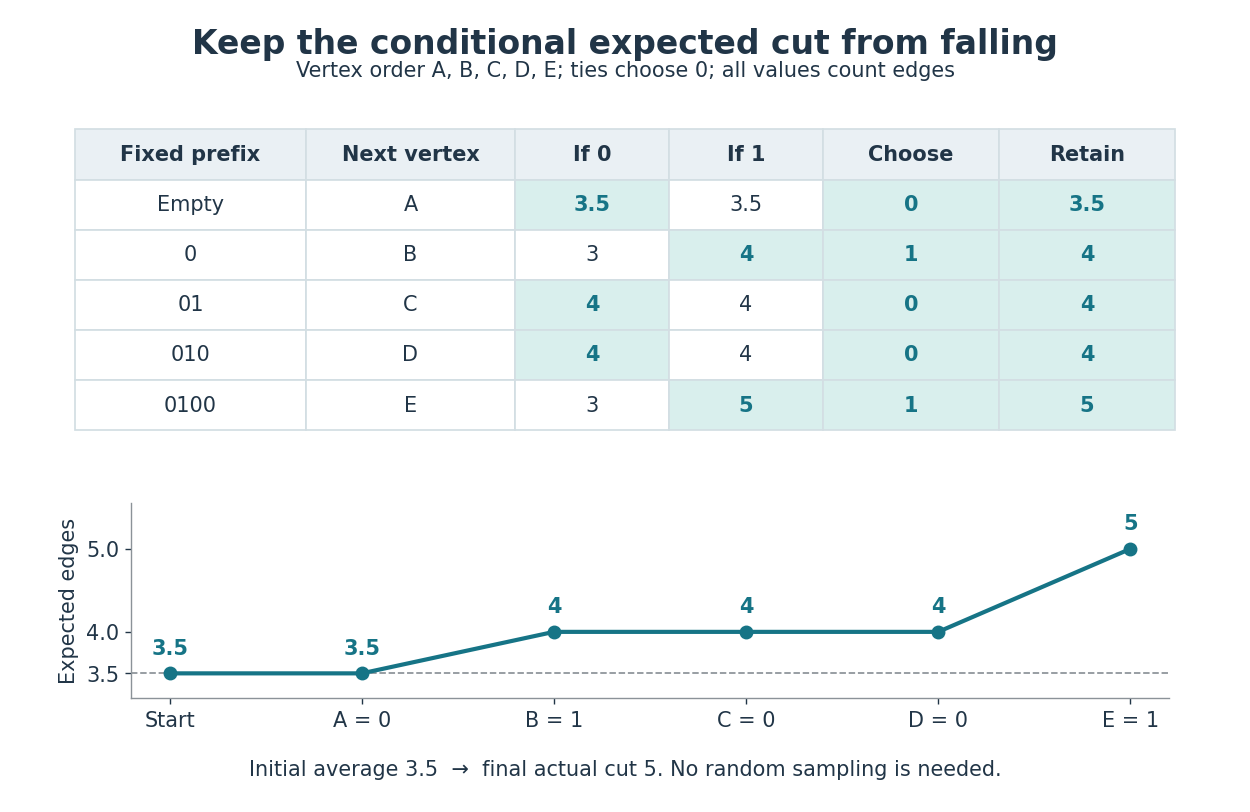
Conditional expected cut values along every chosen branch
. At each step, both candidate values are computed by the conditional expectation cut formula. The highlighted cell is chosen; ties choose zero. Below, the retained conditional expectation follows , starting before any label is fixed. The last value is the actual size of the resulting cut of a graph, rather than an average over remaining choices. Details.
The final labels are , so the two sides are and . The five crossing edges are ; do not cross. This exceeds , and hence also the rounded-up guarantee of four edges.
It is not a maximum cut. Labels cross all edges except , giving six. Seven are impossible because the triangle in a graph cannot have all three edges crossing a two-sided cut of a graph. An independent enumeration of all complete label assignments gives the following distribution, counting an assignment and its label-swapped counterpart separately:
| Size of cut of a graph | Number of label assignments |
|---|---|
The weighted sum is , so the average is , agreeing with linearity of expectation. Choosing in the earlier tie discards the remaining size-six completion while preserving the average of four. The method protects an expected value guarantee; it need not preserve the best possible completion.
Directly scanning all edges to evaluate each child of each of choices takes elementary operations, in Big O notation. There is a faster implementation. When assigning vertex , let and count its already assigned graph neighbours labelled zero and one. Contributions from edges not incident to are unchanged, and contributions from edges to unassigned graph neighbours stay for either choice. ThereforeChoose zero if , otherwise one: put on the side with fewer already assigned graph neighbours. With adjacency lists, scanning each vertex's list once costs operations overall and uses storage including the graph. These bounds count operations on labels and counters that fit in machine words of bits. Multiplying the conditional expectation cut formula by two also permits exact integer comparisons without rounding.
If is the size of a maximum cut, then . The constructed cut of a graph thus has size at least , an approximation ratio of in the maximization convention. The five-versus-six example illustrates the gap between this guarantee and exact optimization.
For a general randomized algorithm, the averaging proof alone does not establish efficient derandomization. One needs a polynomial number of commitments, an efficient way to find a suitable child at each step, and manageable representations and evaluation costs for the relevant conditional expectations. Those evaluations can themselves be hard. Enumerating all completions verifies this small example, but would take exponentially many assignments as grows. The polynomial-time algorithm here comes from the local conditional expectation cut formula, not from that enumeration.
A probabilistic Turing machine is a Turing machine whose transitions may depend on independent random bits.
A randomized decision algorithm has one-sided error when one answer is always correct and only the other answer can be mistaken.
The guarantee concerns each fixed input, with probability taken over the choices of the randomized algorithm. Always state which answer is protected. In polynomial identity testing, call an input positive when its polynomial is identically zero, and let acceptance mean claiming an identity. Then the possibilities are:
| Actual polynomial | Accept: claim identity | Reject: claim nonidentity |
|---|---|---|
| Identically zero | Always correct; every trial accepts. | Impossible with exact polynomial evaluation. |
| Nonzero | Possible mistake if the chosen point is a zero. | Always correct; the point is a witness. |
Thus a zero polynomial evaluation can leave uncertainty, but a nonzero polynomial evaluation settles the question. An error bound for a fixed nonzero polynomial is not the conditional probability that a particular accepted input is an identity; that latter question would need a distribution on the inputs as well.
In computational complexity theory, a polynomial-time algorithm with this orientation and false acceptance probability at most establishes membership in co-RP. Reversing the question to ask whether the polynomial is nonzero gives the RP orientation: negative instances are always rejected. The random evaluation test for a polynomial identity explains the required field, total degree, sampling and evaluation assumptions.
contains decision problems with a polynomial-time randomized algorithm that rejects every negative instance and accepts every positive instance with probability at least one half.
consists of complements of languages in RP. Its algorithms always accept positive instances and reject negative instances with probability at least one half.
. Equivalently, it consists of problems having an always-correct randomized algorithm with polynomial expected running time.
Independent repetitions reduce a randomized algorithm's error probability while preserving polynomial running time.
The combining rule depends on the error orientation. For one-sided error with false acceptance probability at most , reject as soon as any trial rejects and accept only if every trial accepts. For independent trials on the same fixed negative input, false acceptance has probability at most . The protected positive inputs still always accept. If false rejection is the possible mistake instead, accept as soon as any trial accepts. This uses the decisive answer rather than a majority vote.
For constant , grows only logarithmically in to achieve error at most . A polynomial number of trials preserves a polynomial-time algorithm's running-time bound. Independence matters: repeating one answer, or evaluating at the same random point each time, supplies no new evidence. The independent repetition of a polynomial identity test gives an exact -outcome example.
Polynomial identity testing asks whether a polynomial represented implicitly, such as by an arithmetic circuit or a remainder computation, is the zero polynomial.
Here zero means that every coefficient vanishes after collecting equal monomials in the polynomial ring. Testing equality of two polynomials amounts to testing for zero. An arithmetic circuit can permit cheap polynomial evaluation even when expanding all monomials is expensive. The random evaluation test for a polynomial identity exploits this: one nonzero value disproves the polynomial identity, while a known total degree limits how often a nonzero polynomial can evade detection.[ref]
Lecture 9: Polynomial Identity Testing by the Schwartz-Zippel Lemma. CPSC 536N: Randomized Algorithms; Lecture 9: Polynomial Identity Testing by the Schwartz-Zippel Lemma, §1: formal zero means all coefficients vanish; representations and evaluation access
For example, for an integer , has distinct monomials, one for each subset of the variables. Its factored expression needs only additions and multiplications for one polynomial evaluation. Evaluating the compact expression avoids creating its expanded list of coefficients. The saving is especially attractive in many variables; it does not make a zero result into a proof of identity.
Work in the finite field , using modular arithmetic modulo five. Consider the two original polynomial examplesThe distributive property gives , so all coefficients of cancel: is identically zero. In contrast, in this finite field, with nonzero leading coefficient. Its roots of a polynomial are exactly one and two: a product in a field is zero only if a factor is zero.
The complete polynomial evaluations, displayed as representatives modulo five, areIn particular, is a nonzero witness, which disproves identity without examining other points. At one or two, a zero value fails to reveal that is nonzero. A random variable with a uniform distribution on a finite set hits those two polynomial roots with probability .
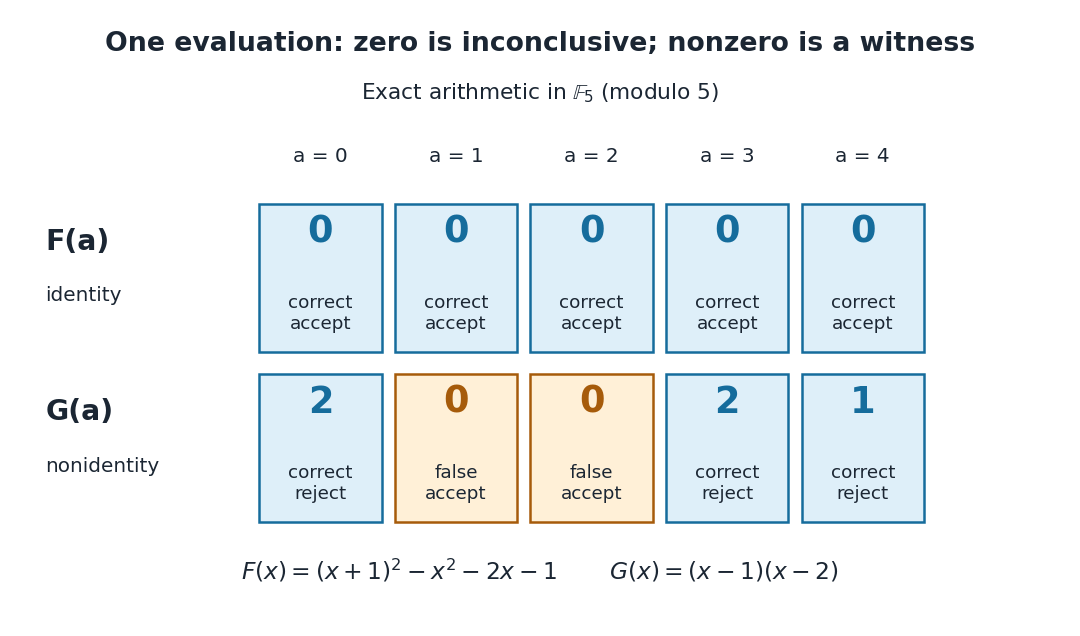

A crucial limit appears with . Its coefficients make it a nonzero polynomial of polynomial degree five in , yet direct polynomial evaluation gives zero at all five field elements: the values before reduction are , all divisible by five. Thus induces the same polynomial function as the zero polynomial. Any number of trials restricted to will falsely accept this identity. This is compatible with the Schwartz-Zippel lemma: the ratio of polynomial degree to sampling-set size is , which gives no useful guarantee.
When a polynomial's representation permits polynomial evaluation over a larger field extension, a larger sampling set can restore the useful degree ratio. Access only to the induced polynomial function on the original finite field cannot distinguish from zero.[ref]
Lecture 9: Polynomial Identity Testing by the Schwartz-Zippel Lemma. CPSC 536N: Randomized Algorithms; Lecture 9: Polynomial Identity Testing by the Schwartz-Zippel Lemma, §1.4: formal nonzero polynomials can vanish everywhere on a finite field; extension-field evaluations need a suitable representation
Let be a nonzero multivariate polynomial over a field , with total degree at most . Choose a nonempty finite set . For independent random variables , each with a uniform distribution on a finite set on , the Schwartz-Zippel lemma givesNonzeroness is essential; the zero polynomial always evaluates to zero. The total degree sums exponents within each monomial, rather than taking their maximum: has total degree five. The field need not be finite, but must be finite. The estimate reduces error only when .[ref]
CMPT 710 - Complexity Theory: Lecture 18. CMPT 710 and CMPT 407 - Computational Complexity - Fall 2007; CMPT 710 - Complexity Theory: Lecture 18, §3.1, pp. 3–4: Lemma 4 and its inductive proof
The proof begins with the root bound for a polynomial. For several variables, write , with . The total degree of is at most . By induction, vanishes with probability at most . Otherwise the remaining univariate polynomial has at most polynomial roots. Adding the two contributions gives .[ref]
CMPT 710 - Complexity Theory: Lecture 18. CMPT 710 and CMPT 407 - Computational Complexity - Fall 2007; CMPT 710 - Complexity Theory: Lecture 18, §3.1, pp. 3–4: split by the leading coefficient in the last variable
The algorithm samples a point, performs exact polynomial evaluation, rejects the identity if the value is nonzero, and otherwise accepts. The lemma bounds false acceptance for every fixed nonzero input. For the polynomial identity testing over a finite field example, has and , so its exact error attains the bound. Numerical near-zero values from floating-point arithmetic do not satisfy this exact algebraic contract. A polynomial-time algorithm claim additionally needs efficient sampling and evaluation, including the bit cost of representing and operating on field elements. Counting field operations alone does not establish that cost.
Repeat the random evaluation test for a polynomial identity with fresh independent random variables, keeping the same fixed polynomial. Reject as soon as any polynomial evaluation is nonzero; accept only if all values vanish. An identity is always accepted, preserving one-sided error. If a nonzero polynomial has single-trial false acceptance probability , independence gives . The Schwartz-Zippel lemma bounds this by when .
For over the finite field , two uniform independent choices have equally likely ordered outcomes, each with probability . Both polynomial evaluations are zero only at . Hence false acceptance falls from in one trial to in two trials, and correct rejection rises from to .
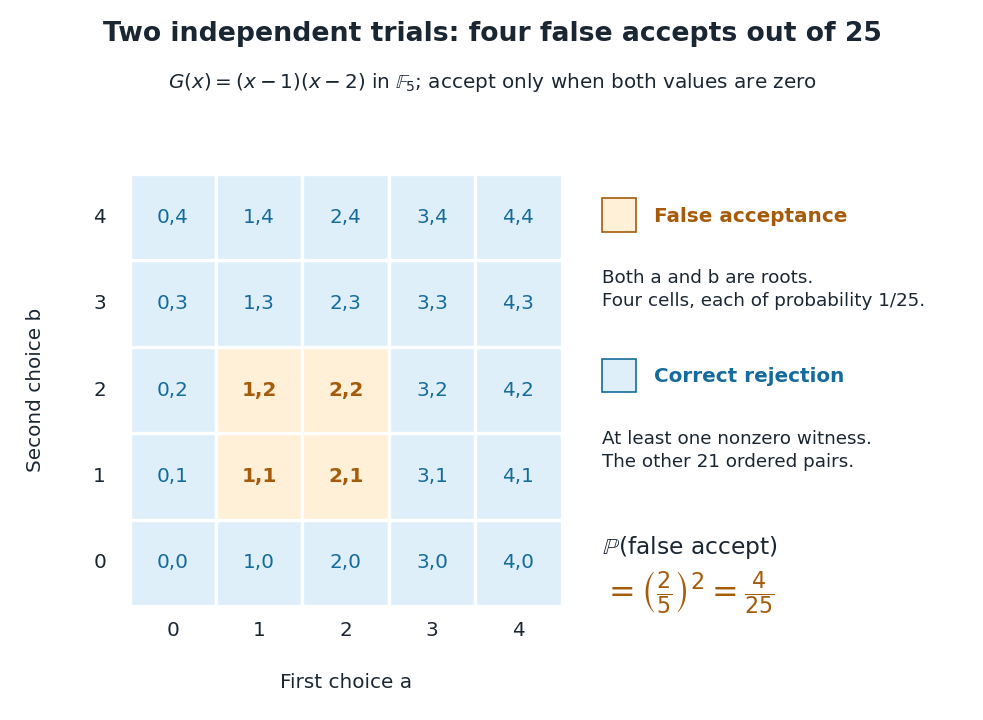
Four of the twenty-five independent pairs falsely accept the nonidentity
. The orange cells have both coordinates among the polynomial roots one and two of in the finite field . Every blue cell supplies at least one nonzero witness. The full grid enumerates exact outcomes under independence and a uniform distribution on a finite set; it is not a simulation. Details.
If the second choice reuses the first, the pair is and only five diagonal outcomes are possible. Two still falsely accept, so the error remains . Choosing fresh independent points is precisely what makes the full -cell grid and the product of probabilities valid. For a target error , this example needsThe ceiling function makes the trial count an integer. Four trials give , while six give ; five still give , so six is the first count below one percent. This is an exact error guarantee for each run on , rather than an observed success rate.
Articles by others on the same topic
There are currently no matching articles.