Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 43 4 Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
The experimental unit for comparing the treatments is the pot: its two plants form a pair. Let be cross-fertilised minus self-fertilised height in pot , for . The paired Wilcoxon signed-rank test assumes independent differences with a continuous distribution symmetric about a location . Its null is , with the one-sided formulation , against . Under this location model it asks whether cross-fertilisation produces a positive shift within a pot. The location is a median, and also a mean if it exists; a hypothesis merely about a median without symmetry does not justify the signed-rank null distribution.
Test 1 uses this paired test and its exact distribution. Form the fifteen differences, omit any zero differences, rank their absolute values, and sum the statistical ranks belonging to positive differences. That positive-rank sum is the reported . Tied absolute differences receive average statistical ranks. Under the symmetric zero-location null, conditional on their magnitudes, the signs are independent fair signs. The exact upper-tail probability is obtained from all sign allocations to the observed statistical ranks: with fifteen nonzero differences there are equiprobable allocations. For untied absolute differences the rank weights are ; ties would require the corresponding conditional rank weights. The reported probability of a positive-rank sum at least as large as observed is . No normal approximation is used.
Test 2 makes exactly the same paired comparison and has the same null and alternative hypotheses.
exact=F replaces the exact distribution by a normal approximation with a continuity correction. Under an untied null the positive-rank sum hasMore generally, conditional on the nonzero absolute statistical ranks , its variance is . The upper-tail correction places the boundary half a lattice unit below the observed statistic. Standardizing gives the reported , and its approximate -value is . Thus the slight difference from Test 1 reflects approximation, not a different scientific question.Test 3 omits
paired=T, so it is the unpaired Wilcoxon rank sum test. Its usual distribution-free null is that two independent samples have the same continuous distribution. In a common-shape location model this is a zero location difference, against a positive cross-minus-self shift. More generally “greater” directs the test towards the cross distribution being shifted upwards; it does not turn the test into a general comparison of means or medians for arbitrary unequal shapes.To form its statistic, pool the thirty heights, rank them together with averaged statistical ranks for ties, and add the cross-group statistical ranks to get . Equivalently use . Under independent untied samples,If the pooled ties have sizes and , the variance becomesSubtract the null mean and the upper-tail continuity correction, then divide by this null standard deviation. This procedure gives the reported rank-sum . Its approximate one-sided probability is . This describes how the statistic and probability are obtained without reconstructing the unprinted heights.
For the statistician, use the paired analysis, preferably the exact Test 1 for these fifteen pairs. The independent units are the pots, while the two heights within a pot share growing conditions and cannot be treated as independent samples. Test 2 is a reasonable approximation to the same paired test and agrees closely. Test 3 discards the matching and uses a null variance that assumes independence between the samples, so its smaller -value is not a reason to prefer it. The appropriate paired result gives evidence at , but not at , that cross-fertilised plants have a positive height shift relative to their paired self-fertilised plants, subject to the symmetry assumption for differences.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 43 3 i by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14 Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 43 2 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For an exponential dispersion family, differentiating the normalization integral with respect to gives an expected score of zero. The score is , hence . Differentiating again, the expected squared score is ; it is also . ThusThe canonical link function sets the linear predictor equal to the natural parameter: . The variance function is , so ; the dispersion parameter is separated from the mean-dependent factor.
The saturated statistical model has a separate mean for each response and fits , with boundary parameters interpreted by limits. At the same fixed dispersion, its log likelihood and the fitted model's log-likelihood define the scaled devianceThe unscaled deviance isKeeping dispersion fixed in this definition is essential; it is not a comparison with a separately estimated zero variance in a Gaussian saturated fit.
For the normal distribution, expanding its density exponent givesConsequentlyHere and the canonical link is the identity, so . The saturated natural parameter is . Substitution into the deviance formula yields
For the cholesterol fits, all formulae include an intercept. Model 1 has age and BMI with three coefficients; models 2 and 3 have one of these covariates with two coefficients; model 4 has only the intercept. Their residual statistical degrees of freedom are respectively . Their reported deviances are residual sums of squares, because these are Gaussian linear models.
The relevant hypothesis is in the full model, against , with age already present. Thus compare model 2 with model 1 using the partial F-test. Its extra sum of squares is , and the common variance is estimated from model 1 by . ThereforeSince , reject at ; the two-sided coefficient-test equivalent has . BMI is associated with cholesterol after adjustment for age, under the linear Gaussian model. The RSS values alone do not identify the sign of its coefficient or the size of the association.
For comparison, the marginal BMI test would compare model 4 with model 3, giving on statistical degrees of freedom, with . This does not answer the adjusted question and makes the BMI evidence appear stronger than the conditional test. Age also contributes after BMI: comparing model 3 with model 1 gives on statistical degrees of freedom, with . Thus retaining both predictors is supported at the stated level.
A raw deviance difference must not simply be compared with the supplied cutoff: Gaussian dispersion is unknown and the differences here are unscaled. If were known, the scaled difference would have a law. Estimating it from the full fit gives the exact finite-sample comparison above, with the appropriate denominator statistical degrees of freedom.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 43 1 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14This is an analysis of covariance: achievement is the response, aptitude is a quantitative covariate, and teaching method is a categorical explanatory variable. The usual normal linear model assumes independent errors with common variance .
read.table reads the data with a header row; attach makes its columns directly accessible, and the two printed vectors confirm their ordering. rep(1:3, each=7) supplies the three group labels, and factor makes them categorical. The contrast option selects treatment coding for unordered factors, with method A as the first-level reference. The polynomial option would apply to ordered factors and has no role here.The formula using
aptitude * Group includes both main effects and their interaction. Writing for the method indicators, its fitted mean has the formThus A, B and C have separate intercepts and slopes. There are six coefficients and residual statistical degrees of freedom. The analysis of variance table uses sequential sums of squares: adding aptitude to an intercept-only model removes from the residual sum of squares; subsequently adding the two group indicators removes ; adding the two slope interactions removes only . The remaining sum of squares is , giving mean square .Each displayed F-test divides the added term's sum of squares by its statistical degrees of freedom and then by this full-model residual mean square. In particular the interaction test isThere is no evidence that the slopes differ, so the common-slope model is preferable among the fitted models. The small group -value concerns differences after including aptitude, whereas the first aptitude row is sequential and does not adjust for Group. It should not be interpreted as the covariate test after treatment adjustment.
The additive formula gives the parallel-lines modelIt has four coefficients and residual statistical degrees of freedom. Removing the interaction raises the residual sum of squares to , but lowers the residual mean square to . The sequential aptitude and group sums of squares are unchanged. The adjusted group test is now on statistical degrees of freedom, with : after allowing for initial aptitude, the methods are not all equally effective.
summary(..., cor=F) displays the fitted coefficients, their standard errors, the individual statistics, and two-sided -values; it omits the coefficient-correlation matrix. The intercept is the fitted A mean at aptitude zero, which is outside the observed range and is mainly a parametrization device. The common slope predicts about extra achievement units per aptitude unit, holding method fixed. Its adjusted test is on statistical degrees of freedom, with about . The method coefficients are adjusted differences from A, not the B and C intercepts themselves. The three fitted lines areThe B-minus-A estimate is with standard error and ; the C-minus-A estimate is with standard error and . Both comparisons are strongly significant.The B-minus-C comparison needs its own treatment contrast; its significance cannot be read off either comparison with A. Reconstructing the coefficient covariance from the design givesThus there is no detectable difference between B and C. This is consistent with pooling their effects in a further reduced model, but does not establish exact equality.
The residual standard error is . The five-number residual summary shows deviations on both sides of zero, with the largest magnitude about ; it does not by itself verify constant variance or normality. The coefficient of determination means about of the achievement variation about its overall mean is explained. The overall compares all three nonintercept coefficients with zero, on statistical degrees of freedom; its -value is . Printed coefficient -values rounded to
0.0000 are small, not literally zero.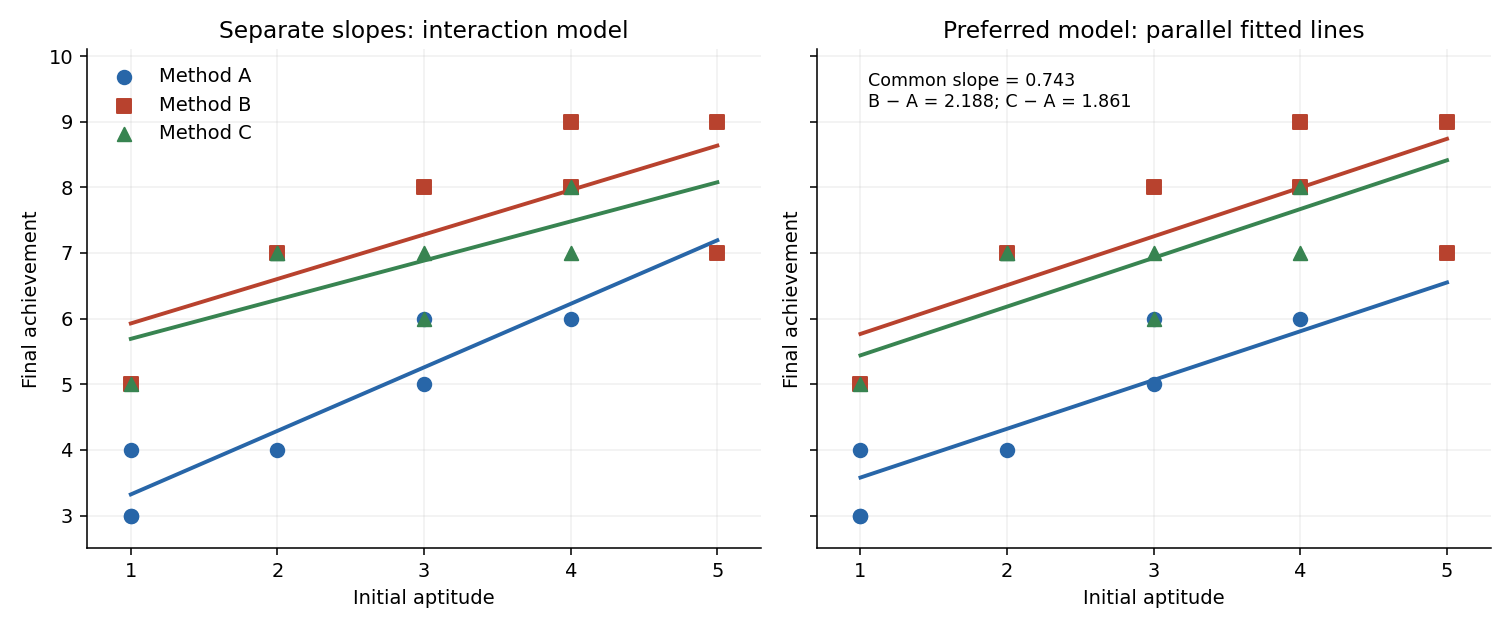
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 42 4 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use the usual stochastic-integrability assumptions implicit in the price stochastic differential equation: the coefficients have progressively measurable versions, the volatility is locally square integrable, and initial prices are finite deterministic positive numbers. A no-consumption admissible trading strategy consists of predictable risky share holdings for which the price stochastic integral exists and the portfolio wealth of the self-financing portfolio isThe remainder is held in the unit cash asset. Admissibility requires throughout the horizon for some deterministic finite ; the more restrictive nonnegative-wealth convention also works. A finite-horizon arbitrage is such a strategy with , almost surely and . The lower bound is essential to exclude doubling strategies.
Interpret the stated uniform ellipticity as for a deterministic . If , the market price of risk is bounded:The authoritative PDF puts both integrals inside the exponent. With that interpretation,On every finite horizon , boundedness of gives the Novikov condition:Hence the positive stochastic exponential is a true martingale with . Define the equivalent probability measure by . The Girsanov theorem says that is a Brownian motion under , up to time . Consequentlyso the prices are local martingales under .
Every admissible zero-initial-capital self-financing portfolio has portfolio wealth which is therefore a -local martingale bounded below by . The shifted process is a nonnegative local martingale, hence a supermartingale by localization and the Conditional Fatou lemma. In particular . If the strategy were an arbitrage, nonnegativity of would force -almost surely. Equivalence of and would then force , a contradiction. The market has no admissible arbitrage on any finite horizon. This proves the exclusion argument itself, rather than just asserting the fundamental theorem of asset pricing.
For the deflated price calculation, let denote the column vector whose transpose is the th row of . The Itô product rule includes the quadratic covariation termSince , the full product equation isLocalization makes the last stochastic integral a true martingale on each stopped interval, proving each component of the deflated price vector is a local martingale under the original measure. This is the bounded-coefficient asset deflator identity; bounded volatility has not yet been used.
If is bounded, then is bounded as well. Solving the last linear stochastic differential equation givesThe Novikov condition now holds for this stochastic exponential on every finite horizon, because its bracket is bounded by a deterministic constant times the horizon. ThereforeThe entire deflated price vector is a true martingale when volatility is bounded. This finite-horizon argument does not assert uniform integrability as time tends to infinity, which is not required. Integrable random initial prices can also be handled by the conditional martingale argument; without any integrability assumption on initial prices, a true-martingale assertion would not be meaningful.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 42 3 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Fix . For , the residual observed path isThis Brownian bridge is independent of . Indeed it is independent of , while its covariance with is ; zero covariance implies independence in the joint Gaussian law. The same argument for every finite collection of bridge times, followed by continuity and generation from rational times, gives independence of the entire bridge. Since the full observed path is determined by its endpoint and this independent bridge, Brownian endpoint sufficiency for a constant drift gives
First suppose the prior covariance matrix is positive definite. The Bayes' theorem multiplies the prior Gaussian density by the conditional observation density, whose dependence on is . Thus the posterior exponent, up to terms not depending on , isCompleting the square gives the Gaussian Brownian drift filter:For invertible these are equivalently and . At they reduce to the prior parameters.
The boxed formulas remain valid for a singular positive semidefinite matrix . To see this directly without inverse prior matrices, the joint Gaussian random vector hasThe latter matrix is invertible for . The conditional multivariate normal distribution therefore has meanand covariance matrixAlternatively, subtract this mean from ; the resulting Gaussian random vector has zero covariance with and is therefore independent of it, which proves these conditional parameters.
Write the proposed innovation process in the observable formIt is adapted to the observation filtration and continuous. To prove the martingale property, take . Future increments of are independent of the joint information generated by and the past of , soAlso the tower property of conditional expectation gives for . Conditional integration is legitimate because . Subtracting the integral proves . Removing a continuous finite variation process does not change quadratic covariation, henceThe Lévy characterization of multidimensional Brownian motion now applies: a continuous zero-start martingale with this bracket matrix is a standard -dimensional Brownian motion relative to its given filtration. The observable innovation is a Wiener process in the observation filtration.
Differentiating the posterior formulas yields andFor the final expression, the printed inverse matrices require the extra assumption that is positive definite. Under that assumption put . The Itô formula givessince and . On the other hand,The trace terms cancel in the innovation exponential for Gaussian drift filtering, leavingThus and is a positive stochastic exponential, hence a nonnegative local martingale. To obtain the requested supermartingale conclusion explicitly, choose localizing stopping times for which is a true martingale. The Conditional Fatou lemma givesThe same argument at gives , supplying integrability. The process is a supermartingale in the observation filtration. No unproved exponential-integrability condition on the random drift is required.
For a singular prior the literal inverse-matrix expression in the PDF is undefined, but there is a natural extension with the same conclusion. Define, for fixed ,For positive definite , a Gaussian integral shows this reciprocal is exactly the printed expression. For any positive semidefinite , the integral is positive and finite, , and , by the same posterior weighting. The Itô formula consequently gives . Its reciprocal satisfies the boxed stochastic differential equation and the same supermartingale proof. This completes the singular-covariance extension while explicitly separating it from the undefined printed formula.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 42 2 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write and let denote the optimal remaining expected reward from positive portfolio wealth at time . The Hamilton-Jacobi-Bellman equation and terminal condition areThe controls are progressively measurable, the investment integrals exist, consumption is nonnegative and locally integrable, and the resulting portfolio wealth stays in the utility domain. At zero consumption use the right limit of the utility function if needed. This is the usual admissible trading strategy formulation; without restrictions preserving the domain the reward need not be defined.
For the verification bound, assume is a nonnegative classical solution, continuous through the terminal time, with one time derivative and two wealth derivatives in the interior. Fix any admissible controls and putThe Itô formula givesThe drift is nonpositive because the actual controls cannot exceed the supremum in the Hamilton-Jacobi-Bellman equation. Localize by stopping times on which the stochastic integral is a true martingale, the derivatives and wealth stay in their interior domain, and the accumulated reward is finite. For each such stop ,Both utilities and are nonnegative. Thus the Fatou lemma, continuity, and the terminal condition giveFor admissible paths strictly positive on the closed horizon, the domain-localizing stops eventually reach . If zero wealth is allowed, the same proof uses the continuous boundary extension of and the utilities there. Nonnegativity is what permits removing the stops without assuming the uncontrolled stochastic term already has zero expectation. This is verification by a nonnegative control supermartingale.
The square-root case needs an additional no-arbitrage qualification because the printed volatility matrix need not be invertible. If there is with , investment has zero volatility and arbitrarily large positive drift. With any fixed positive consumption, sufficiently large preserves positive wealth and makes terminal square-root utility tend to infinity. For example, in one dimension , , , gives , so the value is infinite when . A finite separated solution does not exist for all matrices allowed by the printed hypotheses.
The needed condition is , equivalent to being orthogonal to , because is a symmetric matrix and . Assume this condition and let be its Moore-Penrose inverse; if is invertible, simply use . Put . Seek the square-root investment-consumption value in the formThen and . Completing the quadratic investment expression, using , shows that its maximum is attained at and has value :Any investment component in has no effect. For consumption, set . Its contribution is the concave quadratic , whose maximum is at . Substituting both maxima into the Hamilton-Jacobi-Bellman equation givesWith , this becomes , . Solving this linear ordinary differential equation givesIn particular , so stays positive, and the two controls areThese controls are admissible and actually attain the value. Indeed their portfolio wealth satisfiesSince , the explicit positive solution starting at isIts finite-horizon moments of every positive order are finite. More directly,Differentiating and using the equation for gives . Integrating from to therefore yieldsThis proves attainment without relying on an unjustified expectation of a local martingale. When is outside , the singular-volatility drift arbitrage counterexample applies instead.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 42 1 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let be the inverse marginal utility. The derivative is continuous and strictly decreasing: concavity makes it nonincreasing, and equality at two distinct points would make affine between them, contradicting strict concavity. The Inada conditions therefore make a bijection from onto . For each , the derivative of is positive below and negative above it. Consequently its unique global maximum is finite andThere is no need to differentiate to find the first derivative of this utility conjugate. Comparing the maxima at and gives, for ,Continuity of , together with the corresponding inequalities for , givesThus is strictly decreasing and strictly convex, since its derivative is strictly increasing. This proves all the asserted properties except the second differentiability, which does not follow from the printed hypotheses.
Here is an explicit Inada utility with vanishing curvature. PutThe positive integral defining makes strictly increasing. Also is negative except at one point, so is strictly decreasing and is strictly concave. Near zero is asymptotic to , and at infinity it is asymptotic to ; thus and . This smooth utility function satisfies every printed positive-domain assumption, but . At , differentiability of would imply, by differentiating ,which is impossible. Hence has no finite derivative there. More explicitly, , so its inverse function has a cube-root singularity. The twice-differentiable conclusion is false as printed. With the additional assumption everywhere, the inverse function theorem proves the intended dual differentiability with nonvanishing utility curvature:
For the financial assertions, use the positive-wealth admissible trading strategy class appropriate to the positive-domain utility function, and expectations for which the expressions are defined. A normalized terminal state-price density satisfies , , and defines an equivalent martingale measure by . A self-financing portfolio obeyswhere the holdings are measurable before the next price increment. Under the gains are a martingale when integrable; for the usual lower-bounded admissible class, localization gives a supermartingale. In particular the state-price budget constraint is . The positive-domain qualification matters: assumptions only on at positive arguments do not control its values at nonpositive wealth.
The definition of the utility conjugate gives the pointwise inequalityTaking expectations, using the state-price budget constraint, and then taking the supremum over strategies gives for every and every state-price density. Taking the two infima proves the utility duality with martingale deflators upper bound:If an expectation is infinite, use the same inequality in the extended-real sense whenever the negative parts make it well defined; no subtraction of two infinities is needed.
A complete market is one in which every terminal contingent claim in the specified claim class is attainable by a self-financing portfolio. Bounded terminal claims suffice for the uniqueness argument. In the standard finite-horizon discrete-time market, absence of arbitrage gives existence of an equivalent martingale measure by the fundamental theorem of asset pricing. To prove uniqueness, let and be two normalized state-price densities. Every bounded claim has a replicating price , and its replication has the same price under either equivalent martingale measure:Take for every terminal event . The integrable difference has zero integral over every event, hence vanishes almost surely: its positive and negative sets would otherwise give a nonzero integral. The normalized terminal state-price density is unique up to null sets. Its density process is then uniquely . This uses the usual pricing replication class, where bounded claims have bounded replicating value processes; arbitrary doubling strategies are not an admissible definition of completeness.
For logarithmic utility, direct maximization gives . In the complete market, write . The unique-density utility conjugate bound is minimized at , givingThe candidate terminal portfolio wealth is , whose cost is exactly . If completeness includes nonnegative -integrable claims, it is replicable and attains the bound. There is also an approximation proof using only bounded-claim completeness. DefineThen , , is positive and bounded, and . Replicating therefore gives an admissible terminal claim of initial cost . Since , the negative parts of have an integrable common bound. Monotone convergence after adding this lower bound givesConsequently the logarithmic terminal wealth in a complete market isThe value may be if ; the displayed formula remains meaningful, while attainment by depends on the precise admissible claim class.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 41 6 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use a risk-neutral measure , and let be the price at time of a zero-coupon bond paying one at its maturity . The information available at is the filtration . For positive differentiable bond prices, the instantaneous forward rate iswith . The short rate is . The continuous-time bank account is the discounting numéraire.
If is a true martingale for each fixed maturity, then its terminal value is andMultiplication by the -measurable givesConversely this conditional-expectation formula makes the discounted bond a martingale by the tower property of conditional expectation. The equivalence uses integrability and true martingales, rather than merely local martingales.
Forward-rate modelling specifies the stochastic evolution of as varies at fixed maturity. For example, with one Brownian driver, write . Differentiation of the integral representation and Itô formula give the bond's relative volatility and drift . The discounted-bond condition therefore imposesor, after differentiation in maturity, . This illustrates how the no-arbitrage condition constrains forward-rate drift.
For the Gaussian short-rate model with constant coefficients, let and fix . Future Brownian increments are independent of , givingThe last stochastic integral is Gaussian with mean zero and variance , by the Itô isometry. Its Gaussian moment-generating function therefore givesWhen and the initial rate is deterministic, the Brownian and short-rate filtrations coincide because . If , the same bond formula holds deterministically, while the asserted filtration equivalence is unnecessary.
For a deterministic drift function , the same calculation givesLet the observed initial curve be , normalized by , and define . For a differentiable initial forward curve chooseIndeed the model's initial forward rate is , so integrating it gives exactly the observed bond curve. This is forward-curve calibration of a shifted Brownian short rate, with . Every finite collection of positive bond quotes can first be fitted by a smooth positive curve; an arbitrary entire curve requires the stated smoothness or an appropriate weaker integral interpretation. The freedom is in the deterministic drift, and the initial short rate must match the initial forward rate.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 41 5 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let , and assume the payoff has sufficient integrability for risk-neutral valuation. Under the risk-neutral measure , the Black-Scholes model has , so conditionally on ,Absence of arbitrage gives the time- priceFor a regular payoff this is the solution of the Black-Scholes equation with terminal value , and the delta hedge replicates it. Suitable limits or conditional-expectation representations extend the price formula beyond smooth terminal payoffs.
For the logarithmic stock payoff, put . Its Gaussian moment-generating function is , while differentiating that moment gives . ThereforeThe option delta is , and the second stock derivative is . The Black-Scholes equation can also be checked directly from .
For general convex , let . For , convexity givesTaking the positive discounted expectation proves that is convex. Its derivative, where defined, is therefore nondecreasing, proving that the stock holding in the delta hedge rises weakly with the stock price. For twice differentiable , differentiation gives . For a merely convex payoff, Gaussian smoothing at and the usual growth assumptions give the same conclusion; one-sided derivatives are monotone even without smoothing. Strict increase is not implied by convexity alone: an affine payoff has constant option delta.
For the random constant Gaussian interest-rate mixture, represent the rate as , with independent standard normal variables. This independence simply represents averaging the constant-rate price function over its Gaussian parameter. Completing the square in yields the identityApply it inside the time-zero price formula:The combined normal term has variance . Define and . Then the discount factor is , and the log-price mean is . Thus the expectation is exactly the constant-parameter Black-Scholes model price with those parameters:The argument applies to nonnegative payoffs by Tonelli theorem, and to signed payoffs whenever absolute integrability justifies the expectations. It averages constant-rate prices; it does not assume a stochastic short-rate process.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 41 4 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write and for the risk-free asset paying one at . Under the physical measure, , with , while . A self-financing portfolio with predictable stock and bond holdings has value and gainsRebalancing therefore adds no outside money and withdraws none. This gains equation, rather than merely the value decomposition, defines self-financing.
Let . The Itô formula givesThe prescribed portfolio gains instead have diffusion coefficient and drift . Equality of diffusion coefficients requires , equivalentlyUnder this condition, . Equality of drifts is then . Since , this becomesThese conditions are also sufficient by the same Itô formula. Necessity initially holds along the stock process. Its positive transition density on for every positive time, together with continuity of the coefficient functions, extends the identities to all and then to the time endpoints by continuity.
For a self-financing portfolio, substitute and into the drift identity to obtain the Black-Scholes equationConversely, a smooth solution of this equation gives a self-financing portfolio by choosing the delta hedgeIts value is , and both coefficient identities follow directly.
The printed deduction needs this holdings qualification: the Black-Scholes value equation needs delta-compatible holdings. A value function alone cannot make an arbitrary prescribed decomposition self-financing. As a counterexample, take , , . The value function solves the Black-Scholes equation, but this zero-value portfolio has gains , which contain the nonzero term . Thus for the originally specified , the exact equivalence is the pricing equation together with , not the pricing equation alone.
For a claim paying the holder at rate , let denote its remaining, ex-dividend value. A replicating portfolio pays out , so its net wealth equation is . The delta hedge is still , but the Black-Scholes equation becomesIf there is a terminal payoff , set ; with no terminal payment set it to zero. The corresponding risk-neutral valuation isEach intervening payment is discounted from its own payment time.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 41 3 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let and write for the Brownian terminal density. By the Brownian reflection principle, for the reflected paths that hit and end at have terminal density . HenceThe Girsanov theorem changes zero drift into drift using the finite-horizon density . The finite-horizon maximum of Brownian motion with drift therefore has distribution functionIn the first integral term, complete the square to get a normal density with mean . In the second, substitute and complete the square with mean ; the prefactor is . Here is the standard normal distribution function, and .
Let , with real. Survival means that stays below . Tilt by ; under the tilted probability, has drift . Applying the maximum formula with drift gives the exponential terminal moment below a linear Brownian boundaryThis holds for every real . The maximum distribution has no atom at the positive barrier, so strict or weak survival inequalities give the same probability here.
For the hitting-time moment, first use drift in the maximum formula and take the complementary probability:If and , their standard normal densities satisfy . Differentiating the two terms, with and , yields the drifted Brownian first-passage densityIts total mass need not be one, because the upward-sloping boundary may never be reached.
For , put . Multiplication by gives . Integrating to produces truncated discounted Brownian first passage, with negative discount rate allowed when the square root remains real:This includes the equality case , where it becomes . The expression integrates only finite hitting times up to ; no value is assigned to an exponential at an infinite hitting time.
For the cash-at-hit digital call, use the risk-neutral measure in the Black-Scholes model and denote expiry by . ThenHitting corresponds to , where and . The unit-cash payment is made at the hitting time, so risk-neutral valuation discounts at that time, not at expiry. Set andThe identity on the right verifies the square-root condition even for negative interest rates. The time-zero price isThis is in pounds for the unit-pound contract. It differs from a maturity-paid digital call option, whose discounting and exercise event are different.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 41 1 a by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14 Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact