Power iteration finds a dominant eigenvalue and its eigenvector by repeatedly applying a matrix and rescaling the resulting vector. The essential idea is selective amplification: components along different eigenvectors grow at different rates, so one direction can eventually dominate. It is the computational form of the power method and is useful when applying a large sparse matrix to a vector is cheap but computing its whole spectral decomposition is expensive.
For a square matrix over the real numbers or complex numbers , choose a unit vector and repeatHere is the Euclidean norm. If , stop before division: the current vector is an eigenvector for the zero eigenvalue, and this iteration cannot continue. Otherwise, in exact arithmetic,Repeated normalization keeps the stored vectors at manageable size without changing their directions; it does not guarantee that an individual multiplication cannot exceed the range of floating-point arithmetic. The dominant eigenvalue means largest modulus, which need not mean largest signed real value.[ref]
Consider the symmetric matrix and initial unit vectorIts orthonormal eigenbasis consists of and , with eigenvalues and . Since , direct multiplication givesThe first unnormalized vectors are , , , and . If is the acute angle from the line spanned by the dominant eigenvector, then . Every application divides the unwanted-to-wanted component ratio by three: normalization changes lengths, while the spectral gap selects the direction.
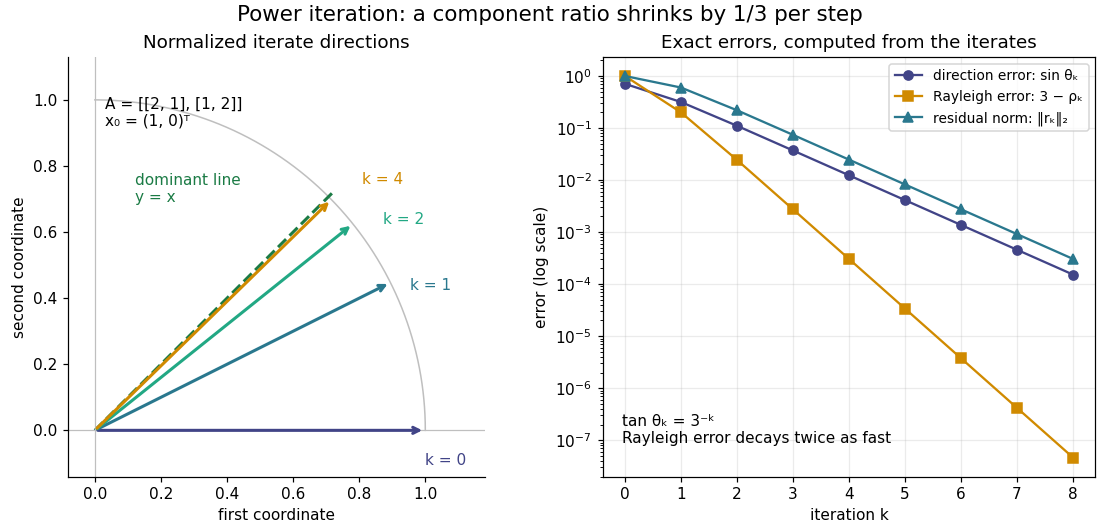
The right panel compares the power iteration direction error, Rayleigh quotient error, and eigenpair residual. With , their exact values areThus a very accurate Rayleigh quotient can appear well before the eigenvector is comparably accurate. This is an example of quadratic Rayleigh-quotient improvement for the power method.
Suppose is a diagonalizable matrix, , with an eigenbasis and spectral decompositionAssume the dominant eigenvalue is a simple eigenvalue andThen the normalized power iteration approaches the one-dimensional eigenspace of . Its asymptotic direction-error bound has factor . This spectral gap is a gap in modulus: if , then . A small relative gap gives slow convergence.[ref]
The short proof is the exact eigenbasis identityThe remaining sum has norm bounded by a constant times . This proves convergence of direction, allowing a changing sign or complex factor. A tiny or a poorly conditioned, nonorthogonal eigenbasis can delay visible convergence: the condition number of affects constants, while controls the eventual rate. The bound need not be an equality; if the initial coefficient of the second-largest eigenvalue vanishes, the active spectrum of the power method gives a faster rate. When , all unwanted components disappear after one multiplication.[ref]
The hypothesis is , not an ordinary nonzero inner product with the right eigenvector. Let be the first row of , a left eigenvector normalized so is for and otherwise; denotes conjugate transpose. Then . For a Hermitian matrix, choose an orthonormal eigenbasis and the criterion becomes : the starting vector must be nonorthogonal to the dominant eigenvector. For a general diagonalizable matrix, the nonorthogonal eigenbasis makes these two tests different, as illustrated under power iteration failure cases.
For a unit vector spanning the target eigenspace and a normalized iterate , defineThis is the norm of the component in the orthogonal complement of , equivalently the sine of the acute angle to its line. It ignores the arbitrary sign or complex unit factor of an eigenvector. Under power iteration convergence for a diagonalizable matrix, in Big O notation. The orthogonal projection defines how we measure direction; it does not assume that the eigenbasis of is orthogonal. In computation, the projection form avoids subtracting nearly equal numbers inside the square root.
Under power iteration convergence for a diagonalizable matrix, take to be a unit vector. The displayed formula describes both the dominant eigenvector direction and its rotating complex unit factor. With real data and a positive dominant eigenvalue, converges to or according to the sign of . With a negative dominant eigenvalue, consecutive vectors approach opposite signs even though their power iteration direction error tends to zero.
For complex data write , where is its complex argument. The leading factor turns by per step, so the vectors generally do not converge. For example, and give : the first component cycles through four phases while the ratio of component moduli tends to zero. Its power iteration direction error is . Multiplying by gives a sequence converging to .
A stopping rule based only on therefore rejects successful sign-alternating iterations. A comparison invariant under complex unit factors isEven this comparison can be small for a slowly changing wrong mixture; the eigenpair residual supplies a separate diagnostic.
For each unit vector iterate compute the Rayleigh quotient and the eigenpair residual . Use the same multiplication for both diagnostics and the next normalized iterate. For any complex matrix, this Rayleigh quotient minimizes over complex scalars , because . Under power iteration convergence for a diagonalizable matrix, and , even when the vectors alternate signs or phases.[ref]
A dimensionless stopping quantity iswhen the denominator is positive; is the operator norm, and a known upper bound may replace it if computing it is costly. A small eigenpair residual certifies a small backward error of an approximate eigenpair, but does not establish that the eigenvalue found is dominant.
For a Hermitian matrix with orthonormal eigenbasis , write . Then the independently useful identityshows that some eigenvalue lies within of . If a specific target eigenvalue is separated from all the others by , it also gives . This separation is measured from the computed Rayleigh quotient; it differs from the dominant-modulus spectral gap. For a nonnormal matrix, the same orthogonal expansion is unavailable and a small eigenpair residual alone need not imply a comparably small distance to the spectrum.
A tied largest modulus can prevent even direction convergence. With and ,The two directions form a cycle; neither is an eigenvector. There is no dominant-modulus spectral gap. A tied modulus is not a universal failure: an initial eigenvector remains on its line, and preserves every direction. Subspace iteration addresses a separated cluster by targeting a dominant invariant subspace instead of one eigenvector.
An orthogonal start can fail despite a strict spectral gap. For and , the dominant component is zero, so and every iterate equals . The Rayleigh quotient is exactly and the eigenpair residual is zero, although the dominant eigenvalue is . Exact arithmetic never creates a missing component.[ref]
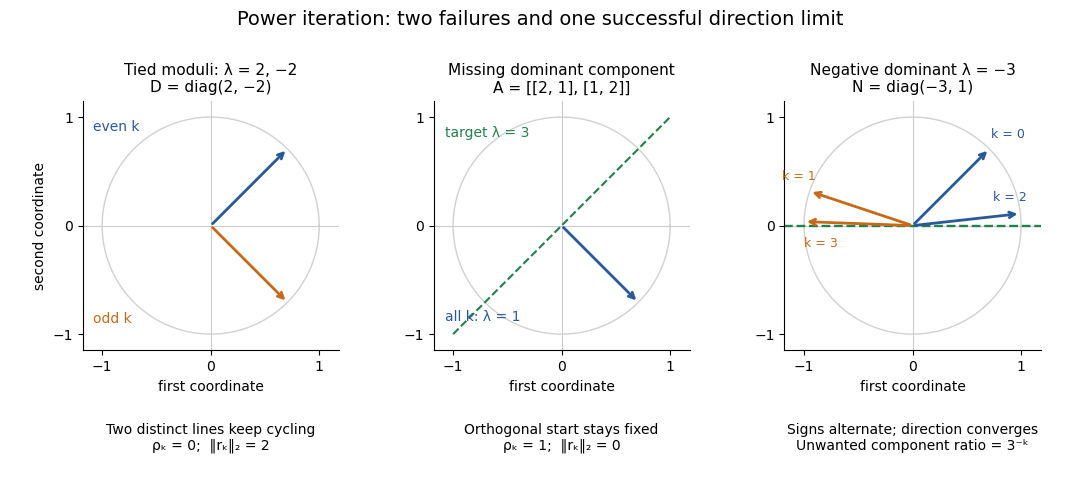
The third panel contrasts these failures with , , for whichHere the horizontal eigenvector direction converges with a strict spectral gap, while the normalized vectors alternate signs. This is the successful direction convergence described under sign and phase in power iteration.
For a nonorthogonal eigenbasis, even the word “orthogonal” must be used carefully. The diagonalizable matrix has right eigenvectors , , and dominant left eigenvector . For , the dominant coefficient is . The starting vector is nonorthogonal to but stays at the smaller eigenvalue ; is orthogonal to but has and converges to the dominant direction. The left eigenvector test, not the right-eigenvector inner product, controls the outcome.
A random vector drawn from a continuous probability distribution with a probability density function on the full real or complex vector space has with probability one. This avoids the exact missing-component hyperplane, but does not guarantee a large component or fast convergence. Floating-point arithmetic may seed a missing component, yet a structurally preserved zero can remain zero, so accidental perturbations are not a convergence guarantee.
Articles by others on the same topic



Power iteration is a numerical method used to find the dominant eigenvalue and its corresponding eigenvector of a matrix. This technique is particularly effective for large, sparse matrices, where traditional methods like direct diagonalization may be computationally expensive or impractical. ### How Power Iteration Works: 1. **Initialization**: Start with a random vector \( \mathbf{b_0} \) (which should not be orthogonal to the eigenvector corresponding to the dominant eigenvalue).