A Krylov subspace method seeks approximations in spaces generated by repeated matrix applications to a starting vector. For a linear system with starting point and residual , the affine search space is . Choosing an optimality or orthogonality condition within it gives different algorithms. The conjugate gradient method minimizes the energy norm of the error for a symmetric positive-definite matrix; other methods use residual minimization or different projections. The growth of the Krylov subspace can stop early when an invariant subspace is reached.
An algorithm for solving a linear system . Tolerance and conditioning can limit a differential-equation calculation even when its time-stepping method is stable.
Matrix preconditioning transforms a linear system using an inexpensive auxiliary solve to improve its eigenvalues. For symmetric positive-definite matrices, a symmetric positive-definite matrix produces , preserving the symmetric structure needed by the conjugate gradient method.
A useful matrix preconditioner combines a cheap solve with favorable transformed eigenvalues; neither property alone is enough.[ref]
The aim is to make each correction more effective without making it expensive. The example under diagonal scaling for a two-dimensional linear system turns thin ellipses into nearly circular ones and makes preconditioned steepest descent effective.
A matrix preconditioner is an auxiliary invertible matrix whose matrix inverse is cheap to apply and whose use improves the eigenvalues of a linear system. In symmetric positive-definite matrix problems, a symmetric positive-definite matrix preserves that structure under the symmetric transformation .
Applying means solving for a supplied vector . This notation does not require forming a general matrix inverse. A diagonal matrix gives componentwise divisions; a factored matrix gives auxiliary solves such as forward substitution and back substitution.[ref]
Notes for Ma221 Lecture 21, Nov 10 2009. Math 221, Matrix Computations, Fall 2009; Basic iterative methods, web lines 297–308, recurrence (*) and cheap auxiliary-solve requirement
Choosing makes the solve trivial but changes nothing; choosing gives the exact correction but asks us to solve the original linear system.[ref]
The Jacobi preconditioner keeps only the diagonal entries of the matrix . For a symmetric positive-definite matrix, these entries are positive, so its auxiliary solve is . It rescales coordinates with very different diagonal sizes, but cannot remove arbitrary off-diagonal coupling.[ref]
This shares a diagonal matrix with the Jacobi method, but the roles differ. The Jacobi method specifies a whole stationary iterative method for a linear system; a Jacobi preconditioner supplies an auxiliary solve to another iterative method, including the Preconditioned conjugate gradient method.
Left preconditioning multiplies both sides of the linear system by the same invertible matrix . It leaves the unknown vector unchanged. The original linear-system residual is ; the transformed linear-system residual is . Applying the transformed linear map to first computes , then solves .
For symmetric positive-definite matrices and , is generally not a symmetric matrix in the Euclidean inner product. Its positive eigenvalues alone do not justify ordinary Euclidean conjugate gradient method recurrences. The remedy is symmetric positive-definite preconditioning, implemented through the Preconditioned conjugate gradient method.
Right preconditioning substitutes into the linear system . Applying its transformed linear map first solves , then computes . Recover the solution by solving . Its linear-system residual is exactly the original linear-system residual , which is useful when monitoring the imbalance in the original equations.
The left preconditioning and right preconditioning transformed matrices are similar matrices:They therefore have the same eigenvalues, although their Euclidean norm condition numbers and residual histories need not agree. A similarity transformation preserves eigenvalues; a nonorthogonal change of coordinates need not preserve lengths.
Let and be real symmetric positive-definite matrices. The principal square root of a positive semidefinite matrix construction gives an invertible matrix for each. SetThen is equivalent to . This is a matrix congruence, and is a symmetric positive-definite matrix: , and for every nonzero vector ,since . This short proof establishes both requirements for applying the conjugate gradient method to the transformed linear system.
The left transformed matrix has the same eigenvalues becauseIts correct geometry uses the weighted inner product : . Thus it is symmetric in this inner product, even when it is not a symmetric matrix in ordinary coordinates. The spectral condition number governing the transformed symmetric problem is , not generally .
The Preconditioned conjugate gradient method realizes this transformation using auxiliary solves , without constructing or its matrix inverse. With fixed , initialize and ; while , usethen solve and setStop at a zero linear-system residual before forming another ratio. Positive definiteness makes the denominators positive before termination.[ref]
Notes for Ma221 Lecture 15, Dec 1, 2023. Math 221, Matrix Computations, Fall 2023; Notes for Ma221 Lecture 15, Dec 1, 2023; PDF p. 1, equivalent symmetric system and Preconditioned CG algorithm
An invertible matrix alone is insufficient: with and , the left transformed matrix has eigenvalues , and has no real symmetric positive-definite matrix square root. Even a valid symmetric positive-definite matrix can worsen conditioning if its scaling is unsuitable, as the next worked example shows.
For a symmetric positive-definite matrix , solving is equivalent to minimizing the quadratic form with linear termWriting the error vector and expanding gives the exact energy norm identityThe cross term vanishes because . With and , the same quantity is . Symmetric positive-definite preconditioning changes coordinates without changing the energy assigned to a corresponding error vector.
In an orthonormal eigenbasis of , the level set has semiaxis lengths . Its longest-to-shortest axis ratio is . A large spectral condition number of a positive-definite matrix therefore appears geometrically as a thin ellipsoid. Good scaling makes the transformed ellipsoid rounder, allowing a simple search direction to improve all coordinates together.
The negative gradient of is the linear-system residual . Relative to the norm , a steepest direction is : the Cauchy-Schwarz inequality applied to shows that the greatest decrease per unit -length occurs along this direction. Equivalently, ordinary gradient descent in becomes preconditioned steepest descent in .[ref]
Consider the original linear systemCompleting the square proves that is a symmetric positive-definite matrix:The Jacobi preconditioner has . Symmetric positive-definite preconditioning givesIts eigenvectors and have eigenvalues and . HenceThe characteristic polynomial of is . Its eigenvalues and spectral condition number of a positive-definite matrix areThe ellipse axis ratio drops from about to . The transformation multiplies the second coordinate by ten, bringing the two energy scales together.
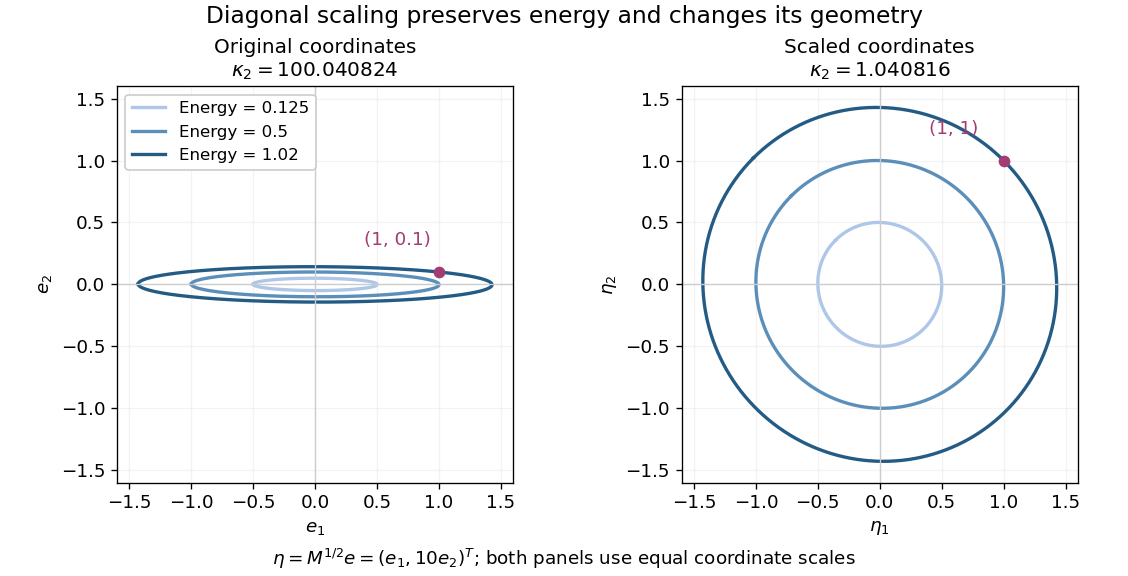
Both panels show the same energy level sets, expressed in error coordinates and . Their coordinate axes have equal scales. The marked displacement becomes ; its energy remains . These are exact contours of the specified quadratic form.
Solving the original equations givesDirect matrix multiplication checks both linear-system residuals:By contrast, left preconditioning gives , which is visibly not a symmetric matrix, despite having the same positive eigenvalues as .
A bad scaling can reverse the benefit: the still valid symmetric positive-definite matrix gives . Its Rayleigh quotients on the coordinate unit vectors are and , so . Cheapness and positive definiteness do not guarantee improved conditioning.
For fixed symmetric positive-definite matrices and , preconditioned steepest descent minimizes along the direction supplied by the auxiliary solve. Given , form the linear-system residual . If , stop: . Otherwise solve and useThis is exact line search for a positive-definite quadratic along . Indeed,whose derivative vanishes at the displayed positive step size. Unlike the Preconditioned conjugate gradient method, it uses the fresh directly rather than combining it with a previous conjugate direction.
For diagonal scaling for a two-dimensional linear system, start at . Without matrix preconditioning, take : , , andWith the Jacobi preconditioner , , , andThe original linear-system residual becomes much smaller after this correction. Quantify progress in the same energy norm in both cases: and . Exact substitution givesIn this particular example the entire histories are and . To check that this is exact, the next step sizes are and , respectively, and their residual updates give and . Multiplying a linear-system residual by a nonzero scalar leaves the next step size unchanged; every pair of steps repeats the same directions at a smaller scale. The two first-step energy ratios then establish these formulas for all .
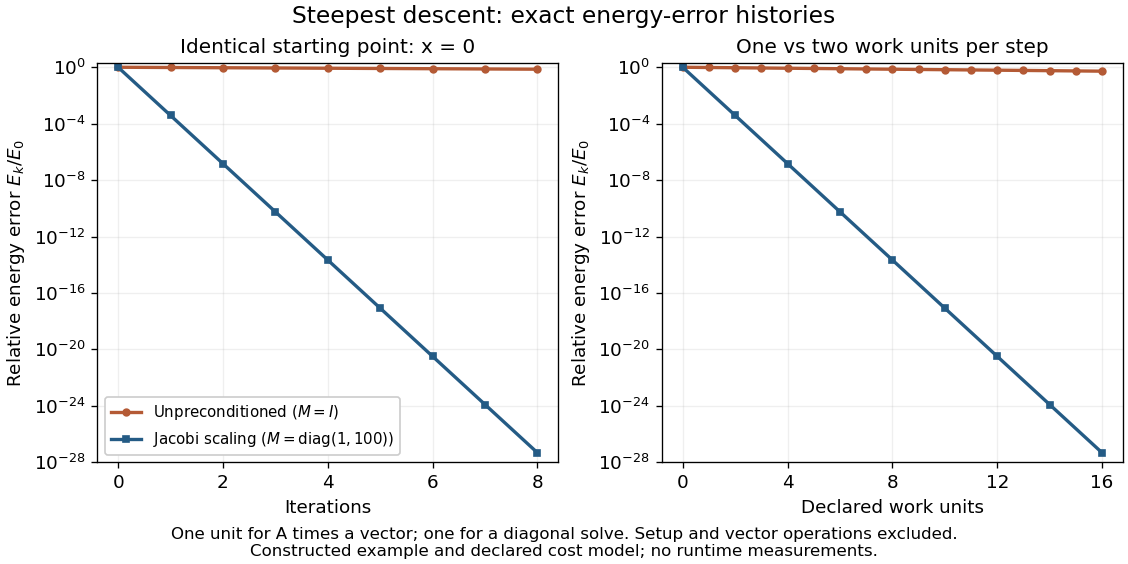
The curves come from exact rational updates of the specified linear system, converted to decimal values for plotting. The left panel counts iterations. The right panel declares one unit for applying and one unit for the auxiliary diagonal solve, charging one unit per unpreconditioned step and two per preconditioned step. It excludes setup and vector operations, so it compares a declared cost model rather than measured runtime. Scaling is advantageous even with that extra charge.
These curves compare steepest descent method iterations. On this two-dimensional linear system, both the conjugate gradient method and the Preconditioned conjugate gradient method terminate within two steps in exact arithmetic. The plot therefore establishes no CG iteration-count advantage for this example; the benefit of scaling for larger problems depends on their eigenvalues and auxiliary-solve costs.
Let , and for the transformed symmetric positive-definite matrix. Then preconditioned steepest descent satisfiesThis is a worst-case bound, not necessarily the actual rate. For our scaled example the bound is , slightly above its computed factor . If the initial transformed error is an eigenvector, exact line search for a positive-definite quadratic removes it in one step, regardless of the full condition number.
A short proof compares exact line search for a positive-definite quadratic with the trial step size in the transformed coordinates. In an orthonormal eigenbasis of , each error coefficient is multiplied by , whose absolute value is at most . Summing times the squared coefficients bounds the trial energy by the square of this factor. The exact minimizing step size does at least as well. This also explains the terminating case : the trial step removes the entire error in one iteration.
Power iteration finds a dominant eigenvalue and its eigenvector by repeatedly applying a matrix and rescaling the resulting vector. The essential idea is selective amplification: components along different eigenvectors grow at different rates, so one direction can eventually dominate. It is the computational form of the power method and is useful when applying a large sparse matrix to a vector is cheap but computing its whole spectral decomposition is expensive.
For a square matrix over the real numbers or complex numbers , choose a unit vector and repeatHere is the Euclidean norm. If , stop before division: the current vector is an eigenvector for the zero eigenvalue, and this iteration cannot continue. Otherwise, in exact arithmetic,Repeated normalization keeps the stored vectors at manageable size without changing their directions; it does not guarantee that an individual multiplication cannot exceed the range of floating-point arithmetic. The dominant eigenvalue means largest modulus, which need not mean largest signed real value.[ref]
Consider the symmetric matrix and initial unit vectorIts orthonormal eigenbasis consists of and , with eigenvalues and . Since , direct multiplication givesThe first unnormalized vectors are , , , and . If is the acute angle from the line spanned by the dominant eigenvector, then . Every application divides the unwanted-to-wanted component ratio by three: normalization changes lengths, while the spectral gap selects the direction.
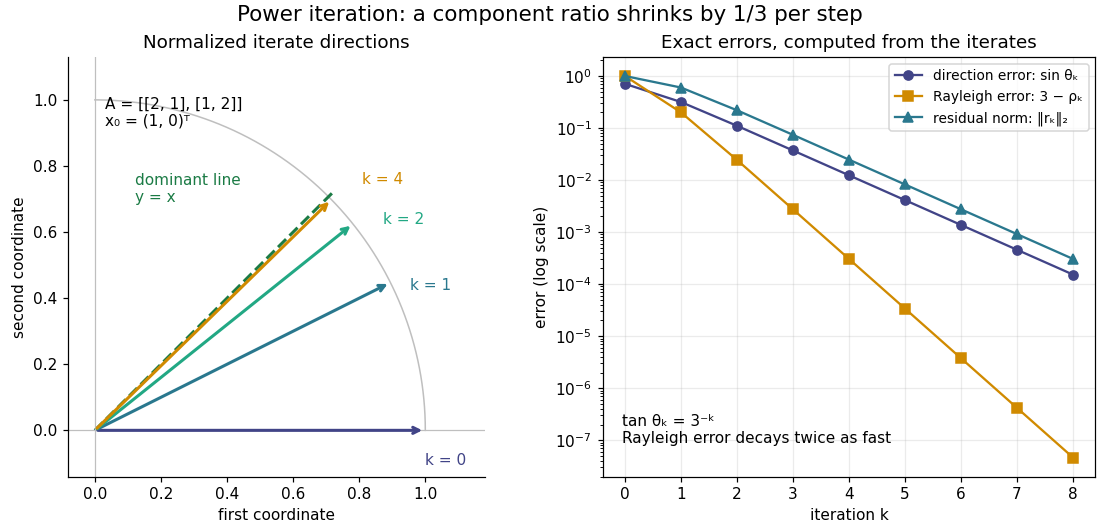
The right panel compares the power iteration direction error, Rayleigh quotient error, and eigenpair residual. With , their exact values areThus a very accurate Rayleigh quotient can appear well before the eigenvector is comparably accurate. This is an example of quadratic Rayleigh-quotient improvement for the power method.
Suppose is a diagonalizable matrix, , with an eigenbasis and spectral decompositionAssume the dominant eigenvalue is a simple eigenvalue andThen the normalized power iteration approaches the one-dimensional eigenspace of . Its asymptotic direction-error bound has factor . This spectral gap is a gap in modulus: if , then . A small relative gap gives slow convergence.[ref]
The short proof is the exact eigenbasis identityThe remaining sum has norm bounded by a constant times . This proves convergence of direction, allowing a changing sign or complex factor. A tiny or a poorly conditioned, nonorthogonal eigenbasis can delay visible convergence: the condition number of affects constants, while controls the eventual rate. The bound need not be an equality; if the initial coefficient of the second-largest eigenvalue vanishes, the active spectrum of the power method gives a faster rate. When , all unwanted components disappear after one multiplication.[ref]
The hypothesis is , not an ordinary nonzero inner product with the right eigenvector. Let be the first row of , a left eigenvector normalized so is for and otherwise; denotes conjugate transpose. Then . For a Hermitian matrix, choose an orthonormal eigenbasis and the criterion becomes : the starting vector must be nonorthogonal to the dominant eigenvector. For a general diagonalizable matrix, the nonorthogonal eigenbasis makes these two tests different, as illustrated under power iteration failure cases.
For a unit vector spanning the target eigenspace and a normalized iterate , defineThis is the norm of the component in the orthogonal complement of , equivalently the sine of the acute angle to its line. It ignores the arbitrary sign or complex unit factor of an eigenvector. Under power iteration convergence for a diagonalizable matrix, in Big O notation. The orthogonal projection defines how we measure direction; it does not assume that the eigenbasis of is orthogonal. In computation, the projection form avoids subtracting nearly equal numbers inside the square root.
Under power iteration convergence for a diagonalizable matrix, take to be a unit vector. The displayed formula describes both the dominant eigenvector direction and its rotating complex unit factor. With real data and a positive dominant eigenvalue, converges to or according to the sign of . With a negative dominant eigenvalue, consecutive vectors approach opposite signs even though their power iteration direction error tends to zero.
For complex data write , where is its complex argument. The leading factor turns by per step, so the vectors generally do not converge. For example, and give : the first component cycles through four phases while the ratio of component moduli tends to zero. Its power iteration direction error is . Multiplying by gives a sequence converging to .
A stopping rule based only on therefore rejects successful sign-alternating iterations. A comparison invariant under complex unit factors isEven this comparison can be small for a slowly changing wrong mixture; the eigenpair residual supplies a separate diagnostic.
For each unit vector iterate compute the Rayleigh quotient and the eigenpair residual . Use the same multiplication for both diagnostics and the next normalized iterate. For any complex matrix, this Rayleigh quotient minimizes over complex scalars , because . Under power iteration convergence for a diagonalizable matrix, and , even when the vectors alternate signs or phases.[ref]
A dimensionless stopping quantity iswhen the denominator is positive; is the operator norm, and a known upper bound may replace it if computing it is costly. A small eigenpair residual certifies a small backward error of an approximate eigenpair, but does not establish that the eigenvalue found is dominant.
For a Hermitian matrix with orthonormal eigenbasis , write . Then the independently useful identityshows that some eigenvalue lies within of . If a specific target eigenvalue is separated from all the others by , it also gives . This separation is measured from the computed Rayleigh quotient; it differs from the dominant-modulus spectral gap. For a nonnormal matrix, the same orthogonal expansion is unavailable and a small eigenpair residual alone need not imply a comparably small distance to the spectrum.
A tied largest modulus can prevent even direction convergence. With and ,The two directions form a cycle; neither is an eigenvector. There is no dominant-modulus spectral gap. A tied modulus is not a universal failure: an initial eigenvector remains on its line, and preserves every direction. Subspace iteration addresses a separated cluster by targeting a dominant invariant subspace instead of one eigenvector.
An orthogonal start can fail despite a strict spectral gap. For and , the dominant component is zero, so and every iterate equals . The Rayleigh quotient is exactly and the eigenpair residual is zero, although the dominant eigenvalue is . Exact arithmetic never creates a missing component.[ref]
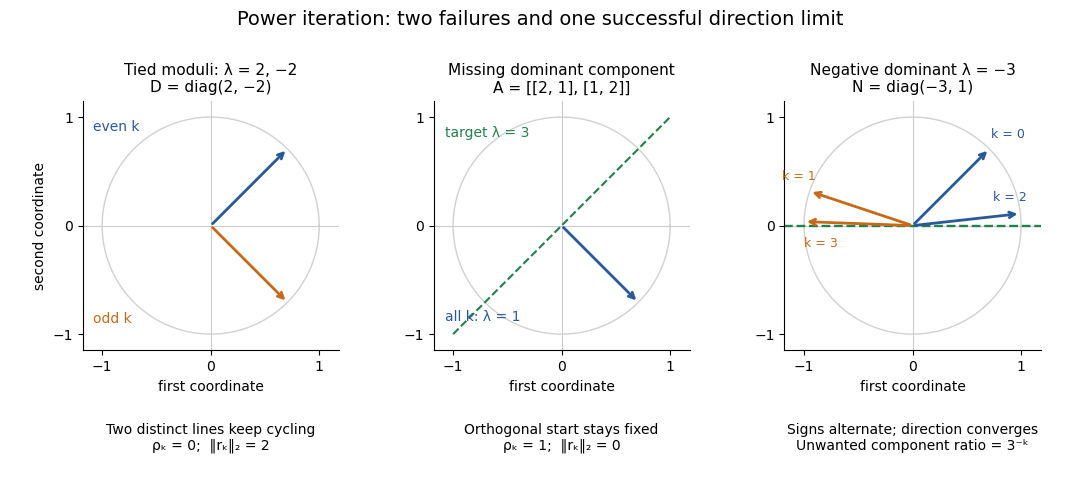
The third panel contrasts these failures with , , for whichHere the horizontal eigenvector direction converges with a strict spectral gap, while the normalized vectors alternate signs. This is the successful direction convergence described under sign and phase in power iteration.
For a nonorthogonal eigenbasis, even the word “orthogonal” must be used carefully. The diagonalizable matrix has right eigenvectors , , and dominant left eigenvector . For , the dominant coefficient is . The starting vector is nonorthogonal to but stays at the smaller eigenvalue ; is orthogonal to but has and converges to the dominant direction. The left eigenvector test, not the right-eigenvector inner product, controls the outcome.
A random vector drawn from a continuous probability distribution with a probability density function on the full real or complex vector space has with probability one. This avoids the exact missing-component hyperplane, but does not guarantee a large component or fast convergence. Floating-point arithmetic may seed a missing component, yet a structurally preserved zero can remain zero, so accidental perturbations are not a convergence guarantee.
Gaussian elimination applies elementary row operations to reduce a linear system to triangular form. Dense elimination uses arithmetic operations.
Gaussian elimination solves a linear system by removing one unknown from later equations at each step. Write the coefficients and right-hand side together as an augmented matrix . Apply the same elementary row operations to both parts until the coefficients form a row echelon form; for a square invertible matrix, this gives an upper triangular matrix system. Then back substitution recovers the unknowns from the last equation upward. The useful simplification is that each successive equation involves fewer unknowns, while the set of solutions stays the same.
Why do elementary row operations preserve solutions? Interchanging equations changes only their order. Multiplying an equation by a nonzero scalar can be undone by division. Replacing equation by itself plus times equation , with , can be undone by adding times the unchanged equation . Equivalently, an elementary matrix is an invertible matrix, so if and only if . Applying an operation to without also applying it to loses this equivalence.
At step , choose a nonzero pivot element after any row interchange. For every , form the elimination multiplier and perform the elementary row operation . Its coefficient in column becomes in exact arithmetic. Later operations combine rows that already have zeros in earlier columns, so those zeros survive. If an active column has no nonzero candidate, general row echelon form reduction skips it; a square invertible matrix always has a candidate at each step with suitable row interchanges. Partial pivoting also considers roundoff error when selecting the candidate.[ref]
2.6 Row pivoting. Fundamentals of Numerical Computation by Tobin A. Driscoll and others; §2.6.1, Definition 2.6.1: select the largest absolute candidate; §2.6.3: permute the right-hand side too
For a dense matrix with one right-hand side, the classical algorithm uses arithmetic operations over the real numbers, counting each addition, subtraction, multiplication and division as one. At step , the coefficient update has entries, each costing one multiplication and one subtraction; the elimination multipliers, right-hand-side updates and back substitution contribute lower-order terms. Searching for partial pivoting adds comparisons, and storing the dense coefficients uses space. These assumptions exclude the different storage and work patterns of sparse Gaussian elimination; the exact loop counts appear in LU factorization and solve costs. Here denotes Big O notation.
Recording the same steps as an LU decomposition makes Reusing LU factors for multiple right-hand sides possible. This is useful whenever the coefficients stay fixed while the forcing vector changes: the expensive elimination is done once. The choice of pivot element matters even when the linear system is well conditioned, as Tiny-pivot roundoff in Gaussian elimination demonstrates.
For a band matrix, elimination without pivoting retains bounded lower and upper bandwidths in its triangular factors. A tridiagonal system therefore needs only linear work and storage, as in the Thomas algorithm. Pivoting can change the precise fill pattern and must be included in the bandwidth and cost analysis when required. The inverse need not be banded, so solving through the factors preserves sparsity that explicit inversion would lose.
A fraction-free elimination algorithm for exact determinants. At each stage it divides a cross-multiplied update by the preceding pivot; the determinantal identities underlying the method make this division exact when its pivot assumptions hold. Pivoting handles zero pivots.
Consider this original linear system and its augmented matrix:The first diagonal entry is zero, so it cannot serve as a pivot element. Interchange and to obtain a pivot element of one:This chooses a convenient nonzero entry for exact arithmetic; partial pivoting would instead interchange and , selecting the largest absolute value, two. For our chosen ordering, the first-column elimination multipliers are and . The elementary row operation givesThe next pivot element is two and the next elimination multiplier is . Applying gives the upper triangular matrix systemEvery operation also changed the right-hand side. Back substitution now givesChecking the original equations, rather than only the reduced ones, verifies the answer by matrix multiplication:Thus a zero first diagonal entry was a row-order obstruction, not a singular matrix. Indeed, the diagonal product of the final upper triangular matrix is ; the single row interchange makes , since the two row additions preserve the determinant.
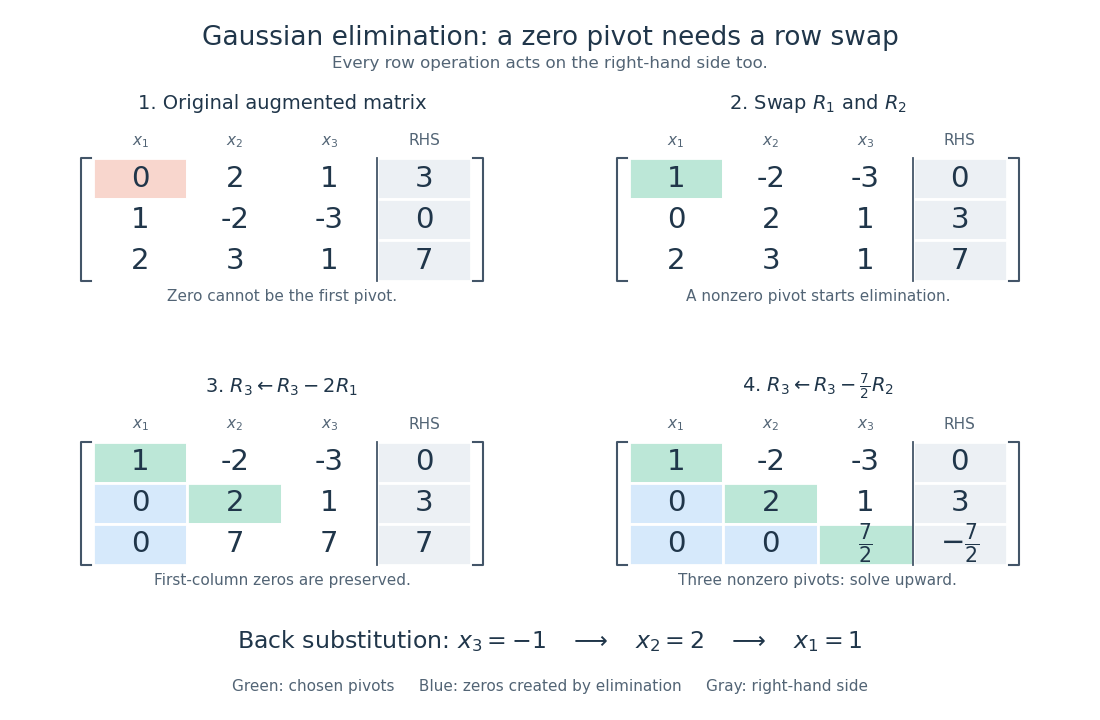
A row interchange supplies the first pivot element; successive elementary row operations create zeros, then back substitution gives
. Details. A pivot element is the current diagonal entry used to eliminate entries below it in Gaussian elimination, after any row interchange. At step it is , where is the current reduced matrix. Computing elimination multipliers requires this entry to be nonzero. A zero pivot element can reflect an unsuitable row order even for an invertible matrix, as Pivoted LU decomposition illustrates.
For , an elimination multiplier is the scalar used in the elementary row operation . This creates a zero below the pivot element. The remaining entries change by for . Storing these elimination multipliers gives the subdiagonal entries of in LU decomposition; later row interchanges must also reorder the already stored coefficients.
Sparse Gaussian elimination solves a linear system by Gaussian elimination while exploiting its sparse matrix structure to avoid storing zeros and performing unnecessary arithmetic operations. The catch is that zeros in the input need not remain zero: eliminating a shared unknown can couple two equations that previously had no direct coupling. These new positions are fill-in, and their number can depend strongly on the order of elimination.
For a real symmetric positive-definite matrix, the usual direct method is a Cholesky decomposition. Choose an ordering, use symbolic factorization to allocate the predicted factor entries, compute their values, then solve two triangular systems. Compressed sparse storage makes the reduced storage useful. General LU decomposition may also need numerical partial pivoting, so an ordering chosen for sparsity can change during factorization.[ref]
Lecture 27: Sparse Gaussian Elimination. Applications of Parallel Computers, CS267, Spring 1996; CS267, Lecture 27, 23 April 1996, Cholesky versus LU Decomposition: distinction between numerical pivot selection and advance ordering, and phases 1–4; Sparse Matrix Storage Schemes
For a fixed ordering, let be the permutation matrix that puts the unknowns in that order. Permute both rows and columns:Here is the lower triangular matrix in the Cholesky decomposition of ; . Forward substitution and back substitution give the original solution. The simultaneous permutation preserves the symmetric positive-definite matrix property because for every nonzero vector . A row permutation alone generally loses the symmetric matrix structure.
The local mechanism is a Schur complement. If the active pivot element is , then for remaining indices ,Even when , two nonzero couplings through make the second term nonzero. Thus the elimination graph removes and joins its remaining neighbors into a clique. The fill-path criterion for symmetric elimination extends this local rule across several steps. The elimination tree organizes the resulting dependencies; the minimum degree algorithm and nested dissection choose orderings to control them.
This connection between graphs and linear systems was already explicit in Donald J. Rose, R. Endre Tarjan and George S. Lueker's 1976 study of fill-in and perfect elimination orderings.[ref]
Algorithmic Aspects of Vertex Elimination on Graphs by Donald J. Rose and others. Abstract: symmetric positive-definite systems, fill calculation for a prescribed ordering, and algorithms for special orderings; publication information, June 1976
Take a star graph with center and four leaves . Let be its Laplacian matrix and the identity matrix. In the order , the original example isFor a nonzero vector , its quadratic form isThus is a symmetric positive-definite matrix and either ordering below admits a Cholesky decomposition. Changing the ordering changes the work, rather than the mathematical solvability.
Center first. Eliminating with pivot element leaves the Schur complementEvery pair of leaves now has coupling : six new edges, hence six undirected fill-in positions. The four remaining vertices form a clique. In the Cholesky decomposition, the first column has and . The rest of the lower triangular matrix is dense. To check that later cancellation does not remove its entries, after leaves have also been eliminated, the active leaf block isIndeed a leaf step sends to . All active off-diagonal entries remain negative. The successive pivot elements in ordinary symmetric Gaussian elimination, equivalently the squared diagonals in the Cholesky decomposition, areThe Cholesky decomposition therefore stores nonzero entries, including its diagonal.
Leaves first. Permute to . Each leaf has only one remaining neighbor, so its elimination changes only the center's diagonal, reducing it by . The successive pivot elements are , and the exact Cholesky decomposition isThere is no fill-in, and only nonzero entries in . This is a concrete instance of leaf elimination of a tree-pattern positive-definite matrix; its general proof explains why the same idea works on every tree pattern. The minimum degree algorithm also chooses a leaf at every nontrivial stage of this particular example, but that success gives no general optimality guarantee.
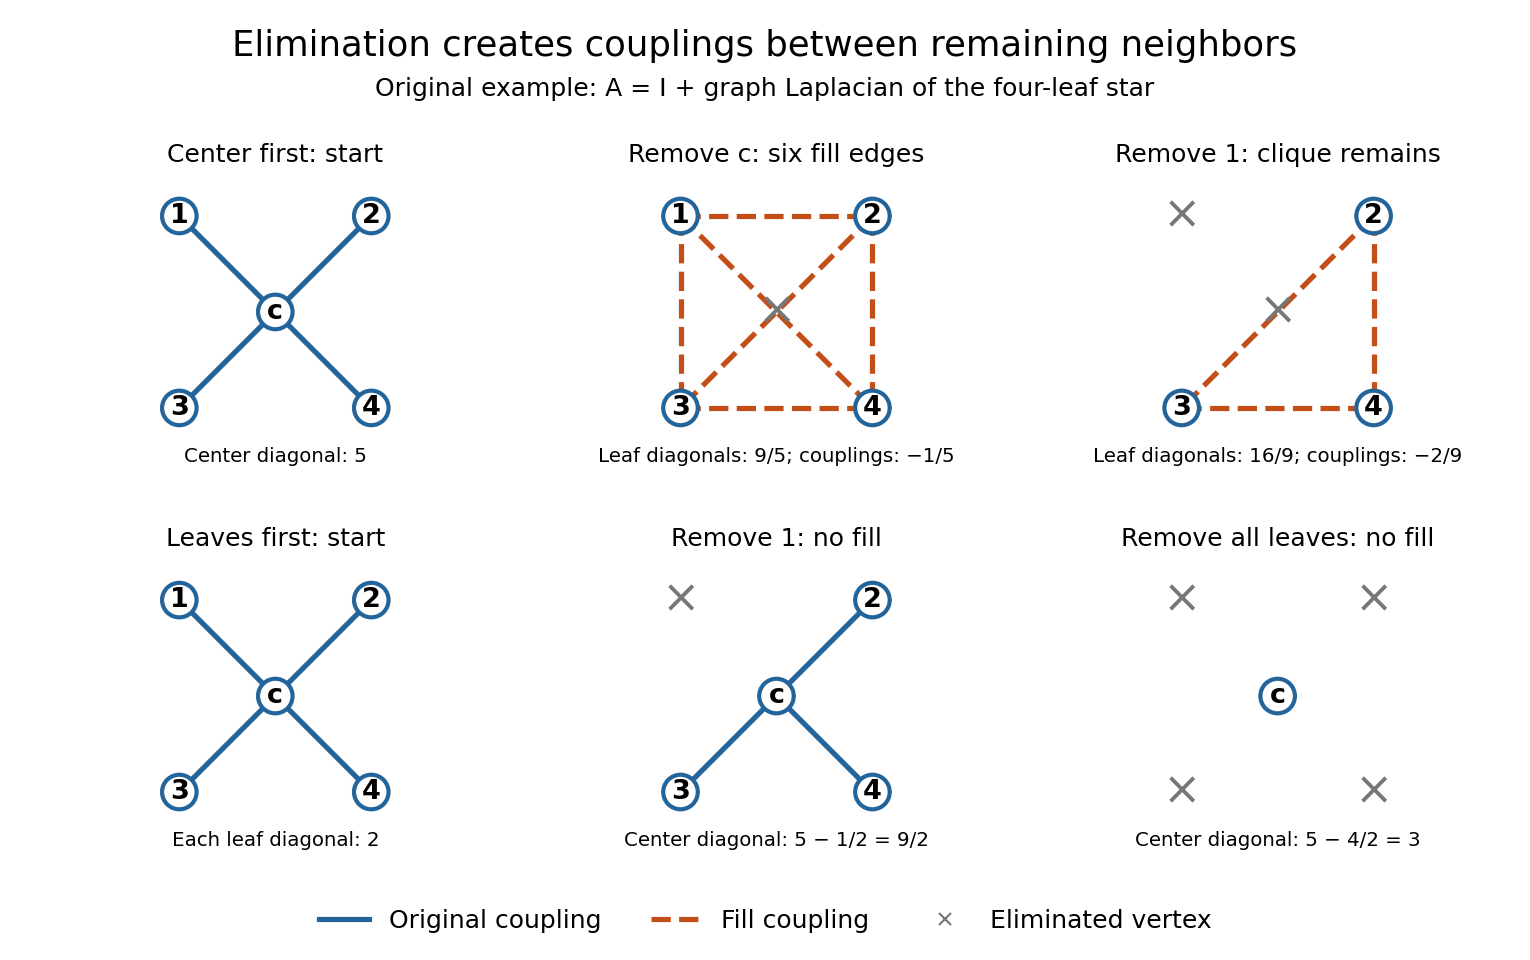
Eliminating the center of a four-leaf star graph creates a clique; eliminating leaves creates no fill-in
. Details. 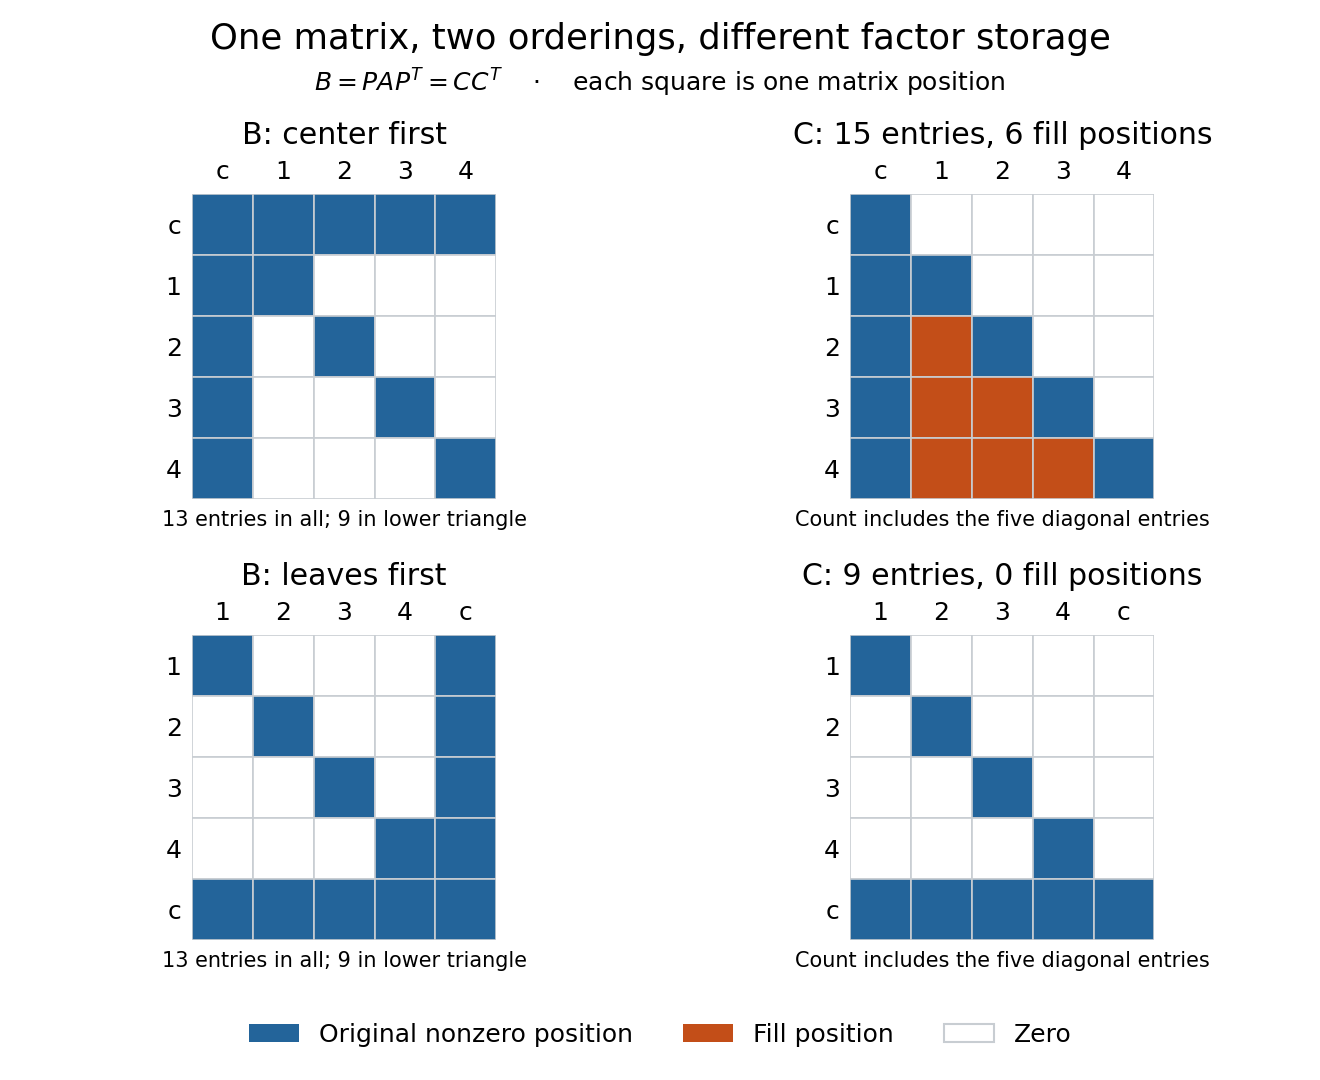
The same symmetric positive-definite matrix has 15 or nine nonzero Cholesky decomposition factor entries, depending on its ordering
. Details. The input has 13 nonzero matrix elements when both symmetric halves are counted, or nine in its lower triangle. The six added undirected edges correspond to six added positions in one triangular factor, or 12 positions if both symmetric halves of the filled pattern are displayed. Comparing all 13 input entries directly with the 15 entries of would mix counting conventions.
Associate an undirected graph with a symmetric matrix's off-diagonal nonzero pattern. Eliminating vertex updates the remaining matrix by . Only pairs of neighbors of can acquire fill-in. If the graph is a tree, remove leaves successively: each eliminated vertex has at most one remaining neighbor, so only a diagonal entry can change. Every Schur complement of a positive-definite matrix is positive definite, so no zero pivot forces a different ordering. Leaf removal therefore constructs a perfect elimination ordering and a fill-free factorization.
Symbolic factorization computes possible nonzero positions and update dependencies from a sparse matrix pattern and ordering before calculating numerical factor values. The elimination graph predicts fill and the elimination tree organizes dependencies. Numerical pivoting or exceptional cancellation can make the computed factor pattern differ from this structural prediction.
For a symmetric factorization in a fixed ordering, the elimination tree assigns the displayed parent to a column of the lower-triangular factor when that set is nonempty. A column with no later entry is a root. The tree records dependencies of descendant updates on later pivots, supports symbolic factor allocation, and exposes parallel subtrees. It describes the factorization ordering, not merely a spanning tree of the original matrix graph.
A vertex separator divides the remaining unknowns into disconnected subdomains. Nested dissection recursively eliminates each subdomain before its separator, keeping interaction localized until late in the factorization. For a regular two-dimensional mesh with unknowns, separators have size ; the resulting direct factorization uses work and storage under the usual geometric separator assumptions.
At each step choose a remaining vertex of minimum degree in the current elimination graph. This heuristic reduces the size of the immediate Schur complement update and often reduces fill-in, but does not guarantee a globally optimal ordering. Its degrees must reflect earlier fill, rather than just the original graph.
Fill-in consists of new nonzero positions created by Gaussian elimination, absent from the original sparse matrix in the same ordering. For a Cholesky decomposition , compare with the lower triangle of , not with the unpermuted input. Each new undirected edge of the elimination graph contributes one structural position in . The sparse elimination of a four-leaf star gives six such positions when the center is eliminated first, and none when the leaves are eliminated first.
Symbolic factorization predicts possible nonzeros from the pattern alone. An initially zero becomes nonzero in a single scalar step if both and are nonzero; however, at later steps several contributions can cancel. For an exact example, letEliminate indices in that order. The first Schur complement, in order , isThe second pivot element updates the entry to . The remaining block is , so all four pivot elements are positive and is a symmetric positive-definite matrix. The elimination graph retains the structural edge , but this exact choice of coefficients makes the numerical entry vanish. A small change to generally removes the cancellation.
Such an exact zero is different from discarding a small value computed with floating-point arithmetic. The symbolic factorization deliberately reserves space for possible entries without depending on special numerical identities. A perfect elimination ordering creates no structural fill-in at all; an ordering with cancellations need not have that property.
For a symmetric sparse matrix, its matrix graph has one vertex per unknown and an edge whenever the off-diagonal entry is structurally nonzero. Simultaneous row and column permutation relabels this graph. Nonsymmetric patterns are instead represented by directed or bipartite graphs when row and column roles must be distinguished.
One step of symmetric Gaussian elimination removes the pivot vertex and connects its remaining neighbors into a clique. The rule follows from the Schur complement update . Repeating it predicts the generic factor sparsity; exceptional numerical cancellations can remove structurally predicted entries.
After eliminating a vertex set , a generic edge between remaining vertices exists exactly when the original matrix graph contains a path from to whose internal vertices all belong to . Inductively, the new edges at pivot concatenate two such paths through ; conversely split any allowed path at , or retain it when it avoids . This characterizes fill by graph reachability.
At each step of Gaussian elimination, select the largest absolute entry in the uneliminated part of the current column and interchange rows to put it on the diagonal. A nonsingular trailing Schur complement has a nonzero entry in its first column, so this procedure always finds a nonzero pivot in exact arithmetic. The permutation matrix records row interchanges; earlier multipliers must be interchanged too when assembling the lower-triangular factor. This yields the LU decomposition with unit diagonal in . Searching within columns and interchanging rows is distinct from interchanging columns.
A nonzero pivot element can still be a poor numerical choice. Partial pivoting bounds the absolute values of the elimination multipliers by one in exact arithmetic, because each numerator is no larger than the selected denominator. This usually improves numerical stability, but does not prevent every possible growth of intermediate entries or guarantee accurate answers for every linear system.[ref]
2.6 Row pivoting. Fundamentals of Numerical Computation by Tobin A. Driscoll and others; §2.6.4, Example 2.6.6, equation (2.6.3) and concluding discussion: small-pivot instability and the limits of pivoting
To see the mechanism without depending on hardware, define a toy floating-point arithmetic model. The operator rounds an exact real number to the nearest value with three significant decimal digits; halfway cases choose the even final digit, and . Allow an unbounded exponent range. Round the inputs and the result of every addition, subtraction, multiplication and division separately; a product followed by a subtraction rounds twice. This is a prescribed arithmetic model, not a measurement of a physical computer. All inputs in the following original example are represented exactly:Without a row interchange, the elimination multiplier is . The last coefficient and right-hand side becomeTwo distinct exact values now have the same rounded representation. Back substitution therefore returnsThe small difference carrying information about was lost during elimination; the final subtraction only exposes that loss. Dividing by the tiny pivot element amplifies sensitivity to the lost information.
With partial pivoting, interchange the two rows, including their right-hand sides, to start from . Now , and the rounded updates areBack substitution gives and . Both paths round intermediate values, but only the first creates million-sized entries and then divides a lost difference by .
The true solution follows from the original second equation :Evaluate the linear-system residual against the original data in exact arithmetic, separately from the three-digit solve. With , the maximum norm, the results areThe respective relative linear-system residuals are and . Computing the diagnostic in higher precision matters: a check made only against the rounded reduced equations would miss the original error.
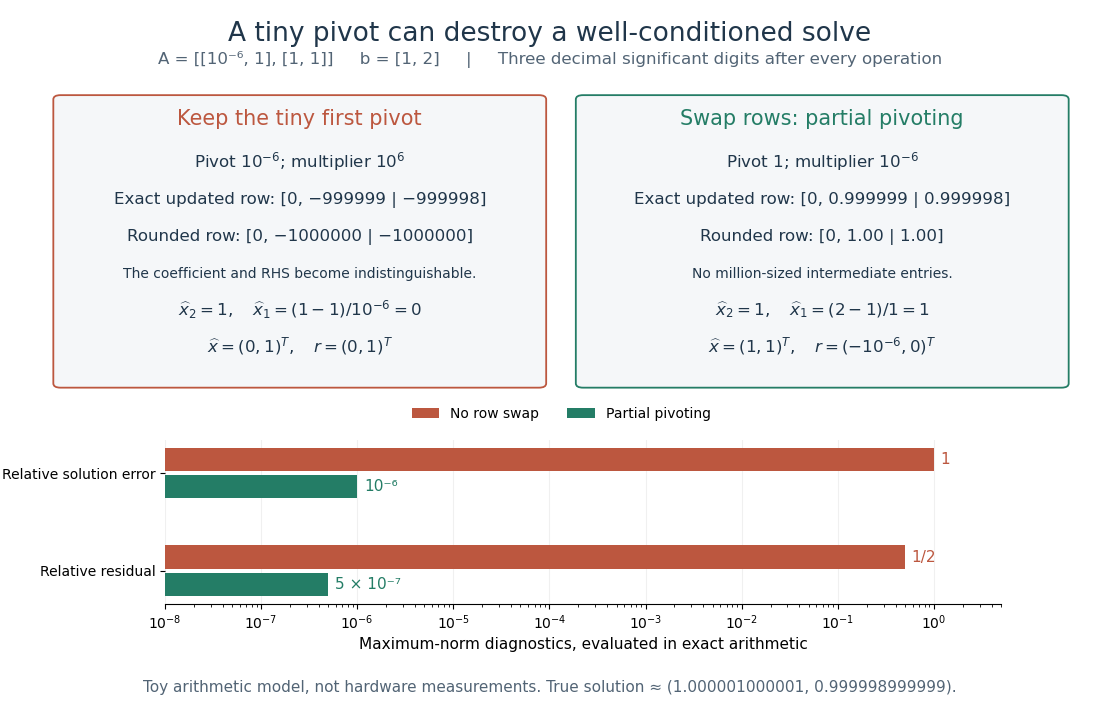
The same three-digit floating-point arithmetic model gives without a row interchange and with partial pivoting; exact linear-system residuals expose the difference
. Details. This matrix is well conditioned in the maximum norm: its induced matrix norm is , whileThe failure therefore belongs to this unpivoted algorithm, rather than a large condition number. In general, however, partial pivoting cannot remove sensitivity inherent in the data. For any approximate solution of an invertible matrix system, ; the induced matrix norm inequality and giveA small linear-system residual controls solution error only in conjunction with the condition number; numerical stability and sensitivity are different questions.[ref]
A matrix over a field is in row echelon form when all zero rows follow the nonzero rows, each nonzero row's first nonzero entry lies strictly to the right of the preceding row's first nonzero entry, and all entries below each such leading entry vanish. These leading entries are its pivot elements. They need not be one, and entries above them need not vanish.[ref]
Row Reduction. Interactive Linear Algebra by Dan Margalit and others; §1.2.2, Echelon Forms: three echelon conditions and definition of a pivot
The staircase turns a linear system into a sequence of simpler equations. For example,is in row echelon form, with pivot columns 1 and 2. Its second equation determines once is chosen; its first then determines by back substitution. It is not in reduced row echelon form, because the second pivot column contains a nonzero entry above its pivot element. Neither being square nor having a nonzero entry in every row is required.
Elementary row operations bring every matrix to row echelon form: choose a nonzero entry in the leftmost available nonzero column, interchange rows, clear entries below it, and repeat on the remaining rows and later columns. Skip columns with no remaining nonzero entry. Clearing above each pivot element and scaling it to one completes reduced row echelon form.[ref]
Row Reduction. Interactive Linear Algebra by Dan Margalit and others; §1.2.3, The Row Reduction Algorithm, forward steps and Last Step
The nonzero rows of an row echelon form are linearly independent: in a vanishing linear combination, inspecting the first pivot column forces the first coefficient to be zero, then the next forces the second, and so on. They give a basis of the original row space. The number of pivot elements is both the row rank and the column rank. To recover a basis of the original column space, select the corresponding original pivot columns; the reduced column vectors generally belong to a different column space.
Here the arithmetic is exact in the specified field. For floating-point arithmetic, deciding whether a computed entry counts as zero requires a numerical criterion; see Tiny-pivot roundoff in Gaussian elimination and condition number. An exact row echelon form classification alone does not settle numerical stability.
Two matrices of the same size over the same field are row-equivalent matrices if a sequence of elementary row operations transforms one into the other.[ref]
Row Reduction. Interactive Linear Algebra by Dan Margalit and others; §1.2.1, definition of row equivalence
Every operation is reversible, so they have the same row space and the same column linear relations. Writing the entire sequence as multiplication by an invertible matrix gives andThus the kernel is preserved. For a nonzero right-hand side, perform every operation on the whole augmented matrix : changing the coefficients while keeping fixed generally changes the solutions. The column space instead transforms to , which need not equal .Work over the rational numbers, allowing unknowns in the real numbers when interpreting the geometry. Consider four equations in three unknowns:The third row of is the sum of its first two rows, and the fourth is their difference, second minus first. The same relations must hold on the right: consistency requires and . The latter condition already holds. Gaussian elimination makes this compatibility test explicit while exposing the remaining freedom.
Apply the elementary row operations in this order, using each row's current value:then and . The resulting augmented matrix is in row echelon form for every :When , the third row has its pivot element in the augmented column. It says , so the linear system has no solution. When , that entire row vanishes and only two pivot elements remain. More equations than unknowns therefore do not force a unique solution: some equations may repeat information.
The final operation reduces the coefficient block toThe product of all six elementary matrices isDirect matrix multiplication verifies both displayed transformations. Its determinant is one, so this transformation is reversible. In particular, the third row of extracts the discrepancy between the third equation and the sum of the first two.
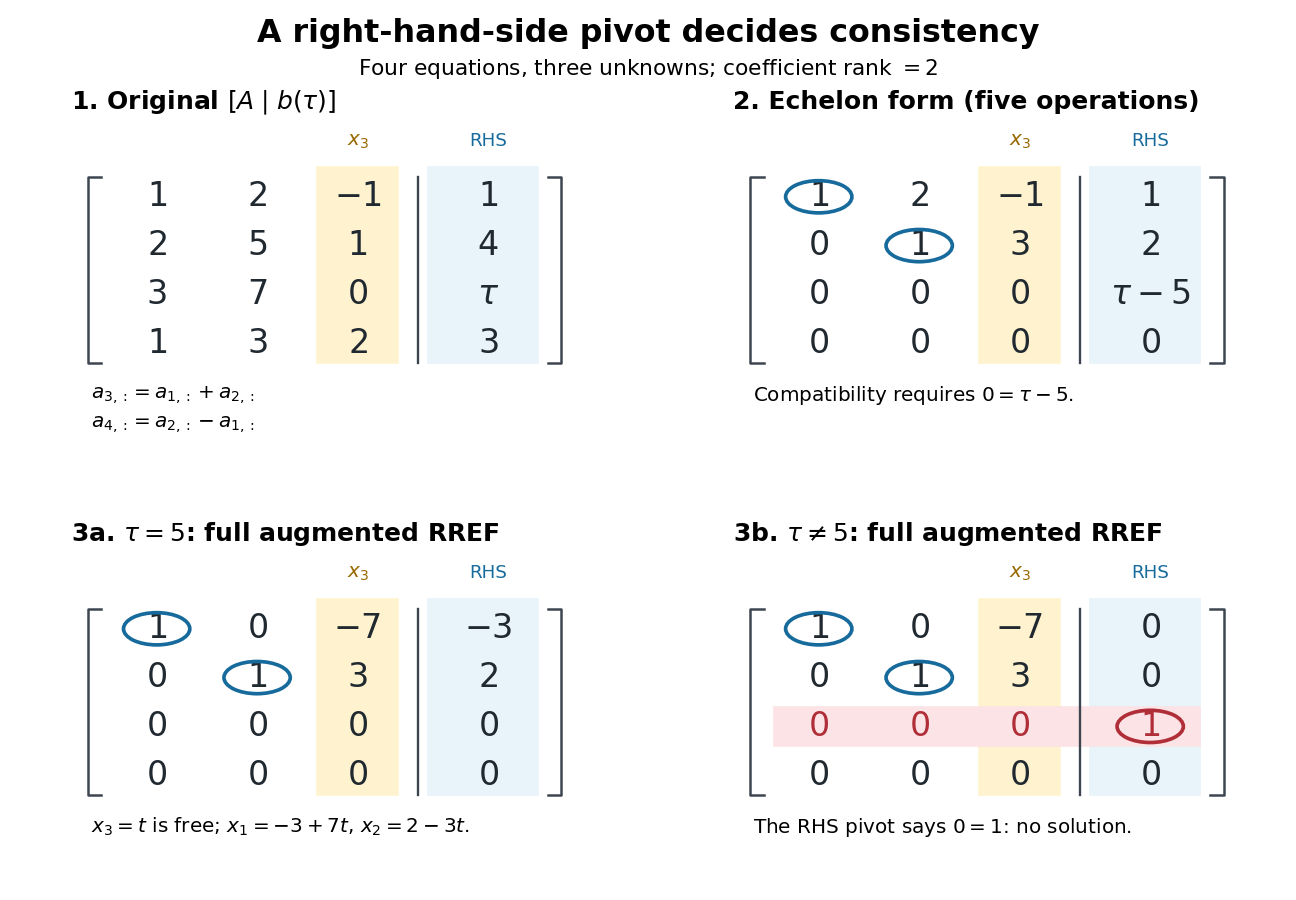
Row echelon form exposes compatibility; a right-hand-side pivot element distinguishes inconsistency from a free variable in a linear system
. Details. For , is the reduced row echelon form of the full augmented matrix. For , only its coefficient block is reduced: scale the third row by and clear the entries above its augmented pivot element. The full reduced row echelon form is thenThe last column is part of the matrix when testing the echelon conditions. Calling fully reduced before clearing that column would miss this distinction.
A row echelon form is in reduced row echelon form when every pivot element is one and is the only nonzero entry in its column.[ref]
Row Reduction. Interactive Linear Algebra by Dan Margalit and others; §1.2.2, reduced echelon conditions 4 and 5
This extra reduction displays each pivot unknown directly in terms of the free variables in a linear system. The zero matrix also satisfies the definition: it has no pivot elements.Every matrix has exactly one reduced row echelon form under elementary row operations, with its size and column order held fixed.[ref]
Row Reduction. Interactive Linear Algebra by Dan Margalit and others; §1.2.3, theorem preceding the Row Reduction Algorithm
Ordinary row echelon form is not unique: multiplying a nonzero row by two over the rational numbers keeps the staircase but changes the matrix. The reduced conditions remove that freedom.For a fixed number of columns, each row space has a unique reduced matrix after zero rows are removed; at a fixed full size, the number of appended zero rows is also determined. Thus reduced row echelon form represents a vector subspace independently of the starting basis. This is the uniqueness used by Gaussian binomial coefficients to count vector subspaces over a finite field.
The fixed column order matters. Elementary column operations can change the row space, the kernel and the resulting reduced row echelon form. For instance, swapping the columns of over the rational numbers gives , whose reduced row echelon form is instead of . When solving a linear system, a column interchange also requires tracking the corresponding interchange of unknowns.
For row reduction with a parameterized right-hand side at , the nonzero reduced equations areColumn 3 has no pivot element, so is a free variable in a linear system. Taking gives every solution:There is no further restriction on . Independent substitution into the original linear system givesConversely, the two reduced equations force exactly these coordinate formulas, so no solutions have been omitted. The same computation with zero right-hand side gives the kernel . Its dimension is one. The rank-nullity theorem appears here as : two pivot columns and one freely chosen coordinate account for the three unknowns.[ref]
The Rank Theorem. Interactive Linear Algebra by Dan Margalit and others; §2.9, Rank Theorem and preceding pivot-column/free-variable count
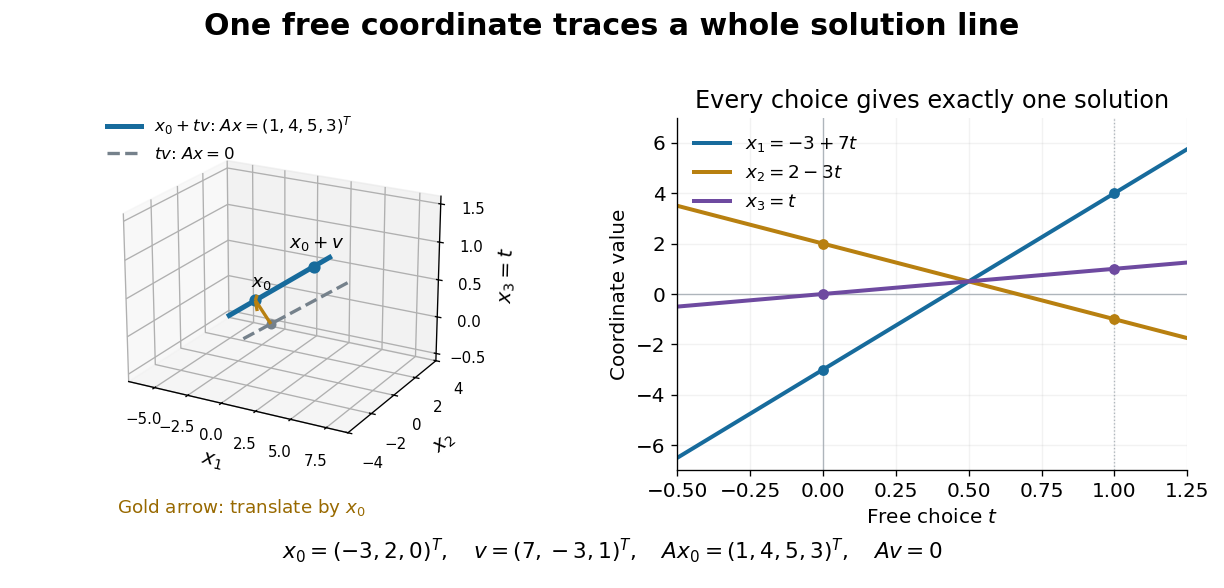
One free variable in a linear system traces an affine solution space of a linear equation parallel to its kernel
. Details. In general a consistent linear system has solution set . Subtracting from proves this description in both directions. The particular solution places the affine subspace, and the kernel supplies its directions.[ref]
Solution Sets. Interactive Linear Algebra by Dan Margalit and others; §2.4.2, Key Observation and its proof: translate homogeneous solutions by any particular solution
Over the real numbers this example is an entire line; over the rational numbers the same formula uses rational . A free variable in a linear system over a finite field instead has only finitely many choices.The pivot columns identify a different object: the original column space. Here they selectwhich form its basis, while . The corresponding reduced columns are and ; their linear span is a different plane. For example, every original output satisfies , but does not. Since is an invertible matrix, column linear relations survive even though the output vectors move. This is why choosing original columns at the reduced pivot positions works.
Here is a short proof that uses only the row space. For a vector subspace , let be the dimension of its projection map onto the first coordinates, with . In any reduced row echelon form with row space , counts the pivot columns among those first columns: later-pivot rows project to zero, while earlier-pivot rows remain linearly independent. Thus the positions where determine all pivot positions from alone.
If those positions are , the map sending to is an isomorphism : the reduced nonzero rows map to the standard basis. Its th row is therefore the unique vector of with pivot-coordinate values equal to the th standard basis vector. Any other reduced row echelon form with that row space has identical nonzero rows in identical order. At a fixed matrix size, the remaining rows must be zero. Together with existence by Gaussian elimination, this proves uniqueness.
An elementary row operation interchanges two rows of a matrix, multiplies one row by a nonzero scalar, or adds a scalar multiple of another row to it. These invertible operations are used in Gaussian elimination. For a square matrix, interchange changes the sign of its determinant, multiplication scales its determinant by the same scalar, and adding another row leaves its determinant unchanged, by multilinearity and alternation.
Exchanging two rows of a matrix. It is its own inverse and changes the sign of the determinant of a square matrix.
An elementary matrix is obtained by applying one elementary row operation to the identity matrix. Multiplying by it on the left performs the same row operation on . Such a matrix is invertible: reverse a row swap, reverse a nonzero row scaling by its reciprocal, or reverse adding a multiple of another row by adding its negative. Right multiplication gives an elementary column operation. In particular these operations preserve matrix rank.
Every invertible square matrix is a product of elementary matrices. Gaussian elimination reduces to the identity matrix by elementary row operations, giving . Reverse their order and invert them to write . Each inverse is again elementary. Conversely every elementary matrix is invertible, so every such product is invertible. The identity may be represented by the empty product.
An LU decomposition writes a square matrix as , with a lower triangular matrix and an upper triangular matrix. We use a unit triangular matrix , meaning . The factors record Gaussian elimination: contains the reduced equations, while stores the elimination multipliers needed to reconstruct the original equations. This makes Reusing LU factors for multiple right-hand sides inexpensive.[ref]
For an invertible matrix, unpivoted LU decomposition requires nonzero pivot elements at every elimination step; invertibility alone does not guarantee this. In general use Pivoted LU decomposition, with the explicit convention and a permutation matrix . Once the factors exist, solving a linear system needs forward substitution followed by back substitution, rather than forming a matrix inverse.
A matrix factorization incorporating a permutation matrix, a unit lower triangular matrix and an upper triangular matrix. The convention differs from by replacing with its inverse. When pivoting during elimination, previously stored lower-triangular multipliers must be permuted consistently with the rows.
Here is an original example of Gaussian elimination that can be checked entirely with integers. Start withThe first pivot element is . The elimination multipliers are and . Apply the elementary row operations and to obtainNow the second pivot element is , and . The elementary row operation givesImportantly, comes from the current reduced matrix, not the original entry . To reconstruct from , its second row is twice the first row of plus the second; its third row is minus the first row of plus three times the second plus the third. These are exactly the coefficients in the lower triangular matrix .
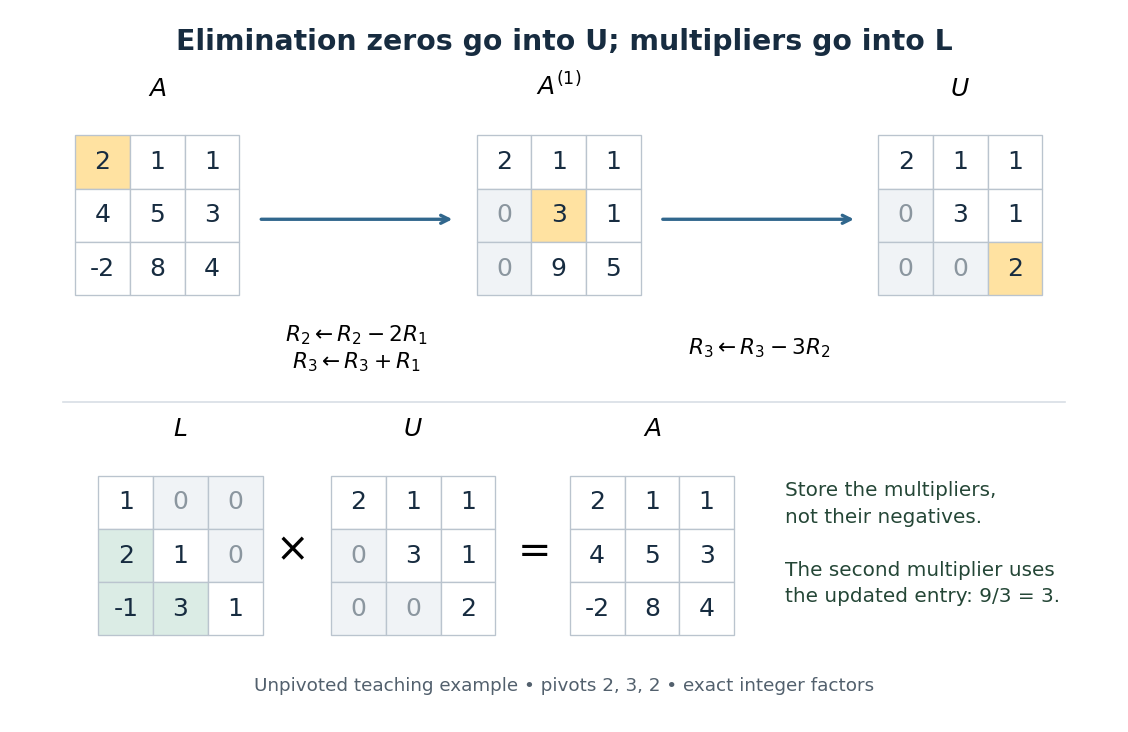
Gaussian elimination turns a three-by-three matrix into an upper triangular matrix, while elimination multipliers are stored in a lower triangular matrix
. Details. The unpivoted calculation here illustrates the structure of LU decomposition; applying partial pivoting to this particular would choose a different first row and different factors. Both procedures can represent the same linear system when their permutation matrices are handled consistently.
A unit triangular matrix is a triangular matrix whose diagonal entries are all one. It is an invertible matrix with determinant one. In the convention used for LU decomposition, is a unit lower triangular matrix, so forward substitution needs no division by its diagonal entries.
Given Pivoted LU decomposition , the linear system is equivalent to . Introduce the intermediate vector : first use forward substitution to solve , then back substitution to solve . With unpivoted LU decomposition, is the identity matrix, so the first right-hand side is simply .[ref]
For the factors in Computed three-by-three LU decomposition and , forward substitution givesThen back substitution givesDirect matrix multiplication verifies . More generally, the back substitution recurrence isThe direction matters: the last row contains only , whereas the first row generally involves every unknown. No dense matrix inverse is needed for either triangular solve.
Forward substitution solves a linear system with a lower triangular matrix and nonzero diagonal, from the first row downward:The first sum is empty, so . Each subsequent row uses only components already found. For a unit triangular matrix , omit the division because . The complementary procedure, back substitution, solves an upper triangular matrix system from the last row upward.[ref]
We fix the convention : the permutation matrix acts on the rows of , and the same row ordering must be applied to before the Triangular solves for LU decomposition. Equivalently, , since . LAPACK documents its factors as instead, so check the defining equation rather than just the letter .[ref] Partial pivoting selects the largest absolute candidate in the current column, among rows , before forming elimination multipliers.[ref]
Fundamentals of Numerical Computation by Tobin A. Driscoll and others. §2.6.1, Definition 2.6.1; §2.6.2, Definition 2.6.2 and equation (2.6.1): pivot selection and reordered-row factorization
A zero first pivot element does not imply a singular matrix. For example,Unpivoted Gaussian elimination would divide by zero. Indeed, no with a unit lower triangular matrix exists: would force , contradicting . One row interchange resolves the obstruction. For , use ; back substitution then gives . Using the original with these factors would solve a different linear system.
Partial pivoting bounds each elimination multiplier by one in absolute value in exact arithmetic. This helps control roundoff error, but intermediate entries can still grow; it is not an unconditional guarantee of numerical stability for every matrix.[ref]
Fundamentals of Numerical Computation by Tobin A. Driscoll and others. §2.6.4, Example 2.6.6 and the concluding discussion: stability of unpivoted and pivoted factorization
It also does not remove the original problem's condition number. For the diagonal matrix with , the condition number in the Euclidean norm is . Row permutations preserve this condition number, because they preserve Euclidean norms. Even an exact solve changes from to when the right-hand side changes from to . This sensitivity is a property of the linear system, not a zero-pivot element failure.[ref]For a permutation matrix and elimination matrices , put . Cancellation of adjacent gives . If the and their inverses are lower triangular, then with and . Lower triangularity needs checking: an arbitrary permutation does not preserve it.
When a fixed matrix is used with several forcing or measurement vectors, compute its Pivoted LU decomposition once. Collect right-hand sides into the columns of , and the corresponding solutions into . ThenEach column undergoes the same row permutation, forward substitution and back substitution. Neither , nor depends on . This is the useful separation between preparing a linear system and applying its solution procedure repeatedly. LAPACK implements it by taking previously computed factors, permuting all right-hand sides, and performing the two triangular solves.[ref]
For the unpivoted factors in Computed three-by-three LU decomposition, takeDirect matrix multiplication checks all three identities , and . The first column reproduces the previous solve; the other two use exactly the same factors. New right-hand sides can also arrive one at a time. If changes, these stored factors generally need to be recomputed.
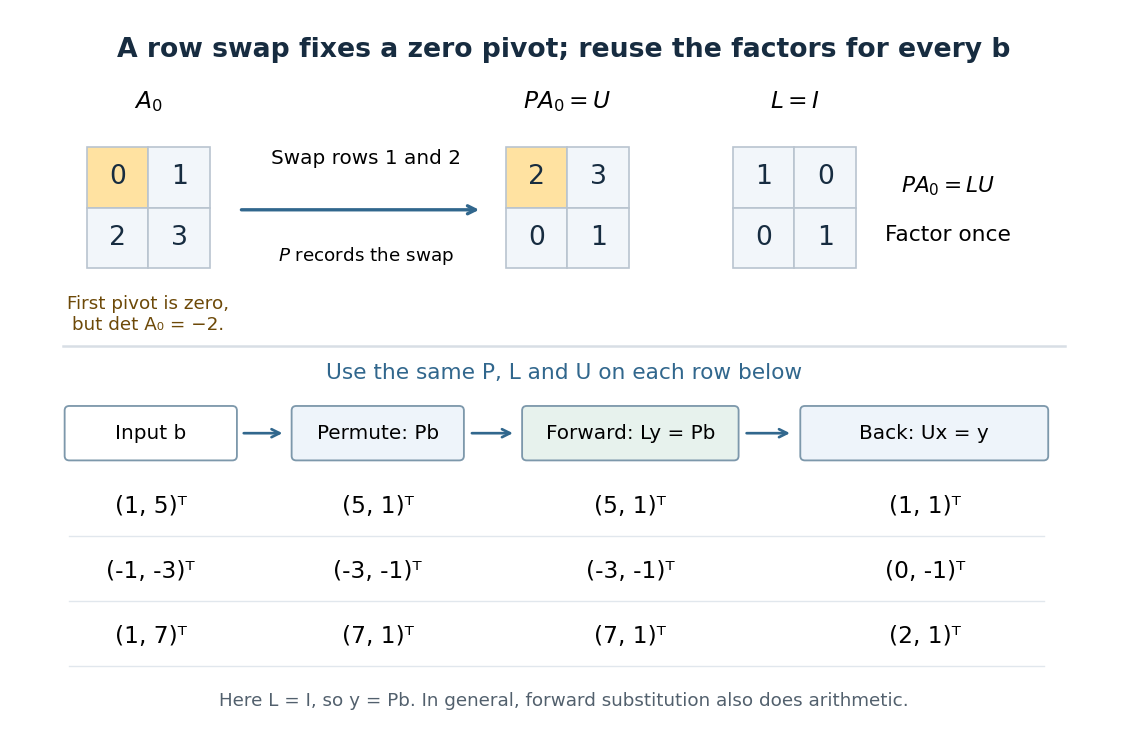
One row permutation fixes a zero pivot element; each new right-hand side reuses the same LU decomposition and two triangular solves
. Details. For classical dense Gaussian elimination over the real numbers, count each scalar addition, subtraction, multiplication or division as one arithmetic operation. At step , there are elimination multipliers to divide out and remaining entries, each requiring one multiplication and one subtraction. Thus this implementation's unpivoted factorization count isHere uses Big O notation. Partial pivoting adds comparisons and row movement, leaving the leading arithmetic count unchanged. The leading count agrees with the standard dense LU decomposition analysis.[ref]
With unit , forward substitution uses arithmetic operations. Back substitution uses another plus diagonal divisions. Together these cost per right-hand side; applying a stored row permutation moves entries and requires no scalar arithmetic. In Big O notation, Reusing LU factors for multiple right-hand sides therefore costswhereas refactorizing for each of the right-hand sides costs . For and , the leading counts are about versus arithmetic operations, nearly a tenfold saving. These are operation counts, not measured runtimes: memory access and optimized matrix multiplication also affect speed.[ref]
Fundamentals of Numerical Computation by Tobin A. Driscoll and others. §2.5.2, Important note after Definition 2.5.2: flop counts are a rough runtime model; the numerical comparison here is an original calculation
An LDL decomposition of a real symmetric matrix iswhere is unit lower triangular and is diagonal. Symmetric elimination computes it one Schur complement at a time. The matrix is positive definite exactly when every diagonal pivot in is positive.
For an approximate eigenpair , the residual is
For a real symmetric matrix , real and nonzero vector , some eigenvalue of lies within the stated ratio of . In an orthonormal eigenbasis, write and . Then , proving the bound.
If , the smallest operator-norm perturbation that makes an exact eigenpair has norm . One such rank-one perturbation is
Successive Householder reflections zero subdiagonal column entries and factor a matrix into an orthogonal factor and an upper-triangular factor.
For full column rank , a full QR factorization gives with invertible upper triangular . The equation is consistent exactly when the final entries of vanish. If consistent, back substitution gives its unique solution. This separates consistency from uniqueness in overdetermined systems.
Orthogonal Householder similarities reduce a real symmetric matrix to symmetric tridiagonal form.
An orthogonal similarity preserves skew symmetry, so upper-Hessenberg reduction of a real skew-symmetric matrix is automatically tridiagonal with zero diagonal. For a Householder reflection, the scalar vanishes, eliminating the fourth term of the general similarity update. Storing only one triangle and using the displayed skew rank-two update costs scalar products, the same leading product count as optimized symmetric tridiagonalization; the simplification saves lower-order work.
The unshifted QR algorithm factors and forms , preserving eigenvalues while driving the matrix toward block diagonal form.
This is the zero-shift case of the QR algorithm.
LetThenThus is a QR decomposition of the matrix power . In particular, the first columns of span the same subspace as the first columns of whenever those columns are independent.
An unshifted QR step preserves the bandwidth of a real symmetric banded matrix. A Givens-rotation implementation exposes this as bulges created during triangularization and removed when the factors are multiplied in reverse order.
The accumulated orthogonal factor in QR iteration is the factor of a matrix power, so its leading columns span the same spaces as simultaneous power iteration.
Let a real symmetric matrix have an orthonormal eigenbasis , withWrite two starting vectors asFor two-column subspace iteration to recover
, the two projections onto that dominant subspace must be independent. The exact condition isRequiring each of the four coefficients to be nonzero does not imply this determinant condition.
, the two projections onto that dominant subspace must be independent. The exact condition isRequiring each of the four coefficients to be nonzero does not imply this determinant condition.
When an off-block subdiagonal entry tends to zero, QR iteration asymptotically separates the corresponding invariant spectral blocks even if eigenvalues within one block have equal modulus.
A stationary iteration has the formwith a fixed iteration matrix . It converges for every initial vector exactly when the spectral radius satisfies .
This is an iterative method whose update matrix remains fixed.
Suppose has a fixed point and with diagonal . For and , subtraction gives . In the Euclidean norm,Thus . Spectral radius below one implies convergence for every start. The unit-constant bound belongs to the transformed coordinates; it does not automatically hold in the original Euclidean norm when is nonorthogonal.
The periodic second-difference circulant matrix has constant null space, so solvability requires . Its Jacobi method has eigenvalues : for odd it converges to some solution, while for even an alternating mode oscillates unless absent from the error. Lexicographic Gauss-Seidel iteration converges to some solution for every compatible right-hand side and every initial vector. For , a coordinate sweep decreases the energy by the sum of squared coordinate changes. This excludes all nonconstant unit-modulus eigenmodes. The constant unit eigenvalue is simple, since the invariant left vector has . Neither method is a strict contraction to a unique solution without fixing the constant nullspace.
For a real symmetric positive definite matrix , the error in each eigenvector direction is multiplied by . Convergence from every initial vector is therefore equivalent to . At either endpoint there is a nondecaying error direction. The optimal constant parameter is , giving contraction factor .
With , the Gauss-Seidel method solves . It uses each newly computed coordinate immediately in the remaining triangular solve. It is successive over-relaxation with parameter one, and converges from every start when is a symmetric positive-definite matrix.
To solve a linear system , split its matrix into the diagonal matrix and the strictly lower and upper parts , retaining their actual signs. Every diagonal entry must be nonzero. A sweep updates coordinates in order:The Jacobi method uses the old vector throughout; the Gauss-Seidel method reuses each fresh coordinate. Thus the update order is part of the method.[ref]
Notes for Ma221 Lecture 21, Nov 10 2009. Math 221, Matrix Computations, Fall 2009; Gauss-Seidel: component loop, splitting and update-order remark, web lines 372–380
The matrix splitting has , , so its iteration matrix isCompute the update by forward substitution with the lower triangular matrix , rather than forming a matrix inverse. For a sparse matrix, a sweep only visits stored entries and can overwrite the working vector. Dependencies on fresh coordinates constrain parallel execution. This makes the Gauss-Seidel method an inexpensive solver component, including in a multigrid method.[ref]
Notes for Ma221 Lecture 21, Nov 10 2009. Math 221, Matrix Computations, Fall 2009; Basic iterative methods, cheap splitting requirement; Gauss-Seidel loop and red-black ordering; opening list of solver building blocks
For a real symmetric positive-definite matrix , let be the Gauss-Seidel method error and . Its recurrence gives . Expanding the two squared energy norms yields . Every diagonal entry of is positive, so the error energy strictly decreases unless . In that case and the exact solution has already been reached. This identity exhibits the method as a sequence of energy-reducing coordinate corrections.
Consider the original linear systemDirect substitution verifies the solution. The matrix is a symmetric positive-definite matrix: completing the square in its quadratic form gives for every nonzero vector. It is also a strictly diagonally dominant matrix.
Starting from , update the first row and then the second:The first sweep gives and . The next gives and . The second row uses during the first sweep, even though the initial first coordinate was zero.
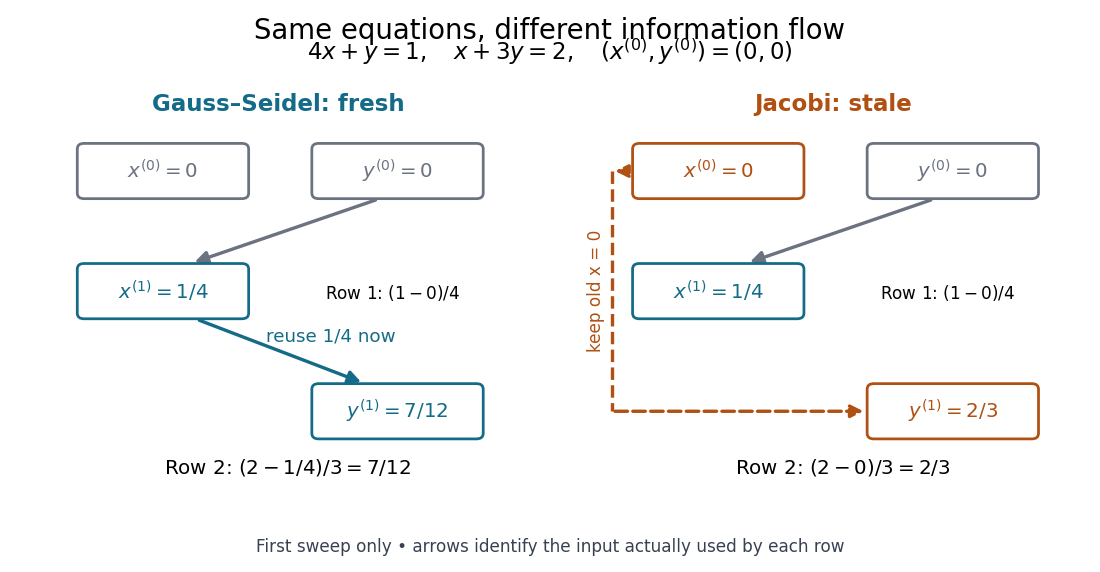
Fresh and stale inputs in the first sweep of the original two-variable linear system
. Details. With a stale first coordinate, the Jacobi method would instead give after the first sweep. Both methods have the same fixed point, but changing when coordinates become available changes the entire sequence of vectors.
For the Gauss-Seidel iteration for a two-variable positive-definite system, define the forward error by and . Subtract the two exact solution equations from the two update equations:The fresh first coordinate passes the old second-coordinate error through two successive factors. The iteration matrix is thereforeIts eigenvalues are and , as seen from the determinant. The zero eigenvalue explains why the old first-coordinate error disappears completely: the first row overwrites it. After one sweep, every remaining forward error lies on the eigenvector line spanned by .
For this zero start, , so the exact vectors for areThe Euclidean norm of the forward error decreases by exactly per sweep from onward. The first decrease is different because the initial error has not yet reached that eigenvector line. Each row update moves horizontally or vertically in the coordinate plane; sweep endpoints then approach the solution along one straight line.
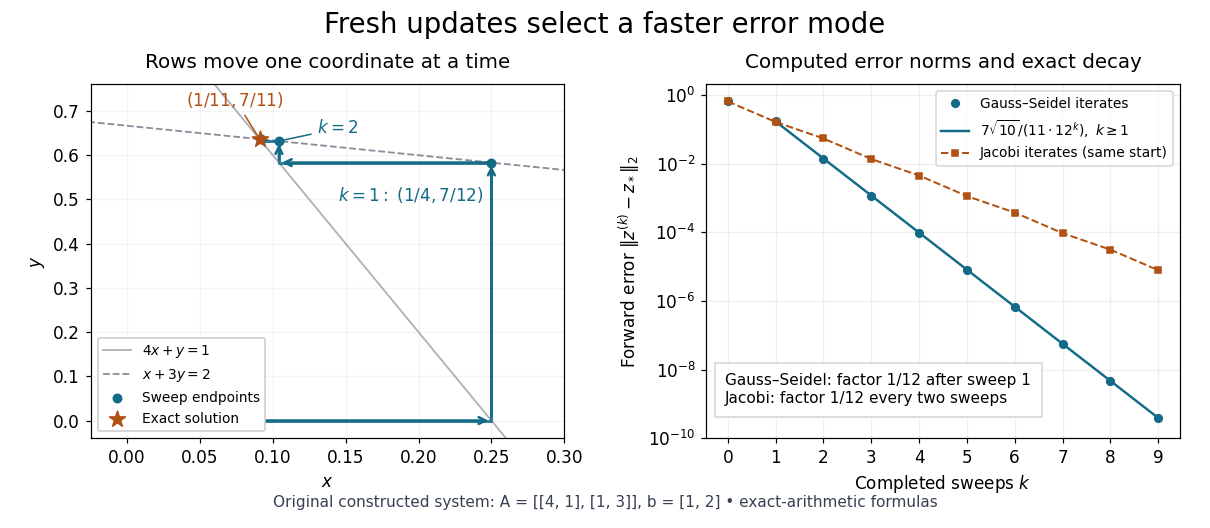
Computed row-by-row Gauss-Seidel method trajectory and exact forward error contraction for the original two-variable linear system
. Details. The linear-system residual is an independent way to check the calculation. Completing a sweep satisfies the second row exactly, but changing disturbs the first row:Thus a zero residual in the last updated row alone does not certify a solution; inspect the complete linear-system residual.
For the same matrix, the stale schedule of the Jacobi method gives the iteration matrixHere its eigenvalues are , whereas the fresh schedule gives . This comparison belongs to this particular linear system; it is not a universal relation between the two methods' spectral radii.
A strictly diagonally dominant matrix or a real symmetric positive-definite matrix guarantees convergence of the Gauss-Seidel method from every initial vector. These are sufficient conditions.[ref]
Notes for Ma221 Lecture 21, Nov 10 2009. Math 221, Matrix Computations, Fall 2009; Theorem 1, strict row diagonal dominance, web lines 462–465; Theorem 3, positive-definite SOR and its ω = 1 specialization, web lines 490–493
For strict diagonal dominance, putInduct through a sweep. Old coordinates have absolute error at most ; previously updated coordinates have absolute error at most . The component update and the triangle inequality therefore bound the new error by . This proves , a maximum norm contraction.
For a symmetric positive-definite matrix, write . The Householder-John theorem applies to and , because is a positive-definite matrix. Hence the iteration matrix has spectral radius less than one, which gives the convergence criterion for a stationary iteration.
There is also a geometric reason fresh updates help: the Gauss-Seidel method is exact coordinate descent on the convex quadratic functionHolding the other coordinates fixed, minimizing in coordinate gives the corresponding row update. A change lowers by exactly . Each fresh coordinate is therefore the minimizer for the current vector, and a complete sweep lowers the quadratic form error unless every coordinate already solves its row. This explains the method's beauty without implying monotone decrease in every vector norm.
An invertible matrix and nonzero diagonal entries make the update well defined, but do not guarantee convergence. For the original linear systemthe Gauss-Seidel method updates and . Starting at zero gives , then . The second-coordinate forward error is , and the iteration matrix has spectral radius . The linear system has a unique solution while this particular stationary iterative method for a linear system diverges.
For a splitting , successive over-relaxation updatesIt reduces to the Gauss-Seidel method at . If is symmetric positive definite, the Householder-John theorem applies to , , since is positive definite for .
Let be a real symmetric positive-definite matrix, with diagonal and strictly lower triangular. Put and for . The matrix norm induced by an energy norm reduces the question to . Direct multiplication and giveThe left side is positive semidefinite. The matrix following the scalar coefficient on the right is positive-definite, since has positive diagonal and is an invertible matrix. For , every eigenvalue of therefore lies in . Hence its spectral radius is below one and . Iteration errors consequently decay geometrically in the energy norm. The argument proves convergence from every initial vector, without requiring the original iteration matrix to be symmetric.
For a stationary iteration , the matrix propagates the error by . Convergence from every initial error is equivalent to .
For a matrix splitting , the iteration matrix is , where is the identity matrix. If , subtracting its fixed point equation from the update givesThus determines the fixed point, while determines how the forward error moves. An eigenvector with eigenvalue is an error direction whose coefficient is multiplied by on every step. A negative real eigenvalue reverses its sign; a zero eigenvalue removes that component in one step.
A stationary iterative method for a linear system converges to its specified fixed point for every initial vector if and only if its iteration matrix satisfies , where the spectral radius is the largest modulus of an eigenvalue.[ref]
Notes for Ma221 Lecture 21, Nov 10 2009. Math 221, Matrix Computations, Fall 2009; Basic iterative methods: theorem following the spectral-radius lemmas, before the Jacobi update
For a diagonalizable matrix, write . Then , so each eigenvector coefficient tends to zero exactly when its eigenvalue has modulus less than one. For a general matrix, the Jordan normal form gives the same result: a Jordan block with a nilpotent matrix of size satisfiesIf , every coefficient tends to zero because exponential decay beats any fixed polynomial in ; if , the block vanishes once . Conversely, an eigenvector with provides an initial error that cannot tend to zero. For a real matrix with complex eigenvalues, the same obstruction appears in the real invariant subspace spanned by the real and imaginary parts of an eigenvector.
The words "every initial vector" matter. For example, fails the criterion, but still tends to zero. Here a generic initial error has a nonzero first coordinate and diverges; the exceptional errors lie on the second coordinate axis. With , generic errors oscillate rather than diverge in norm, while the same exceptional axis still converges. Both are valid matrix splittings with and . In general the convergent errors form the direct sum of the generalized eigenspaces for ; if , this is a proper linear subspace.
A small spectral radius describes eventual convergence, but does not imply that the Euclidean norm of the error decreases on every step for a non-normal matrix. An operator norm bound does give the stepwise estimate . For a real symmetric matrix, the matrix 2-norm equals its spectral radius, making this particularly direct.
The linear-system residual is computable without knowing . The forward error is the actual difference from the desired solution. For an invertible matrix,Keeping fixed, the approximate vector exactly solves with . Thus, for , is the relative backward error when only the right-hand side may change. For a vector norm and its induced operator norm,A small relative linear-system residual ensures a small relative forward error when the condition number is moderate; an ill-conditioned matrix can amplify it. The bound follows directly from and .[ref]
2.8 Conditioning of linear systems. Fundamentals of Numerical Computation by Tobin A. Driscoll and others; §2.8.1, Theorem 2.8.1, equation (2.8.6), right-hand-side perturbation bound applied with Δb = −r
For the Jacobi iteration for a three-variable tridiagonal system, the first linear-system residual is , while the first forward error is . In the Euclidean norm, the relative forward error is and the relative linear-system residual is . Its spectral condition number of a positive-definite matrix is , so the bound is about . The bound is a guarantee, not an equality. In floating-point arithmetic, recompute the linear-system residual from the current vector when checking termination; a small update alone need not certify a small forward error.
A matrix splitting chooses an easy part of a matrix and corrects for the remaining part . To solve the linear system , first rewrite it as , then use the old vector on the right and solve for the new vector on the left. The matrix inverse notation describes the update mathematically; each step should solve with rather than construct its matrix inverse.[ref]
Notes for Ma221 Lecture 21, Nov 10 2009. Math 221, Matrix Computations, Fall 2009; Basic iterative methods: definition A = M − K and recurrence (*), with the two conditions for a useful splitting
The same identity also yields a correction based on the linear-system residual:This connects a matrix splitting to matrix preconditioning: rescales the imbalance before adding a correction. Choosing gives and the exact solution in one step, but requires solving the original linear system; choosing cheaply matters as much as the convergence criterion for a stationary iteration.
With the sign convention , is the diagonal matrix of diagonal entries and contain the actual lower and upper entries, without reversing their signs. The Jacobi method uses , ; the Gauss-Seidel method uses , . The first requires only division by diagonal entries; the second uses a lower triangular matrix and forward substitution. These choices explain their different information flows.
For the five-point Dirichlet Laplacian on an square grid, a block-Jacobi splitting that solves each horizontal line exactly has blocks . Its tensor-product sine modes have angles and the displayed iteration matrix eigenvalues. With , its spectral radius is , so it converges on every fixed grid. However the mode has multiplier . It is highly oscillatory between lines and is barely damped. The undamped method is therefore not a uniformly effective smoother for the multigrid method, even though it converges. Convergence and smoothing test different properties of the error spectrum.
Let be Hermitian positive definite. If is also Hermitian positive definite, then is invertible andThus the stationary iteration associated with the splitting converges from every initial vector.
The Jacobi method solves a linear system by updating every coordinate from the same old vector. It requires every diagonal entry to be nonzero. Isolating coordinate in row gives the simultaneous ruleHere is the iteration matrix. A sweep computes a complete new vector before replacing the old one, so its coordinate updates can run independently.[ref]
Notes for Ma221 Lecture 21, Nov 10 2009. Math 221, Matrix Computations, Fall 2009; Jacobi: component loop and splitting immediately before Gauss-Seidel
For a sparse matrix, a sweep needs work proportional to the stored nonzero entries, while Gaussian elimination may create fill-in. The Jacobi method is therefore a simple starting point for large linear systems, and the weighted Jacobi method supplies a useful building block of a multigrid method. Its beauty is that a local row correction becomes a global eigenvalue question: the convergence criterion for a stationary iteration is exactly .
Consider the original linear system with a symmetric matrix that is also a tridiagonal matrix:Here and the Jacobi method readsStarting from , the first three vectors areEvery right-hand side uses superscript , including the middle row, even when a new first coordinate has already been computed.
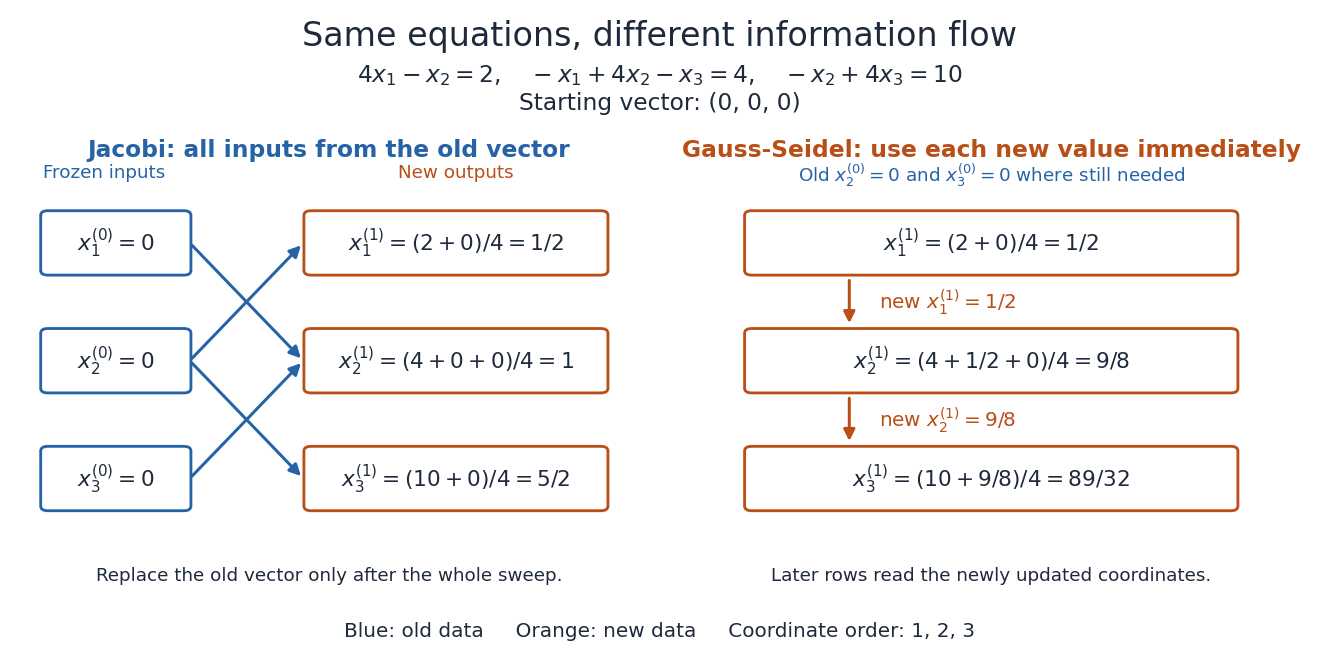
Simultaneous old-to-new component updates in the Jacobi method, compared with immediate reuse in the Gauss-Seidel method
. Details. For comparison, a first Gauss-Seidel method sweep in coordinate order givesThe new first coordinate enters the middle update, and the new second coordinate enters the final update. Accidentally overwriting old coordinates during a Jacobi method sweep therefore changes the mathematical method.
For the Jacobi iteration for a three-variable tridiagonal system,An orthonormal eigenbasis iswith eigenvalues , , and , respectively. These are error modes: their shapes persist under the iteration matrix, while their coefficients change. Direct multiplication verifies them, or expansion of the determinant gives . Thus and convergence holds for every starting vector.
With , the initial forward error has coefficientsFor ,The zero mode disappears after one sweep; the negative mode alternates in sign. The Euclidean norm drops by exactly per sweep from onward. The first norm drop is different because includes the zero mode. A starting error proportional to would disappear entirely in one sweep, faster than the spectral radius predicts for generic errors.
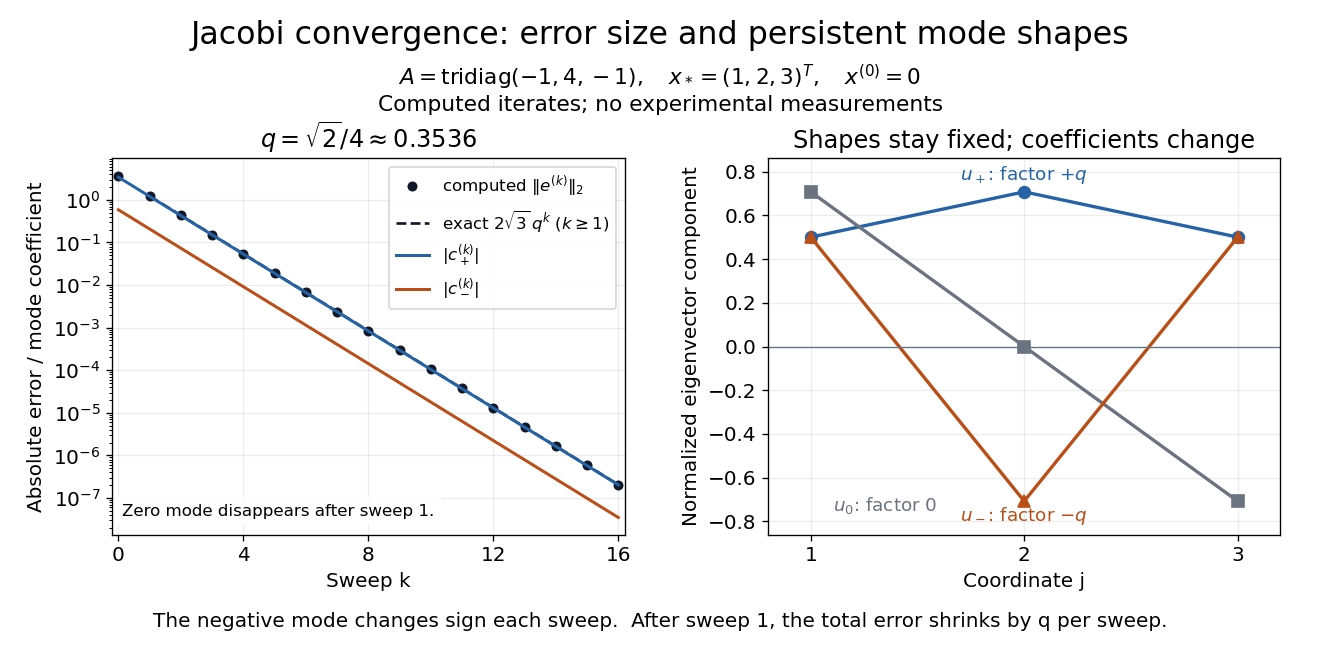
Computed Jacobi method error curves and eigenvector modes for the original three-variable tridiagonal matrix
. Details. The curves are computed iterates and exact formulas for this linear system. Since , the same eigenvectors have eigenvalues , , and for . They prove that is a positive-definite matrix, and give the condition number used in residual and forward error in a stationary iteration.
A strictly diagonally dominant matrix guarantees convergence of the Jacobi method for every initial vector.[ref]
Notes for Ma221 Lecture 21, Nov 10 2009. Math 221, Matrix Computations, Fall 2009; Theorem 1 on strict row diagonal dominance and its proof beginning “Split A = D − (D − A)”
Indeed, using the maximum norm , the induced operator norm is the largest absolute row sum. The Jacobi method has and for , soThis gives a cheap sufficient check without computing any eigenvalues. For the Jacobi iteration for a three-variable tridiagonal system, the absolute row sums of are , giving . The true spectral radius gives a sharper eventual rate.
Strict diagonal dominance is sufficient, not necessary: violates it in the first row, but its Jacobi method has eigenvalues and converges. Conversely, being a positive-definite matrix alone is insufficient: the Jacobi convergence for a three-by-three equicorrelation matrix with has positive eigenvalues for , but spectral radius for its iteration matrix. The extra tridiagonal matrix structure in Jacobi convergence for a symmetric positive-definite tridiagonal matrix is therefore substantive.
For , with the four-dimensional unit superdiagonal, the Jacobi method has eigenvalues , . The Gauss-Seidel method has two zero eigenvalues and . Therefore both methods converge for every starting vector exactly when . This equality of convergence ranges follows from their spectra, not from positive-definiteness of the nonsymmetric coefficient matrix.
Equivalently, the weighted Jacobi method takes a weighted average of the old vector and its full Jacobi method update: . If , its iteration matrix multiplies that eigenvector by . For the diagonal-4 Jacobi iteration for a three-variable tridiagonal system, the factors are and ; a Poisson equation smoothing parameter must not be inferred from this different matrix.
For the five-point discretization of on the unit square, the weighted iteration eigenvalues are . A fixed parameter converges for every mesh when , but poorly damps the highest frequencies.
For the five-point Dirichlet Poisson matrix, weighted Jacobi iteration has sine-mode multiplier . Call a mode high-frequency if at least one cosine is nonpositive. Then the sum lies in , so for the multiplier lies in . This uniform damping makes the iteration a useful smoother for a multigrid method, even though low-frequency multipliers approach one on fine grids. Balancing and shows why is the minimax parameter for this high-frequency interval. The two-dimensional high-frequency set gives a different optimum from the familiar one-dimensional value .
For the centered second-difference matrix with diagonal and off-diagonals , the weighted-Jacobi eigenvalues areThe method converges for every grid size exactly when .
Multiplying both and by leaves and the weighted Jacobi method unchanged. Thus the same formula applies to the positive second-difference matrix with diagonal and neighboring entries , the finite difference form of the one-dimensional Poisson equation with Dirichlet boundary conditions. Its eigenvectors have components , and has eigenvalues . At , upper-half modes have factors between and , while low-frequency factors remain close to one on fine grids. This explains why the weighted Jacobi method helps a multigrid method by reducing oscillatory errors, even when it is a slow solver on its own.[ref]
CS267: Supplemental Notes for Lecture 17 — How Multigrid Damps High Frequencies by James Demmel. Error eigenvector expansion, coefficient 1/3 + (2/3) cos(jπ/2^i), and concluding upper-half-frequency attenuation statement
Articles were limited to the first 100 out of 103 total.
Articles by others on the same topic



Numerical linear algebra is a branch of mathematics that focuses on the development and analysis of algorithms for solving problems in linear algebra using numerical methods. It deals with the theory and practical application of techniques for the manipulation of matrices and vectors, which are fundamental structures in many scientific computing and engineering problems.