The characteristic function of a real random variable isIt determines the probability distribution of .
Here and . By Euler's formula, its real part and imaginary part are and . The complex exponential has absolute value one, so this expected value exists for every real random variable, even without finite absolute moments. Moreover,The bound uses the triangle inequality for a vector-valued integral; the last identity is complex conjugate symmetry.[ref]
Probability: Theory and Examples (fifth edition) by Rick Durrett. §3.3.1 definition, printed p. 125; Theorem 3.3.1(a)–(c), printed p. 126
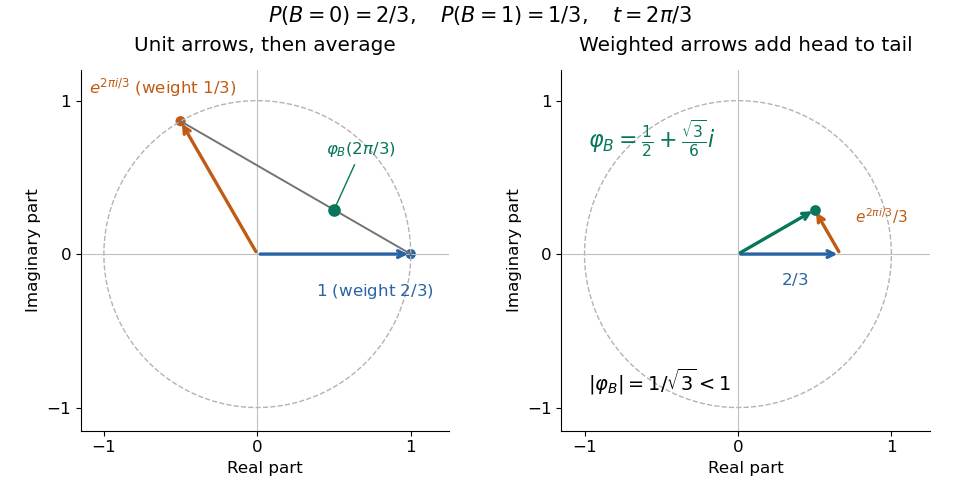
Consequently the real part is an even function and the imaginary part is an odd function.For a discrete probability distribution with values and probabilities , the characteristic function is : a weighted average of points on the unit circle in the complex plane. For example, if has the Bernoulli distribution with and , thenEach point being averaged has absolute value one, but their directions partially cancel. At , the same average is ; at , it returns to one. The characteristic function is thus neither a probability density function nor a probability mass function: its argument is a frequency parameter, and its values can be complex numbers. This Bernoulli distribution has no probability density function with respect to Lebesgue measure, yet its characteristic function is defined at every frequency.
For a probability density function , the same definition becomes , the Fourier transform with the displayed sign convention. The Laplace transform of a nonnegative random variable instead uses for , a real decaying weight. For the Bernoulli distribution above, it is ; neither transform is the probability density function. The uniqueness theorem for characteristic functions explains why the oscillating averages still retain the entire probability law, while the characteristic function of a sum of independent variables turns combining laws into multiplication. These two properties make the representation useful even when directly computing a sum's probability distribution is cumbersome.
If , the characteristic function satisfies . The bound and the dominated convergence theorem justify differentiation at zero. For mean zero, extends continuously by , and by a finite geometric series. This supplies a direct characteristic-function proof of the weak law of large numbers.
// Target: martingale.bigb
If is an integer and , the characteristic function has continuous derivatives through order , withThus finite absolute moments justify recovering moments from derivatives.[ref]
For a short justification of differentiation under the integral sign, the difference quotient for the st derivative has integrand . Its absolute value is at most , since for real . Lower absolute moments are finite because . Apply the dominated convergence theorem successively, then use the same integrable bound to obtain continuity of each derivative.
For the Bernoulli distribution with parameter , direct differentiation gives and , agreeing with . Its variance is therefore . Existence and continuity of a characteristic function alone do not authorize these moment calculations: the standard Cauchy distribution, whose expected value is undefined, still has a characteristic function. The stated finite absolute moment hypothesis is a sufficient condition for the derivative formula, not an assumption built into the definition of a characteristic function.
Average over . Multiplication by gives , with value zero at . This is at least when . Tonelli's theorem then gives the displayed bound for a probability measure with characteristic function . The bound converts control of the characteristic function near zero into tightness of probability measures and is useful in proving the Lévy continuity theorem.
For a real random variable and a sigma-algebra , the conditional characteristic function is . If it equals the nonrandom characteristic function of a probability law for every , then has that law and is independent of . To verify the independence assertion, multiply the identity by any bounded -measurable test variable and use the uniqueness theorem for characteristic functions on the resulting finite measures. Equality for rational extends by continuity, so simultaneous null sets can be arranged when needed.
For a sample , is the characteristic function of the sample's empirical measure. For independent and identically distributed random variables, and , without any moment condition on the observations.
The centered process describes fluctuations of the empirical characteristic function. At a fixed frequency, its real and imaginary parts satisfy a multivariate central limit theorem. A process-level limit requires further control over the frequency index.
Every characteristic function is uniformly continuous and satisfies and . Continuity follows from the dominated convergence theorem applied to .
More explicitly, if , then pointwise and . Apply the dominated convergence theorem to the real part and imaginary part separately. There is no finite moment hypothesis. For uniform continuity, the stronger estimatefollows by factoring out , whose absolute value is one. The integrand tends pointwise to zero and is bounded by two, so the dominated convergence theorem applies again. The bound is independent of , which supplies uniform continuity on the entire real line.[ref]
If the first absolute moment is finite, additionally gives , a Lipschitz continuity estimate. The earlier argument matters because continuity survives even when this expected value is infinite. For convergence in distribution, the separate Lévy continuity theorem concerns limits of whole sequences of characteristic functions; the argument here establishes continuity of one characteristic function.
If is irrational and , then is almost surely constant. For independent copies , both and lie in almost surely; irrationality makes the two corresponding lattices intersect only at zero, so almost surely. Two independent identically distributed variables can agree almost surely only when their common law is a point mass.
For an -valued random vector, the characteristic function is . It determines the joint distribution and satisfies for every deterministic matrix .
If , then
A random vector is orthogonally invariant when has the same distribution as for every . Its characteristic function is radial and real: for a continuous function .
If an orthogonally invariant random vector in dimension at least two has independent coordinates, then it is centered isotropic Gaussian, possibly degenerate at zero. Independence and rotational invariance givewhile continuity and imply for some . Thus .
Two finite Borel measures on with the same characteristic function are equal. One proof convolves both measures with centered Gaussians, applies Fourier inversion to the smooth densities, and then lets the Gaussian variance tend to zero.
Let be compactly supported and continuous, let , and use . If , thenThis follows by Fubini's theorem, a change of variables, Fourier inversion theorem, and dominated convergence theorem. It gives a direct proof of the uniqueness theorem for characteristic functions because the right side depends only on .
Independence makes the characteristic function of a sum equal the product of the individual characteristic functions.
For mutually independent random variables , write . ThenThis is the expectation of a product of independent random variables applied to bounded complex exponentials; no moment hypothesis is needed.[ref]
Identical probability distributions are unnecessary. When the random variables are independent and identically distributed random variables, the product is . A deterministic rescaling also follows directly from the definition: for real . Consequently the sample mean has characteristic function , and a sum divided by has characteristic function .
The independence assumption does real work. Let take and with equal probabilities and set . Both characteristic functions are , but , not . At they give and zero respectively. Knowing the two marginal probability distributions does not determine the sum without their joint probability distribution.
Let be independent random variables, each with the Bernoulli distribution of parameter , and let . Multiplying their characteristic functions and expanding by the binomial theorem givesThe coefficients are exactly the probability mass function of the binomial distribution with parameters : the sum takes with probabilities . Direct outcome counting verifies them: an outcome with ones has probability , and there are such outcomes. The coefficients sum to one, recovering .
At , . This is also : the complex exponential now records parity. The moments agree by two routes: linearity of expectation gives , while the variance of a sum of independent random variables gives . Summing gives the second moment , also recovered as .
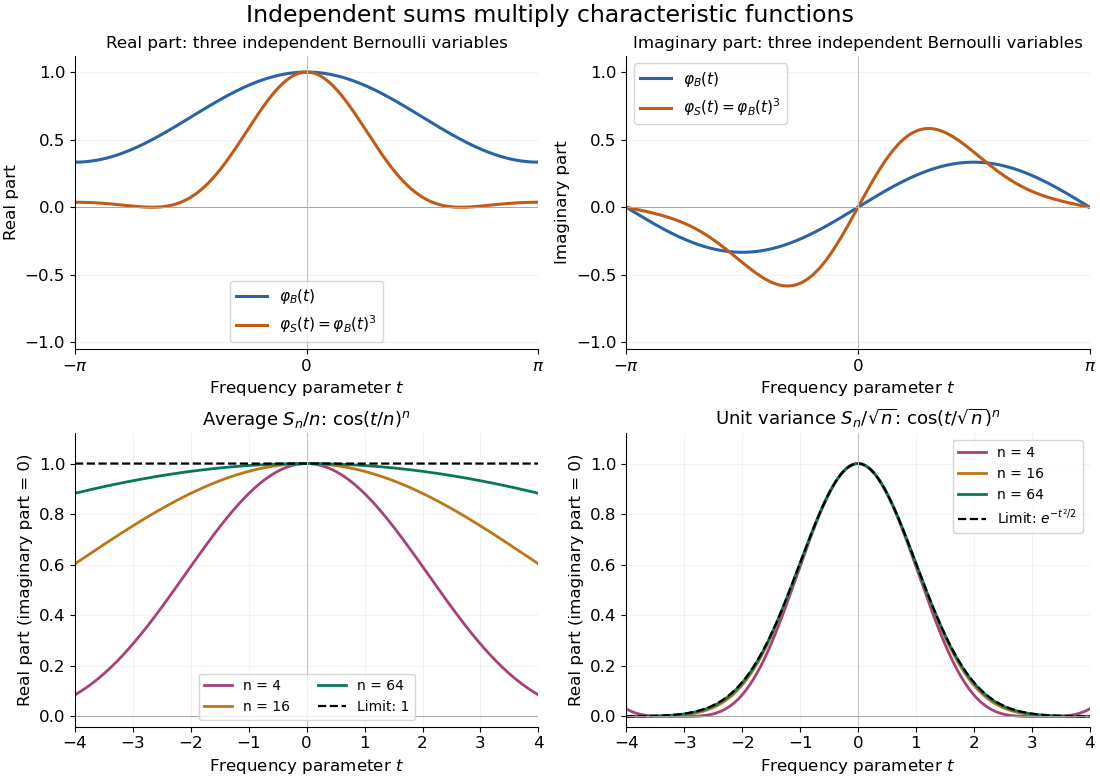
Let be independent and identically distributed random variables taking and with equal probabilities, the Rademacher distribution. The two opposite complex exponentials give . Their expected value is zero and their variance is one. For , the characteristic functions of its sample mean and its variance normalization are respectivelyFor each fixed , the bases are positive for all sufficiently large . The Taylor expansion at zero then givesExponentiating proves the two displayed pointwise limits. The first limit is the characteristic function of the constant zero; the second is that of the standard normal distribution. The Lévy continuity theorem gives the corresponding convergence in distribution statements. Averaging has variance , whereas dividing the sum by preserves variance one. This sign calculation illustrates why the law of large numbers and the central limit theorem use different scales; it is not a proof for arbitrary probability distributions.
If the characteristic functions of probability distributions converge pointwise to a function that is continuous at zero, then is a characteristic function and converges in distribution to its distribution. Conversely, convergence in distribution implies pointwise convergence of the characteristic functions.
For a probability measure on the real line with characteristic function , averaging over gives . This is at least when . Integrating gives the displayed bound. Consequently pointwise convergence of characteristic functions to a function continuous at zero implies tightness of probability measures, by the dominated convergence theorem on and a separate tail bound for the finitely many initial measures.
If independent and identically distributed random variables have characteristic function at zero, then their sample mean has convergence in distribution to : its characteristic function is . This is also convergence in probability by convergence in distribution to a constant implies convergence in probability.
Articles by others on the same topic



In mathematics, particularly in the fields of probability theory and statistics, a characteristic function is a tool used to uniquely identify the probability distribution of a random variable. The characteristic function of a random variable is defined as the expected value of the exponential function of the random variable, typically involving a complex variable.