The main modes include almost sure convergence, convergence in probability, convergence in Lp, and convergence in distribution. The strong law of large numbers and weak law of large numbers explain why a sample mean approaches an expected value; the central limit theorem describes the probability distribution of its remaining error after magnification by .
A probabilistic invariance principle is a limit theorem saying that a suitably rescaled random process converges to a universal limiting process. A basic instance is the functional central limit theorem: many different microscopic increment laws produce the same limiting Brownian motion after centering and variance normalization.
Let be independent identically distributed random variables with mean zero and finite variance . Put , and interpolate the values linearly at times . The resulting random continuous function converges in distribution in , with its uniform norm, to standard Brownian motion.[ref]
Probability: Theory and Examples (fifth edition) by Rick Durrett. Theorem 8.1.4, Example 8.1.6, printed page 392; linearly interpolated random walk and its maximum
This is stronger than convergence at each fixed time: it controls continuous functionals of the whole path. For a simple symmetric random walk, the maximum satisfies, for ,using the Brownian reflection principle and the standard normal distribution function . For this is about . The maximum here is one-sided, rather than the maximum absolute displacement. Convergence of finite-dimensional distributions alone would not establish a path-space theorem; control of path fluctuations, expressed through tightness of probability measures, is also needed.
A sequence is contiguous with respect to if implies for every measurable sequence of events. It transfers negligible-event assertions, including consistency, between changing sampling laws. It need not imply small total variation distance.
Let be the probability density function of the absolutely continuous part of relative to . If converges in distribution under to almost surely with , then are mutually contiguous. Indeed, and convergence to a mean-one limit imply uniform integrability and vanishing singular mass, giving forward contiguity. For reverse contiguity, , and one first takes and then .
Two sequences of probability laws are mutually contiguous when contiguity of probability measures holds in both directions. A positive mean-one limit of their likelihood ratio is a standard sufficient criterion.
For , convergence in Lp of real random variables on one probability space means . For this is convergence in the Lp norm; when , the same moment criterion is used without claiming it is a norm. The Markov inequality gives , so it implies convergence in probability. The converse fails: for uniform on , tends to zero in probability but .
Convergence in L1 means that the expected value of the absolute error tends to zero. It implies convergence in probability and convergence of expected values.
For nonnegative integrable functions converging almost everywhere to an integrable , convergence of their integrals implies L1 convergence. Indeed almost everywhere and is dominated by , so the dominated convergence theorem gives convergence of its integral. Use . This applies to probability densities, giving convergence in total variation distance.
If square-integrable random variables satisfy almost surely, then in exactly when . Boundedness in and almost-sure convergence first give weak convergence in the Hilbert space ; weak convergence together with convergence of norms gives strong convergence.
random variables converge in distribution, or converge weakly, to whenfor every bounded continuous function . For real random variables this is equivalent to convergence of the distribution functions at every continuity point of the limiting distribution function.
The probability distribution approached in convergence in distribution. It can depend on the initial state of a Markov chain when several closed communicating classes are accessible.
If has probability at least p at , with and , every weak limit has probability at least p at z. Apply the closed-set bound of the Portmanteau theorem to arbitrarily small closed intervals containing z and eventually , then decrease their radii. Thus a persistent atom prevents convergence to a continuous law, including a chi-squared law. This provides a direct check when bounded-information estimation fails standard asymptotic-normal theory.
Let take values with equal probabilities. Set for every , and for even , for odd . Both marginal laws are constant, but alternates between the law of and a point mass at zero. Thus separate weak convergence of random variables does not determine a joint limit or a sum limit. The obstruction disappears when one marginal limit is constant, as in the Slutsky theorem.
For convergence in distribution of random elements in a separable complete metric space, one can construct copies of the sequence and its limit on one probability space which converge almost surely. The copies preserve the individual laws; they need not preserve the original dependence between sequence elements. Suitable more general versions permit a separably supported limit in a metric space.
If all moments of real random variables converge to those of a moment-determinate limit law, then the variables converge to that law in the sense of convergence in distribution. Moment determinacy is essential; the standard normal distribution meets this condition.
probability measures on a metric space converge weakly to when for every bounded continuous real function .
A family of path laws satisfies Compact containment when for every finite horizon and every error tolerance there is a compact set which contains the whole path up to that horizon with at least the complementary Probability, uniformly over the family. In Euclidean state space this is the displayed condition. It prevents escape to distant regions where local coefficient approximations give no control. A nonnegative Lyapunov function with uniformly bounded generator growth often proves it by the optional stopping theorem.
A scaling limit of a random curve is a weak limit of laws after rescaling the curves and choosing the space in which they are compared. One first specifies a topology; tightness is then proved in that topology, rather than determining the topology by itself.
For continuous curves on considered up to increasing reparameterization, a common comparison starts fromwhere ranges over increasing homeomorphisms of and curves at zero distance are identified. This compares geometric traces with their order of traversal while allowing different traversal speeds. A parametrized process limit may instead use uniform distance or a Skorokhod J1 topology, so the intended notion of a curve matters.
For example, Brownian scaling gives the same law as Brownian motion for every . It is already invariant under this rescaling. For lattice models a scale change can instead produce a different continuum law; SLE is a central family of candidate limits. In an appropriate curve space, tightness supplies subsequential weak limits, and identifying every subsequential law with the same law establishes convergence of the full sequence. Finite-dimensional distributions alone do not provide the required control over entire curves.
On càdlàg paths on a compact time interval, convergence in this topology means that increasing continuous bijections of the time interval can be chosen converging uniformly to the identity, while the corresponding time-changed paths converge uniformly to the limit. At a continuous limiting path this reduces to uniform convergence. It is a standard topology for weak limits of accelerated discrete-time chains, whose paths are step functions.
This is the coarsest topology making all displayed bounded-continuous test integrals continuous. On a separable metric space it is metrized by the bounded-Lipschitz metric. This probability-measure topology should be distinguished from the weak topology of a Banach space.
The bounded-Lipschitz metric tests probability measures against a uniformly bounded Lipschitz class. It metrizes weak convergence of probability measures on separable metric spaces. With a complete compatible base metric, it is complete on the probability measures of a Polish space. Replacing the sum norm by the maximum norm changes the metric only by uniform constant factors.
On a Polish space, a family of probability measures is relatively compact for weak convergence exactly when it is tight. For finite measures, one additionally requires uniformly bounded total masses.
A weakly closed uniformly tight family of Borel probability measures on a Polish space is weakly compact. Embed the underlying space into a compact metric closure, take subsequential pushforward limits, and use the closed-set Portmanteau theorem on the common tightness compact sets. The limit retains full mass in the original space; inverse continuity of the probability pushforward embedding theorem then returns the weak limit.
On a compact metric space, every sequence of Borel probability measures has a subsequence with weak convergence of probability measures to a Borel probability measure. To see this, choose a countable uniformly dense subset of continuous functions, extract a diagonal subsequence of their bounded integrals, and extend the resulting positive normalized functional to all continuous functions. The Riesz representation theorem supplies its Borel probability measure. This is useful for constructing an invariant measure from orbit empirical measures.
For random variables supported in one fixed compact interval, convergence of every moment is equivalent to weak convergence. One direction tests monomials; the other follows by uniformly approximating continuous functions by polynomials.
Two probability measures supported on one compact interval are equal if all their moments are equal. Indeed, equality on monomials gives equality on polynomials, the Weierstrass approximation theorem extends it to every continuous function on the interval, and compactly supported continuous functions determine a finite Borel measure.
The Portmanteau theorem gives equivalent formulations of weak convergence, including inequalities on open and closed sets and convergence of expectations for every bounded measurable function whose discontinuity set has zero limiting Probability.
If and a measurable function is continuous at almost surely, then . The same principle holds for random elements of metric spaces.
Laws of large numbers give conditions under which sample means approach a deterministic expected value. For independent and identically distributed random variables with , the strong law of large numbers gives almost sure convergence, while the weak law of large numbers gives convergence in probability. These conclusions specify different modes of convergence of random variables, rather than a universal numerical accuracy guarantee. The central limit theorem is a separate result about the remaining fluctuations after rescaling.
A sequence of random variables converges almost surely when the set of outcomes on which pointwise convergence fails has Probability zero.
A sequence converges completely to when for every . The first Borel-Cantelli lemma implies Almost sure convergence. For independent , any limit in Probability is almost surely constant; the second Borel-Cantelli lemma then gives the converse from almost sure to complete convergence. independence is essential: for one uniform random variable converges almost surely to zero but its exceedance probabilities have a divergent sum.
If independent random variables converge almost surely to a finite , then is measurable for the tail sigma-algebra. The Kolmogorov zero-one law forces every rational threshold event for that limit to have Probability zero or one. A real-valued probability distribution with this property is a point mass, so is almost surely constant. Consequently the Second Borel-Cantelli lemma upgrades Almost sure convergence of independent sequences to complete convergence.
random variables and are almost surely equal when . Probability theory conventionally identifies random variables that differ only on a null event.
Let be real independent and identically distributed random variables with , and let be their expected value. Their sample mean satisfiesThis is almost sure convergence: with probability one, an entire infinite sequence of observations has averages that eventually stay within every prescribed positive tolerance of . The variance need not be finite. The strong law of large numbers implies the weak law of large numbers, which asserts convergence in probability at each increasing sample size.
For independent trials with a Bernoulli distribution of parameter , is one for success and zero for failure. Then is the observed success proportion, and the strong law of large numbers says almost surely. This turns a theoretical probability into a quantity one can estimate by repetition. It does not say that each new trial improves the estimate: a long string of failures can move the proportion away from before later observations bring it back.
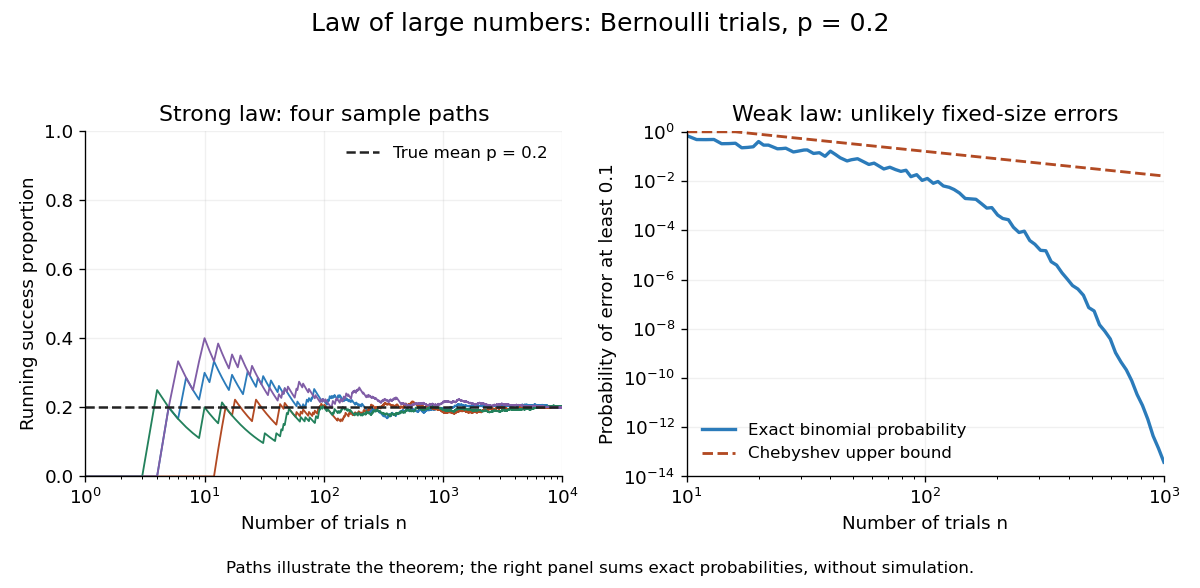

The strong law of large numbers gives the limiting location of the sample mean, while the central limit theorem describes its fluctuations when the variance is finite and positive. The two assertions can hold together:The first error shrinks to zero; the second has been enlarged enough to retain a nontrivial probability distribution. The second assertion is convergence in distribution, not a claim that the enlarged error along one sequence approaches a particular normal random variable.
The assumptions make a practical difference. If every observation repeats the same nonconstant Bernoulli random variable, , then for all : identical probability distributions alone do not make repeated observations informative. For independent observations with a Standard Cauchy distribution, the Cauchy sample mean has an unchanged distribution, so it does not concentrate around a constant. Its expected value is undefined, and ; neither example contradicts the stated strong law of large numbers.
A brief proof outline in the case of finite variance uses the Kolmogorov maximal inequality for the centered partial sums. The probability that their maximum up to exceeds is at most . These bounds are summable, so the Borel-Cantelli lemma controls all sufficiently large such blocks and hence every intermediate sample size. The general case requires truncation to control large observations; the argument using finite variance alone does not prove that full version.
For independent identically distributed random variables, the tail-sum formula applied to shows that for every when the first absolute moment is infinite. The Borel-Cantelli second lemma, followed by a countable intersection over positive integer , gives the first limsup assertion.
If had finite limsup along such a sample path, it would eventually be bounded by some finite constant . Then would imply eventually, a contradiction. This is a necessary-integrability counterpart to the strong law of large numbers; without a finite first absolute moment, the normalized sums cannot converge to any finite value.
Take independent random variables equal to and with probability each, and otherwise equal to one. Their first absolute deviations are , so in L1 convergence. The same triangle-inequality argument gives convergence in of their arithmetic averages to one. For , however, .
The exceptional jumps occur infinitely often almost surely by the Borel-Cantelli second lemma, since . If the arithmetic averages converged to any finite value along a sample path, then would tend to zero. At each exceptional jump its magnitude is at least one. Thus the averages have no finite almost sure limit. Independence and convergence of first-moment averages do not alone give a strong law of large numbers.
If the positive factors are independent and identically distributed and , the strong law of large numbers applied to their logarithms gives the displayed almost sure convergence. A negative limit forces the products to tend to zero; a positive limit forces them to tend to infinity. A zero limit alone gives neither conclusion. For a uniform distribution on , the logarithmic expected value is , so the products tend to zero almost surely for and to infinity almost surely for .
For independent and identically distributed random variables with and , the sample mean of tends to almost surely. Split into odd and even indexed products; each subsequence consists of independent and identically distributed random variables that are integrable random variables. Apply the strong law of large numbers separately.
If independent centered random variables satisfy , then converges almost surely. It follows from Kolmogorov's maximal inequality and a Cauchy-tail argument.
Let be independent and identically distributed real random variables with and . Write . The iid law of the iterated logarithm statesFinite variance is sufficient in this iid theorem; the lower conclusion follows by applying the upper theorem to . The iterated logarithm is the slowly growing factor .[ref]
For a simple symmetric random walk, . Its scaled partial sums exceed every fixed multiple of along some times almost surely, even though the central limit theorem gives a tight normal limit for at each growing deterministic time. The iterated-logarithm law concerns the extremes encountered along one infinite realization, rather than only the distribution at one time.
It also implies , since , and therefore refines the strong law of large numbers. For the sample mean, the almost-sure envelope is . The upper law of the iterated logarithm and Brownian upper law of the iterated logarithm articles isolate one-sided parts of the argument; proving a summable upper-tail bound alone does not establish the matching lower excursions.
For standard Brownian motion, the Brownian reflection principle bounds the Probability that its maximum up to exceeds by . This is summable for every and . The Borel-Cantelli first lemma controls these geometric times, monotonicity of the normalizing function controls the intervening times, and countable choices , give the bound. Equality requires a separate lower-bound proof.
For a simple symmetric random walk, geometric blocking and the Borel-Cantelli first lemma yield the upper estimate almost surely. Equality requires a separate lower-bound argument.
random vectors converge weakly to exactly when every linear projection converges weakly to . The reverse implication follows because these one-dimensional limits give pointwise convergence of the multivariate characteristic functions.
Random variables converge in probability to when for every fixed . It makes a fixed-size error unlikely at a late deterministic time; it does not assert that every path eventually avoids such errors. For uniform on , converges to zero in probability since its probability of being one is . Almost sure convergence and convergence in Lp each imply convergence in probability. No shared rate is part of the definition, and convergence of expected values requires further conditions.
For real random variables on one probability space, fix a continuity point of the cumulative distribution function . For every , inclusions of events giveTake the lower and upper limits as , using convergence in probability, and then let . Continuity at makes both bounds , proving convergence in distribution. The two modes of convergence have different information: convergence in probability concerns the coupling on one probability space, whereas convergence in distribution concerns only the marginal probability distributions.
For , Markov's inequality gives the displayed bound, so implies convergence in probability to zero even when the first absolute moment does not tend to zero. For products of independent and identically distributed factors, it suffices that . With the uniform distribution on , the product of independent uniform random variables formula makes this . Since as , such an exists whenever .
Uniform convergence in probability means that the supremum of the absolute discrepancy on the entire index set tends to zero in probability. It controls evaluation at random indices in that set, unlike pointwise convergence in probability. On a fixed compact index set it is a special case of uniform convergence on compacts in probability.
A sequence of random variables is bounded in Probability when . A sequence converging in probability to a finite random variable has this property, and its product with a sequence tending to zero in probability also tends to zero in probability.
The notation means that is bounded in probability asymptotically: for every some gives . A tail bound is sufficient. In statements involving bandwidths, specify whether the constants must be uniform over bandwidth sequences.
A bound on does not give the same bound on . Even independent standard normal random variables each have uniformly bounded tails while their Gaussian maximum over indices grows at scale . This distinction matters in nonparametric statistics when a shrinking bandwidth permits many spatial windows.
If for fixed real , convergence of the distribution functions at and shows . Thus convergence in distribution to a deterministic limit implies convergence in probability to that limit, even though the implication fails for nonconstant limits on a specified probability space.
Let be real independent and identically distributed random variables with and expected value . The weak law of large numbers states that their sample mean has convergence in probability to : for every fixed ,Thus a large sample is unlikely to give an average with a specified fixed-size error. The strong law of large numbers makes the stronger statement of almost sure convergence along an entire sequence. Under the displayed assumptions both laws apply; their names distinguish the conclusions, not two competing predictions.
When the variance is finite, variance additivity for independent random variables gives . The Chebyshev inequality immediately supplies a useful quantitative form and a brief proof:For independent trials with a Bernoulli distribution of parameter , the expected value is and the variance is . At , the chance of an error of at least is therefore at most . The exact binomial distribution gives a much smaller probability, as the figure under the strong law of large numbers shows. The bound is conservative, but it is valid for every sample size under these assumptions and does not require a normal approximation.
The weak law of large numbers addresses a fixed tolerance . The central limit theorem instead resolves errors on the shrinking scale and gives their approximate normal distribution. In particular, the weak law of large numbers alone supplies neither a bell-shaped error law nor a universal rate of approach. For example, a Pareto distribution with minimum one and shape has expected value three but infinite variance: both the weak law of large numbers and strong law of large numbers apply, while the finite-variance statement of the central limit theorem does not.
Suppose the variances of a sequence of random variables are bounded by and whenever , for a fixed nonnegative integer . The Cauchy-Schwarz inequality bounds each remaining covariance in absolute value by . In the variance of a sum, there are at most off-diagonal pairs, proving the displayed bound. The Chebyshev inequality makes the average minus its mean converge to zero in Probability. If all means equal , the average therefore converges in Probability to . independence of every summand is unnecessary.
Let have a symmetric probability distribution with for , mass at zero, and no mass with . Then , but independent copies satisfy the weak law of large numbers with limit zero. Indeed . Their symmetric truncations have mean zero and second moment , so Chebyshev's inequality gives in Probability. A union bound shows that the original and truncated sums differ with Probability tending to zero. This also gives a differentiable characteristic function at zero whose derivative cannot be interpreted as an absolutely convergent expectation.
For independent and identically distributed random variables with characteristic function , suppose their sample mean converges in Probability to a finite constant . Bounded exponential tests give uniformly on bounded intervals: the error is at most on . Taking the continuous complex logarithm vanishing at zero shows uniformly; an integer-valued branch difference is continuous and therefore zero. For arbitrary , put and , so . Dividing the uniform limit by proves , and thus . No absolute first moment is assumed.
Let be independent and identically distributed with probability law , and let be a class of measurable -integrable functions. Write and . A uniform law of large numbers concernswith measurability of the supremum assumed. A uniform weak law uses convergence in probability; a uniform strong law uses almost sure convergence. The mode and sampling assumptions are part of the statement.
For a finite class, the strong law of large numbers for each function holds simultaneously and gives the uniform strong law. For infinite classes, pointwise convergence alone is insufficient. For example, let be the uniform distribution on and take indicators of all finite subsets. Each fixed function has expectation zero and empirical mean tending to zero almost surely. Yet for every sample the finite set belongs to the class and its empirical mean is one. The displayed supremum is therefore one for every .
Conditions such as finite bracketing of a function class at every positive width control this complexity. The Glivenko-Cantelli theorem gives the uniform strong law for indicators of half-lines, the class determining the empirical distribution function.
A measurable-function class is pointwise separable if it has a countable subclass such that every member is the pointwise limit of a sequence from that subclass. With an integrable common envelope, dominated convergence theorem makes both empirical averages and population expectations converge along each such sequence. Thus the supremum of the absolute empirical errors equals the supremum over the countable subclass and is measurable. A finite integrable bracketing cover provides an integrable envelope by taking the maximum absolute value of all its endpoints.
A bracket contains every measurable function satisfying pointwise. For a Probability measure , its width is , with integrable endpoints. Finite bracketing at every positive width is a sufficient complexity condition for a uniform law of large numbers. Pointwise inequalities, or inequalities outside a single common null set, allow empirical inequalities to hold simultaneously throughout the class.
A measurable function is an integrable envelope of a function class for a class under a probability law if for every and . Such an envelope permits the dominated convergence theorem to control shrinking function brackets.
Suppose an integrable measurable-function class can be covered by finitely many function brackets of every positive width. For an independent sample with common law , the empirical measure satisfies on a common probability-one event. For one finite -cover, the supremum is bounded by plus the largest empirical error among its endpoints. The strong law of large numbers makes that finite maximum vanish. Taking a countable sequence of widths decreasing to zero proves the assertion. A measurable supremum can be obtained from a pointwise separable function class; otherwise the probability-one-event formulation expresses the same pathwise conclusion.
Let be a compact metric space, let be continuous in for each and measurable in for each , and assume the envelope is integrable under . For an independent and identically distributed sample,Compact metric structure supplies both finite parameter nets and countable dense sets, so the relevant suprema can be treated measurably under these continuity assumptions.
For a proof, define . Uniform continuity on the compact parameter set gives for each , and . Thus by the dominated convergence theorem. At a finite -net of centers, apply the strong law of large numbers to every center and to . For a nearby center ,The limiting supremum is at most . A countable sequence proves the claim. Equivalently, these center functions and their oscillation envelopes give the function brackets used in the uniform strong law from finite L1 bracketing.
For independent and identically distributed real observations with cumulative distribution function , the empirical distribution functionsatisfies the Glivenko-Cantelli theoremThe population law may have atoms; continuity of is not required. The conclusion is uniform over every threshold, strengthening the separate strong laws for fixed thresholds.[ref]
Here is a proof using inverse transform sampling. First take iid uniforms and their empirical CDF . At the finitely many grid points , the strong law of large numbers gives simultaneously. Monotonicity bounds the discrepancy between grid points by the largest grid discrepancy plus . Taking countably many proves uniform convergence on .
For general , construct using the quantile function. Then exactly when , so and the general supremum is bounded by the uniform one. This also handles jumps of . The theorem does not apply merely because an empirical CDF was formed: for repeated copies of the same nondegenerate random observation, the empirical CDF does not approach its population law in this way.
For a cumulative distribution function , let , . Right continuity gives exactly when , including at atoms. Thus applying to independent uniform variables constructs an independent sample with distribution function . Its empirical distribution function is , where is the uniform-sample empirical distribution function. Consequently . For the uniform sample, monotonicity and a grid of mesh bound the last supremum by the largest error at grid points plus . The strong law of large numbers on the countable union of all such grids proves the almost-sure limit. This construction proves the theorem for distributions with atoms as well as continuous distributions.
If converges in Probability to both and , then almost surely. Indeed, the triangle inequality and a union bound show that for every .
Convergence in probability is equivalent toThe forward implication splits at a fixed error threshold; the reverse implication is Markov's inequality.
independent indicators with success probabilities converge to zero in Probability, but successes occur infinitely often almost surely by the second Borel--Cantelli lemma.
If in Probability and , then in for every . The bound gives Uniform integrability of the th powers, while Convergence in probability controls their bounded part.
A family of integrable random variables is uniformly integrable whenAlmost-sure or probabilistic convergence together with Uniform integrability upgrades to convergence.
On a finite measure space, a family is uniformly integrable exactly when it admits the displayed bound for some nonnegative increasing convex superlinear function . By the Dunford-Pettis theorem this ensures relative weak compactness in . For the sufficient direction, choose so for ; then gives uniform integrability. Conversely choose increasing thresholds so . The convex function is locally a finite sum, has uniformly bounded integrals by summing these tail estimates, and is superlinear because for its first terms sum to at least . This proves the criterion in both directions.
Choose increasing so whenever . Put for . This is nonnegative, increasing and convex. If terms are active, then for . For every fixed , gives , proving superlinearity. Thus a nonconvex superlinear energy lower bound still supplies the convex function needed in the De la Vallée-Poussin criterion. A continuous superlinear function not initially nonnegative can first have its finite global minimum subtracted.
On a finite-measure space, a bounded subset of is relatively weakly compact exactly when it is uniformly integrable. In particular every uniformly integrable bounded sequence has a weakly convergent subsequence. This is the compactness substitute for reflexivity at exponent one. A superlinear integral bound , with and , gives the required uniform integrability: for outside ,Choose large and then the measure of small. This is the direction used in the direct method in the calculus of variations; a mere bounded norm does not suffice, as concentrating spikes show.
For a uniformly integrable bounded sequence of derivatives on a compact interval and a fixed initial value, its primitives are uniformly bounded and equicontinuous. The increment over any short interval is bounded by the integral of the absolute derivative on that interval. The Arzelà-Ascoli theorem gives relative uniform compactness. If the derivatives converge weakly in , tests by interval indicators identify every pointwise limit with . Hence every convergent subsequence has this same limit and the primitives converge uniformly. The limit belongs to and retains any common terminal value. Uniform integrability alone gives no essential-supremum bound on its derivative, so this compactness statement does not assert a Lipschitz limit.
On a finite time horizon, an adapted process is of class D if its values at all stopping times in that horizon form a uniformly integrable family. Deterministic boundedness implies this property. The stopping-time uniformity is stronger than having an integrable value at each fixed time.
An adapted process is of class DL when, for every finite , the family is uniformly integrable. A local martingale is a true Martingale exactly when it has this property. This is a local-in-time condition, not Uniform integrability over the whole half-line.
// Target: probability-and-statistics.bigb
For integrable random variables ,Apply this with and to prove that convergence in L1 implies uniform integrability; control finitely many early terms separately.
For one integrable random variable , the family , over arbitrary sigma-algebras , has uniform integrability. On , the defining property of conditional expectation gives , while by the Markov inequality. The integrable random variable has uniformly small absolute integrals over events of sufficiently small Probability.
A sequence satisfies a Large deviation principle with speed and Rate function when probabilities of measurable sets decay exponentially between the bounds
The Schilder theorem gives a large deviation principle for small Brownian motion paths. For standard Brownian motion starting at zero on , the laws of on continuous paths with the uniform norm have speed and good rate functionIn particular, the zero starting value and finite-energy path class are part of the rate. Typical Brownian motion paths are not themselves absolutely continuous; the rate describes the exponential cost of neighborhoods of prescribed paths.[ref]
An Introduction to Large Deviations by Vitalii Konarovskyi. Section7.1, Theorem7.1, and section7.3 proof
For paths constrained by , the Cauchy-Schwarz inequality gives , with equality for . Thus the least endpoint cost is , agreeing with the exponential scale of the normal distribution of .
If a large deviation principle has a finite continuous rate function, then the infima on any open set and its closure agree. Approximate every closure point by points of the set and use continuity. The open-set lower and closed-set upper bounds consequently match, giving the displayed logarithmic limit, including the empty-set convention. A single-point event need not obey such an equality.
Let be independent and identically distributed with mean , variance , and a moment-generating function finite on an open interval about zero. Choose with and . The moderate deviation principle foris a large deviation principle of speed and good rate function .
To see the Gaussian quadratic rate, center one summand and expand its logarithmic moment-generating function at zero. For every fixed real ,The limiting function is finite and differentiable everywhere, so the Gärtner–Ellis theorem applies; its Legendre-Fenchel transform is the displayed rate. This proof states an actual sufficient exponential-moment hypothesis rather than leaving the assumptions implicit.
For , a fixed positive corresponds to a sample-mean displacement of order , between the ordinary central-limit scale and a fixed order-one displacement. Its tail has logarithmic Probability of order . The scaling is intermediate, but the rate is still quadratic under these hypotheses.
For a Poisson random variable of mean and , the scaled cumulant-generating function is . Its Taylor expansion tends to for every real . The Gärtner–Ellis theorem applies because the limit is finite and differentiable everywhere. Its Legendre-Fenchel transform is the displayed quadratic good rate function.
For a fixed finite number of nonnegative terms and , use . The logarithm of , divided by the large-deviation speed, tends to zero, and a finite maximum commutes with the limit superior. If all individual logarithmic limits exist, the limit of the sum is their maximum.
Let have the positive-support geometric distribution with . As , satisfies a large deviation principle of speed and good rate functionFor every real threshold , the exact upper-tail formula isThe maximum with zero matters at and at thresholds below the first lattice point; the uncapped exponent would otherwise give a Probability greater than one.
For positive , dividing the logarithm by gives the limit . These tails bound closed sets through their leftmost nonnegative point. For an open neighborhood of a positive , choose integers with ; their individual masses have the same logarithmic limit. Neighborhoods of zero have Probability tending to one, supplying rate zero there. Negative-only sets have Probability zero, and the rate sublevel sets are compact intervals.
For example, with , and , the event is and has Probability . Meanwhile converges in Probability to zero. The nontrivial rate describes the rare excursions away from that degenerate weak limit.
For fixed finitely many independent geometric random variables, the product large-deviation principle gives rate on the nonnegative orthant for their scaled vector, where . The contraction principle for large deviations under addition minimizes this over . The answer is , achieved by assigning all scaled excess to a coordinate with the slowest geometric tail. The rate is infinite for negative . Deterministic coordinates with contribute zero on this scale; if all coordinates are deterministic, only zero has finite rate.
Let be independent random variables with normal distribution , , and let be an independent exponential random variable of rate . At speed , has the good rate functionThe product large-deviation principle gives the joint cost for , and the contraction principle for large deviations gives its infimal convolution under . The minimum occurs at . The fixed exponential perturbation changes the far upper tail even though it vanishes in probability after division by ; a fixed Gaussian random variable divided by instead has exponential equivalence with zero at speed .
A weak large deviation principle has the usual lower bound on every open set, but requires the upper bound only on compact sets. It does not by itself control probabilities escaping every compact set. Exponential tightness provides that missing control.
Suppose a weak large deviation principle with rate function holds on a Hausdorff space, at speed , and the random elements are exponentially tight. For a finite , choose a compact set whose complement has upper exponential rate strictly below , with . The open-set lower bound on implies , so . Lower semicontinuity makes this sublevel set closed, hence compact. For any closed set , split its probability between the compact and . The upper exponential rate is at most . Letting proves the full large deviation principle with a good rate function.
Suppose a large deviation principle at speed has a good rate function with unique zero mu. At any slower speed with , its rate is zero at mu and infinity elsewhere. On a closed set excluding mu, the positive original rate gives decay faster than every exponential at speed . Neighborhoods of mu have Probability tending to one, giving the slower-speed open-set lower bound. The new rate is good because its finite sublevel set is the singleton mu.
If random elements satisfy a large deviation principle at speed with rate function I, then a bounded continuous real function f satisfies the displayed exponential-integral identity. For the upper bound, partition its bounded range into finitely many closed intervals of width epsilon and apply the closed-set upper bound to their preimages. The largest exponential term controls the finite sum. For the lower bound, restrict to an open neighborhood where f is within epsilon of its value at a chosen point and use the open-set lower bound. Let epsilon tend to zero and optimize over the point. Boundedness avoids a separate exponential tail assumption.
For a continuous and a family satisfying a large deviation principle at speed , the displayed exponential tail condition extends Varadhan's lemma to unbounded above. Apply the bounded-above result to and split the full integral into and its tail; the tail is negligible and the truncated variational suprema increase to . A sufficient condition is for some , since the tail is at most .
The exponential integral of a fixed measurable function is controlled, on its logarithmic scale, by the function's essential infimum. Suppose and is finite. For , the integral is at most . For every , the set has positive finite Lebesgue measure, and the integral is at least . Taking logarithms, dividing by , and then letting proves the displayed limit. The argument needs no isolated or nondegenerate minimizer. The Laplace principle for probability measures treats families whose distributions also change with the scaling parameter.
A family satisfies this principle with speed and rate function when the displayed variational identity holds for every bounded continuous real function . A large deviation principle implies it by the Varadhan lemma. The lower bound restricts the expectation to a neighborhood of a chosen point; the upper bound partitions the bounded range of into small intervals and applies the closed-set probability bounds.
For nonnegative , the identity also givesFor , truncate below at . The resulting bounded-function identity applies, while the difference of the two exponential expectations is at most . Choosing sufficiently large makes this error negligible on the claimed exponential scale. The case is immediate. This extension identifies moment-decay rates of a passive scalar from fluctuations of its logarithmic stretching.
Let and . Define the scaled cumulant-generating functionSuppose its pointwise limit exists, is lower semicontinuous, has in the interior of its effective domain, and is essentially smooth: it is differentiable on that interior, which is nonempty, and its gradient norm diverges at every finite boundary point approached from the interior. Then satisfies a large deviation principle with good rate function given by the Legendre-Fenchel transformThe Chernoff bound supplies the upper estimate. The lower estimate uses exponential tilting at a parameter whose gradient selects the required mean; essential smoothness supplies the boundary approximation needed for the full lower bound. A finite boundary slope can leave an affine branch of outside this argument, so a separate lower-bound proof is then necessary.
Suppose and are independent random variables in Polish spaces, each satisfying a large deviation principle at speed , with good rate functions and . Their pair has good rate function . On open rectangles, independence makes the logarithmic lower bounds add. For the upper bound, the marginal families are exponentially tight, and so is their pair. Cover a closed set intersected with the product of the two compact containment sets by finitely many small rectangles and add the corresponding local upper bounds. The finite union bound and then increasing the containment level give the closed-set bound. Goodness follows because is closed inside .
Articles were limited to the first 100 out of 132 total.
Articles by others on the same topic
There are currently no matching articles.