Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 34 2 c Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
Expected death counts are the number of users multiplied by the death risk per user, with matching time windows and definitions. Relative to the MDMA benchmark, the proposed use prevalence contributes a multiplier of and the per-user fatality risk contributes a multiplier of . HenceThis assumes comparable user exposure durations and recording of single-drug deaths. Population death counts alone would not identify a per-user risk ratio without the prevalence denominator.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 34 2 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Model deaths in disjoint equal-duration periods as independent observations with Poisson distributions with comparable population exposure and ascertainment. The expected before and after counts are and . Their difference hasThe expected signal relative to its standard deviation is thereforeUnder the null of equal rates, condition on : the first-period count has a binomial distribution with parameters and . At a total near 720, the two-sided 5% rejection boundary for is approximately . Under the proposed alternative, conditional on that total, its mean is and its variance is . Thus at the normal approximation gives power approximatelyThe lower-tail rejection probability is negligible at this alternative; allowing the Poisson total to fluctuate and using discrete rejection cutoffs changes the approximation slightly: an exact two-sided conditional test has about power under these Poisson means. Two years on each side should have adequate power for a 20% reduction under this model, though a particular realization can still fail to detect it.
This conclusion needs stable recording of drug-related deaths, comparable exposure denominators and no substantial overdispersion or temporal dependence. A change in population size, certification practice or other drug use can affect the comparison. Detecting a decline does not establish that mephedrone caused it: attributing displacement requires a credible comparison of potential outcomes, using an otherwise expected trend or other controls for changes occurring at the same time.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 34 2 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use a concurrent comparison: test the same specimens for both cocaine and mephedrone, rather than treating the historical cocaine percentage as an exactly known 2010 parameter. Assume representative sampling of privates, effectively independent specimens, stable underlying rates during the sampling period, and sufficiently accurate assays. I use a two-sided 5% test of equal positive-test probabilities, with 80% statistical power at and . This is a design to distinguish the rates at a twofold alternative; a significance test does not prove that their ratio is exactly two.
The paired design needs the joint positive-test distribution. For specimen , write and . Put andThen and . Under equal marginal rates, the two discordant outcomes have equal probabilities; conditional on the total number of discordant specimens, their split is a fair binomial distribution. This gives the McNemar test. Its large-sample version rejects for a sufficiently large absolute difference between the discordant counts, divided by their estimated standard deviation.
For planning, suppose simultaneous positives are negligible, so . Under the alternative the difference in positive counts has mean and standard deviation ; the approximate upper null rejection boundary is . Requiring 80% upper-tail rejection probability gives the paired binary sample size calculationAdd the mephedrone assay to about 5,000 existing tests, roughly ten weeks at 500 per week. An exact conditional-power calculation under the negligible-overlap model gives about at 4,707 specimens and at 5,000, so the rounding also compensates for the conservative discrete test. If positivity for the two drugs were independent within a specimen, , giving a very similar requirement of about 4,676. For the stated marginal rates, , so negligible overlap is a conservative variance choice within this approximation. Substantial co-use reduces the discordant proportion and changes the necessary size. Repeated tests on the same person, unit-level clustered data or inaccurate assays can instead reduce effective information and require more specimens.
A pre-specified one-sided 5% comparison would use in place of and require about 3,708 specimens before allowing for discreteness under the negligible-overlap assumption. These are different testing conventions. Treating the historical 1% as fixed would give a one-sample calculation, but would ignore uncertainty or changes in the actual 2010 cocaine rate.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 34 1 i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14A reversal this large calls for an audit, but the aggregate table cannot identify a particular error. Check the outcome and exposure coding, the reference category, the subset used in each analysis, missing-data exclusions, denominators, weights, and whether the reported coefficient actually corresponds to the intended comparison. Reversing an exposure contrast or exponentiating the wrong fitted coefficient would change the reported odds ratio. Conditioning on variables affected by delivery, or including inappropriate interactions, could also change the causal inference rather than merely improve precision.
Start by reproducing the crude odds ratio from an independent two-by-two calculation. Then fit progressively adjusted logistic regressions, recording how the coefficient and analysis population change; inspect within-clinic comparisons, sparse cells and separation. For an ordinary likelihood fit, check the fitted expected event count against the observed count and verify that changing only to cluster-robust standard errors leaves the fitted coefficients unchanged. A sandwich covariance matrix corrects uncertainty for clustered data; it does not by itself turn a crude odds ratio below one into an adjusted odds ratio above one. Adding clinic effects, using weights or changing the model can change the point estimate and must be distinguished from that variance correction.
Programming or reporting error is a possibility to check, not a conclusion proved by the reversal. Strong legitimate confounding remains another explanation.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 34 1 h Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The displayed information does not establish increased maternal mortality caused by elective exposure. There are no observed deaths in that group, and the reported adjusted estimate concerns a composite adverse outcome, not death alone. A composite can show an association driven by nonfatal components without identifying a mortality effect.
If the logistic regression and its adjustment are correct, its confidence interval supports an adjusted association with the composite outcome. Calling that association a causal increase in risk additionally requires a defensible comparison group, adequate control of confounding, valid outcome classification and a well-defined intervention. The crude result is in the opposite direction, and the implied very low counterfactual baseline risk deserves examination. Conversely, zero deaths does not prove absence of harm. The justified conclusion is an association conditional on model and study assumptions, with mortality and morbidity distinguished.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 34 1 g Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The groups were not formed by randomization. Their background health, access to care, clinic, country and reasons for selecting a delivery method can predict both the method and the outcome, creating confounding and selection bias. Moreover, the label describing the reference delivery may be determined after labour: patients whose attempted nonoperative delivery develops a complication can move into an operative category, leaving a selected uncomplicated reference group. Comparing intended strategies would avoid treating this post-baseline classification as a baseline assignment.
A useful comparison would therefore align eligibility and follow-up time, compare intended delivery strategies among patients genuinely eligible for both, and account for sufficient pretreatment predictors. Logistic regression cannot create comparable patients where the positivity assumption fails or remove unmeasured confounding.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 34 1 f Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14As a rough rare-event calculation, divide the observed elective-group event count by the reported adjusted odds ratio:For a homogeneous illustrative risk, the exact odds conversion starts from and givesThe corresponding baseline risk is about , compared with in the observed reference group, roughly seven times lower. Thus taking the adjusted result literally implies exceptionally low background risk among the elective patients.
This is a diagnostic approximation, not an identified mean of potential outcomes obtainable from the aggregate table. A conditional odds ratio cannot generally be inverted at an aggregate mean: individual background risks are needed for outcome standardization. Interpreting the calculation causally also requires conditional exchangeability, the positivity assumption and a correctly specified outcome model. At very small risks the rare-event approximation makes the estimate of roughly three events useful for checking the plausibility of the adjustment.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 34 1 e Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Using the reference event rate as the background-risk benchmark givesThis is the expected count if the elective group had the reference group's baseline risk and the procedure added no effect. It is substantially above the observed count, illustrating the importance of the background-risk comparison.
Similarity of background factors alone does not fix the elective group's event risk if the procedure itself changes it. If one additionally retained the reported common adjusted odds ratio and used as the common baseline risk, then conversion from odds to probability would giveThese are different assumptions: about 25 is the baseline/no-effect benchmark; about 64 includes an odds multiplier of 2.7.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 34 1 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14There is an apparent reversal, but not a mathematical contradiction. The crude odds ratio averages over the actual background distribution in each group, whereas the adjusted logistic regression compares groups at the same fitted background values. Strong confounding could make those distributions very different: for example, elective patients might disproportionately come from low-risk backgrounds or clinics, while the reference patients come from higher-risk backgrounds. The Simpson paradox can then reverse the marginal comparison even when every conditional comparison favours the same direction.
The noncollapsibility of the odds ratio can also make marginal and conditional odds ratios differ in magnitude. It does not, by itself, explain a sign reversal if both groups have the same covariate distribution and the common conditional effect has one sign: if for every , averaging over the same distribution of still gives a larger exposed risk. A genuine reversal therefore requires differing background distributions, heterogeneous effects or another change in what is being compared. The observed reversal is a reason to investigate these issues, not proof of a programming error.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 34 1 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write the logistic regression aswhere denotes elective exposure and contains the measured background predictors. At fixed , changing from zero to one changes the log odds by , so the adjusted odds ratio is . If is the estimated coefficient covariance matrix, thenUse the clinic-cluster sandwich covariance matrix if that is how within-clinic dependence is allowed for. The interval is first calculated on the coefficient scale and then exponentiated; one does not add and subtract a standard error directly from the odds ratio. This is a large-sample Wald confidence interval; profile-likelihood limits are another option when the likelihood shape warrants them. If exposure interacts with background variables, there is no single common conditional odds ratio: its logarithm includes the corresponding interaction terms.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 34 1 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Zero observed events do not mean that the underlying event probability cannot be estimated. For independent observations having a common Bernoulli distribution, the binomial likelihood with no events is , maximized at . A zero-event binomial upper confidence bound shows the remaining uncertainty: the one-sided 95% upper bound solves , givingThus the point estimate is zero, but a nonzero mortality risk is compatible with the observations. This bound is an illustration under independent equal-risk sampling; clustered data or unequal risks require their own uncertainty calculation.
The empirical unadjusted odds ratio is also defined:Its log odds ratio is , so the ordinary normal approximation for a log-odds confidence interval is unavailable. Exact likelihood-based limits can still describe uncertainty; a specified continuity correction would instead yield a finite, method-dependent point estimate.
In an unpenalized logistic regression with a separate coefficient for elective exposure, every exposed death outcome is zero. Decreasing that coefficient toward increases the exposed observations' likelihood contributions and leaves the reference observations unchanged. This is quasi-complete separation: there is no finite ordinary maximum-likelihood estimate of the exposure coefficient, even after adding background predictors. It is reasonable to say that the usual finite adjusted coefficient could not be fitted; it is too strong to say that no risk estimate or statistical information is possible. A specified penalized likelihood or Bayesian inference with proper coefficient priors can provide a finite adjusted estimate, whose dependence on the regularization must be reported.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 34 1 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The odds ratio compares event odds, not event probabilities. Let group 1 denote the elective group and group 0 the reference group. Their fitted event probabilities are and . ThusThe risk ratio is similarly about . The unadjusted observations show a lower adverse-event frequency in the elective group, rather than an increase. This is an association, not evidence that choosing the procedure prevents adverse outcomes. The direction is opposite to the reported adjusted odds ratio above one; the two analyses compare different populations or different conditional risks.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 33 1 i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The displayed equation has nominal orders , withThe AR root is , and the MA roots are and , all strictly outside the unit disc. Thus its stationary solution is causal and invertible. There is also common factor cancellation in an ARMA model: the convergent inverse of cancels the shared factor, givingConsequently the displayed representation is ARMA(1,2), but its minimal order is ARMA(0,1). This also follows without formal operator cancellation: the difference between any solution and the right-hand side satisfies . A stationary finite-variance difference must have zero variance, since stationarity would give ; its constant mean must also vanish. A transient chosen by an arbitrary initial condition is not the stationary process whose ACF is requested.
For this moving-average model, independence of the noise giveswhile for , since the two noise sets are disjoint. Therefore its autocorrelation function isThe reduced moving-average inverse is , whose coefficients are absolutely summable, confirming invertibility directly.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 32 2 2 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Set and . For the Poisson distribution observations, factors independent of can be removed from the likelihood function, leavingWhen , the log-likelihood derivative is and its second derivative is negative. The unique positive maximum-likelihood estimator is thereforeThere is a genuine boundary qualification: if , the likelihood decreases strictly on , so no maximum is attained in the stated open parameter space. On the closure , its maximizer is . Defining the usual extended maximum-likelihood estimator by the same displayed formula for every allows its statistical consistency to be examined; the all-zero event cannot be ignored because its probability does not tend to zero.
Indeed, sums of independent Poisson distribution variables give , soThus the extended maximum-likelihood estimator is inconsistent. More precisely, increases to , and shows that this total count is finite almost surely. Its distribution is Poisson distribution with mean , by taking limits of the finite-sum laws. HenceThis finite-exposure Poisson inconsistency leaves a nondegenerate random limit even with infinitely many observations. Correspondingly, the total Fisher information is , rather than diverging. The common-distribution hypothesis in the introductory maximum likelihood estimation theorem is absent here.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 32 2 1 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The likelihood function for the shifted exponential distribution isIt increases strictly up to the smallest observation and is zero beyond it. Thus shifted exponential maximum likelihood givesFor , independence and the survival function of the exponential distribution give the exact order statistic lawIn particular, almost surely and . This proves statistical consistency. The exact endpoint limit for a shifted exponential distribution is stronger than an asymptotic approximation:The limit is one-sided and nonnormal; the moving support endpoint explains why a regular square-root- asymptotic normality of a maximum likelihood estimator theorem does not apply here.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 30 4 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let maximize SYSTEM. Under the usual positive-capacity, nonempty-route assumptions, the feasible set is compact, contains a positive point, and has a Slater condition point. Strict concavity makes the optimum unique. The condition forces : moving from any optimum with a zero component slightly toward a positive feasible point gives an infinite positive directional derivative in that component and only finite losses in the positive components.
By the Karush-Kuhn-Tucker conditions, there are link Lagrange multipliers withSet the route congestion price and chooseThen , as required. For USER with fixed , the substitution is a bijection of the nonnegative half-line, and its objective becomes . This is a strictly concave function whose derivative vanishes at , so its unique maximizer is and the corresponding USER optimizer is .
For NETWORK at , its objective derivative at isThus obey its Karush-Kuhn-Tucker conditions, with the same feasibility and complementary slackness. The NETWORK objective is a strictly concave function, so is also its unique maximizer. The triple solves all three problems simultaneously. This is a user-network decomposition of concave utility maximization.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 30 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The objective approximates the logarithm of the product-form stationary distribution of a loss network. To make the approximation precise, multiply arrival rates and capacities by and write . The Stirling formula gives, uniformly on the feasible compact set,with . The feasible set is . Positive capacities and a nonempty route for each class make compact with a strictly positive feasible point. Since is a strictly concave function, its maximizer is unique; its infinite inward derivative at makes every component positive.
The Karush-Kuhn-Tucker conditions give nonnegative link Lagrange multipliers satisfyingFor any neighborhood of , continuity and uniqueness give a strictly positive objective gap outside it. There are only polynomially many feasible lattice states, while their weights differ exponentially in . The feasible point has objective tending to . It follows that the stationary law concentrates at on the scale ; in particular,Thus NETWORK predicts the dominant occupancy and mean occupancy in a large loss network. For unscaled inputs it gives a continuous approximation to the modal integer state.
It also gives an exact useful change of variables. Substituting into the equilibrium weights yieldsThis is Poisson exponential tilting for a loss network: independent Poisson random variables centered at the predicted occupancies, restricted to the feasible region and penalized for slack in positively priced resources. It explains why an unconstrained Gaussian approximation should not automatically be applied at a saturated capacity boundary.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 30 3 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The alternative routing term feeds additional traffic back into the link. We can prove the existence of three solutions rather than relying on an iteration that happens to find different answers. Choose , , and define the continuous residualBy the proportional scaling limit of the Erlang loss formula, at each fixed ,At , the multiplier is , so . At it is , givingAlso and for every , since a finite-capacity Erlang loss formula gives a blocking probability strictly between zero and one. For all sufficiently large , the signs at therefore alternate. Applying the intermediate value theorem in the three disjoint intervening intervals proves at least three distinct fixed points. This supplies a fluid scaling proof of multiple Erlang fixed points.
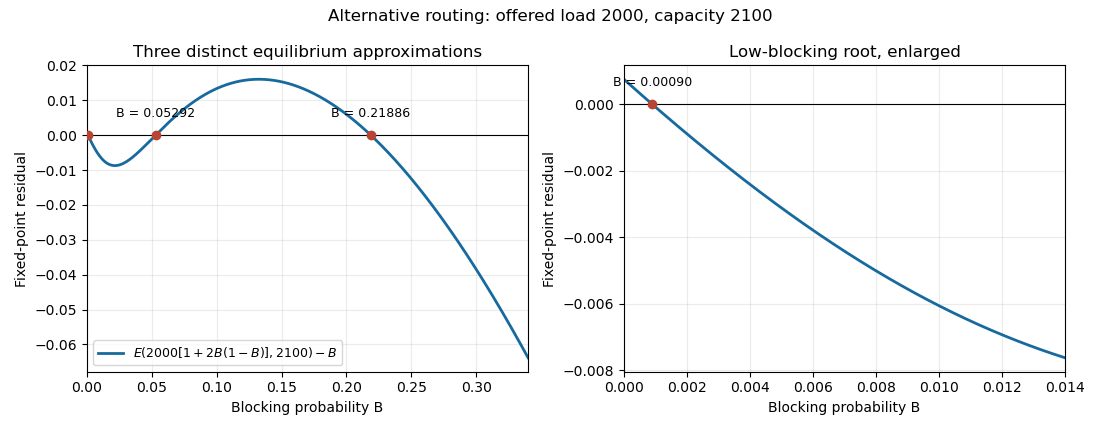
This multiplicity concerns the Erlang fixed point approximation. It does not imply several equilibrium laws for an exact finite irreducible Markov chain, which has a unique stationary distribution.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 30 3 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For the link-route incidence matrix , the reduced-load approximation and Erlang loss formula giveIntroduce and accepted route flows . Multiplying the reduced load by the link's own acceptance probability givesThese are precisely the first-order optimality conditions for the convex potential for the Erlang fixed point, sinceEach exponential term is a convex function, and the integral of the strictly increasing function is a strictly convex function. Hence is a strictly convex function. Moreover as , by the saturation of the carried load of an Erlang loss resource. Its integrals tend to infinity at least linearly, so is a coercive function on the nonnegative orthant and has a unique minimizer.
At , . If link is used by any positive-rate route, then , excluding a boundary minimizer there. An unused link instead minimizes at and has zero derivative. Thus the minimizer satisfies the displayed flow equations for every link. Conversely, those equations imply and therefore minimize the convex potential for the Erlang fixed point. Finally with converts the flow equations back to . The Erlang fixed point approximation has exactly one solution under fixed routing.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 30 3 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Start from the Erlang loss formula and reverse the order in its denominator:For each fixed , the product tends to . If , it is bounded by this same summable geometric series. Extend the summand by zero for and apply the dominated convergence theorem with counting measure to obtainIf , retain the first summands. Their limiting sum is at least , so the reciprocal tends to infinity as can be arbitrarily large. This includes without a separate normal approximation. ThereforeHere and are positive integers, as appropriate for circuit counts; taking gives the same limit for a positive real capacity scale. This is the proportional scaling limit of the Erlang loss formula.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact