The estimated intercept means that a female mouse with weight zero would have predicted mean testosterone concentration under this linear regression; zero weight is an extrapolation without a meaningful adult-mouse interpretation.
Holding sex fixed, each additional gram of weight is associated with an estimated increase in mean testosterone concentration, according to the fitted multiple linear regression.
At the same weight, male mice have an estimated mean testosterone concentration higher than female mice; the sex regression coefficient is an adjusted difference between the groups.
At a conventional 5% significance level, there is evidence for an association with sex after adjusting for weight, because its two-sided p-value is . There is insufficient evidence for a weight association after adjusting for sex, because its p-value is .
These Student t-tests test whether the corresponding regression coefficients are zero within the additive multiple linear regression. Failure to reject the weight hypothesis does not establish an exactly zero effect; these associations alone also do not justify a causal inference. The later model with a statistical interaction asks a different question, allowing the weight association to differ by sex.
Two assumptions of the usual normal linear model used for the reported coefficient Student t-tests are:
- The errors are independent random variables across mice.
- Conditional on the predictors, each error has a normal distribution with mean zero and the same variance : .
The second statement includes homoscedasticity. Normality concerns the conditional errors, rather than requiring the weights themselves to have a normal distribution.
Include both main effects and their interaction term:
fit_interaction <- lm(testosterone ~ weight * sex, data = mice)Here
mice denotes the data frame containing the named variables. In this R formula, weight * sex expands to weight + sex + weight:sex; it does not omit the main effects.The interaction term estimates that the weight-associated change in mean testosterone concentration is per gram greater in males than females: the female slope is and the male slope is per gram.
Use Poisson regression for the offspring count, with testosterone as a predictor. It models a nonnegative integer response through its conditional mean. If the conditional variance substantially exceeds that mean, a negative binomial regression is a possible alternative for overdispersion.
Use the log link:where is the offspring count and is testosterone concentration. This link function keeps the fitted conditional mean positive.
A one-unit increase in testosterone concentration, here , multiplies the expected offspring count by under the Poisson regression with a log link. Thus the exact percentage change in the conditional mean is . The regression coefficient itself is the change in the logarithm of the expected count, not an additive change in offspring number.
Each observation has normal distribution probability density functionThe observations are independent and identically distributed, so their joint probability density function, viewed as a function of the unknown mean, is the product:Independence justifies multiplication; the common mean and known unit variance justify using this same density factor for every observation.
TODO: Complete the data-specific numerical results and diagnostics when the original
Iris_data.csv is available.The estimate requested is the sample mean, . The named electronic file
Iris_data.csv is not present in the supplied source archive or this repository, and its measurements are not printed in the paper. Consequently its numerical sample mean cannot be recovered from the paper alone. The familiar built-in iris data must not be silently substituted: the question does not identify those observations as its sample.The following R code reads the actual file and prints its sample mean. The later code blocks in Question 2 continue this same script and use the resulting
x, n and xbar.dat <- read.csv("Iris_data.csv", check.names = FALSE)
# Recognize common labels, or a single measurement column.
keys <- tolower(gsub("[^[:alnum:]]", "", names(dat)))
j <- which(keys %in% c("sepallength", "sepallengthcm", "x"))
if (length(j) == 0L && ncol(dat) == 1L) j <- 1L
if (length(j) != 1L) {
stop("Select the sepal-length column explicitly after inspecting names(dat).")
}
x <- dat[[j]]
stopifnot(is.numeric(x), length(x) > 0L, all(is.finite(x)))
n <- length(x)
xbar <- mean(x)
cat("n =", n, " sample mean =", format(xbar, digits = 12), "\n")This reader assumes a header row and one observation per row. An alternative layout should be identified explicitly rather than dropping measurements or treating an identifier column as a length.
TODO: Complete the data-specific numerical results and diagnostics when the original
Iris_data.csv is available.The identityshows that the likelihood function is a bell-shaped curve in , maximized at the sample mean, with width . Its actual vertical scale also depends on the within-sample sum of squares.
Continue the R script with:
sse <- sum((x - xbar)^2)
loglik <- function(mu) {
  -n/2 * log(2*pi) - 0.5 * (sse + n * (mu - xbar)^2)
}
grid <- seq(3, 6, length.out = 2001L)
ell <- loglik(grid)
png("q2-likelihood.png", width = 900, height = 600)
par(mar = c(4.5, 4.5, 4, 1))
if (max(ell) > log(.Machine$double.xmin)) {
  plot(grid, exp(ell), type = "l", xlab = expression(mu),
       ylab = expression(L(mu)), main = "Likelihood on [3,6]")
} else {
  # Explicitly label a proportional likelihood if the true scale underflows.
  plot(grid, exp(ell - max(ell)), type = "l", xlab = expression(mu),
       ylab = "Likelihood relative to maximum on plotted grid",
       main = "Likelihood on [3,6] (rescaled)")
}
abline(v = xbar, col = "steelblue", lty = 2)
dev.off()
Working first with the log-likelihood avoids premature numerical underflow. The fallback preserves the shape on the requested interval and labels the altered scale. A data-specific plot requires the missing CSV file; no fabricated observation set is used here.
The exponential distribution prior has rate and support , so its prior density is . By Bayes' theorem,where is a normalizing constant independent of .
Completing the square gives a useful exact reference for the numerical sampling. PutThen this normal mean posterior with an exponential prior is a normal distribution with location and variance , truncated below at zero. With the standard normal distribution density and its cumulative distribution function,The exponential rate is , not three; the prior mean is three. The support restriction must be retained in both the formula and the sampler.
TODO: Complete the data-specific numerical results and diagnostics when the original
Iris_data.csv is available.Use the random-walk Metropolis algorithm with proposal , where . The proposal is symmetric, so for a nonnegative proposal the acceptance probability isNegative proposals are rejected. They are not redrawn until positive, since that would change the proposal kernel and require a different acceptance ratio. On rejection, store the current state again; keeping accepted moves alone would bias the empirical posterior distribution.
set.seed(20240528)
B <- 10000L
mu <- numeric(B + 1L)
mu[1L] <- 4
logpost <- function(u) {
  if (!is.finite(u) || u < 0) return(-Inf)
  loglik(u) - u/3
}
lp <- logpost(mu[1L])
accepted <- 0L
for (i in seq_len(B)) {
  proposal <- rnorm(1L, mean = mu[i], sd = 1)
  lp_new <- logpost(proposal)
  if (log(runif(1L)) < min(0, lp_new - lp)) {
    mu[i + 1L] <- proposal
    lp <- lp_new
    accepted <- accepted + 1L
  } else {
    mu[i + 1L] <- mu[i]
  }
}
cat("Acceptance fraction =", accepted/B, "\n")
# A provisional discard; assess it with the trace in part (e).
burn <- 1000L
post <- mu[(burn + 2L):(B + 1L)]
m <- xbar - 1/(3*n)
s <- 1/sqrt(n)
posterior_density <- function(u) {
  ans <- numeric(length(u))
  ok <- u >= 0
  ans[ok] <- exp(dnorm(u[ok], m, s, log = TRUE) -
                   pnorm(m/s, log.p = TRUE))
  ans
}
png("q2-posterior.png", width = 900, height = 600)
hist(post, breaks = 40, probability = TRUE, xlab = expression(mu),
     main = "Retained Metropolis draws and exact posterior")
u <- seq(0, max(post) + 3*s, length.out = 4001L)
lines(u, posterior_density(u), col = "firebrick", lwd = 2)
dev.off()
The exact truncated normal distribution density overlays the histogram as a check; it does not replace the requested Markov chain Monte Carlo procedure. The 9,000 retained states exclude the initial state and the first 1,000 transitions. The particular histogram and acceptance fraction remain dependent on the missing measurements.
TODO: Complete the data-specific numerical results and diagnostics when the original
Iris_data.csv is available.Plot all 10,001 stored states, including the initial value, and indicate the provisional burn-in boundary. Also display the retained chain's autocorrelation function:
png("q2-trace.png", width = 1000, height = 700)
par(mfrow = c(2, 1), mar = c(4, 4.5, 2.5, 1))
plot(0:B, mu, type = "l", xlab = "Iteration", ylab = expression(mu),
     main = "Complete Metropolis trace")
abline(v = burn, col = "firebrick", lty = 2)
abline(h = m, col = "steelblue", lty = 3)
acf(post, main = "Autocorrelation after provisional burn-in")
dev.off()
# Check sensitivity to the chosen discard and to the retained time window.
for (discard in c(500L, 1000L, 2000L)) {
  kept <- mu[(discard + 2L):(B + 1L)]
  cat("Discard", discard, ": posterior mean", mean(kept), "\n")
}
cat("Means of retained halves:", mean(post[1:4500]),
    mean(post[4501:9000]), "\n")
A satisfactory trace plot should show an initial transient, if any, followed by repeated exploration of one stable range with no continuing drift. Repeated values are expected because rejections are stored. If is large, the prescribed proposal standard deviation one can be much wider than the posterior scale , giving low acceptance and conspicuous plateaus. A flat-looking trace is therefore not by itself evidence of good exploration.
Compare the retained histogram with the exact posterior density, inspect autocorrelation, compare separate retained windows, and assess sensitivity to the discarded count. Agreement supports the adequacy of this run; neither 10,000 iterations nor a chosen burn-in of 1,000 proves convergence. The effective sample size of a Markov chain can be much smaller than the number of stored states.
The actual trace cannot be diagnosed without
Iris_data.csv. The code produces the required trace when the measurements are available; the comments here specify what to examine rather than asserting an unseen chain has converged.TODO: Complete the data-specific numerical results and diagnostics when the original
Iris_data.csv is available.Estimate the posterior mean by averaging the retained states:The exact truncated normal distribution reference isFor a posterior well separated from zero, the truncation correction is tiny and the posterior mean is approximately , slightly below the sample mean.
The R continuation prints the Monte Carlo estimator, its approximate batch-based Monte Carlo standard error, and the exact value for comparison:
posterior_mean_mc <- mean(post)
posterior_mean_exact <- m + s * exp(dnorm(m/s, log = TRUE) -
                                    pnorm(m/s, log.p = TRUE))
# Nonoverlapping batches account approximately for serial dependence.
batch_length <- floor(sqrt(length(post)))
number_batches <- floor(length(post)/batch_length)
used <- post[seq_len(batch_length * number_batches)]
batch_averages <- colMeans(matrix(used, nrow = batch_length))
mcse <- sd(batch_averages)/sqrt(number_batches)
cat("Posterior mean, MCMC =", posterior_mean_mc,
    " approximate MCSE =", mcse, "\n")
cat("Posterior mean, exact =", posterior_mean_exact, "\n")
The batch length must be long enough relative to the chain's dependence for this uncertainty estimate to be reliable. No numerical data-specific posterior mean is determined by the supplied paper alone.
Treat as a prescribed input protein concentration, and as the downstream gene-product concentrations. Define the Hill activation functionA minimal model with no basal expression isHere are maximal production rates, are Hill constants with the same units as , and are dimensionless Hill coefficients. The negative terms describe a first-order reaction for loss of each gene product, with both rate constants set to one in the chosen time units. Thus have units of concentration per time and the unit loss rates have units of inverse time.
The equations model regulation of gene expression at the level of its effective protein output, without separate messenger RNA dynamics. The independent branches mean that neither nor regulates the other in this initial model. Additive basal production could be included, but is not required by the question and is set to zero throughout this example.
For a constant , set both ordinary differential equation derivatives to zero:These equilibrium concentrations are unique for each input. For a loss rate other than one, divide the corresponding production term by .
Choose , , and , , . The following Python code plots the requested equilibrium concentrations and defines the functions used in part (c):
import numpy as np
import matplotlib.pyplot as plt

def hill(u, K, n):
    u = np.asarray(u)
    return u**n / (K**n + u**n)

X_grid = np.linspace(0, 5, 501)
Y_eq = 2 * hill(X_grid, 1, 2)
Z_eq = 3 * hill(X_grid, 2, 4)
plt.figure(figsize=(6, 4))
plt.plot(X_grid, Y_eq, label="Y equilibrium: K=1, n=2")
plt.plot(X_grid, Z_eq, label="Z equilibrium: K=2, n=4")
plt.xlabel("X concentration")
plt.ylabel("Equilibrium concentration")
plt.legend()
plt.tight_layout()
plt.show()
The Hill constant sets the half-maximum input: and . Increasing that constant shifts activation toward larger . The Hill coefficient changes steepness rather than the half-maximum position; the normalized slope at is . Because the two examples also differ in and maximal production, compare normalized responses when isolating the effect of alone. Both curves vanish at zero and saturate toward their respective maxima.
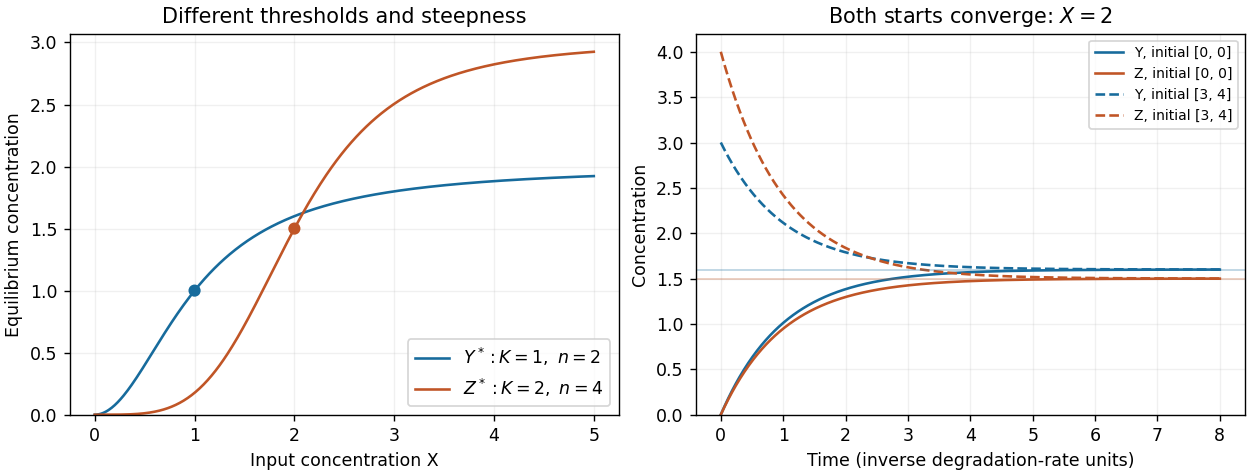
Independent Hill activation and convergence from two initial states
. The left panel shows different half-activation inputs and Hill coefficients. The right panel integrates the two independent output equations at fixed X=2; dashed curves start above equilibrium and solid curves start at zero. Details.
At a fixed input the production terms are constant, so both linear ordinary differential equations can also be solved exactly:Each displacement from its equilibrium concentration decays with time constant one. The Jacobian matrix is , with two eigenvalues equal to , so the fixed point is globally asymptotically stable for the nonnegative state space.
Here is a numerical solver using the classical fourth-order Runge-Kutta method; it uses only the repository's existing NumPy and matplotlib dependencies. Continue the definitions from part (b):
def integrate(rhs, initial, times):
    out = np.empty((len(times), len(initial)))
    out[0] = initial
    for j, dt in enumerate(np.diff(times)):
        state = out[j]
        k1 = rhs(state)
        k2 = rhs(state + dt*k1/2)
        k3 = rhs(state + dt*k2/2)
        k4 = rhs(state + dt*k3)
        out[j+1] = state + dt*(k1 + 2*k2 + 2*k3 + k4)/6
    return out

def direct_rhs(state, X):
    Y, Z = state
    return np.array([2*hill(X, 1, 2) - Y,
                     3*hill(X, 2, 4) - Z])

times = np.linspace(0, 8, 801)
plt.figure(figsize=(7, 4))
for initial, style in [([0, 0], "-"), ([3, 4], "--")]:
    trajectory = integrate(lambda s: direct_rhs(s, 2), initial, times)
    exact = np.array([1.6, 1.5]) + (np.array(initial) - [1.6, 1.5]) \
            * np.exp(-times[:, None])
    assert np.max(np.abs(trajectory - exact)) < 1e-8
    plt.plot(times, trajectory[:, 0], style, label=f"Y, initial {initial}")
    plt.plot(times, trajectory[:, 1], style, label=f"Z, initial {initial}")
plt.xlabel("Time")
plt.ylabel("Concentration")
plt.legend()
plt.tight_layout()
plt.show()
For , . The initial state approaches those values from below, while approaches from above. Over eight time units the initial displacement is reduced by , explaining why both trajectories nearly coincide with the equilibria from part (b). The two-panel figure above displays these simulations.
Add the activating link from to and multiply the two Hill activation functions for the target:The extra Hill constant has units of concentration and is its Hill coefficient. Both inputs are required for substantial target production: if either is zero, the production term for vanishes. This all-activating circuit is a coherent feed-forward loop. A product of graded input functions implements the specified AND rule; it is a phenomenological rule rather than a complete molecular promoter model.
Retain the parameter values of parts (b) and (c), and set , . Continue the same Python script with the altered right-hand side:
def and_rhs(state, X):
    Y, Z = state
    return np.array([2*hill(X, 1, 2) - Y,
                     3*hill(X, 2, 4)*hill(Y, 1, 4) - Z])

times = np.linspace(0, 10, 1001)
plt.figure(figsize=(7, 4))
for X in [1, 3]:
    trajectory = integrate(lambda s: and_rhs(s, X), [0, 0], times)
    plt.plot(times, trajectory[:, 0], "--", label=f"Y, X={X}")
    plt.plot(times, trajectory[:, 1], label=f"Z, X={X}")
plt.xlabel("Time")
plt.ylabel("Concentration")
plt.legend()
plt.tight_layout()
plt.show()
At , and . At , and . In both simulations first accumulates and opens the additional gate; therefore initially grows more slowly than under direct activation alone. The equilibrium concentration of is unchanged by the added outgoing interaction.
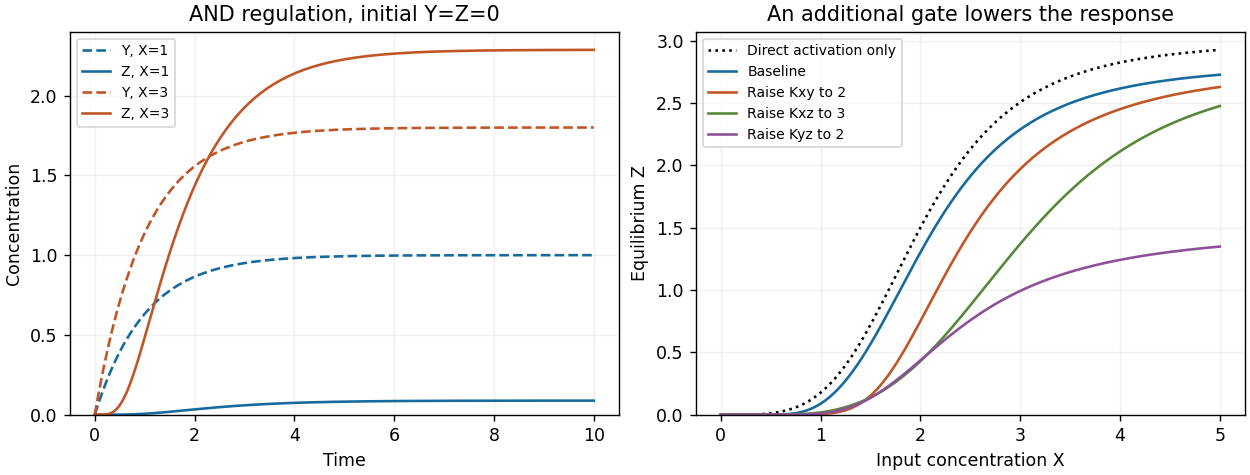
AND feed-forward dynamics and the effect of activation thresholds
. The left panel compares fixed inputs X=1 and X=3 from the zero state. The right panel compares the full feed-forward equilibrium response with direct activation alone and with individual Hill constants increased. Details.
The quasi-steady-state approximation for sets . Substituting into the equation givesIts equilibrium concentration is thereforeFor constant input this is also the exact equilibrium of the full two-variable model: the fast- assumption is needed to replace the transient dynamics, not to calculate a fixed point.
Relative to the direct-activation result, . The extra activation gate suppresses the response at low input and can sharpen its rise. The high-input limit is , which need not reach because saturates at .
For the parameters in part (d), the following Python continuation plots the expression and changes each Hill constant separately:
def z_equilibrium(X, Kxy=1, Kxz=2, Kyz=1):
    Yeq = 2 * hill(X, Kxy, 2)
    return 3 * hill(X, Kxz, 4) * hill(Yeq, Kyz, 4)

X_grid = np.linspace(0, 5, 501)
plt.figure(figsize=(7, 4))
plt.plot(X_grid, 3*hill(X_grid, 2, 4), ":", label="Direct activation")
for parameters, label in [((1, 2, 1), "Baseline"),
                          ((2, 2, 1), "Kxy=2"),
                          ((1, 3, 1), "Kxz=3"),
                          ((1, 2, 2), "Kyz=2")]:
    plt.plot(X_grid, z_equilibrium(X_grid, *parameters), label=label)
plt.xlabel("X concentration")
plt.ylabel("Equilibrium Z")
plt.legend()
plt.tight_layout()
plt.show()
Increasing lowers at fixed finite , delaying opening of the indirect gate. Increasing delays opening of the direct gate. Neither changes the limiting response as , provided the constants remain finite. Increasing makes a given less effective and also lowers the high-input plateau. These changes are visible in the preceding figure. At small , the response is proportional to , while both gates are far below saturation, explaining the increased low-input suppression.
For a persistence detector, retain finite dynamics and use, for example,with unit loss rates, , , and initially . On switching the input on, andThe time to reach the half-activation threshold of the indirect gate isAn isolated input pulse of duration ends well before this threshold; a duration-four pulse persists long enough to open the gate. The large but finite Hill coefficient makes this a graded filter, not a perfectly sharp cutoff. Once vanishes, its direct gate closes immediately and stops production of , which then decays with time constant one. The protein output itself does not drop discontinuously. This delayed-on, prompt-production-off mechanism is the characteristic persistence detector interpretation of an AND-type coherent feed-forward loop.[ref]
Structure and function of the feed-forward loop network motif by Shmoolik Mangan and Uri Alon. p. 11981, Equations for Gene Regulation Reactions; pp. 11983–11985, coherent FFL kinetics and Coherent FFLs as Persistence Detectors
This final Python continuation simulates both pulse durations. Each discontinuity is placed on the time grid and the input is held constant within each integration step:
def persistence_rhs(state, X):
    Y, Z = state
    return np.array([hill(X, 1, 4) - Y,
                     hill(X, 1, 4)*hill(Y, 0.7, 8) - Z])

def pulse_trajectory(duration, dt=0.005):
    times = np.arange(round(8/dt) + 1) * dt
    out = np.zeros((len(times), 2))
    for j in range(len(times)-1):
        X = 2.0 if 1 <= times[j] + dt/2 < 1 + duration else 0.0
        # Each step is integrated with its constant input.
        out[j+1] = integrate(lambda s: persistence_rhs(s, X),
                             out[j], [0, dt])[-1]
    return times, out

fig, axes = plt.subplots(1, 2, figsize=(10, 4))
for duration in [0.25, 4]:
    times, out = pulse_trajectory(duration)
    axes[0].plot(times, out[:, 0], label=f"Y, duration {duration}")
    axes[1].plot(times, out[:, 1], label=f"Z, duration {duration}")
    print(duration, "maximum output", out[:, 1].max())
axes[0].axhline(0.7, color="black", linestyle=":")
for ax in axes:
    ax.set_xlabel("Time")
    ax.set_ylabel("Concentration")
    ax.legend()
plt.tight_layout()
plt.show()
The chosen example produces peak of about for the short pulse and for the long pulse. These are original illustrative simulations, not fitted experimental measurements.
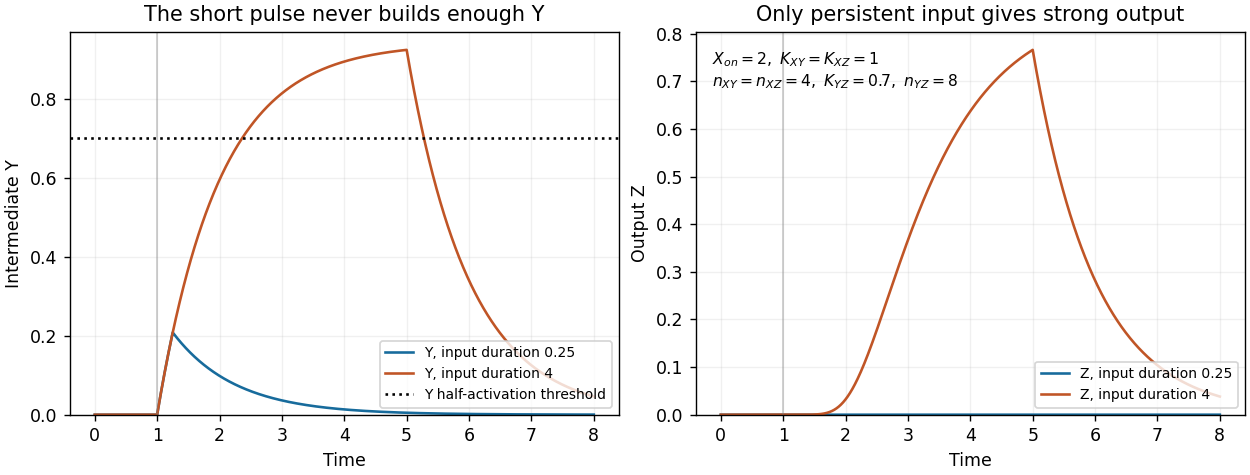

Finally, the strict instantaneous- reduction used for the equilibrium calculation has no separate intermediate accumulation delay. Its remaining one-variable dynamics can still attenuate short pulses through ordinary output relaxation, but it cannot demonstrate the additional delay caused by finite buildup. The pulse test therefore uses the full two-variable model.
Articles by others on the same topic
There are currently no matching articles.