Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Relative entropy nonnegativity
Information projection Created 2026-09-24 Updated 2026-10-14
An information projection chooses the probability distribution that satisfies a constraint while departing least from a reference law in relative entropy. The constraint might specify an expected value, several marginal probability distributions, or another convex set of permissible laws. The reference is held fixed: the variable is the first argument of . Reversing the arguments gives a different minimization problem.
For a finite alphabet , take a positive reference probability mass function and a nonempty closed convex set in the probability simplex. ThenThe minimum exists and its minimizing probability distribution is unique. In this article, natural logarithms give nats. Using base-two logarithms rescales the objective without changing the minimizer.[ref]
Information Theory and Statistics: A Tutorial by Imre Csiszár and Paul C. Shields. §3, printed pp. 440–441: finite-alphabet information projection onto a closed convex set
If already meets the constraint, its information projection is itself by relative entropy nonnegativity. If not, a constraint can change the relative weights of outcomes without specifying every weight individually. Relative entropy minimization under a mean constraint gives an especially useful example: it tilts the reference law rather than choosing an arbitrary distribution with the right average.
Kullback-Leibler divergence Created 2026-09-24 Updated 2026-10-14
The Kullback-Leibler divergence, also called relative entropy, compares two probability distributions in a specified order. In , observations follow and the comparison probability distribution is : the first argument supplies the averaging weights. For probability mass functions on a finite alphabet,Here is a random variable with probability distribution . For probability density functions relative to the same measure , replace the sum by . These formulas use natural logarithms unless stated otherwise. The expected value is under , even though appears in the denominator. [ref]
Take and on two outcomes. Direct calculation givesThe second outcome contributes negatively to the first sum: assigning it more probability than does makes its individual contribution negative. Nevertheless, relative entropy nonnegativity guarantees a nonnegative total. Reversing the arguments changes both the likelihood ratio and the averaging probabilities; taking an absolute value inside the logarithm would define a different quantity.
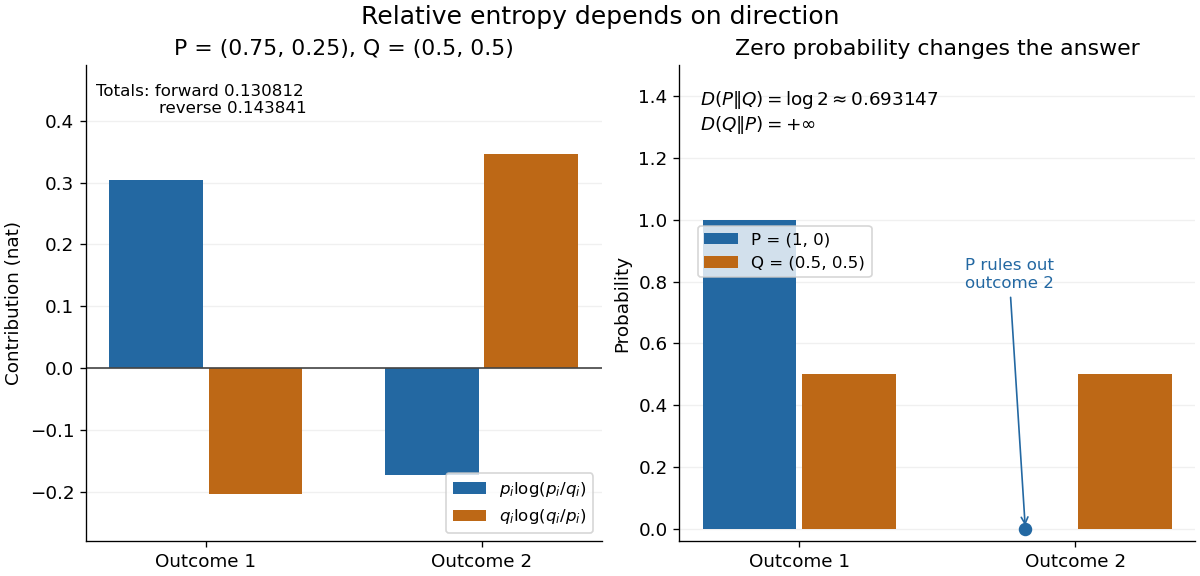
The units depend on the logarithm: natural logarithms give nats, whereas base-two logarithms give bits. Divide a value in nats by to obtain bits; the forward example is approximately bits. Changing the base rescales every Kullback-Leibler divergence by the same positive factor. Since the two calculated directions differ, Kullback-Leibler divergence is asymmetric and cannot be a metric. It also need not satisfy the triangle inequality. [ref]
https://web.stanford.edu/~kedart/ee376a_winter1617/Lecture_3.pdf. Tse, relative entropy, 2017, Section 3.3
The operational meaning is an expected penalty for using the wrong probability distribution. A prediction incurs log-loss when outcome occurs, the negative of the logarithmic scoring rule. Under , its expected value is the cross-entropy . Predicting with itself incurs information entropy , soThus Kullback-Leibler divergence is exactly excess expected log-loss, whenever these separate quantities are finite. [ref]
https://web.stanford.edu/class/ee276/files/previous_notes/lecture_2.pdf. Weissman, information measures, 2024, property 3
For lossless source coding, ideal codeword lengths similarly give excess expected length in bits per symbol. Actual prefix codes require integer codeword lengths; Shannon's source coding theorem explains how long blocks approach ideal per-symbol lengths. The interpretation concerns an average, not a fractional physical bit attached to every outcome. In our example, ideal coding with costs one bit per symbol, while bits; the difference is exactly the computed bits. [ref]
https://web.stanford.edu/~kedart/ee376a_winter1617/Lecture_3.pdf. Tse, information theory, 2017, Section 3.4
Zeros require explicit conventions. An outcome with contributes zero, including when ; the convention agrees with the relevant limit. If but , the Kullback-Leibler divergence is infinite: the predictor has declared impossible an outcome that can occur. On a finite alphabet, the probability support of must therefore be contained in the probability support of for a finite answer. For example, and give , but . For general probability measures, failure of absolute continuity of measures likewise gives infinity. Even does not guarantee a finite integral. [ref]
https://arxiv.org/pdf/1206.2459. van Erven and Harremoës, Rényi Divergence and Kullback-Leibler Divergence, 2014, Section II
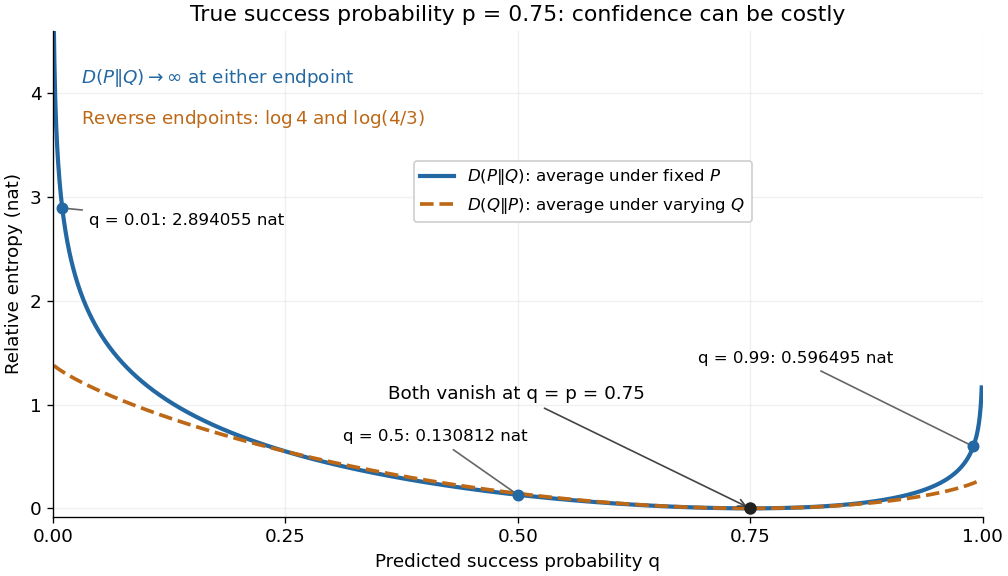
To see how confidently wrong predictions are punished, hold the true Bernoulli distribution parameter at and vary the predicted parameter . Its binary relative entropy isIt vanishes at , equals approximately nats at , and equals nats at . Both endpoints give infinity because both outcomes remain possible under . Predicting almost no successes is especially costly because successes actually occur three quarters of the time. The reversed binary relative entropy stays finite at the endpoints: its averaging probability distribution concentrates on just one outcome, and assigns positive probability to both.


For model selection, minimizing expected log-loss ranks candidate statistical models by , since is common to them. The true probability distribution is usually unknown, so one estimates predictive performance using fresh observations or cross-validation. Fitting and assessing on the same data can reward overfitting; a small fitted Kullback-Leibler divergence alone does not establish useful prediction.
In variational inference, a tractable trial probability distribution commonly minimizes against a target posterior distribution . Maximizing the evidence lower bound accomplishes this without evaluating the target's normalization constant. The averaging now follows : placing trial probability where the posterior distribution assigns almost none is strongly penalized. The chosen direction and trial family therefore matter. [ref]
https://www.cs.columbia.edu/~blei/papers/BleiKucukelbirMcAuliffe2017.pdf. Blei, Kucukelbir and McAuliffe, Variational Inference: A Review for Statisticians, 2017, Section 2.2
These comparisons do not by themselves establish causal inference. Two statistical models can reproduce the same observed probability distribution while predicting different responses to an intervention. Choosing the smaller Kullback-Leibler divergence therefore needs additional assumptions or experimental evidence before supporting a causal claim. [ref]
https://ftp.cs.ucla.edu/pub/stat_ser/r350.pdf. Pearl, Causal inference in statistics: An overview, 2009, Section 2
The original reference is S. Kullback and R. A. Leibler's 1951 paper [ref]
https://doi.org/10.1214/aoms/1177729694. On Information and Sufficiency
, published in The Annals of Mathematical Statistics 22(1), pages 79–86. Its title connects this comparison with sufficient statistics: the historical setting was statistical information, before today's widespread applications in prediction and variational inference. Past exam of the information theory course of the University of Oxford 2021 1 a ii Solution 2026-10-25
Expand the two observations in order using the chain rule for mutual information:The remaining conditional mutual information isRelative entropy nonnegativity proves the inequality. Equality requires every positive-weight relative entropy to vanish, which is equivalent to for every of positive probability. Thus equality holds exactly when and have conditional independence given . No unconditional independence is required.
For the maximum entropy distribution on the nonnegative integers, use the geometric distribution counting failures before the first success. Write and defineThe geometric series gives . Termwise differentiation of a power series applied to that geometric series for gives , hence .
For any competing probability mass function of mean , its cross-entropy against isThis is finite. The fact that finite cross entropy bounds countable information entropy must be justified without assuming in advance that is finite. Use with when . Including zero terms by their limiting convention yields, for every finite ,Let . The information entropy partial sums increase, the cross-entropy partial sums converge to the finite value above, and the final mass difference tends to zero. This proves finiteness and the upper bound. We may now writeRelative entropy nonnegativity has equality exactly when . Therefore the displayed geometric probability mass function is the unique maximizer, andThe mean constraint is essential: without it, uniform distributions on longer initial intervals have unbounded information entropy.
Past exam of the mathematics course of the University of Cambridge 2002 iii Paper 77 1 Solution Created 2026-10-03 Updated 2026-10-14
Let and let the daily distances be independent and identically distributed random variables with probabilities , . The unconditioned mean daily distance is , whereas the observed trip requires a daily average near . Conditioning on that rare average changes the typical frequencies substantially. It does not determine an exact boost count.
Use the method of types: for a fixed finite alphabet, the probability of an empirical distribution iswhere is relative entropy, using natural logarithms. This follows directly from Stirling's approximation. There are only polynomially many types, so the empirical distribution conditional on a mean constraint concentrates at its unique relative entropy minimizer, when admissible lattice types approximate that minimizer. Any fixed neighborhood of it has a strictly smaller minimum cost than its complement.
Minimize subject to and . The entropy minimization under a prescribed sample mean gives the exponential tiltingTo verify minimization without relying only on Lagrange multipliers, any feasible distribution satisfiesRelative entropy nonnegativity makes the unique minimizer. Its mean determines through , orThe derivative of the tilted mean is the tilted variance, which is strictly positive. The mean rises from at to as , so this equation has one positive solution. Numerically,The predicted boost count is . Thus the conditional large-deviation estimate is about 382 boosts.
For exact arrival at total distance , let count days of distances . The constraints giveConsequently can be any even integer from to . In particular, a unique count cannot be inferred from the return time. The exact conditional weights are proportional toTheir most probable count is , consistent with the exponential tilting calculation. This finite-sample inference is a conditional probability statement, not an assertion that all journeys with the stated duration have that count.
If returning home means first crossing the distance threshold on day , the final total instead lies between and . The last increment must exceed the overshoot; for fixed counts this selects the corresponding fraction of possible last days. Near the tilted optimum that factor is bounded away from zero, so it does not alter the leading exponential type cost. The same approximate answer follows. Exact conditional enumeration of this first-arrival interpretation also has mode .
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 8 3 c Solution Created 2026-10-03 Updated 2026-10-06
In the one-dimensional unit-mass setting, put . Using the convention , the relative entropy isBecause , we can subtract inside the integral:This is relative entropy nonnegativity from the given scalar inequality. Its integrand vanishes only at , so zero relative entropy characterizes almost everywhere. The nonnegativity remains valid with value when entropy is not finite.
Let be a probability mass function on a finite alphabet with numerical outcomes . Prescribe a mean strictly between the smallest and largest outcomes. Exponential tilting giveswith chosen so that . For any other feasible law , direct substitution yieldsRelative entropy nonnegativity therefore proves optimality and uniqueness. At an extreme prescribed mean, feasible laws may have zero probabilities; a finite tilting parameter need not realize them, although a limit can.
Total correlation Created 2026-09-28 Updated 2026-10-14
Total correlation measures how much dependence is lost when a joint probability distribution is replaced by the product of its marginal probability distributions. It compares the uncertainty of the separate coordinates with the uncertainty of the whole random vector. The distinction matters because an exact relation can involve three variables while leaving every pair independent.
For random variables with finite alphabets, defineHere is information entropy, the entropy of the full random vector is joint entropy, and is relative entropy. Base-two logarithms give bits; natural logarithms give nats. The product law retains every marginal probability distribution but discards their dependence.[ref]
Information Theoretical Analysis of Multivariate Correlation by Satosi Watanabe. Abstract, printed p. 66: total correlation for the partition into individual variables
A positive joint probability guarantees positive marginal probabilities at that outcome, so the displayed relative entropy is finite in this finite-alphabet setting.For two variables, total correlation is exactly mutual information. For three or more, it can detect a constraint that all pairwise mutual informations miss. Relative entropy nonnegativity gives , with equality exactly when the coordinates are jointly independent random variables.
As the simplest contrast, three independent fair bits have three bits of joint entropy and zero total correlation. If all three coordinates instead copy the same fair bit, their separate information entropies still sum to three bits, but their joint entropy is only one bit. Their total correlation is therefore two bits. The separate uncertainties count the same underlying choice three times.