Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 73 2 iv Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
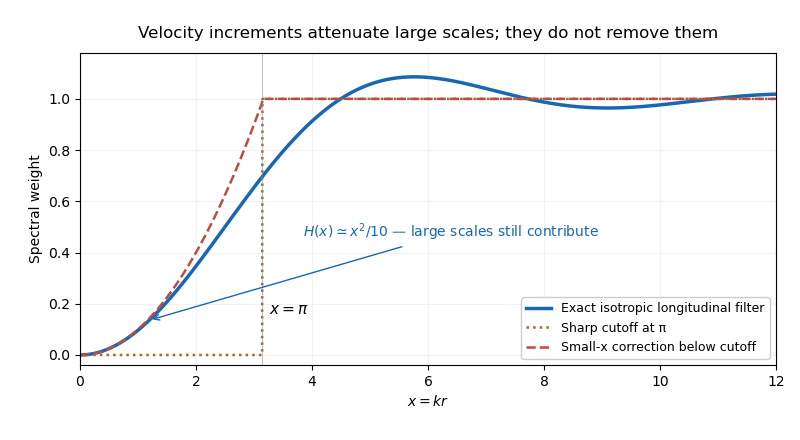
Write and normalize the turbulent energy spectrum by . In isotropic incompressible turbulence the longitudinal velocity correlation isCombining with gives the exact spectral filterThe expression has a smooth removable limit at . Its asymptotic forms areAn eddy much larger than contributes nearly the same velocity at the two points and mostly cancels in the increment. An eddy much smaller than contributes decorrelated velocities and does not cancel. Replacing the smooth transition of by a step at therefore gives the common estimate . The cutoff corresponds roughly to a half wavelength equal to the point separation; its exact numerical location is conventional.
Keeping the leading nonzero low-wavenumber term gives the improved estimateIt remains imperfect because is not small throughout the whole low-wavenumber interval and the exact kernel oscillates above the transition. The data sheet's alternative coefficient is a nearby approximate matching prescription; is the exact Taylor coefficient. Neither piecewise filter is an exact identity.
Higher-order longitudinal structure functions also retain large-scale information. Decompose , where varies on a length much larger than . Its longitudinal increment is , which is small but not zero. Expanding gives its own moments and mixed moments with the small-scale increment. Rare large gradients or correlated amplitude modulation can matter particularly strongly at large .
Thus a velocity increment is not an exact scale-local bandpass filter. Its moments may retain large-scale strain and forcing information, undermining an unqualified claim of universal small-scale statistics determined by one local parameter. This observation alone does not refute an asymptotic inertial range theory: for a three-dimensional spectrum, the low-wavenumber correction is mainly supplied by wavenumbers of order , while an isolated integral-scale smooth contribution behaves as and is subleading to . The issue is whether large-scale contamination and mixed moments actually become negligible in the regime and moment order being used.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 73 2 iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let and define a coarse-grained energy dissipation at scale , for example by a ball average,This is the random variable denoted . The refined similarity hypothesis uses the local supply of energy available to motions of size , rather than replacing it everywhere by a global mean. In its inertial range form,At high local Reynolds number, has a universal conditional distribution independent of , forcing details and within the inertial range. This givesFor signed odd orders the coefficients carry the appropriate sign; absolute moments use their own coefficients. Universality is retained in the normalized conditional velocity statistics, while the distribution of can retain integral-scale information. This distinction resolves the particular averaging objection: its nonuniversal viscous dissipation moments are now explicitly present.
The quoted second viscous dissipation moment does not by itself determine every longitudinal structure function exponent. The extra lognormal intermittency model assumes is Gaussian. Write its variance as . Normalization of the mean requires , soThe second-moment estimate gives . Hence, with ,In particular , and .
The most problematic step is the extrapolation of a lognormal viscous dissipation law to rare events and all moment orders. It is not entailed by a measured second moment. Its quadratic exponents eventually decrease with and become negative for . If the velocity has finite uniformly bounded moments, the bound prohibits such divergence as . Thus the model cannot be an unrestricted high-order inertial range law. This is a criticism of the lognormal closure, rather than an algebraic contradiction in refined similarity itself.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 73 2 ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For the Landau intermittency counterexample, combine two locally homogeneous turbulent populations, with the same sufficiently wide inertial interval but different viscous dissipation rates and . This can mean an ensemble randomly selected between two intensities, or large turbulent patches whose small-scale increments are sampled away from the patch boundaries. Suppose each population individually obeys the proposed universal coefficient . If their proportions are and , the combined longitudinal structure function isIts effective coefficient referenced to the global mean viscous dissipation is thereforeFor a concrete example let and , with . ThenFor this is , explicitly dependent on the strength of the large-scale modulation. For it is less than one by concavity. Thus coefficients based solely on mean viscous dissipation cannot be universal under arbitrary integral-scale intermittency. The common inertial interval can be maintained by taking both local Reynolds numbers sufficiently large.
At the ratio is exactly one. This exception is consistent with the signed third-order energy-flux law and must not be used to rescue universality of all other orders. For noninteger orders one uses absolute increments; the even-order examples already establish the counterexample without a sign convention ambiguity. The issue is the difference between a moment of the local viscous dissipation and the same power of its mean, not a failure of averaging itself.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 73 2 i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Internal intermittency is the uneven distribution of activity within an already turbulent fluid: intense gradients and viscous dissipation occupy relatively small, fluctuating regions separated by much quieter regions. It concerns the internal field, rather than a turbulent/non-turbulent interface intermittently passing a probe.
Integral-scale intermittency is the variability of the energy-containing eddies and their local or time-dependent energy supply. Its modulation occurs on lengths and times of order and , can depend strongly on forcing or initial conditions, and changes the background intensity experienced by smaller eddies.
Equilibrium-range intermittency concerns the increasing fluctuations of local transfer and viscous dissipation as the averaging scale is reduced below the integral scale of turbulence. It appears as non-Gaussian velocity-gradient statistics, fluctuating coarse-grained viscous dissipation and anomalous longitudinal structure function exponents. It includes the inertial range and its continuation into the dissipation range, where kinematic viscosity ultimately limits gradients. Large-scale modulation varies the local energy supply; small-scale intermittency concentrates and redistributes that supply. These effects can coexist, so they should not be identified simply because both broaden a distribution.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 73 1 v Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14In the Townsend-Betchov cascade cartoon, bi-axial strain sweeps distributed vorticity into extended sheets at the upper part of the inertial range. These are predominantly inviscid structures: their shape and instability arise from advection and strain rather than local viscous smoothing. Strong velocity variation across a thin sheet permits Kelvin-Helmholtz instability, roll-up and three-dimensional deformation. The resulting small vortex tubes are stretched into still finer cores.
At the dissipative end, stretching and kinematic viscosity balance in Burgers-like cores. A core of strain rate has radius of order ; taking gives the Kolmogorov length . Circulation and shrinking cross-section allow finite integrated tube viscous dissipation. Thus sheet formation and tube formation play different roles, rather than the entire cascade being a succession of identical geometrical eddies.
The cartoon challenges a literal, uniformly self-similar, step-by-step cascade with independent interactions only between neighboring scales. Large-scale sheet formation can generate much smaller scales through an instability, and the resulting structures retain coherent spatial organization. A branching model that assumes every scale-transfer step has the same geometry and loses information about the parent flow can miss this mechanism. Closures that erase the relevant phase correlations also have difficulty representing its concentrated gradients and intermittency. The objection is to these dynamical assumptions, not to conservation of energy or the existence of a mean energy flux through scales. The cartoon alone is not a proof that all spectral transfer is nonlocal.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 73 1 iv Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The high-Reynolds-number balance gives positive mean vortex stretching. The Betchov relation therefore gives . To connect this to a fixed longitudinal velocity derivative, additionally assume isotropic turbulence, or average over the direction of that derivative. For a unit vector , the derivative is . Uniform directional averaging, with , givesFor example these identities follow by averaging products of direction cosines on a sphere. Hence in isotropic turbulenceand division by the positive derivative variance to the power gives negative longitudinal velocity-gradient skewness. Homogeneity alone does not fix the orientation statistics and does not establish this sign for every chosen coordinate direction.
Order the principal strain rates as . Except at degeneracies, and , so corresponds to : two extensional directions and one compressive direction, or bi-axial strain. The negative average of says that such configurations dominate this cubic amplitude-weighted statistic over axial-extension configurations with . In the usual physical interpretation, comparably intense strain events are therefore biased toward bi-axial extension.
An unweighted frequency claim needs more information. As a counterexample to deducing it solely from the cubic average, assign strain eigenvalues to 10% of samples and to 90%, with randomly oriented eigenvectors. Then , despite bi-axial extension occurring in only 10% of the samples. This example addresses what the moment inequality can infer, not a construction of a complete turbulent velocity field. A measured frequency preference is a further statistical observation.
The geometric significance is that a fluid element stretches in two directions and contracts in the third, becoming sheet-like while preserving volume. Distributed vorticity is swept into thin layers and its component along an extensional direction is amplified. The associated shear layers can subsequently roll up and produce vortex tubes. Thus the weighted strain bias helps explain sheet formation in the energy cascade even though the most intense dissipative structures can be tubes.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 73 1 iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use , where is the rate-of-strain tensor and is antisymmetric. For incompressible flow . Since , taking a trace givesThis uses the positive convention specified here; a convention with the opposite sign for must not be mixed into the calculation. For a compressible flow there is an additional term , so the displayed incompressible formula is not literally valid for every flow.
One can exhibit the required divergence directly. DefineDifferentiating, terms containing vanish, and the two terms with a second derivative cancel after relabeling indices. Thereforein homogeneous turbulence with finite differentiable moments, or under periodic averaging. This is the Betchov relation. The preceding trace identity then impliesThe principal strain rates are the real eigenvalues of the symmetric matrix . Incompressibility gives , and the identity givesNo isotropy is required for this averaged tensor identity: statistical homogeneity and incompressibility are the key assumptions.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 73 1 ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For unforced incompressible flow, multiply the vorticity equation by . The antisymmetric part of the velocity gradient tensor drops out of , leavingStatistical homogeneity removes mean divergences. Integration by parts, together with , givesThe last equality holds for the averages, not pointwise. It follows from the usual curl/divergence identity after the divergence terms have averaged to zero. Vortex stretching produces enstrophy, while viscous diffusion destroys it.
Let , , and use the Kolmogorov microscales and . Since , a slowly changing mean enstrophy has a time derivative of order . The usual small-scale estimate givesThe relative imbalance is consequently , yieldingThe estimate assumes an established high-Reynolds-number cascade and integral-time evolution of the mean, not a rapid initial transient. In a forced flow the exact balance includes ; forcing smooth on the integral scale of turbulence is smaller than the leading small-scale terms.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 73 1 i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Work with an incompressible Newtonian fluid of constant kinematic viscosity. The vorticity equation is . In the axisymmetric Burgers vortex the swirl does not advect the axial vorticity, and the stretching rate is . Put and . The Gaussian profile hasSubstitution into matches both the constant and terms precisely whenFor every finite positive initial ,The strain compresses the cross-section and stretches its vorticity, while kinematic viscosity spreads the core. The attracting radius is the balance of these effects; its relaxation time is . Total circulation stays fixed because stretching increases the vorticity as the cross-sectional area decreases.
At the steady core radius, the swirl speed is of order , and its velocity gradient tensor is of order . Its viscous dissipation integrated over a cross-section therefore scales asThis is per unit length and per unit density. More precisely, for the swirl contribution, integration by parts relates the integrated strain viscous dissipation to ; the boundary term vanishes for the swirl velocity. ThusMultiply by density for power per physical length. Here the azimuthal velocity's circulation is , as follows by integrating over the cross-section. The result is finite as with strain and circulation held fixed. Local core viscous dissipation grows like while its area shrinks like . For , the swirl gradients dominate the background strain within the core.
This finite quantity is the excess viscous dissipation due to the vortex. The uniform straining flow alone dissipates per unit volume, and integrating that over an infinite cross-section diverges. The total viscous dissipation of the complete idealized flow is therefore not a finite tube power unless the background is subtracted or spatially bounded.
A Burgers vortex sheet instead smooths a fixed velocity jump across a layer of thickness . Its viscous dissipation per sheet area is of orderA tube with fixed circulation supports finite viscous dissipation in a vanishingly small core; a sheet with fixed velocity jump does not. This makes strained vortex tubes plausible intense dissipative structures at high Reynolds number. It does not assert that sheets are absent from turbulence: sheets can carry inertial range organization and become unstable, producing finer vortical structures.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 70 6 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The half-open translates partition the real line. Exactly one summand is therefore nonzero in the periodization of , giving .
Choose the Shannon scaling mask to be the -periodic extension of . On the support of , its product with is ; outside that support both sides vanish. Thus the scaling refinement equation holds in frequency. The Fourier coefficients give its precise filter normalization:These coefficients are square summable, so the interpretation in part (b) applies.
The Fourier inversion theorem gives the Shannon scaling functionThis is the normalized sinc function. Its Fourier transform is taken in the Plancherel theorem sense: the Shannon scaling function belongs to but not , so its Fourier integral is not absolutely convergent. The inverse integral above is an ordinary integral because the rectangular transform belongs to . The resulting refinement spaces are exactly the functions with Fourier transform supported in ; their union is dense and their intersection is zero. Thus this example also gives a full multiresolution analysis.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 70 6 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14An orthonormal multiresolution analysis consists of closed subspaces of a Hilbert space of the Hilbert space such thatThere is a scaling function whose integer function translations form an orthonormal basis of . Consequently form an orthonormal basis of ; in particular is invariant under integer function translations.
Let be the orthogonal complement of in . Nesting, density and the trivial intersection imply the orthogonal direct sumFor example, telescoping and letting , gives this decomposition; the corresponding orthogonal projections converge strongly to zero and the identity by the intersection and density properties.
To construct the orthonormal wavelet, use to write the scaling refinement equation , with and . Put . The orthonormal translates and Fourier periodization criterion proved in part (b), applied to the scaling refinement equation, yieldsThis is the quadrature mirror filter identity. DefineThe Fourier series of is , and . The two rows and form a unitary matrix almost everywhere: both have squared norm one and their inner product is zero. This wavelet completion of a multiresolution filter proves not just orthogonality but completeness. Splitting a finer-scale coefficient Fourier series into its values at and , this invertible two-channel matrix resolves it into a coarse-scale channel and its complementary channel. Thus the integer function translations of form an orthonormal basis of .
The dilated functions therefore form an orthonormal basis of each . The orthogonal direct sum proves the conclusion: every orthonormal multiresolution analysis produces an orthonormal wavelet basis of .
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 70 5 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14A strict diagonal dominance argument proves the estimate even on a nonuniform strictly increasing spline knot sequence. Put . Then has a rising piece of length and a falling piece of length , while . The same integrations as in part (b) give the linear-spline mixed Gram matrixOnly entries with indices in are present. Thus in every row.
For , choose an index with . The reverse triangle inequality then yieldsHence . Applying this to every provesThis is the inverse infinity-norm bound from diagonal dominance; no total positivity theorem is needed. The proof also gives invertibility directly by taking .
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 70 5 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For on an equidistant spline knot sequence, is the triangular hat with value one at and support . Its slopes on the two pieces are and , and . Direct integration givesNonadjacent hats have disjoint interiors of their supports, so their inner product vanishes. Dividing by therefore givesThis linear-spline mixed Gram matrix is tridiagonal. Every diagonal entry is , including the first and last: the distinct-knot hats have their full supports inside . End rows simply lack one off-diagonal neighbor; there are no repeated endpoint spline knots here.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 70 5 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The orthogonal projection has range , not all of : the latter is an infinite-dimensional vector space whereas is a finite-dimensional vector space. For a concrete counterexample, cannot belong to any finite-degree piecewise polynomial space, since all its derivatives are nonzero on every open interval. For , the B-splines are continuous, so the orthogonal projection is a map . For order one it instead has a generally discontinuous piecewise constant range. For example, a single interval indicator on is the projection of the constant function one onto its span, and is not continuous.
Write . Since is a positive scalar multiple of , the operator normal equations are equivalent toThe mixed-normalization spline Gram matrix is invertible: where and is the ordinary positive-definite matrix of inner products of a linearly independent basis. The positivity and unit-integral normalization of a B-spline give . The subpartition of unity for B-splines givesHere the operator norm of a matrix on is its maximum absolute row sum. Consequently,This proves the maximum-norm bound for spline projection.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 70 4 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The divided difference is a finite linear combination of spline knot values, so it commutes with the finite integral. For every spline knot in the defining interval,It follows thatbecause the order- divided difference of a monic degree- polynomial is its leading coefficient. This proves the unit-integral normalization of a B-spline.
For the partition of unity, let denote the partition-normalized order- B-spline. The Cox-de Boor recurrence isIt follows by substituting the explicit divided difference formula into both sides and collecting each truncated power function. The starting case is , with endpoint conventions irrelevant when . The two weights are nonnegative wherever their respective lower-order B-splines are nonzero. Induction therefore gives and strict positivity in its open support.
Extend the finite spline knot sequence strictly in both directions, with no finite accumulation. At each point only finitely many B-splines are nonzero. For the full extended family the sum is one for order one. Summing the Cox-de Boor recurrence, the combined coefficient of isInduction gives a full partition of unity at every order. On , all extended order- functions with index or vanish by their supports. HenceThe same argument gives the useful global subpartition of unity for B-splines, , including outside the basic spline knot interval.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 70 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use the usual strictly increasing spline knot sequence, and initially assume . The explicit formula for the order- divided difference givesEach summand is a truncated power function in , with its junction at . It is a piecewise polynomial function of degree at most and has continuous derivatives. Finite summation preserves these properties.
For all summands vanish. For , all spline knot data come from the polynomial . An order- divided difference annihilates a polynomial of smaller degree, so there too. Thus the support is contained in .
On the last open spline knot interval only the term survives; it is a nonzero multiple of . On the first open spline knot interval, compare the truncated spline knot data with the untruncated polynomial data: only the value differs. Since the untruncated divided difference is zero, the result is a nonzero multiple of . Consequently both outer pieces are nonzero, giving exact closed support. The Cox-de Boor recurrence used below also proves positivity throughout the open support. ThereforeThis is simple-knot B-spline regularity. For the B-splines are interval indicators; they are piecewise constant and need not be continuous. The notation should then be read as no continuity requirement, not as a classical negative-order differentiability space.
Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 70 3 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14 Past exam of the mathematics course of the University of Cambridge 2012 iii Paper 70 3 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The Weierstrass M-test gives uniform convergence and continuity of the series. For the proposed trigonometric polynomial, set and . The tail satisfiesAt , for , the integer is odd for every omitted frequency. Thus and . In particular .
Since , these points include at least consecutive alternating extrema in a single period. Also , so . The trigonometric Chebyshev alternation theorem proves that the proposed partial sum is the unique best approximant, withThis is an instance of positive lacunary trigonometric series: all omitted odd frequency ratios align their extrema.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact