A discrete probability distribution is a probability distribution concentrated on a finite or countable set of possible values : a random variable with this law satisfies . Its probability mass function assigns a probability to each value:Thus the probability of an event is obtained by adding masses, rather than integrating a probability density function. The possible values need not be equally spaced, or even integers. When the relevant moments are finite, its expected value and variance are
For a constructed example, assign values masses . They sum to one; , , and . Hence the variance is . A mean can lie between possible values: no outcome here equals .
The useful organizing question is what an experiment records. One yes/no indicator random variable gives a Bernoulli distribution; a success count in a fixed number of independent attempts gives a binomial distribution; the attempt number of the first success gives a geometric distribution. A Poisson distribution describes an event count under different assumptions. Naming the quantity first helps prevent selecting a familiar formula for the wrong experiment.
For , this probability distribution on positive integers has mass . The Taylor identity proves normalization. Its expectation is , by summing the geometric series after multiplying the mass by .
For an independent sample, the maximum-likelihood estimator solves the equation making this model mean equal to the sample mean. The model mean is strictly increasing: set to obtain , whose derivative is positive for . Hence a sample mean greater than one determines a unique interior estimate. Pooling several categories changes the likelihood and generally changes this estimate; the ungrouped sample mean is no longer recoverable from the pooled category counts alone.
For a positive random variable , let be its first nonzero base-ten digit. The Benford law is the discrete probability distribution with probability mass functionHere need not be an integer: , and all have . Multiplication by an integer power of ten changes the decimal point's position and leaves the first nonzero digit unchanged. Zero has no first nonzero digit, so exclude it. For negative inputs one may explicitly use their absolute values, still excluding zero; that convention must be stated rather than applying a logarithm to a negative number.
The Benford law favors small digits: , whereas . Thus the model assigns about to digit one and to digit nine. The masses are positive and their normalization is a finite telescoping series:
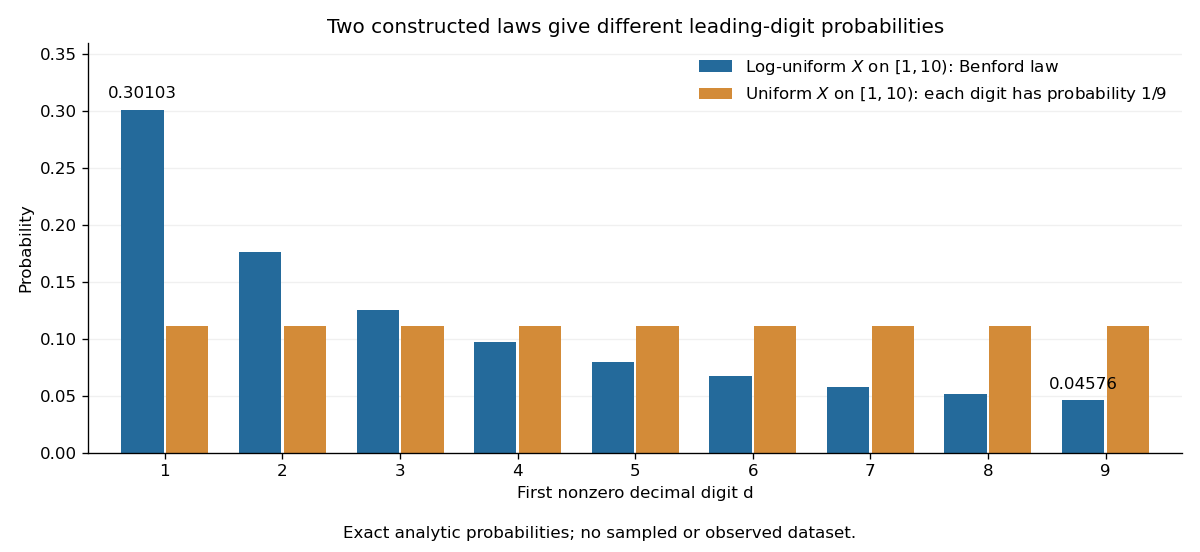
Why can digit one be so common? In a decimal significand interval , the digit-one region occupies a larger fraction of the logarithmic scale than the digit-nine region . The precise assumption is that the fractional part of the base-ten logarithm is distributed uniformly on ; Benford law from logarithmic uniformity turns those unequal interval lengths into probabilities. This makes a surprising digit pattern into a simple geometry of multiplicative size. The logarithmic explanation is also presented in Peter Sheridan Dodds, Benford's Law, essential story.
The Benford law is useful as a proposed model for leading digits when the mechanism supports logarithmic uniformity or an appropriate limiting argument, such as Benford frequencies for powers of an integer. Merely spanning many powers of ten does not establish that assumption. A discrepancy from the Benford law can prompt investigation of the model and data collection; by itself it does not establish fraud, and agreement does not establish authenticity.
Simon Newcomb's 1881 paper, Note on the Frequency of Use of the Different Digits in Natural Numbers, appeared in the American Journal of Mathematics 4, pp. 39–40. Its opening connects unequal leading-digit frequencies with the faster wear of early pages in logarithm tables. The publication metadata and original opening excerpt are available in Newcomb (1881), original publication record and [ref]
https://www.benfordonline.net/fullreference/414. Newcomb (1881), reproduced opening excerpt
. Frank Benford's The Law of Anomalous Numbers, Proceedings of the American Philosophical Society 78 (1938), pp. 551–572, likewise discusses worn logarithm tables on p. 551 and tabulates observations on p. 553. See Benford (1938), transcription of the original paper with page numbers and publication metadata. These observations motivated study of the digit pattern; they do not make the Benford law universal.A decimal significand lies in , obtained by removing the integer power of ten from a positive number. Multiplication by a constant rotates the fractional logarithm modulo one. Invariance under every such rotation makes the fractional logarithm uniform and hence implies Benford law. This is an invariant significand distribution, not a proper scale-invariant distribution for the entire positive number.
For , the decimal significand is the unique such that for an integer . Explicitly, and , using the floor function and the fractional part. For , and , the decimal significand is and the first nonzero digit is . In the classical terminology of logarithm tables, the logarithmic mantissa is , which differs from the decimal significand .
For a positive random variable , write its base-ten logarithm as an integer part plus a fractional part:The floor function handles values below one as well: for , and the decimal significand is . Since , the first nonzero decimal digit is . The monotonicity of the logarithm gives the exact event equivalenceIf has the uniform distribution on , the probability of this interval is its length. Consequently , proving the Benford law. This argument assumes uniformity of the fractional part of the logarithm, rather than uniformity of itself. See the logarithmic-coordinate explanation in Peter Sheridan Dodds, Benford's Law, essential story.
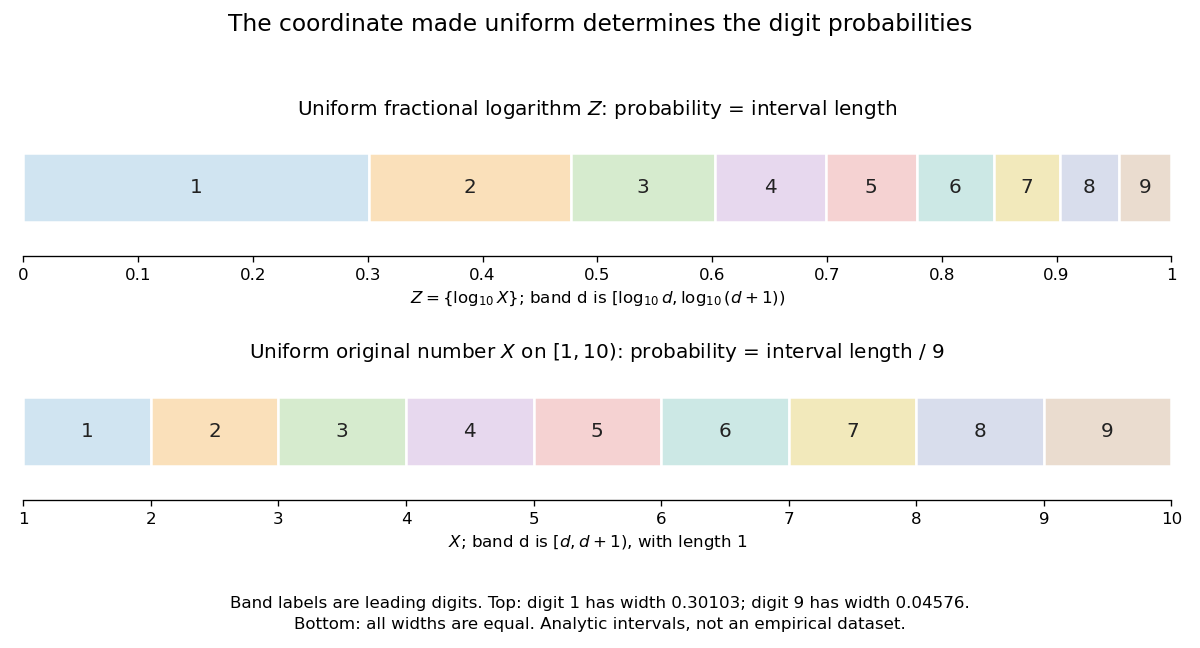
Leading-digit intervals have unequal lengths in the fractional logarithm and equal lengths in the original number
. Details. An exact constructed example is the log-uniform distribution on , with probability density function there and zero elsewhere. Its total mass is . The change of variables formula with gives for . Equivalently, integrating directly givesFor example, the probability of first digit four is . By contrast, an ordinary uniform distribution for on has probability density function there, so for every digit. This is a concrete counterexample to any claim that the Benford law holds for every positive random variable.
More generally, a log-uniform distribution on with has uniform on . If its logarithmic span is a positive integer, reduction to the fractional part wraps an interval of length around the unit interval exactly times, making uniform even when is not a power of ten. Arbitrary partial-decade truncations generally do not have this property: for a log-uniform distribution on , the first digit is always one.
Under the uniform fractional-logarithm assumption, multiplication by any constant replaces by . This is a rotation modulo one, which preserves the uniform distribution and therefore preserves the Benford law; see scale invariance of decimal significands. For the constructed example, multiplying by gives a log-uniform distribution on with the same digit probabilities. The claim concerns the decimal significand law: there is no proper probability density function proportional to over all of , since its integral diverges. The existing scale-invariant prior describes that unnormalizable measure, while a finite log-uniform distribution is normalizable.
If is an integer with irrational , then the leading digit of has limiting frequency . Indeed the logarithmic fractional parts are the orbit of zero under an irrational rotation of the circle, so everywhere interval frequency under an irrational rotation applies. Thus for , digit seven has frequency .
A discrete uniform distribution gives every element of a nonempty finite set the same probability. Write for its cardinality. A random variable with this law has support of a probability distribution and probability mass functionThe masses sum to . Conversely, if all masses equal , their sum is , so necessarily . Thus equal chances determine the whole law.[ref]
Counting now computes an event's probability: for any set of possible values,In particular, when , the answer is . The intersection matters: values outside the support of a probability distribution contribute zero. This turns a probability question into a combinatorics question, provided that equal chances are justified by the model.
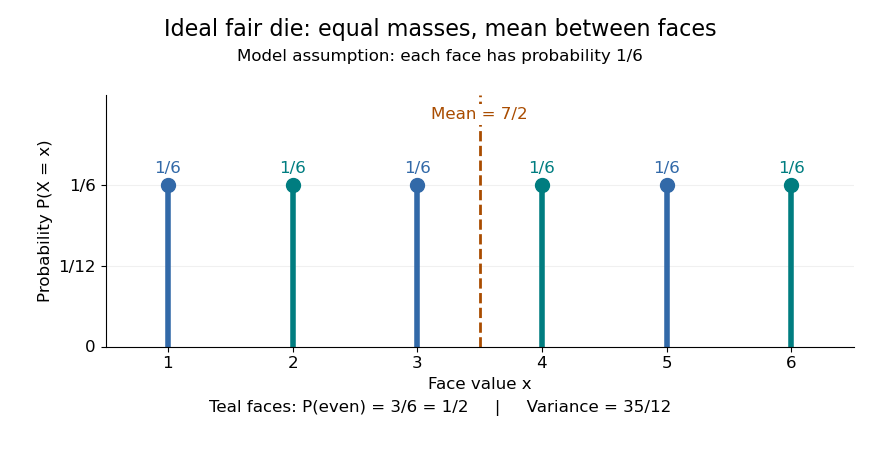
For an ideal fair six-sided die, and each face has probability . The event of an even integer is , so its probability is ; the event has probability . Direct summation gives the expected value and the variance . The mean is a balance point between possible outcomes. These are exact consequences of stipulated fairness, rather than measured frequencies from physical dice.
Uniformity describes probabilities, not distances between values. For a second constructed model, stipulate equal-chance selection from . Every value has probability , despite the unequal gaps . Here , while the expected value and variance areNeither the midpoint of the extreme values, , nor a formula using only the cardinality gives these moments. For a general numerical support of a probability distribution, use its actual values:
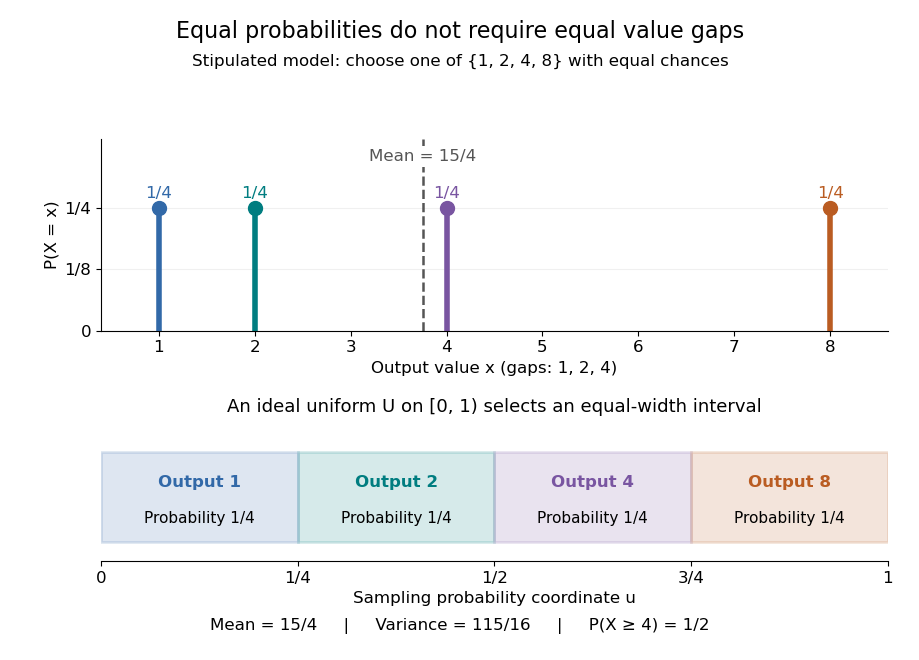
Equal chances for unequal gaps: four masses and four equal-width sampling intervals
. Details. Choosing an item from a finite list with equal chances is a basic building block of simple random sampling. A bijection that relabels the items preserves equal probabilities, although changing numerical labels can change the expected value and variance. A function that merges labels can destroy uniformity: for the fair-die model, has masses at , since four faces map to three. Always count the original equally likely outcomes.
An indicator random variable for membership in a set has a Bernoulli distribution with parameter ; counting that event over independent repetitions gives a binomial distribution with parameters and . Equal chances among individual values need not produce equal chances among aggregated counts.[ref]
Introduction to Probability, Statistics, and Random Processes by Hossein Pishro-Nik. §3.1.5, indicator random variables and binomial variables as sums of independent Bernoulli variables
Suppose the support of a probability distribution consists of all consecutive integers from to , including both endpoints, with . Its cardinality is , and a discrete uniform distribution on it satisfiesFor a short derivation, set , whose possible values are . The finite sums giveand henceAdding shifts the expected value by and leaves the variance unchanged. For completeness, the first sum follows by pairing with . For the second, sum from to : the left side is , so inserting the first sum gives the stated result.
The edge case has : with probability one, expected value , and variance zero. On an arithmetic progression with , the same argument instead gives expected value and variance . Equal spacing is the extra hypothesis behind these formulas; the discrete uniform distribution on requires the general sums above.
Let the numerical support of a probability distribution be . Its cumulative distribution function counts how many values have been passed:It is zero below , equals on for , and is one at and above . Every jump is , even when the horizontal gaps differ.
For inverse transform sampling, take an ideal continuous uniform distribution for on . Partition that interval into intervals of width and outputEach interval has probability , proving the desired discrete uniform distribution. Using the floor function, the index is ; for consecutive integer values the output is . With the usual quantile function convention , one instead writes for , using the ceiling function. The endpoint conventions differ only at a finite set of points with probability zero under the ideal continuous uniform distribution.
For , the four intervals , , , and select , respectively. Thus selects , while selects . The upper half of the interval selects values at least four, recovering probability . Equal widths refer to the sampling probability coordinate, not to distances between output values. This is an exact mathematical construction assuming an ideal continuous uniform distribution; a finite computer random-number source needs its own justification of equal output chances.
An ordered sample from equally likely values is nondecreasing exactly when it is the unique sorted representative of its multiplicities. Stars and bars counts the nonnegative multiplicities summing to ; repeated values are included automatically.
A Bernoulli random variable records one success as and one failure as . For , its probability mass function iswith zero mass elsewhere. The terms success and failure merely name outcomes; success need not be desirable. Any event produces such a variable through its indicator random variable , with . A single Bernoulli distribution requires no independence assumption; independence becomes relevant when several trials are combined.
Because , the expected value and variance follow immediately:For a constructed trial with , these are and . The variance is greatest at , where it equals , since . At or , the outcome is certain and the variance vanishes.
The beauty of an indicator random variable is that counting becomes addition: summing such indicators counts successes, and the linearity of expectation gives the expected count even when the indicators are dependent. With independence and a shared , the full count law is the binomial distribution. These models are summarized in Penn State STAT 504, discrete distributions.
A historical anchor is Bernoulli's posthumous Ars conjectandi: its original title page identifies the author and records publication at Basel in 1713. This documents the book's publication, rather than establishing priority for the modern name Bernoulli distribution. See Ars conjectandi, original title page, ETH Library.
On a cyclic sequence of independent Bernoulli random variables with success probability , count all runs of consecutive successes, allowing overlaps and taking . The count has expected value . Its variance is the displayed expression: each starting indicator has variance ; two starts at cyclic distance have joint probability ; nonoverlapping starts are independent. There are ordered overlapping pairs at each such distance, because the two ranges do not meet when .
For , summing a geometric series gives . Markov's inequality therefore proves absence with high probability when , and Chebyshev's inequality proves existence and relative concentration when . This remains valid for varying probabilities eventually at most one half.
A Bernoulli string is a finite sequence of independent binary digits, each taking value one with a specified probability. Unless stated otherwise, all positions use the same probability.
For independent Bernoulli observations with sum , the extended maximum-likelihood estimator is . Its unbiased improvement is , obtained by conditioning on . The Rao-Blackwell theorem gives strict variance reduction for . With a uniform prior on and squared-error loss for , the Bayes estimator is . For parameter space strictly , samples with or have only a boundary likelihood supremum, not an attained maximum.
A random experiment with two outcomes, success and failure, whose success indicator has a Bernoulli distribution. Repeated trials sharing success probability give a binomial distribution for their success count if they are independent conditional on ; integrating over an uncertain common generally makes the trials dependent marginally.
If an event occurs with probability and is independently retained with conditional probability , its retained indicator is Bernoulli with probability . Applying this independently to a binomial count turns into .
Consider successive independent Bernoulli trials with the same success probability . A geometric distribution models waiting for their first success. Two conventions coexist, so always say what is counted. Let count all trials up to and including the successful trial, and let count preceding failures. Their probability mass functions areThe factors describe failures followed by one success; independence permits multiplication. Summing the geometric series verifies that each law has total mass one. Their expected values differ by one, while shifting by a constant leaves the variance unchanged:The positive convention and these moments are also given by Penn State STAT 414.[ref]
11 Geometric and Negative Binomial Distributions. STAT 414: Introduction to Probability Theory at Pennsylvania State University; §11.1, Definition 11.1; §11.2, mean and variance theorems
For a constructed retry mechanism with independent attempts and , success on attempt four has probability . More than four attempts are needed precisely when the first four fail: . The expected values are and , and the common variance is . The large spread explains why the average waiting count is not a deadline.
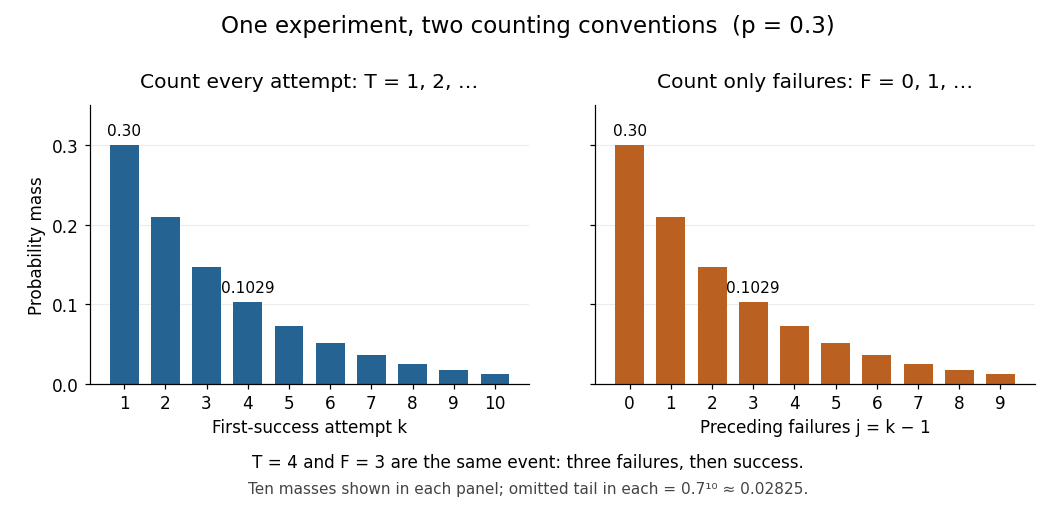
First-success trial versus preceding failures: the same probability masses shifted by one
. Details. The two probability mass functions have identical heights with different labels: and describe the same event. For , consecutive masses have ratio , explaining the name geometric distribution. The support of a probability distribution is the positive integers for and the nonnegative integers for . At , it collapses to and , both with variance zero; interpret an empty product, including , as one. These counts concern attempts; converting them into elapsed time requires specifying the time spent per attempt.
The survival function makes the counting convention especially visible. Put . For nonnegative integers , and for ,The event requires failures, whereas requires only when . For the constructed mechanism, differs from . The geometric success deadline uses the latter tail to control the chance of still waiting.
The striking memorylessness of the geometric distribution says that, for nonnegative integers with ,After five failures, the conditional probability of requiring more than two additional attempts is still . The analogous zero-based identity uses ; keeping the inequalities straight avoids an off-by-one error. This property follows from fresh independent trials with unchanged ; learning or changing conditions can destroy it. At , success never occurs, so there is no proper finite waiting-count law.
For independent positive-support geometric random variables with success probabilities , all must exceed for their minimum to exceed . The resulting survival function is . This is the positive-support geometric distribution with the displayed success probability. Independence is needed for multiplying the survival probabilities.
The same argument works for any integer base . Suppose has geometric distribution , , with . Its Euclidean division gives and . Their joint probability mass function isThe factors are normalized probability mass functions, so the final digit and quotient are independent. The quotient again has geometric distribution, with success probability . If is the integer part of an exponential random variable of rate , take .
Suppose a contest uses trials initially and ends there with probability . Conditional on an initial tie, independent further rounds each use trials and resolve the contest with a fixed probability . The number of further rounds, conditional on that tie, has a geometric distribution: for . Thus the total number of trials has an atom at and the displayed probabilities thereafter. The geometric series sums to , so termination has probability one, and the expected value is . The displayed distribution requires independence of the future rounds from the initial tie.
For the positive-integer geometric distribution with success probability , the displayed identity holds for nonnegative integers whenever the conditioning event has positive probability. The first attempts have failed; future independent attempts use the same success probability. Equivalently, divide the tail by . For a zero-based failures count , use . Constant success probability and independence are essential: accumulated wear or learning would require a different model.
The full remaining-count law is unchanged, not only one tail probability. With , after failures set on the event . For , its probability mass function under this conditional probability isHere independence makes the future trials unaffected by the observed failures, and the unchanged success probability makes their law identical to the original one. Consequently , while . For the constructed mechanism, five failures leave a mean of more attempts, making the conditional mean total ; the five already spent are still counted.
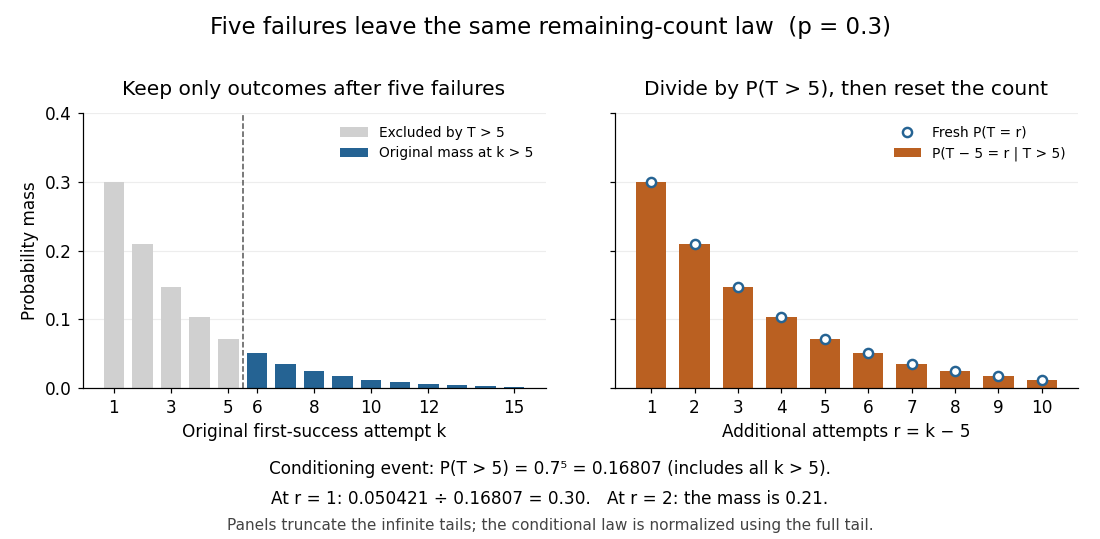
Conditioning on five failures, renormalizing, and resetting the count gives the original geometric law
. Details. The same mechanism has constant discrete hazard:Thus each reached attempt has the same chance of success. This differs from the decreasing unconditional probability : later success requires surviving earlier attempts. At , only conditioning on an event of positive probability is allowed: permits only , and only .
Among proper laws on the positive integers, memorylessness of the geometric distribution also characterizes the geometric distribution. Write . The identity gives ; if , both sides vanish anyway. Since , induction yields . Properness excludes , so setting recovers the geometric distribution, including .[ref]
The Geometric Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; Basic Theory, Distribution Functions and the Memoryless Property: conditional remaining-count identity and its converse
The retry example stipulates independent Bernoulli trials with a known constant ; it is not evidence that a real retry system behaves this way. Shared changing conditions or adapting attempts can alter the next success probability. Even constant individual success probabilities alone do not imply independence.
For an original contrasting model, uniformly shuffle one success card and three failure cards, then draw by sampling without replacement. Its success position has the discrete uniform distribution on . Initially the success probability is ; after one failure it is . In particular,This shows concretely why sampling without replacement need not be independent and why the remaining wait can change. Every draw still has unconditional success probability when all four positions are considered; the relevant discrete hazard changes after failures.
How many attempts give at least a chosen success probability ? For a positive-integer geometric distribution with , completion by attempt means , soThe logarithm is negative, which reverses the inequality when dividing. The least integer meeting the target is therefore obtained with the ceiling function:For our constructed independent retry mechanism with and ,To verify minimality directly, eight attempts give , whereas nine give . Under the zero-based convention, the same completion event is , with failure to complete given by ; saying would allow ten attempts. A 95% deadline controls a tail probability, while the expected value describes an average.
At success occurs on the first attempt, so ; the logarithm formula is inapplicable. At no finite deadline achieves a positive target. For , no finite deadline guarantees success with probability one because . A retry cap at produces the capped geometric waiting time as the number of attempts actually spent; reaching the cap can mean either success on the last allowed attempt or failure of all attempts.
Start a Markov chain at a nonabsorbing state . If each departure from has probability of absorption before the next return, the Strong Markov property makes the number of visits to , including the initial one, a positive-integer geometric random variable of parameter . For a continuous-time Markov chain whose holding times at are independent rate- exponentials, independently of the embedded jump chain, the total occupation time at is a sum of such holding times and has expected value .
Independently retain each event of a zero-based geometric distribution count with probability . Conditional on the original count, the retained count is binomial, so its probability generating function is . This is again a zero-based geometric distribution, with success parameter and mean . In excess of loss reinsurance, is the probability that a claim exceeds the retention.
Let for and , with . Write . Summing the joint probability mass function with the differentiated geometric series identity gives . By Bayes' theorem,Thus , given , has the failure-count negative binomial distribution for successes and success parameter . Its conditional expectation is for itself. The shift by , the number of retained successes, must be retained when identifying the posterior distribution.
For a positive-integer geometric distribution with , the capped time has masses for and at . The last mass includes all later arrivals, not only . Its probability generating function and expected value areThe expectation follows either by differentiating the PGF or summing the tail probabilities up to .
When independent uniform draws are made from types, the time until every type has appeared decomposes as a sum of independent geometric waiting times with parametersConsequentlyand Chebyshev's inequality gives in probability.
For independent coupon labels arriving at rate , Poisson thinning makes the type-specific first arrival times independent exponentials of rates . Completion time is their maximum. Its distribution is . The completion count depends only on the labels and is independent of the exponential interarrival sequence. Therefore and nonnegative integration gives the displayed identity. Completion count and its expectation do not depend on arrival rate.
In independent trials with two outcomes of probabilities and , let include the first trial and the trial that first completes the pair. Conditional on the first outcome, has a geometric distribution of parameter or , with mixture weights . The law of total expectation and law of total variance giveThe final term in the unsimplified variance is the variance of the two conditional means; omitting it is incorrect unless . Both outcomes must have positive probability for these finite formulas.
For uniform independent draws of coupon types, the waiting times with unseen types remaining are independent positive-support geometric distributions of parameter . Summing their means gives , and summing their variances gives the displayed formula. Independence follows from fresh draws after each discovery and the fact that the next stage's conditional distribution depends only on the count of remaining types.
The negative binomial distribution counts failures before a target number of successes in successive independent Bernoulli trials with constant success probability . In this stopping model, is a positive integer and . On the failures-before-the-th-success convention, the random variable takes values ; for , its probability mass function isThe binomial coefficient counts possible arrangements before the final success, as explained by the negative binomial stopping argument. At , every trial succeeds: with probability one, so its expected value and variance are both zero. This handles the endpoint without needing to interpret . At , the target is never reached and there is no proper finite waiting-count law.
For a worked example, toss a fair coin until the second head, calling heads and tails . Thus and . Exactly two failures means that the second success is on trial four. The complete stopped sequences are , and ; each has probability , giving . The first three masses areBoth and are modes, each with mass : there is no unique mode here. Later masses decrease, since for .
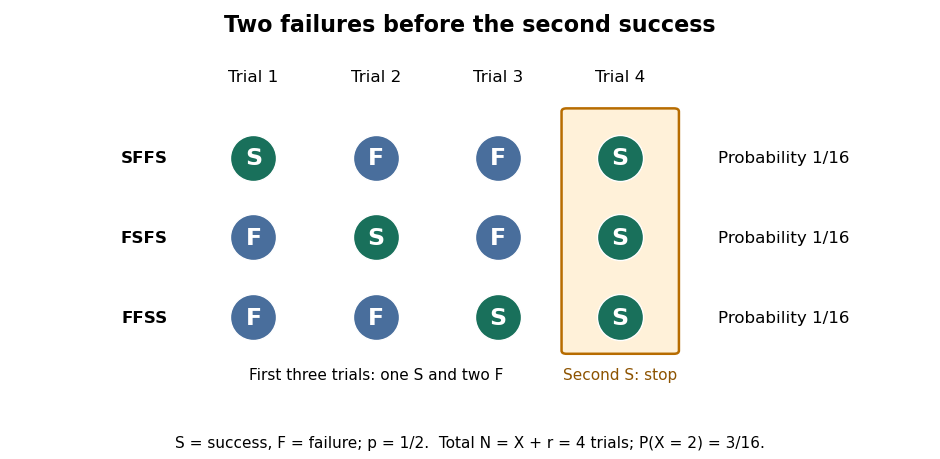
The expected value and variance of the failures count areIf instead counts all trials, including the successes, then andFor the fair-coin example, , , and . Shifting the count changes its expected value but preserves its variance. When , has the failures-count geometric distribution, while has the all-trials geometric distribution. The two conventions and the moments are treated in Kyle Siegrist, The Negative Binomial Distribution, Random Services.
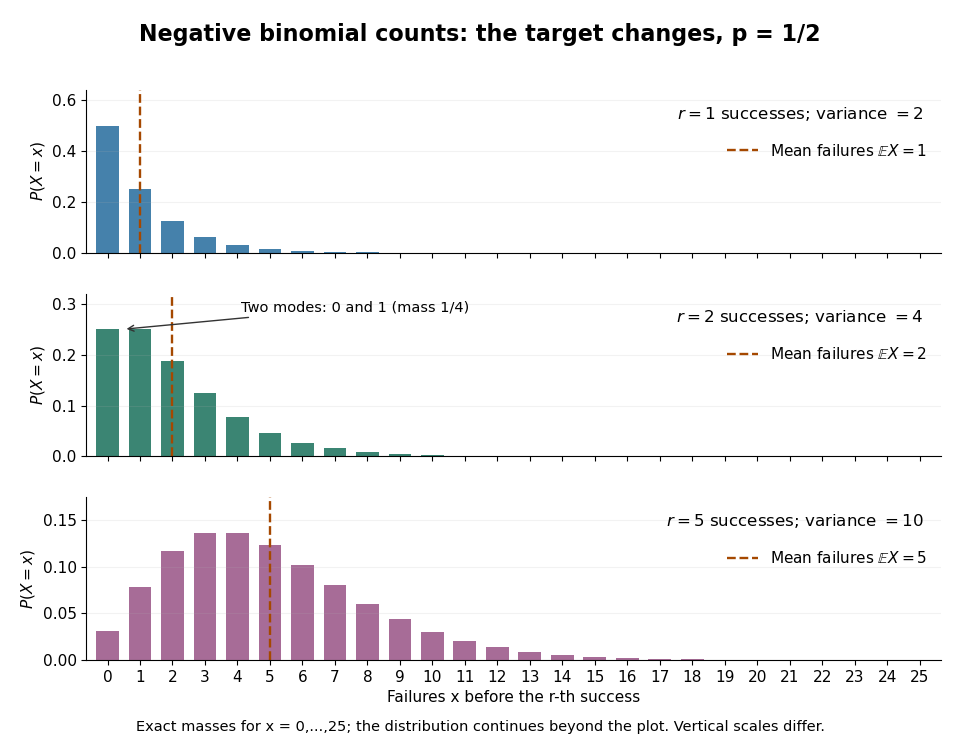
Negative binomial failure counts for success probability 1/2 and targets of one, two and five successes
. Details. The negative binomial distribution is useful when a procedure runs until it collects a target number of successes: for example, obtaining usable samples from independent attempts with a stable acceptance probability. A binomial distribution instead counts successes in a fixed number of trials. The attractive connection is that these two experimental questions can be answered from the same trial sequence, using the negative binomial stopping argument. For the failures count and , the positive mean satisfies , so the law allows overdispersion relative to a Poisson distribution. At , both quantities vanish and the inequality is not strict. The separate Poisson-gamma mixture explains another way this count law arises; its noninteger shape parameters do not represent a literal target number of successes.
When each observation counts untagged captures before the th tagged capture with immediate replacement, its negative binomial distribution has success probability . For independent runs, the log-likelihood is plus a constant. Differentiation gives the displayed estimator and expected Fisher information. For an interior true parameter, its asymptotic variance is . A confidence interval for transforms to for the population size, with endpoint order reversed.
For the negative binomial distribution with positive integer target and success probability , the th success occurs after exactly failures only if the final trial is a success, while the preceding trials contain failures and successes. Choosing the failure locations gives the binomial coefficient . Each such stopped sequence has probability by independence, and the sequences describe mutually exclusive events, so their probabilities add. This proves the probability mass function. Counting arrangements among all positions would wrongly include sequences that already reached the target earlier. The same argument is used for three heads in MIT 18.05, spring 2022, problem set 9 solutions, problem 2(b).
A short route to normalization and moments is to split the failures count into successive waiting blocks:where counts failures after success and before success , with starting at the first trial. Fresh independent Bernoulli trials make the blocks independent, each with the failures-count geometric distribution. Each block has total mass by the geometric series, so their sum also defines a normalized probability distribution. The linearity of expectation and variance additivity for independent random variables give and . This makes the moments transparent without a long calculation of sums. For , every block is zero.
The same stopping rule connects a waiting count to a fixed-length count. Let be the trial number of the th success, and let count successes in the first trials, so has a binomial distribution. For any nonnegative integer ,The target is still unmet after trials exactly when fewer than successes have occurred. With , and , this gives ; equivalently, , matching . At , the event identity still holds, with and deterministically.
In independent Bernoulli trials with success probability and failure probability , let be the trial of success and the trial of failure , for positive integers . If success occurs after failures, its final trial is a success and the preceding trials have successes and failures. The negative binomial stopping argument therefore gives the title sum.
Put . By trial , at least one target must have been reached, so the same event is that a binomial distribution with trials has at least successes. Conditioning instead on the final trial of a block of trials givesIndeed, more than successes in the full block guarantee the success target won; with exactly successes it won only when the final trial was a failure. These disjoint cases explain the extra boundary term. A zero success target wins immediately; a zero failure target has already been reached. To include in the displayed finite sum requires the explicit generalized convention ; an upper summation limit of denotes an empty sum.
Suppose independent Bernoulli trials give a player a win with probability , and the match ends when either player reaches wins. The player's match-win probability isFor a win with losses, the final trial must be a win. The preceding trials contain exactly wins and losses; the binomial coefficient counts their arrangements. Because , the opponent cannot already have won, and because the player has only previous wins, the match has not ended earlier. Summing the disjoint terminal events gives the formula, a truncated negative binomial distribution sum. The constant game-win probability must describe independent games, or equivalently remain the same conditional on every previous history.
If and has a gamma distribution, then has a negative binomial distribution. For gamma shape and scale ,
The binomial distribution counts successes in a fixed number of independent Bernoulli trials with common success probability . Equivalently,Here is a nonnegative integer and . The binomial coefficient counts placements of the successes; each particular arrangement has probability . The binomial theorem makes the masses sum to . At all mass is at zero, and at all mass is at ; these endpoint laws can be read directly without interpreting .
The linearity of expectation and addition of variances for independent random variables giveThe fixed trial count, common success probability, and joint independence are substantive model assumptions. Sampling uniformly without replacement from a finite population instead leads to a hypergeometric distribution. Independent trials with different success probabilities generally give a Poisson binomial distribution. Common marginal success probabilities alone are insufficient: if all ten indicators equal the same Bernoulli random variable with , their sum is zero with probability or ten with probability . Its mean is still three, but its variance is . The standard construction is given in Penn State STAT 504, binomial distribution.
For an exact constructed example, let each of ten independent trials choose uniformly from ten labelled tokens, with replacement, and mark three tokens as successes. Then and . Exactly three successes have probabilityThe mean is , the variance is , and the standard deviation is . Zero successes have probability , so at least one success has probability . A single count calculation replaces enumeration of all equally likely token sequences.
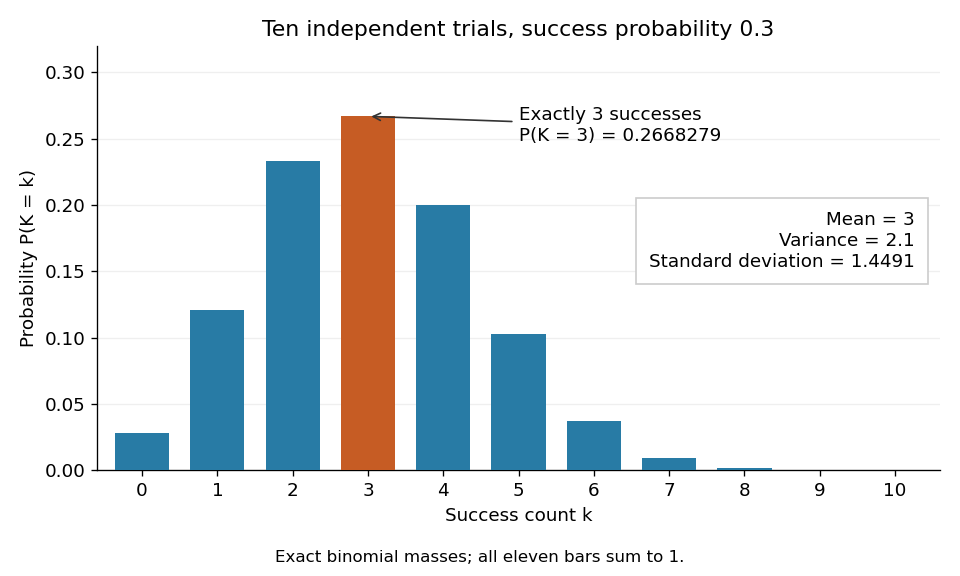
Each bar's height is one probability mass. Three is the most likely count, but its mass is only about : a most likely outcome need not occur most of the time.
For a binomial distribution with parameters and , the binomial theorem gives the displayed moment-generating function, finite for every real . Products of these moment-generating functions show that the sum of independent binomial random variables with the same success probability again has a binomial distribution, with trial counts added.
If independent trials give a specified digit with probability , its observed fraction is with binomial count . Since and , the mean squared discrepancy is the displayed inverse-sample-size law. Dividing by converts it to a relative squared discrepancy without changing the log-log slope. Nested prefixes are correlated; a single deterministic expansion's plotted discrepancies do not prove that its digits are independent or normally distributed in the number-theoretic sense.
For independent random variables with the same binomial distribution , partition the tie event into the mutually exclusive events . Independence makes each probability the square of its binomial probability, proving the formula. At , Vandermonde's identity gives . Symmetry under exchange of the two variables then gives .
The binomial distribution with parameters and assigns the displayed probability to successes, for integers . Each specified sequence of independent trials has probability , and the binomial coefficient counts the sequences with exactly successes. Outside this range the probability is zero.
Let and be independent random variables with binomial distributions and . Conditional on having positive probability, the possible values of satisfy . Their probabilities arewhere the denominator sums over that feasible integer range. The formula follows by multiplying independent binomial probabilities and dividing by the probability of the disjoint union of all feasible count pairs.
For , common factors cancel and the weights are proportional to , where . If , this reduces to the hypergeometric distribution, with probabilities . At parameter endpoints, use the original probability weights and check that the conditioning event has positive probability before dividing.
For with , the sample binomial proportion is . Its expectation is p and its variance is . The central limit theorem gives a normal approximation when both expected outcome counts are sufficiently large. These moments determine a standard error and model-based control limits.
With groups of trials and common marginal failure probability , each count has expectation , so the displayed estimate is unbiased without assuming independence within groups. Independent individual trials give variance . If only groups are independent, estimate the variance instead by , retaining within-group dependence. Equal marginal probabilities alone do not justify a binomial confidence interval.
If and is observed, the maximum-likelihood estimate of is zero. A one-sided upper confidence bound solves , so . For large , , giving approximately at 95% confidence. This describes uncertainty after no observed events, rather than proving that the underlying probability is zero. It assumes independent observations with a common event probability; clustered data require a different uncertainty calculation.
The zero-truncated binomial distribution has probabilities for . Its natural parameter is and its cumulant is . Mean and variance are and , where . The conditional normalizer depends on , so its likelihood is not proportional to the untruncated likelihood even after a positive observation. At and , its likelihood supremum is at rather than at .
For , expand the fourth power of the sum of centered independent Bernoulli variables. Terms with an index occurring once vanish; single-index fourth moments contribute and paired second moments contribute . Their sum is the displayed formula. Scaling by yields a uniform fourth moment for .
For independent Bernoulli observations with success probability , the sample proportion is the success count divided by the sample size. It is an unbiased estimator with variance . It supplies the arm-specific risks in a risk ratio and the mean difference in a two-proportion comparison.
For two independent samples of Bernoulli random variables, the difference of their sample proportions estimates the difference of population probabilities. Since the samples are independent,Substitution of the sample proportions gives a standard error for a large-sample Wald confidence interval. This interval is a descriptive comparison of the specified groups; a causal effect needs further assumptions. Sparse counts and probabilities near zero or one can make the normal approximation poor. Testing equality can instead use a null-pooled estimate of the common probability for the test's standard error.
If successes occur in independent Bernoulli trials, the binomial likelihood for the success probability is proportional to .
The hypergeometric distribution counts marked objects in a uniformly chosen sample of fixed size from a finite population, using sampling without replacement. Let be the population size, let objects be marked, and sample distinct objects. If counts the marked objects selected, its probability mass function isThe bounds describe the support of a probability distribution and must be an integer; the mass is zero elsewhere. The denominator counts all size- subsets, while the numerator counts choices of marked and unmarked objects using binomial coefficients. This counting argument requires every size- sample to have the same probability.[ref]
https://web.mit.edu/14.380/www/handouts/hypergeometric.pdf. MIT 14.30, hypergeometric distribution handout, §§1–4
For a constructed example, a box contains ten labelled objects, four red and six blue. Select five without replacement. There are possible samples. The probabilities for areIn particular, . Five red objects are impossible because the box only contains four. The expected value is , and the variance is .
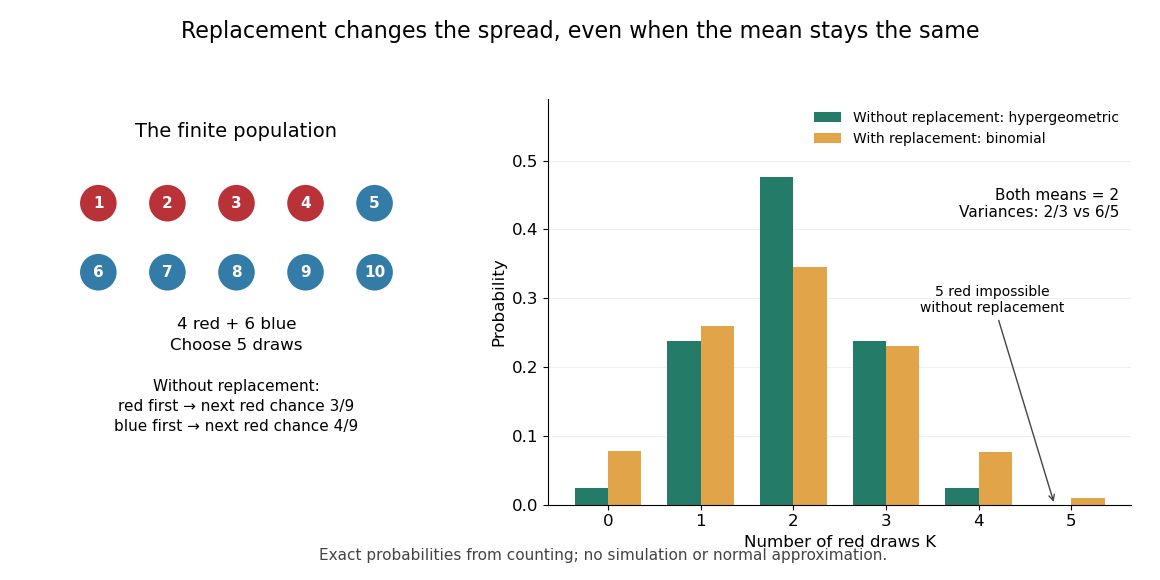
Five draws from four red and six blue objects: replacement preserves the mean but changes the spread
. Details. The count law also answers a detection question: what is the chance that five draws find at least one red object? By the complement rule of probability, it is , approximately . This can model inspecting five distinct objects from a known finite collection, with a mark indicating the property we want to detect. If repeated inspections can select the same object again, the replacement model instead gives . Equal expected values therefore do not imply equal chances of detecting a marked object.
The corresponding binomial distribution counts red draws when each selected object is put back before the next independent draw: . It has the same expected value , but variance , and it permits five red draws. Without replacement, a red first draw leaves red probability for the next draw; a blue first draw leaves . This statistical dependence pulls the total toward the fixed composition of the population, producing the finite population correction.
The useful modelling question is whether previously selected objects remain available. A fixed-size sample of distinct items calls for a hypergeometric distribution; fresh independent trials with constant success probability call for a binomial distribution. When the population grows with while stays fixed, the hypergeometric masses tend to the corresponding binomial distribution masses: removing finitely many objects has an increasingly small effect on the next draw's probability.
For uniform sampling without replacement from a population of objects, the finite population correction accounts for the reduced spread caused by drawing distinct objects. For the marked-object count in a hypergeometric distribution, put . ThenRelative to the corresponding binomial distribution, the variance is multiplied by and the standard deviation by . The square-root convention for the correction is used in Philip Stark's discussion of sample sums.[ref]
https://www.stat.berkeley.edu/~stark/SticiGui/Text/standardError.htm. Stark, SticiGui, Standard Error: sample sums without replacement
The factor has a direct interpretation. For , replacement makes no difference and . For , the entire population is observed and the marked count is exactly , so . In the ten-object, five-draw example, and . The exceptional population size is deterministic and should be handled directly rather than inserting it into a zero denominator.
A short explanation uses an indicator random variable for a marked object at draw . Each has expected value and variance . For distinct draw positions ,Since , the variance of a sum includes individual terms and ordered covariance terms, giving the displayed correction. Linearity of expectation still gives despite this dependence.
For arbitrary fixed real population values, use for population size and for sample size. Write the finite population mean , the finite population variance and . Under simple random sampling without replacement, the sample mean satisfiesThus is the variance factor relative to , while is the exact variance ratio to independent uniform sampling with replacement, whose sample mean has variance . The standard error uses the square root of the corresponding factor. These formulas agree because ; the denominator convention must be specified. The sample mean under simple random sampling gives a derivation and an exact six-value example.
Suppose a finite population is split into categories with fixed sizes summing to . A uniform size- sample drawn by sampling without replacement has category counts with the displayed joint probability mass function, for integers summing to . It extends the two-category hypergeometric distribution; replacing the sampled objects instead gives a multinomial distribution.
For a box with category sizes and a sample of four distinct objects, the count pattern has probabilityPut . When , its covariance matrix is the corresponding multinomial distribution covariance matrix multiplied by the squared finite population correction:This connects the fixed-total dependence between categories with the further reduction from sampling without replacement. X. G. Duan gives a symmetry-based explanation of this shared covariance structure.[ref]
https://arxiv.org/abs/2101.00548. Duan, Better understanding of the multivariate hypergeometric distribution, 2021 preprint
A multinomial distribution describes category counts from independent trials, each choosing exactly one of categories with the same probabilities . Require to be an integer, , and . If counts the trials in category , then andThe are integers, and the mass is zero for other count patterns. A category with has count zero almost surely, with in this formula. For a specified ordered trial sequence, independence gives the product of numbers ; the multinomial coefficient counts the different sequences with that same count pattern.
For four trials with category probabilities , the count pattern can occur in orders, each of probability . Thus its total probability is . This is a constructed independent-trial example, distinct from drawing four objects without replacement from a ten-object population of composition , where the multivariate hypergeometric distribution gives .
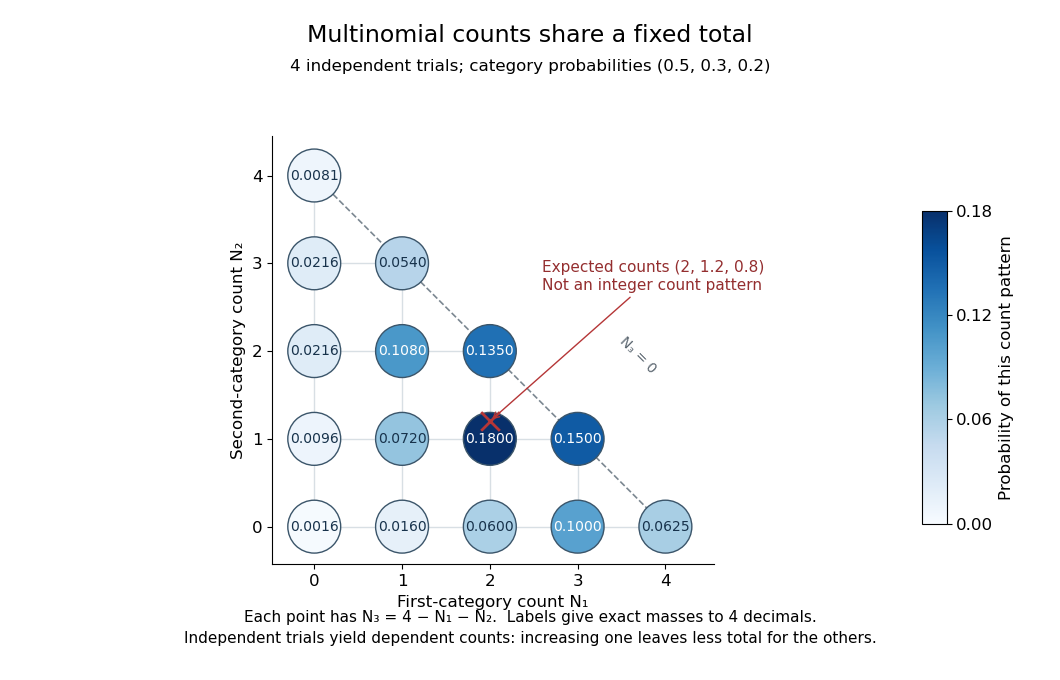
Three category counts from four independent trials: every point fixes the third count through the total
. Details. The diagram shows all fifteen possible count patterns. Coordinates determine ; the triangle is a constraint on integer counts, not a continuous probability density. The mode is , where the probability mass function is largest, but the expected values are not a possible count pattern.
Each single count has a binomial distribution, because recording category versus all other categories reduces every trial to a Bernoulli trial. Consequently,These statements about the joint count model are summarized in Aditya Guntuboyina's lecture notes.[ref]
https://stat238.berkeley.edu/spring-2026/lecturetwelve238spring2026/. Guntuboyina, Berkeley STAT 238, lecture 12: multinomial distribution
Independent trials do not make the resulting counts independent random variables. Within one trial the indicator random variables for two distinct categories cannot both equal one, so their product is zero and their covariance is . Summing over independent trials gives . In the four-trial example, the variances are and the pairwise covariances are . Knowing that all four trials were in the first category fixes the other two counts at zero.
The attraction is that one formula describes any fixed-total list of category counts while preserving the constraint that they add up to . It underlies multinomial likelihood calculations and uniform balls-in-bins allocation. The multinomial aggregation rule lets us merge categories without leaving this family of probability distributions. Allowing independent category counts with an unfixed total instead leads to a different model, related through Poisson-multinomial conditioning.
If has a multinomial distribution with trials, group its categories into disjoint nonempty sets covering all categories. The grouped counts in the displayed equation have the multinomial distributionEach original trial belongs to exactly one group, its group probability is the sum of its category probabilities, and grouping preserves independence between trials. This gives the rule without summing the original probability mass function over every possible internal count pattern.
For the four-trial example with probabilities , merge the last two categories. Their total has the binomial distribution , so and . The same variance follows from the variance of a sum:Ignoring the negative covariance would give , although the two counts share a fixed total. Multinomial aggregation lets the resolution of category labels change while retaining a consistent model for the counts.
For cell means with , the independent Poisson distribution likelihood and the multinomial distribution likelihood with probabilities differ by a parameter-independent factor. Thus a maximum-likelihood estimator for the unrestricted Poisson model whose fitted total is is also an estimator for the constrained multinomial model. Equality of named parameter estimates presumes identifiability and uniqueness; without these, the conclusion concerns the sets of maximizers. A free intercept in a log-linear Poisson model enforces the fitted-total equation.
Counts of several categories before a fixed number of stopping-category outcomes have a negative multinomial distribution. For one stopping outcome of probability , the two-count mass function is . Its probability generating function is and its means are and .
For independent one-stop negative multinomial distribution observations, the natural estimates are and . Their sum is with strictly concave , so Jensen's inequality makes its expectation strictly below . Conditional category proportions split this bias between both estimates. With zero observed counts of a category, that estimate lies at zero; in a parameter space requiring strict positivity the likelihood supremum is not attained.
The vector of category counts is the sum of independent categorical indicator vectors. Their means are and covariance is , so the multivariate central limit theorem gives the displayed limit. At uniform probabilities on categories, Pearson-standardized deviations have covariance equal to the orthogonal projection onto the -dimensional subspace of zero-sum vectors. Their squared norm has an asymptotic chi-squared distribution with degrees of freedom.
Place labelled balls independently into labelled bins, each with probability . The vector of bin counts has a multinomial distribution, and each count separately has the binomial distribution . Distinct bin counts have covariance , so they are dependent for and . Counts of bins of a specified size are sums of indicator variables; their expectations follow from the linearity of expectation, without any independence between bins.
In repeated uniform balls-in-bins allocation, remove each ball that is alone in its bin and independently reallocate all remaining balls in the next round. If balls remain, the conditional expectation of the next count is for , and zero for . The surviving-ball indicator random variables need not be independent. For two balls and two bins, both remain with probability after rounds, so .
For balls in uniformly and independently chosen boxes, put . The empty-box indicators in uniform allocation have negative pairwise covariance, so . Chebyshev's inequality givesSince , this proves the displayed convergence in probability. The centring and the negative covariance are essential to this short proof; an expectation limit alone would not establish concentration.
Place balls independently and uniformly into boxes. If indicates that box is empty, then , , and, for ,Indeed all balls avoid one specified box with probability and two specified boxes with probability . The indicator random variable identities give the expectations, variances, and covariance. Finally proves strict negativity. Thus the number of empty boxes has and by the variance of a sum.
In a uniform balls-in-bins allocation with and , a fixed bin count has convergence in distribution to a Poisson distribution variable of mean by the Poisson limit theorem. If counts bins containing exactly balls, symmetry and the linearity of expectation give for each fixed . In particular the expected empty fraction tends to , and the expected fraction with at least two balls tends to . These are statements about expectations; convergence of the random fractions requires an additional argument.
For category counts with fixed total and probabilities , the multinomial likelihood isIts maximum-likelihood fitted probabilities are .
For counts with a multinomial distribution, this is twice the log likelihood ratio of the saturated cell-probability estimate to fixed probabilities . Zero-count terms have limiting value zero. Simulation under the specified probabilities gives a direct reference distribution when asymptotic approximations are unsuitable.
A categorical distribution describes one trial with one of labelled outcomes and probabilities summing to one. The labels need not be numbers or have an order. It is the single-trial building block of the multinomial distribution: independent draws with the same categorical distribution produce multinomial category counts.
For a trial choosing labels with probabilities , the category-indicator random vector is , , or . Its expected value is ; its components are dependent because exactly one is one. A numerical encoding of is a separate modelling choice: the category labels themselves do not define an arithmetic mean.
The sum of independent Bernoulli random variables with possibly unequal success probabilities has a Poisson binomial distribution. Its probability generating function is : expand the product to read off the probability mass function. Linearity of expectation and additivity of variance for independent random variables give and . Equal recover the binomial distribution.
For three trials with success probabilities , expanding gives masses at . Their expected value is and variance is . Replacing all three success probabilities by their average preserves the expected value but gives binomial distribution variance , so it does not preserve the law.
A sum of independent Bernoulli random variables whose success probabilities may differ. Its distribution is the Poisson binomial distribution.
For , a Poisson random variable has probability mass functionThe exponential function series verifies normalization. At , define with certainty. The equality of mean and variance is a distinguishing model property, though it does not by itself characterize the law.
When counting events in a homogeneous Poisson process, distinguish its rate from the distribution parameter: an interval of duration has . A rate measured per minute times a duration measured in minutes gives a dimensionless expected count. This process assumes independent increments, a constant rate, and a negligible chance of multiple events relative to interval length in a sufficiently short interval. A rate alone does not establish a Poisson distribution. See Bertsekas and Tsitsiklis, chapter 6 summary, pages 46-47.
For a constructed arrival model with events per minute over minutes, . The mean and variance are both three, andThe probability of at least one event is . These results describe the specified process, not every arrival mechanism with the same average rate.
The Poisson limit theorem, often called the law of rare events, connects this law to the binomial distribution. Keep fixed and let for integers . For each fixed nonnegative integer and sufficiently large ,There are more opportunities, each less likely to succeed, while the mean stays and the variance approaches . For , the probability of three successes is at , at , and at , approaching the Poisson distribution value .
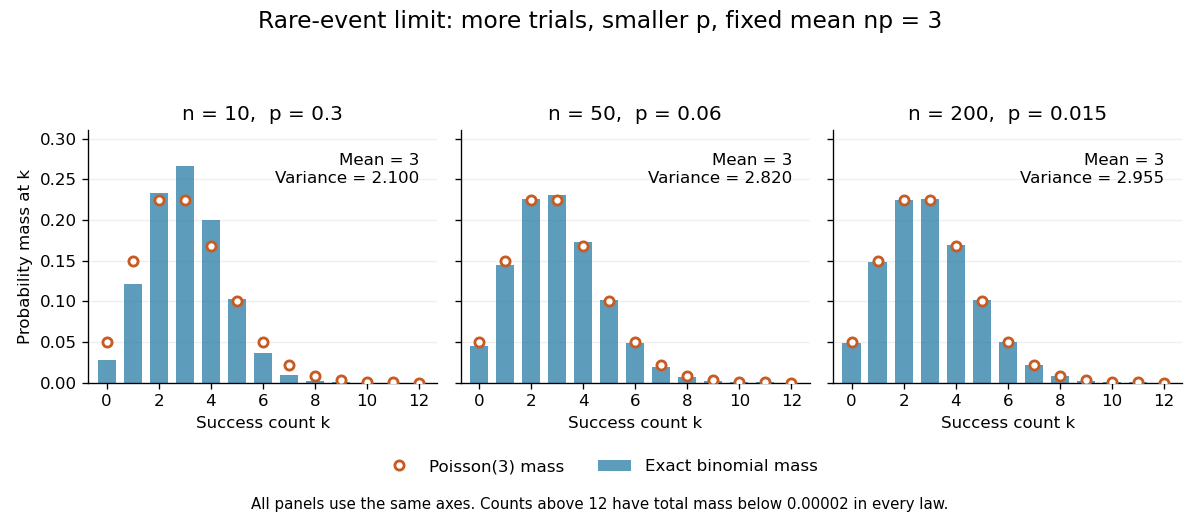


The panels show the same count scale and the same Poisson distribution reference. At , is not especially small and the difference is visible. No universal trial-count cutoff guarantees an adequate approximation for every event.
The independence assumption matters even when every success is rare. For , if all indicator random variables equal one shared Bernoulli random variable of parameter , their sum is zero with probability and with probability . Its mean is three, yet its zero-count probability tends to one, not . Some dependent counts still admit approximation through the Stein-Chen method, but this requires additional control of dependence.
For historical orientation, the BnF records Poisson's original probability treatise, Recherches sur la probabilité des jugements, as published in Paris in 1837. This bibliographic fact alone does not establish when the modern distribution terminology arose. See BnF record of Poisson's 1837 treatise.
When a Poisson distribution is observed in cells , the last cell probability is a tail sum, not the probability of exactly . With and , telescoping derivatives give . Thus an interior maximum-likelihood estimate solves . Substitution of the estimate into these cell probabilities supplies fitted expected counts for a likelihood-ratio test. With cells and one regular fitted parameter, the asymptotic chi-squared distribution has degrees of freedom. Replacing every grouped tail observation by changes the data model and generally does not give the grouped maximum likelihood estimate.
For with , insert its probability mass function into the expected value:The exponential series shows finiteness for every real . Differentiating this moment-generating function gives mean and variance both . Taking the logarithm gives the cumulant-generating function , so every positive-order cumulant is also .
If has a Poisson distribution with parameter , then the ordinary factorial has finite expectation exactly when . Indeed, its nonnegative expectation series is , since cancels the denominator of the probability mass function. The geometric series gives the formula and proves divergence for . This differs from a falling-factorial moment of fixed order, which is finite for every finite Poisson distribution parameter.
The distribution of for independent Poisson random variables with means is the Skellam distribution. Its characteristic function is , its mean is and its variance is . For equal means ,This is the fixed-time law of a symmetric Poisson difference process.
// Target: markov-process.bigb
A mixture of Poisson distributions over a nonnegative random intensity. With exposure and prior density , its probability mass function is . A gamma mixing distribution gives a negative binomial distribution. Counts sharing the same latent intensity are conditionally independent, but generally dependent after mixing.
If has Poisson mean , conditional expectation and the law of total variance give the display. A positive variance of the random mean prevents the unconditional count from being Poisson. For Poisson parents of density and offspring mean , the count in has excess variance , which is positive for a bounded positive-area set and a nontrivial model.
For a mixed Poisson distribution with known exposure , multiply the unnormalized posterior density by and compare its integral with the next probability mass. The factors give the displayed identity whenever . Both mass probabilities have the same exposure . For a future conditionally independent unit-exposure Poisson distribution count, this is also its posterior predictive expected value. It holds for arbitrary proper mixing distributions, with integrals taken against the prior measure when there is no density.
The information entropy of a Poisson distribution is strictly increasing for . Given , take independent and . Their sum has Poisson distribution with mean , so entropy monotonicity under independent addition gives . All these information entropies are finite, and excludes equality.
// Target: probability-and-statistics.bigb
The Stein-Chen method compares an integer-valued count with a Poisson distribution by solving the Poisson Stein equation and estimating its expectation at the count. For sums of indicator random variables, dependency neighborhoods expose local overlap errors. This gives total variation distance bounds without having to compute the entire count distribution.
Let and , where each indicator random variable is independent of all indicators outside jointly. Write and . For a test-event solution of the Poisson Stein equation, independence givesTelescoping each difference and using bounds the total variation distance by that factor times . Directed dependence neighborhoods are allowed. If , the count is identically zero.
For indicators with means , let contain and suppose is independent of the entire family outside . Put , and . The Poisson Stein equation and its bound give the displayed total variation distance estimate. Stronger Stein factors can improve the bound when is large.
For indicator test functions , the equation has a solution with . One proof uses an immigration--death process with immigration rate and per-particle death rate one. Its potential satisfies its generator equation, and . Coupling two additional initial particles bounds the second difference of by .
For with Poisson distribution of mean , the equality proves the identity by summation. For an independent random sum of independent claims with this count, exchangeability of the summands gives , where on the right is independent of and has the severity law. These identities hold for nonnegative measurable functions, and for integrable signed functions. They obtain moments without assuming that a positive exponential moment exists.
A Poisson distribution of parameter conditioned to lie in . It is the occupancy law of a unit-resource loss network. Its mean is the carried load of an Erlang loss resource, . Differentiating the mean with respect to gives its variance, which is positive for and ; this proves strict monotonicity of the carried load.
A model with for a nonnegative random intensity. Conditional expectation and total variance give and , explaining overdispersion. A Poisson-gamma mixture gives the negative binomial distribution.
For a uniform prior distribution on with , conditionally independent Poisson distribution observations have sufficient count . Their Bayesian posterior density is proportional to on that bounded interval. The displayed posterior mean is the Bayes estimator under squared error loss, and is generally not the affine Bühlmann credibility estimate.
When the random intensity is with having an exponential distribution of rate , the mixed count is the sum of independent Poisson distribution and support-zero geometric distribution counts. The Poisson parameter is and the geometric success probability is . At the law is geometric.
For the shifted-exponential Poisson mixture, the displayed relation holds for , initialized by and . It follows by differentiating the probability generating function and comparing coefficients. Nonnegativity follows from the independent Poisson-geometric convolution of independent random variables representation.
For the zero-truncated Poisson distribution, is the unique integrable nonrandomized unbiased estimator of . Indeed unbiasedness gives , and power series coefficients force the parity values. Its variance is ; clipping it to gives mean squared error , strictly smaller for .
The sum of independent Poisson random variables is Poisson, with parameter equal to the sum of their parameters. This follows by multiplying their probability generating functions .
For Bernoulli random variables , which need not be independent, put , , and . ThenThe dependence penalty is the total correlation. The proof compares the joint Bernoulli law with the product of Poisson laws of means , then applies the data processing inequality for relative entropy to addition.
A Poisson observation model represents a nonnegative count as conditionally Poisson with a mean supplied by an underlying process or regression model.
A Poisson observation is an integer-valued count modeled by a Poisson distribution of specified intensity, possibly conditionally on a latent field. Independent Poisson observations motivate Poisson data fidelity through their log-likelihood.
Articles were limited to the first 100 out of 111 total.
Articles by others on the same topic
There are currently no matching articles.