Matrix preconditioning transforms a linear system using an inexpensive auxiliary solve to improve its eigenvalues. For symmetric positive-definite matrices, a symmetric positive-definite matrix produces , preserving the symmetric structure needed by the conjugate gradient method.
A useful matrix preconditioner combines a cheap solve with favorable transformed eigenvalues; neither property alone is enough.[ref]
The aim is to make each correction more effective without making it expensive. The example under diagonal scaling for a two-dimensional linear system turns thin ellipses into nearly circular ones and makes preconditioned steepest descent effective.
A matrix preconditioner is an auxiliary invertible matrix whose matrix inverse is cheap to apply and whose use improves the eigenvalues of a linear system. In symmetric positive-definite matrix problems, a symmetric positive-definite matrix preserves that structure under the symmetric transformation .
Applying means solving for a supplied vector . This notation does not require forming a general matrix inverse. A diagonal matrix gives componentwise divisions; a factored matrix gives auxiliary solves such as forward substitution and back substitution.[ref]
Notes for Ma221 Lecture 21, Nov 10 2009. Math 221, Matrix Computations, Fall 2009; Basic iterative methods, web lines 297–308, recurrence (*) and cheap auxiliary-solve requirement
Choosing makes the solve trivial but changes nothing; choosing gives the exact correction but asks us to solve the original linear system.[ref]
The Jacobi preconditioner keeps only the diagonal entries of the matrix . For a symmetric positive-definite matrix, these entries are positive, so its auxiliary solve is . It rescales coordinates with very different diagonal sizes, but cannot remove arbitrary off-diagonal coupling.[ref]
This shares a diagonal matrix with the Jacobi method, but the roles differ. The Jacobi method specifies a whole stationary iterative method for a linear system; a Jacobi preconditioner supplies an auxiliary solve to another iterative method, including the Preconditioned conjugate gradient method.
Left preconditioning multiplies both sides of the linear system by the same invertible matrix . It leaves the unknown vector unchanged. The original linear-system residual is ; the transformed linear-system residual is . Applying the transformed linear map to first computes , then solves .
For symmetric positive-definite matrices and , is generally not a symmetric matrix in the Euclidean inner product. Its positive eigenvalues alone do not justify ordinary Euclidean conjugate gradient method recurrences. The remedy is symmetric positive-definite preconditioning, implemented through the Preconditioned conjugate gradient method.
Right preconditioning substitutes into the linear system . Applying its transformed linear map first solves , then computes . Recover the solution by solving . Its linear-system residual is exactly the original linear-system residual , which is useful when monitoring the imbalance in the original equations.
The left preconditioning and right preconditioning transformed matrices are similar matrices:They therefore have the same eigenvalues, although their Euclidean norm condition numbers and residual histories need not agree. A similarity transformation preserves eigenvalues; a nonorthogonal change of coordinates need not preserve lengths.
Let and be real symmetric positive-definite matrices. The principal square root of a positive semidefinite matrix construction gives an invertible matrix for each. SetThen is equivalent to . This is a matrix congruence, and is a symmetric positive-definite matrix: , and for every nonzero vector ,since . This short proof establishes both requirements for applying the conjugate gradient method to the transformed linear system.
The left transformed matrix has the same eigenvalues becauseIts correct geometry uses the weighted inner product : . Thus it is symmetric in this inner product, even when it is not a symmetric matrix in ordinary coordinates. The spectral condition number governing the transformed symmetric problem is , not generally .
The Preconditioned conjugate gradient method realizes this transformation using auxiliary solves , without constructing or its matrix inverse. With fixed , initialize and ; while , usethen solve and setStop at a zero linear-system residual before forming another ratio. Positive definiteness makes the denominators positive before termination.[ref]
Notes for Ma221 Lecture 15, Dec 1, 2023. Math 221, Matrix Computations, Fall 2023; Notes for Ma221 Lecture 15, Dec 1, 2023; PDF p. 1, equivalent symmetric system and Preconditioned CG algorithm
An invertible matrix alone is insufficient: with and , the left transformed matrix has eigenvalues , and has no real symmetric positive-definite matrix square root. Even a valid symmetric positive-definite matrix can worsen conditioning if its scaling is unsuitable, as the next worked example shows.
For a symmetric positive-definite matrix , solving is equivalent to minimizing the quadratic form with linear termWriting the error vector and expanding gives the exact energy norm identityThe cross term vanishes because . With and , the same quantity is . Symmetric positive-definite preconditioning changes coordinates without changing the energy assigned to a corresponding error vector.
In an orthonormal eigenbasis of , the level set has semiaxis lengths . Its longest-to-shortest axis ratio is . A large spectral condition number of a positive-definite matrix therefore appears geometrically as a thin ellipsoid. Good scaling makes the transformed ellipsoid rounder, allowing a simple search direction to improve all coordinates together.
The negative gradient of is the linear-system residual . Relative to the norm , a steepest direction is : the Cauchy-Schwarz inequality applied to shows that the greatest decrease per unit -length occurs along this direction. Equivalently, ordinary gradient descent in becomes preconditioned steepest descent in .[ref]
Consider the original linear systemCompleting the square proves that is a symmetric positive-definite matrix:The Jacobi preconditioner has . Symmetric positive-definite preconditioning givesIts eigenvectors and have eigenvalues and . HenceThe characteristic polynomial of is . Its eigenvalues and spectral condition number of a positive-definite matrix areThe ellipse axis ratio drops from about to . The transformation multiplies the second coordinate by ten, bringing the two energy scales together.
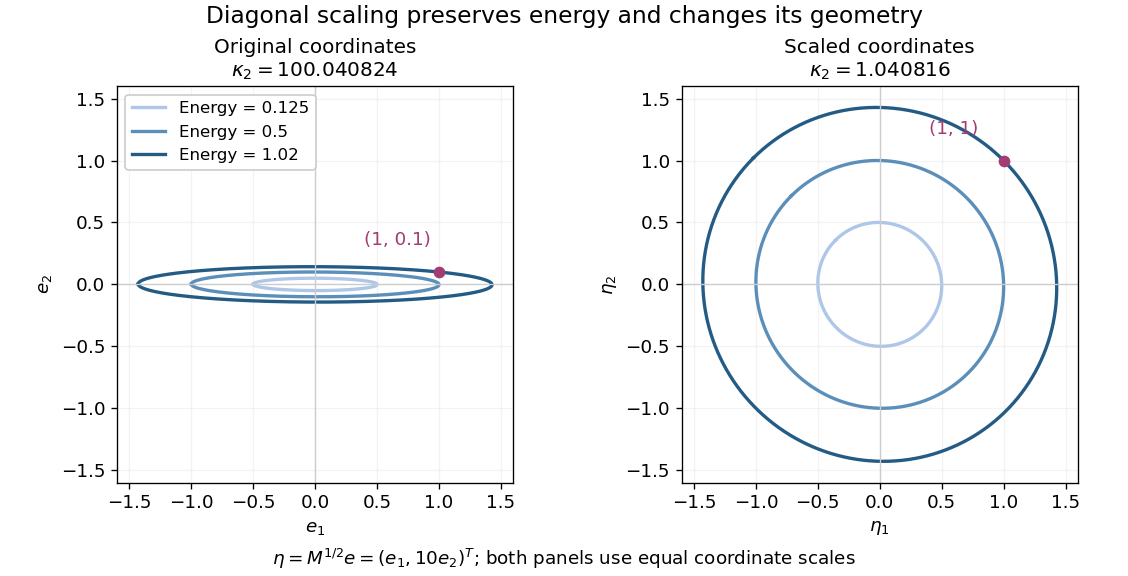
Both panels show the same energy level sets, expressed in error coordinates and . Their coordinate axes have equal scales. The marked displacement becomes ; its energy remains . These are exact contours of the specified quadratic form.
Solving the original equations givesDirect matrix multiplication checks both linear-system residuals:By contrast, left preconditioning gives , which is visibly not a symmetric matrix, despite having the same positive eigenvalues as .
A bad scaling can reverse the benefit: the still valid symmetric positive-definite matrix gives . Its Rayleigh quotients on the coordinate unit vectors are and , so . Cheapness and positive definiteness do not guarantee improved conditioning.
For fixed symmetric positive-definite matrices and , preconditioned steepest descent minimizes along the direction supplied by the auxiliary solve. Given , form the linear-system residual . If , stop: . Otherwise solve and useThis is exact line search for a positive-definite quadratic along . Indeed,whose derivative vanishes at the displayed positive step size. Unlike the Preconditioned conjugate gradient method, it uses the fresh directly rather than combining it with a previous conjugate direction.
For diagonal scaling for a two-dimensional linear system, start at . Without matrix preconditioning, take : , , andWith the Jacobi preconditioner , , , andThe original linear-system residual becomes much smaller after this correction. Quantify progress in the same energy norm in both cases: and . Exact substitution givesIn this particular example the entire histories are and . To check that this is exact, the next step sizes are and , respectively, and their residual updates give and . Multiplying a linear-system residual by a nonzero scalar leaves the next step size unchanged; every pair of steps repeats the same directions at a smaller scale. The two first-step energy ratios then establish these formulas for all .
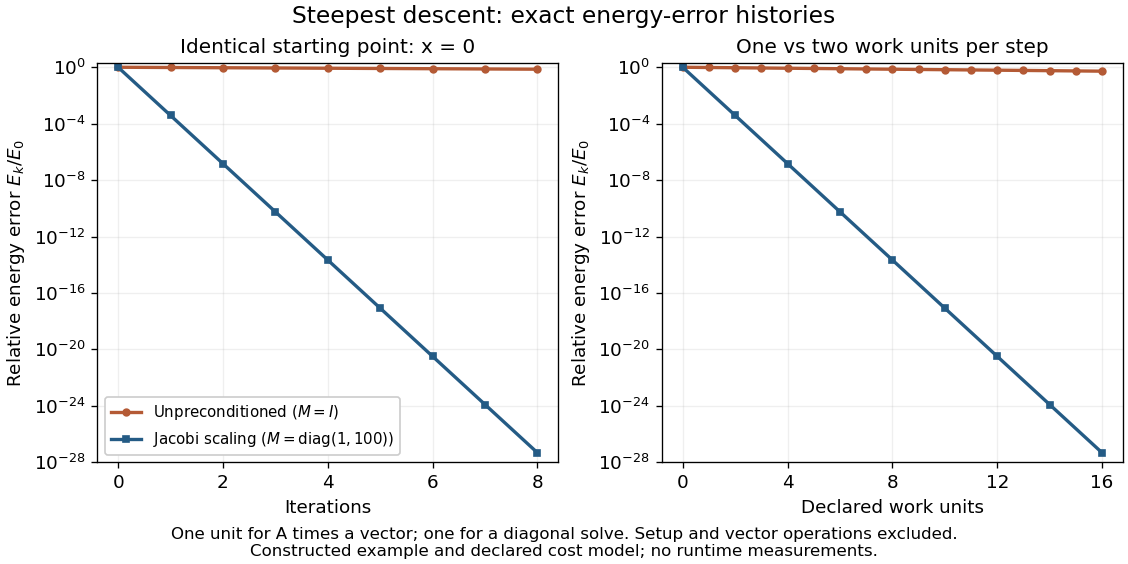


The curves come from exact rational updates of the specified linear system, converted to decimal values for plotting. The left panel counts iterations. The right panel declares one unit for applying and one unit for the auxiliary diagonal solve, charging one unit per unpreconditioned step and two per preconditioned step. It excludes setup and vector operations, so it compares a declared cost model rather than measured runtime. Scaling is advantageous even with that extra charge.
These curves compare steepest descent method iterations. On this two-dimensional linear system, both the conjugate gradient method and the Preconditioned conjugate gradient method terminate within two steps in exact arithmetic. The plot therefore establishes no CG iteration-count advantage for this example; the benefit of scaling for larger problems depends on their eigenvalues and auxiliary-solve costs.
Let , and for the transformed symmetric positive-definite matrix. Then preconditioned steepest descent satisfiesThis is a worst-case bound, not necessarily the actual rate. For our scaled example the bound is , slightly above its computed factor . If the initial transformed error is an eigenvector, exact line search for a positive-definite quadratic removes it in one step, regardless of the full condition number.
A short proof compares exact line search for a positive-definite quadratic with the trial step size in the transformed coordinates. In an orthonormal eigenbasis of , each error coefficient is multiplied by , whose absolute value is at most . Summing times the squared coefficients bounds the trial energy by the square of this factor. The exact minimizing step size does at least as well. This also explains the terminating case : the trial step removes the entire error in one iteration.
Articles by others on the same topic
There are currently no matching articles.