The printed cover dates this paper to 12 June 2015. All three questions are solved below. The zero-dimensional exception in 1(b), the distinction between affine and homogeneous separators in 1(d), and the endpoint convention in the AdaBoost update are made explicit.
The hypothesis class shatters a set when it realizes every binary labelling of : for every function there is an with . Identifying each classifier with its positive set, this sayswhere is the power set. Different labellings may require different members of the hypothesis class.
The VC dimension isIt is infinite if arbitrarily large finite sets are shattered. A hypothesis class has VC dimension zero when it shatters no one-point set; for a nonempty hypothesis class, the empty set is always shattered.
The shattering coefficient, also called the growth function of a hypothesis class, counts the largest number of labellings obtainable on inputs:When has at least points, the same value is obtained by maximizing over -point sets . Always , with equality exactly when some -point set is shattered.
The Sauer-Shelah lemma says that a hypothesis class of finite VC dimension satisfiesIn particular, for ,Here the binomial coefficients count small subsets. One way to obtain the last inequality is to set : since for ,Thus finite VC dimension replaces the unrestricted exponential number of labellings by a polynomial bound in the sample size.
Fix an -point set . The restriction of an intersection to is determined by the ordered pair of restrictions . Some pairs can yield the same intersection, so the growth function of a hypothesis class satisfiesAssume first that . If points were shattered by , the Sauer-Shelah lemma would implyBut , so . Raising this strict inequality to the positive integer power gives a contradiction. No -point set can therefore be shattered; neither can any larger set, since shattering passes to subsets. ConsequentlyThe printed strict inequality needs . For example, on a nonempty domain let contain only the identically zero classifier. Then , whereas the stated conclusion would require . More generally, a nonempty hypothesis class of VC dimension zero has only one distinct labelling function, since two different functions would shatter a point on which they differ. Its self-intersection class also has VC dimension zero.
Choose distinct points of . The vectors lie in the -dimensional vector space , so they are linearly dependent. Hence there are real numbers , not all zero, such thatThe second equality forces both a positive and a negative coefficient. Put , , andRearranging the first equality givesEach side is a convex combination: the coefficients are positive and sum to one. Thus belongs to both convex hulls. Place the points with indices in in , those with indices in in , and assign every zero-coefficient point and every remaining point of to . Then are nonempty, disjoint, and have union . Adding points cannot shrink a convex hull, soThis proves the intersecting convex hull partition theorem, including when has more than points or is infinite: only the initial finite collection was needed.
Expanding the squared Euclidean norm givesIn lifted coordinates , this is the closed half-spaceEvery labelling of the original points obtainable by a Euclidean ball is therefore obtainable on their lifted images by an affine linear classifier. The feature map is injective, since it preserves the first coordinates; distinct original points remain distinct. If the original points are shattered, every labelling of the lifted points is realized, as required.
Here “linear separator” means a separator with an intercept, namely an affine hyperplane. If a convention demands strict separation on the finite sample, increase the constant term of the positive score by a sufficiently small positive amount. Positive points then have strictly positive score, and the finitely many negative scores remain strictly negative. A homogeneous separator can alternatively be obtained after adjoining one more constant coordinate; this distinction matters for dimension counts.
For , take the vertices of a regular simplex in , centered at zero and scaled so that . For example, realize them asin the -dimensional vector subspace , identified isometrically with . These vertices are affinely independent.
Assign arbitrary desired signs , positive for inclusion. Affine independence implies that there is an affine function with for every : the interpolation conditions form an invertible linear system. For a sufficiently small , chooseAt every vertex,Thus the Euclidean ball contains exactly the positively labelled vertices, with none on its boundary. This construction also covers the all-positive and all-negative labellings. Therefore
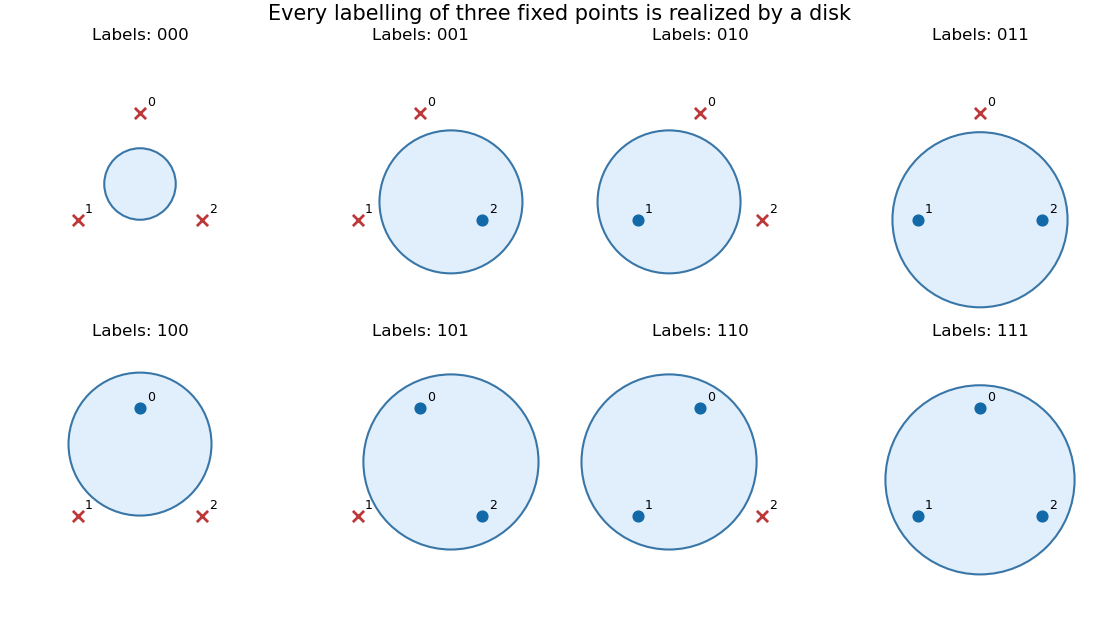

An affine linear classifier in has VC dimension . The upper bound follows from the intersecting convex hull partition theorem: for any points, label the two parts oppositely. The two convex hulls cannot be strictly separated by an affine hyperplane, since they intersect. A weak boundary convention gives the same contradiction: an affine score is nonnegative on the positive convex hull and strictly negative on the negative convex hull. The lower bound comes from the affinely independent vertices of a simplex, because an affine score can interpolate arbitrary signs there.
Consequently, parts (i) and (ii) immediately giveThe one-sided orientation of the lifted separators permits the sharper, exact conclusionTo prove the remaining upper bound, take any distinct points and a nonzero affine dependence as in part (c). Write . Reverse every coefficient if necessary so that . Prescribe positive labels when and negative labels when ; zero coefficients may be labelled arbitrarily. If a Euclidean ball realized these labels, its score would satisfyIndeed, every positive-coefficient term is nonnegative and every negative-coefficient term is strictly positive, with at least one of the latter. On the other hand, expanding the score and using the two affine dependence identities givesa contradiction. No points are shattered, completing the exact determination of the VC dimension of Euclidean balls. In the exceptional zero-dimensional Euclidean space, every positive-radius Euclidean ball is the whole singleton space, so the VC dimension is zero.
Take labels and fix the standard normalization in which the squared weight penalty has coefficient . The squared-slack support vector machine, a form of soft-margin support vector machine, has primal problemThe slack variables of a support vector machine permit margin violations. Penalizing favors a wide support-vector-machine margin, while sets the cost of the violations. The intercept is unpenalized, and the resulting classifier is , with a fixed choice at zero. The square on is essential to the Lagrangian dual problem below.
Use Lagrange multipliers for and for . The optimization Lagrangian isThe Lagrange dual function is the infimum over the now unconstrained primal variables. The first-order optimality conditions in and giveIf the latter equality fails, the infimum over is . The first-order optimality condition in givesSubstitution, or completing the square separately in and each , producesprovided . For fixed nonnegative , this expression is maximized over at . Thus the simplest Lagrangian dual problem isIn particular, there is no upper box constraint . That constraint belongs to the linear-slack penalty; squared slack instead contributes the displayed diagonal quadratic penalty. With and Gram matrix , the objective can also be writtenSince is positive semidefinite and , the matrix in parentheses is positive-definite. The objective of the Lagrangian dual problem is therefore strictly concave, and the feasible maximizer is unique.
The primal problem is a convex optimization problem, and is strictly feasible for both families of inequalities. Slater's condition gives strong duality, so an optimum of the Lagrangian dual problem yields a primal optimum. The Karush-Kuhn-Tucker conditions supplyFor any with , the intercept is consequentlyAll such choices agree at an exact optimum. If all labels have one sign, the optimal coefficients can all be zero: choose , , and any constant intercept of that sign with magnitude at least one.
A real positive-semidefinite kernel on an input set is a function for which there is an inner product space and a feature map satisfyingEquivalently, is symmetric and every finite Gram matrix is positive semidefinite: for all real coefficients . An infinite-dimensional Hilbert space is allowed.
Replace every inner product in part (b) by and solveThis is precisely the Lagrangian dual problem obtained by replacing each original input by in the primal problem. The weight vector it determines isand the intercept follows from the same Karush-Kuhn-Tucker conditions. For example, if ,Thus training needs only the finite Gram matrix, even if the feature map has infinitely many coordinates. This is the kernel trick. The result is an affine linear classifier in the feature space; its boundary in the original input space can be nonlinear. The squared-slack diagonal term and the equality constraint remain unchanged.
An embedding is determined by its chosen increasing sequence of positions. Accordingly, the all-subsequence embedding kernel counts pairs of embeddings, one in and one in , that spell the same subsequence. The two embeddings are distinguished even when they spell the same word as another pair. The empty word contributes exactly one pair.
Let , , and define for prefixes. When either prefix is empty, only the empty word has an embedding in both, soTo derive a dynamic programming recurrence, count pairs that do not use position of or do not use position of . Inclusion-exclusion givesThe remaining pairs use both final positions. These positions must be the final letters of the common word, so they contribute nothing if . If , deleting those two final positions is a bijection to arbitrary embedding pairs on the two shorter prefixes, including their empty pair. Their contribution is therefore . HenceEquivalently, when the final symbols agree the recurrence simplifies to ; when they differ, subtract the diagonal term. Fill the table in increasing prefix order and return . The boundary values and the disjoint counting argument prove correctness by induction on .
A one-row implementation of this dynamic programming uses the saved old diagonal entry:The assignment to
F[0..p] := 1
for i := 1 to n:
    diagonal := 1
    for j := 1 to p:
        above := F[j]
        if x[i] = y[j]:
            F[j] := above + F[j-1]
        else:
            F[j] := above + F[j-1] - diagonal
        diagonal := above
return F[p]diagonal retains the value from the previous row before F[j] was overwritten. Swapping and if necessary minimizes the row length. Thus the time complexity is arithmetic operations and the extra space complexity is integer cells. Empty inputs return one immediately.These counts include multiplicity: for , the empty word contributes , the word contributes , and contributes , giving , not three. More generally, each result is at most , since it counts some pairs of position subsets. Exact integers therefore require bits; the stated quadratic bound is an arithmetic-operation bound, with a conservative bound for elementary bit arithmetic.
The proposed positive-semidefinite kernel is valid: for each finite string only finitely many coordinates are nonzero, so is a well-defined feature map into the inner product space of finitely supported coordinate families, and its inner product is exactly .
The two-interval approximation by one interval supplies an approximation guarantee for every input probability distribution . Merge overlapping target intervals, and write the target positive set as at most two disjoint ordered intervals . Put and . If there is only one nonempty component, the target already belongs to the interval hypothesis class and has zero misclassification risk. If the interval notation permits empty intervals and the target is empty, choose that same empty interval in .
In the two-component case, choosing the heavier component as the hypothesis loses only the lighter component, so its misclassification risk isAlternatively, choose the single interval spanning both components. This produces no false negatives, and its false positives lie in the gap. Its misclassification risk is at most . Both candidates are in , so there exists an interval withFor the last step, use if , and if . This avoids any assumption that an empty interval or the whole real line belongs to .
Use empirical risk minimization over intervals on independent labelled examples. The generalization result needed here is the VC uniform convergence theorem: for a binary hypothesis class of finite VC dimension , there is a universal constant such that, for any labelled-data probability distribution and , a sample sizeensures, with probability at least , that every hypothesis's empirical misclassification risk differs from its misclassification risk by at most . This theorem does not require the labels to be realizable by the hypothesis class.[ref]
Learnability and VC Dimension in MIT 6.790. Sections “Uniform Convergence implies Agnostic PAC Learnability” and “Fundamental Theorem of Learnability”
The interval hypothesis class has VC dimension two: any two ordered points can receive all four labellings, whereas an interval cannot label three ordered points . Take and choose an interval minimizing the empirical misclassification risk. On the simultaneous convergence event,ThereforeSince and are fixed constants, examples suffice, which is polynomial in as required by the paper's definition of weak PAC learning.
For completeness, empirical risk minimization over intervals is computationally effective. Sort the sample and group equal coordinates, since one interval cannot split identical inputs. Give each group weight equal to the number of positive labels minus the number of negative labels in that group. The number of empirical mistakes made by an interval is the total number of positives minus the total weight of the consecutive groups it contains. Select the consecutive block of maximum weight, or select a finite interval outside the sample if every nonempty block has negative weight. This enumerates all possible sample labellings by intervals and attains the minimum empirical misclassification risk; sorting and a maximum-block scan are sufficient. The time complexity is .
Use weighted decision stump optimization with the convention , and write . For each coordinate , sort the examples by their th coordinate and group all equal coordinate values. For a threshold between the th and st distinct values, the decision stump predicts on the left and on the right. Its weighted misclassification risk isStart with a threshold below the minimum observed value. Every prediction is then , and the initial error is . Sweep the threshold from left to right. When it passes an entire group of equal coordinate values, that group's prediction changes from to , so updateRecord the smallest value and a threshold achieving it, including the final threshold above all observations, which predicts everywhere on the sample. Representatives can be chosen strictly between successive distinct values; the two outer representatives are finite real numbers below the minimum and above the maximum.
Every threshold has exactly the same sample predictions as one of these representatives. In particular, if a threshold equals an observed value, the equality group is on the side under the chosen sign function convention, which duplicates the representative immediately before that group. Thus the sweep includes every possible sample labelling by the stated decision stump. Repeating for all coordinates and returning the globally smallest error proves optimality.
Sorting costs per coordinate and the grouped sweep costs . The overall time complexity iswith working storage when coordinates are processed one at a time. Pre-sorted coordinate orders can be reused across repeated AdaBoost rounds, leaving work per round for changing weights. The paper allows only the orientation ; reversing its polarity would enlarge the hypothesis class and is unnecessary here.
Write , , and . Correctly classified observations have and total -weight ; incorrectly classified observations have and total weight . The normalizing constant in the AdaBoost update is thereforeFor , the definition of givesIf observation is correct, its multiplier in the normalized update isif it is incorrect, the multiplier isThe corresponding denominators are exactly : they are when and when . ConsequentlyAs a check, the new total mass on correctly classified observations is , and the mass on incorrectly classified observations is . The update thus produces a probability distribution and assigns the two groups equal aggregate mass. When , and every individual weight is unchanged.
The displayed finite update assumes . The usual weak learner guarantees , but it can return a perfect classifier with ; then the logarithm is infinite and the normalized exponential formula is not defined. AdaBoost stops on that perfect hypothesis rather than executing this update. Similarly, the printed formula is not an ordinary finite update at .
Articles by others on the same topic
There are currently no matching articles.